Cover image

Talk, Tool, Triumph: Training Agents with Real Conversations

TL;DR for operators The paper behind this article is useful because it changes the unit of training. Instead of training an agent to emit the right function call after a tidy prompt, MUA-RL trains the agent inside a live-feeling loop: user message, agent response, tool call, database result, another user message, another decision, and so on.1 That is much closer to customer support, travel booking, retail order management, telecom troubleshooting, and internal workflow automation. In other words: the model is not just learning which button to press. It is learning when to ask, when to verify, when to act, and when not to confidently vandalise the database. Progress. ...
August 27, 2025 · 16 min · Zelina
Cover image

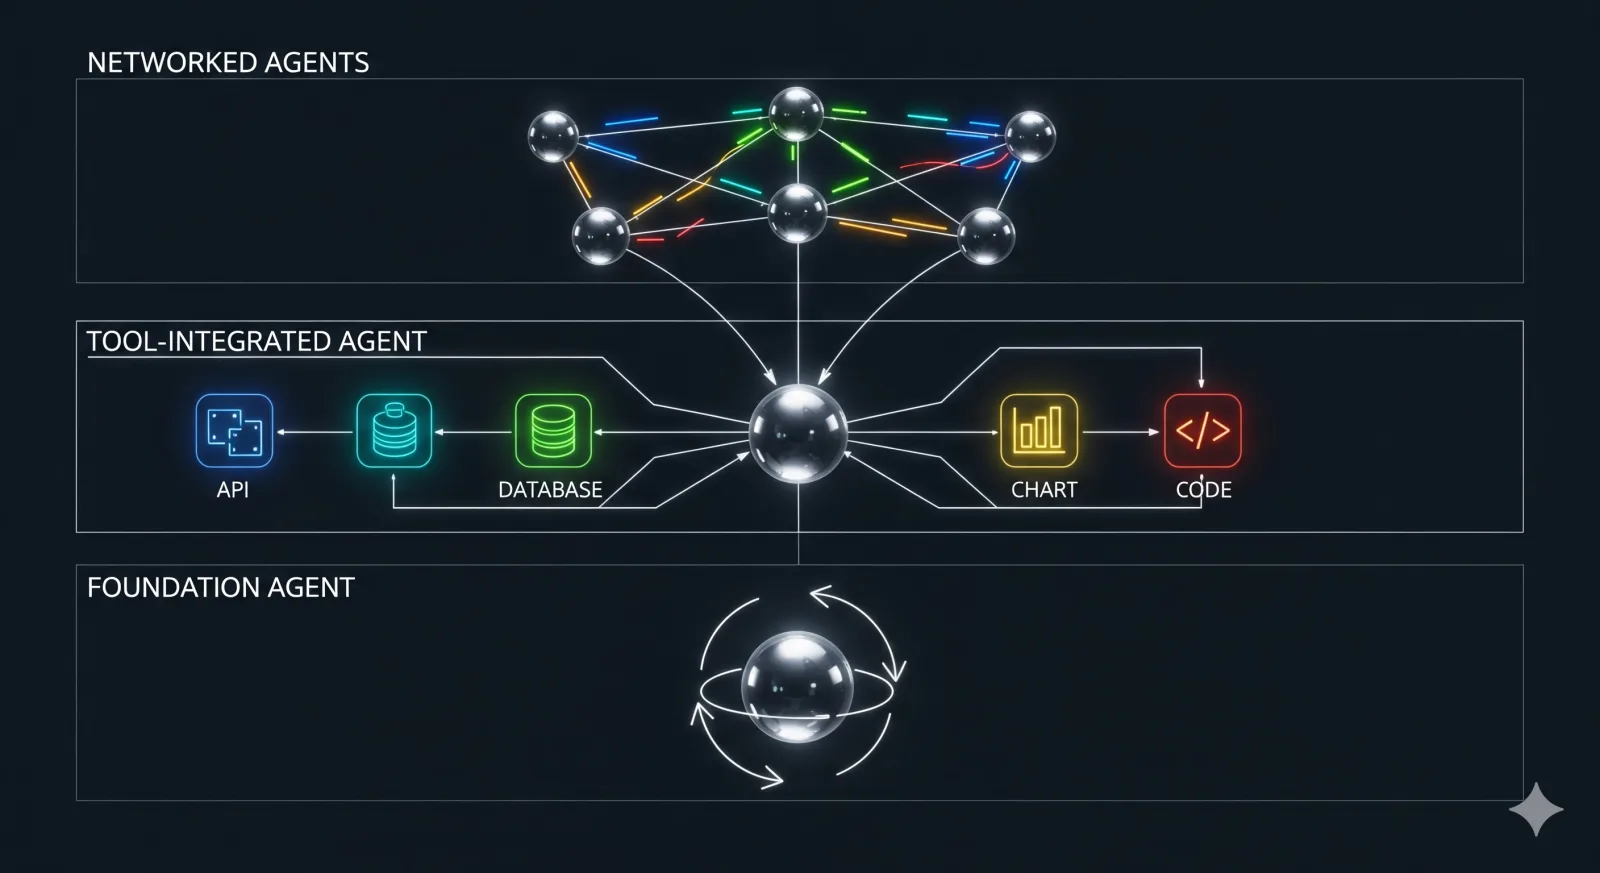
Agents on the Clock: Turning a 3‑Layer Taxonomy into a Build‑Ready Playbook

TL;DR for operators Most agent projects fail in a wonderfully unglamorous place: not at “intelligence”, but at the loop. The agent forgets what it already did. It calls the wrong tool. It reflects poetically instead of usefully. It delegates to three other agents because the demo looked impressive, then spends the next minute staging a management retreat in token form. Charming, but not production. ...

August 26, 2025 · 15 min · Zelina
Cover image

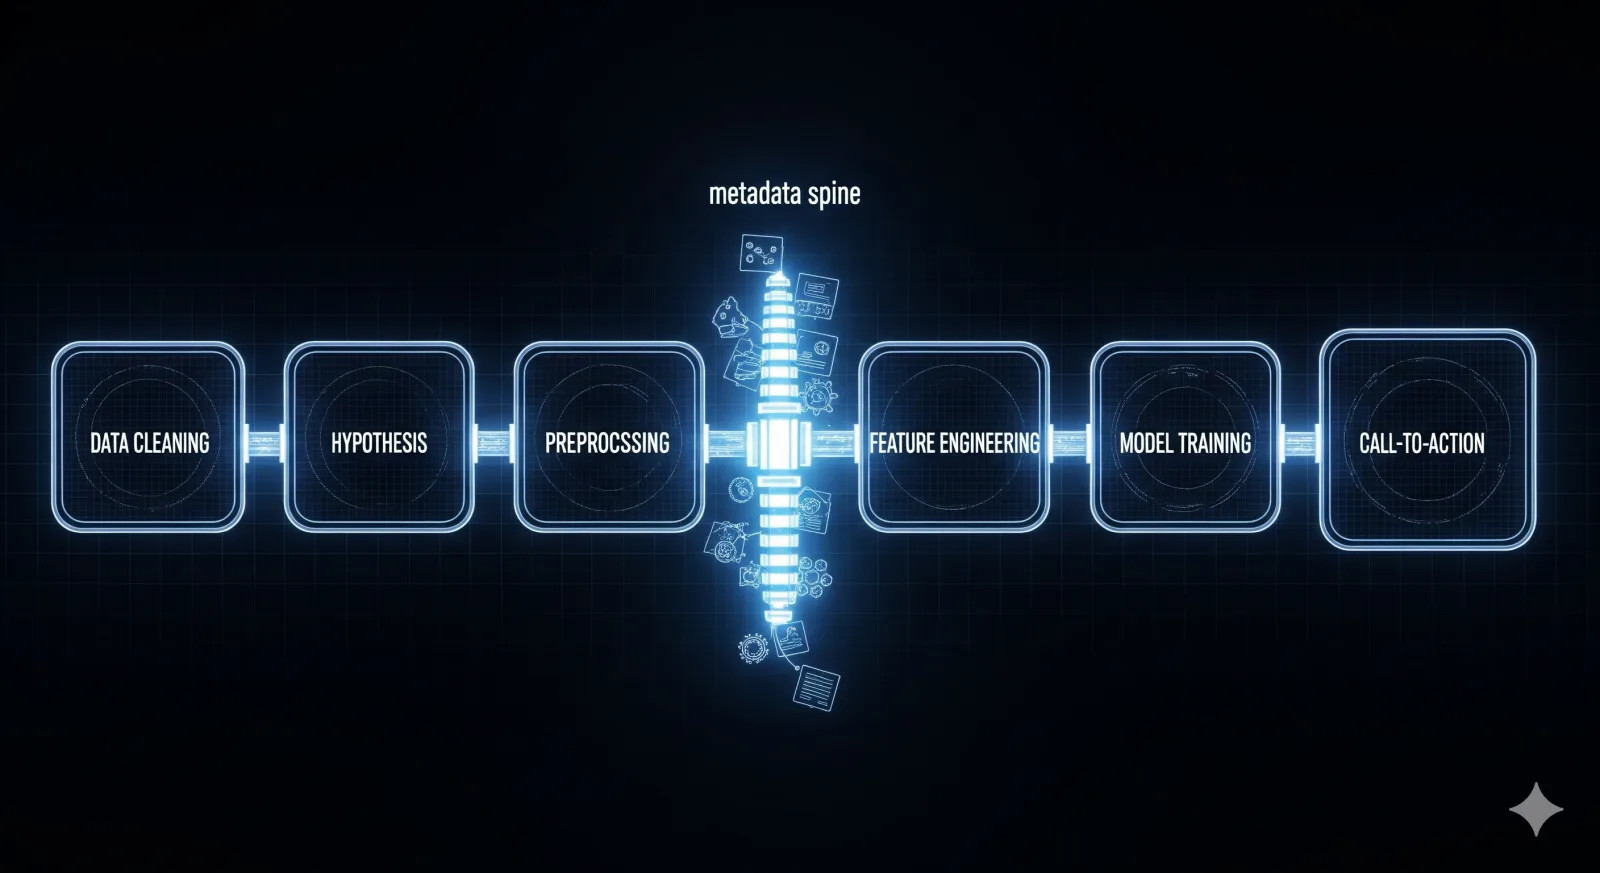
Hypotheses, Not Hunches: What an AI Data Scientist Gets Right

TL;DR for operators The paper introduces an “AI Data Scientist”: a six-subagent system that moves from raw tabular data to cleaned data, tested hypotheses, engineered features, trained models, and business-facing recommendations.1 The useful idea is not that another agent can write Python. Congratulations, we have met 2025. The useful idea is that hypothesis testing becomes the workflow’s organising rail. ...

August 26, 2025 · 18 min · Zelina
Cover image

Stop at 30k: How Hermes 4 Turns Long Chains of Thought into Shorter Time‑to‑Value

TL;DR for operators Reasoning models are not expensive because they are philosophical. They are expensive because they can keep thinking long after the business value has stopped arriving. The Hermes 4 Technical Report is easiest to misread as another open-weight leaderboard announcement. That is the least useful reading. The more useful reading is that Hermes 4 is a build manual for making open reasoning models behave like deployable systems: generate diverse synthetic data, verify what can be verified, preserve general instruction-following, control runaway reasoning length, and evaluate with enough logging to know whether the model failed or the benchmark harness sneezed.1 ...

August 26, 2025 · 18 min · Zelina
Cover image

MoA vs. Moat: Agentic LLMs for Drug Competitor Mapping Cut Diligence Time 20×

TL;DR for operators A recent arXiv paper on LLM-based agents for drug-asset due diligence shows something more useful than “AI does research now.” It shows a practical operating pattern: convert past expert memos into a measurable benchmark, send a persistent web-search agent to maximise competitor recall, then pass candidates through a stricter validator before analysts see them.1 ...

August 25, 2025 · 17 min · Zelina
Cover image

Put It on the GLARE: How Agentic Reasoning Makes Legal AI Actually Think

TL;DR for operators GLARE is useful because it attacks the boring but expensive failure mode in legal AI: the model jumps to the familiar label, decorates the guess with legal-sounding prose, and hopes nobody asks whether a nearby charge would have fit better. The paper proposes an agentic legal judgment prediction framework that does three things in sequence: it expands the set of candidate charges, retrieves precedents with explicit reasoning paths rather than just similar facts, and performs targeted legal search when the model detects a knowledge gap.1 That mechanism matters more than the branding. GLARE is not “RAG, but with legal documents.” It is closer to a small operating procedure for legal reasoning: widen the hypothesis space, compare alternatives, then fetch the missing premise. ...

August 25, 2025 · 17 min · Zelina
Cover image

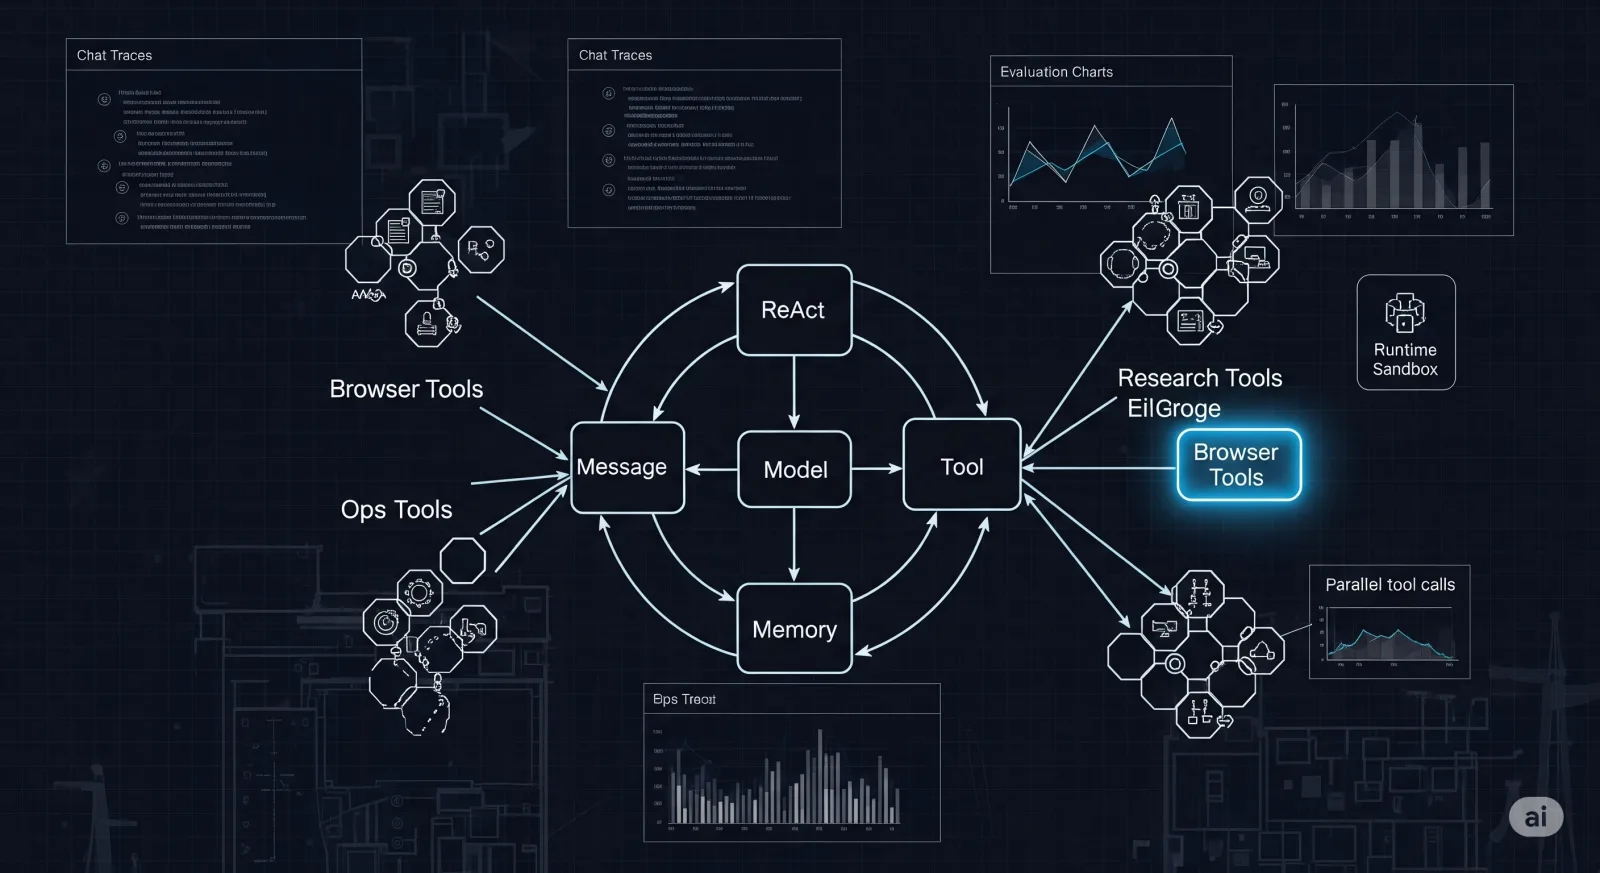
ReAct Without the Chaos: AgentScope 1.0 Turns Tools into Strategy

TL;DR for operators AgentScope 1.0 is best read as a production-shaping framework for agentic applications, not as a victory lap over rival agent frameworks. Alibaba’s paper describes a developer-centric stack that rebuilds agents around four core abstractions — message, model, memory, and tool — then places a ReAct-style reasoning-and-action loop on top of them.1 ...

August 25, 2025 · 17 min · Zelina
Cover image

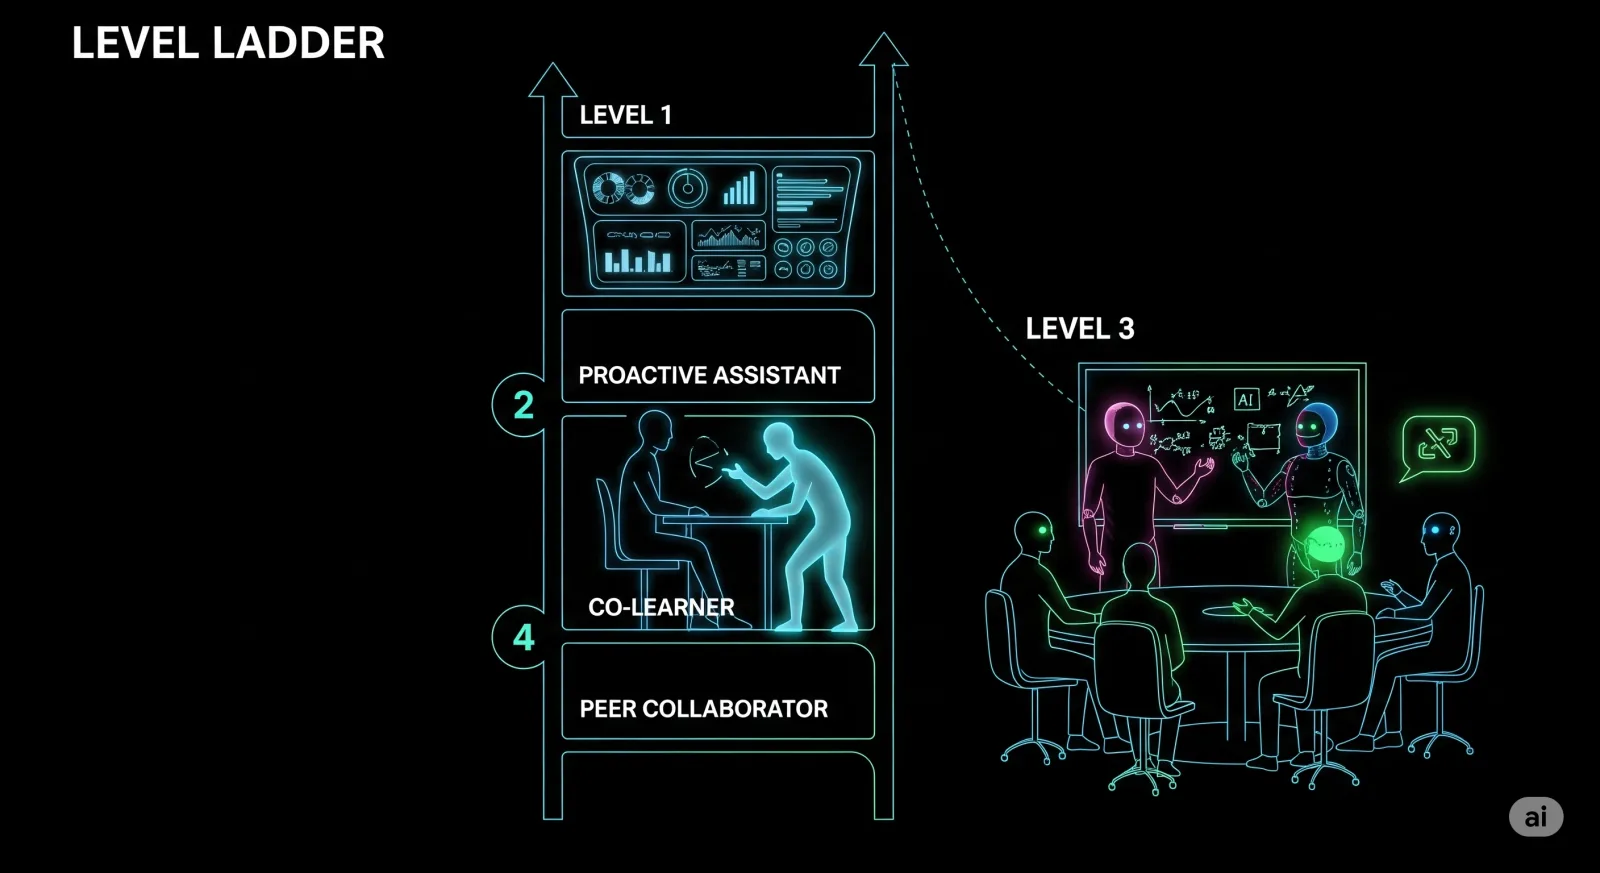
From Copilot to Colleague: The APCP Ladder for Agentic Learning

TL;DR for operators The useful part of the APCP framework is not that it gives AI another grand title. We already have enough of those. Its value is that it separates four very different product promises that are often mashed together under “AI learning assistant”: an AI that executes commands, an AI that nudges, an AI that shares cognitive work, and an AI that behaves like a peer collaborator.1 ...

August 23, 2025 · 20 min · Zelina
Cover image

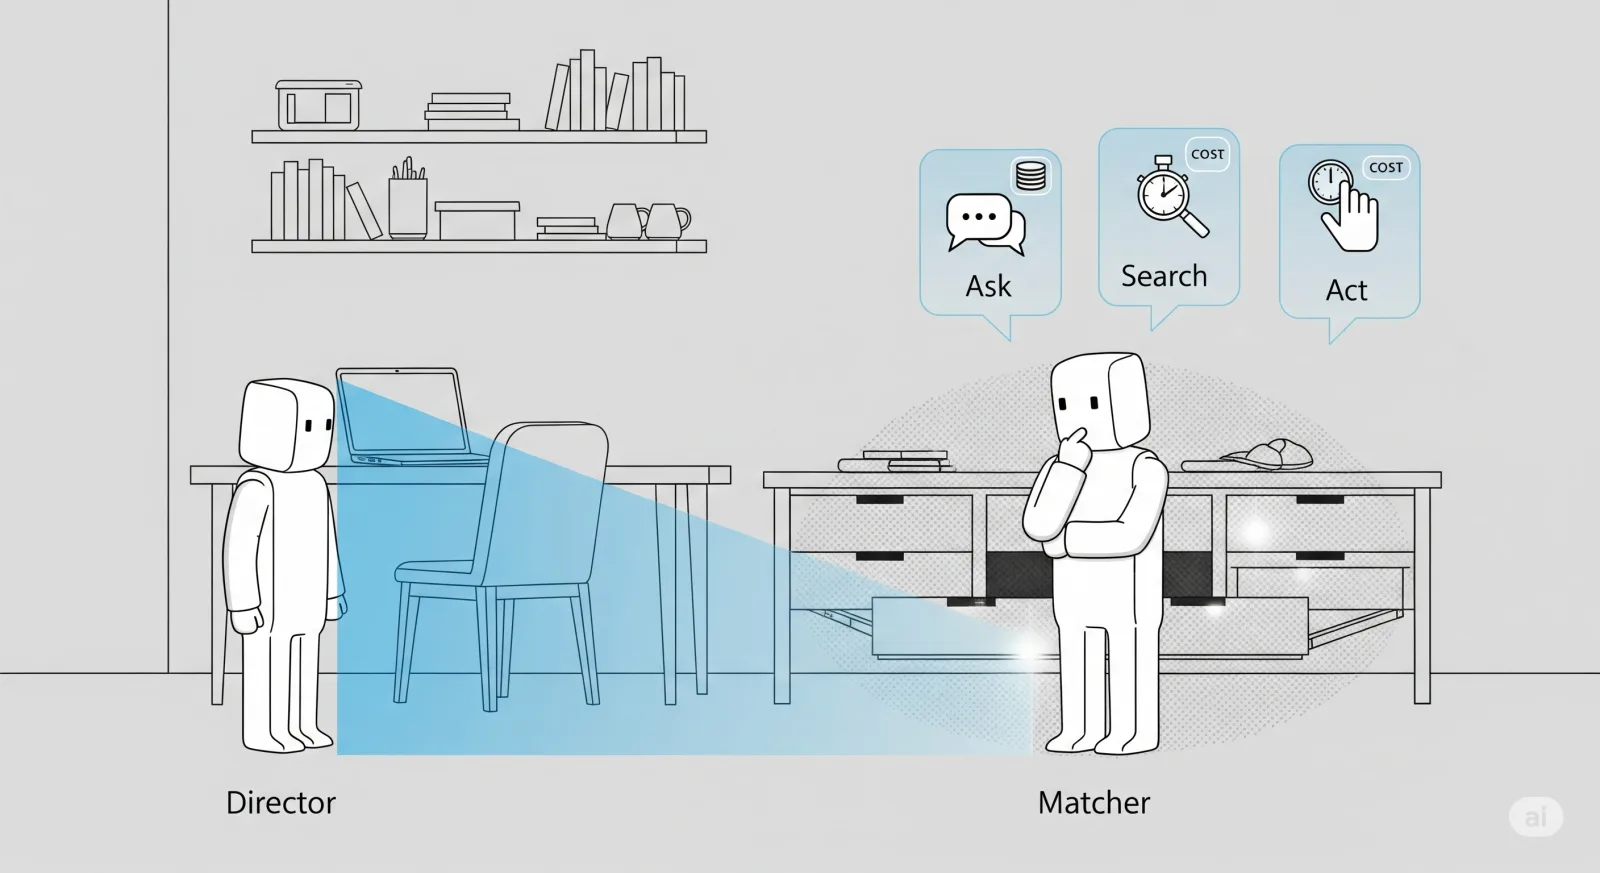
Who Sees What, Who Pays the Cost? Teaching Agents to See Through Others’ Eyes

TL;DR for operators The paper’s useful message is not “symbolic planners can teach LLM agents to reason socially.” That would be tidy, flattering, and mostly wrong. The useful message is narrower and more operational: planner-derived thought-action examples can scaffold some agent behaviour, especially local decision discipline, but they do not automatically create robust perspective-taking. In the tested Director–Matcher environment, agents do well when the task is basically “ignore what the other party cannot see.” They struggle when they must imagine what exists in another agent’s private view, or decide whether it is worth asking, moving, opening, or acting under uncertainty.1 ...

August 23, 2025 · 20 min · Zelina
Cover image

IRB, API, and a PI: When Agents Run the Lab

TL;DR for operators Lab work is mostly not white coats and dramatic discoveries. It is protocol design, ethics paperwork, recruitment settings, data cleaning, model diagnostics, figure formatting, reference checking, and the slow discovery that your beautiful hypothesis has politely declined to exist. That is what makes this paper interesting. Virtuous Machines: Towards Artificial General Science presents an agentic AI system that did not merely write a speculative research proposal. It designed and executed an online human-participant experiment, collected data through Prolific and Pavlovia, analysed the results, produced figures and tables, wrote manuscripts, and ran peer-style review over the outputs.1 ...

August 20, 2025 · 16 min · Zelina