Cover image

Tool Time, Any Time: Inside RLFactory’s Plug‑and‑Play RL for Multi‑Turn Tool Use

Tool calls are where agent demos stop being cute. A chatbot can talk through a task all day. A working agent has to search, query, execute, verify, retry, and sometimes discover that the tool it politely called has returned a malformed answer after making everyone wait. That is the difference between “reasoning about work” and doing work. The former gives you fluent paragraphs. The latter gives you latency, interface contracts, timeout handling, reward ambiguity, and a suspicious number of JSON parsing errors. Glamorous, naturally. ...
September 13, 2025 · 16 min · Zelina
Cover image

Fault Lines & Safety Nets: How RAFFLES Finds the First Domino in Agent Failures

A failed agent run rarely fails politely. It does not raise its hand at step 4 and say, “Here is the causal error; please patch the planner.” It drifts. A web agent grabs the wrong source. A coding agent trusts a bad assumption. A verifier rubber-stamps a plausible-looking answer. Twenty steps later the final output is wrong, the dashboard says “failed,” and the team is left doing digital archaeology with a very expensive shovel. ...

September 12, 2025 · 16 min · Zelina
Cover image

Graph and Circumstance: Maestro Conducts Reliable AI Agents

A broken AI agent often looks deceptively close to working. It answers most questions. It calls the right tool sometimes. It follows the instruction until the conversation gets long, the retrieval query gets vague, or the arithmetic becomes just difficult enough for the model to start doing spreadsheet theatre. The usual repair is prompt editing. Add a stern sentence. Add a role. Add an example. Add “think step by step,” because apparently the machine needed a motivational poster. ...

September 11, 2025 · 15 min · Zelina
Cover image

Plan, Then Rewrite: Why Explicit Intent Wins in Agent Workflows

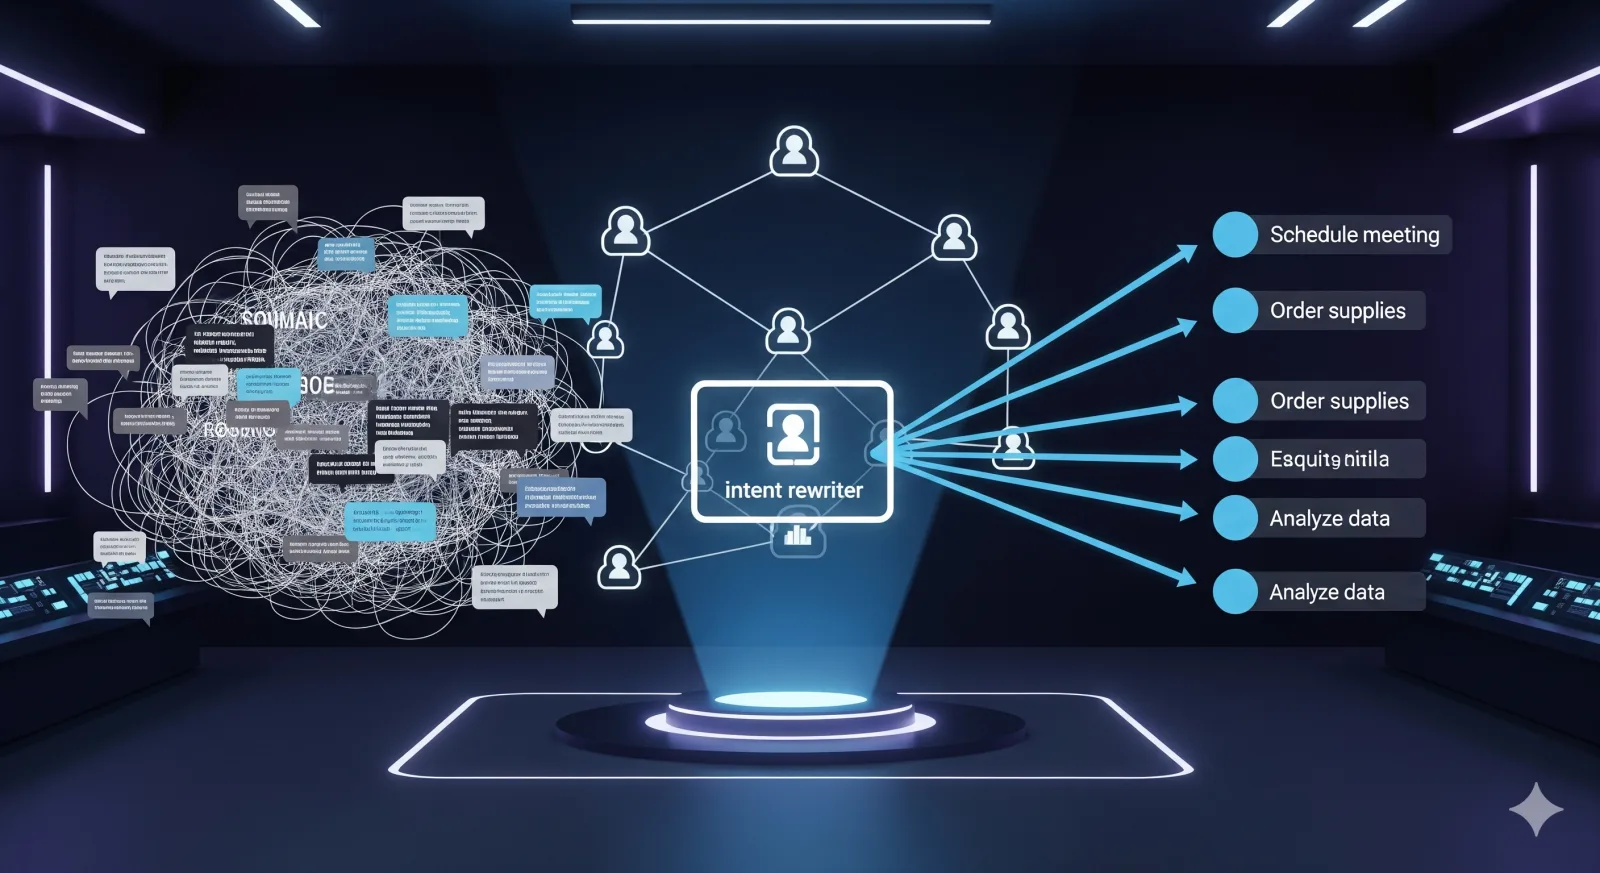
A user starts by asking for Italian restaurants, answers a few clarification questions, then changes their mind and asks for Mexican instead. A human hears the reversal. A planner may hear: pizza, pasta, Italian, Mexican, recommendations, and perhaps a vague invitation to overachieve. Naturally, it may then produce a plan with the confidence of a consultant who attended only half the meeting. ...

September 11, 2025 · 14 min · Zelina
Cover image

Pieces, Not Puzzles: How ArcMemo Turns LLM Reasoning into Reusable Skills

Tickets repeat. Spreadsheets repeat. Compliance reviews repeat. Code reviews repeat. Not exactly, of course. That would be merciful. They repeat with just enough variation to make last month’s solution almost useful and therefore mildly dangerous. This is where many enterprise “AI memory” systems become filing cabinets with delusions of competence. They store prior chats, snippets, tickets, documents, and summaries, then hope the next prompt will rhyme closely enough with something in the archive. Sometimes it does. Often it does not. The agent remembers the old puzzle, not the transferable piece. ...

September 8, 2025 · 15 min · Zelina
Cover image

Plan, Don't Spam: The Goldilocks Rule for Test‑Time Compute

A busy agent is not necessarily a thinking agent. Anyone who has watched an LLM agent narrate every tiny move knows the feeling. It reviews the goal. It drafts a plan. It revises the plan. It reconsiders the revision. Then, with exquisite deliberation, it clicks the wrong button. The transcript looks intelligent; the behaviour looks like a consultant trapped in a revolving door. ...

September 8, 2025 · 15 min · Zelina
Cover image

Guard Rails > Horsepower: Why Environment Scaffolding Beats Bigger Models

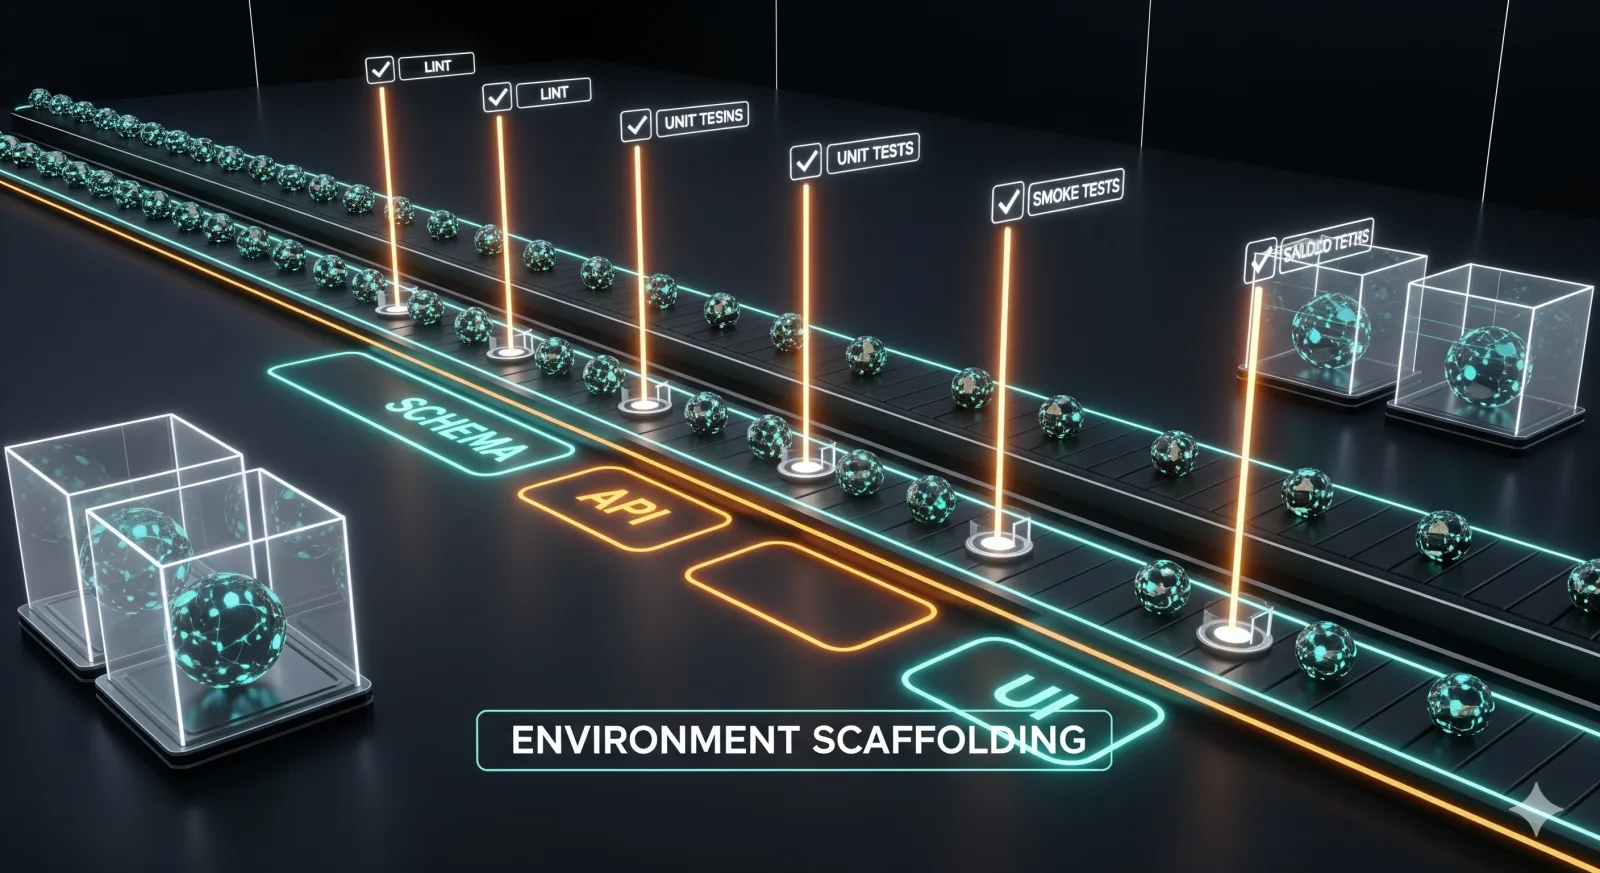
A demo is cheap. Ask an AI agent to build a web app, watch it spin up a cheerful interface, click a few buttons, and everyone briefly pretends software engineering has been solved. Then production begins. The app boots but stores nothing. The database schema exists but the handler quietly forgets foreign keys. The UI looks plausible until the first state transition. The test suite passes because it checked the page title, not the workflow. Somewhere, a dashboard reports “success.” Somewhere else, a user discovers the thing is an elegant cardboard storefront. ...

September 6, 2025 · 14 min · Zelina
Cover image

Control Plane, Not Pain: How Agentic OS Turns Linux Scheduling into a Semantic Service

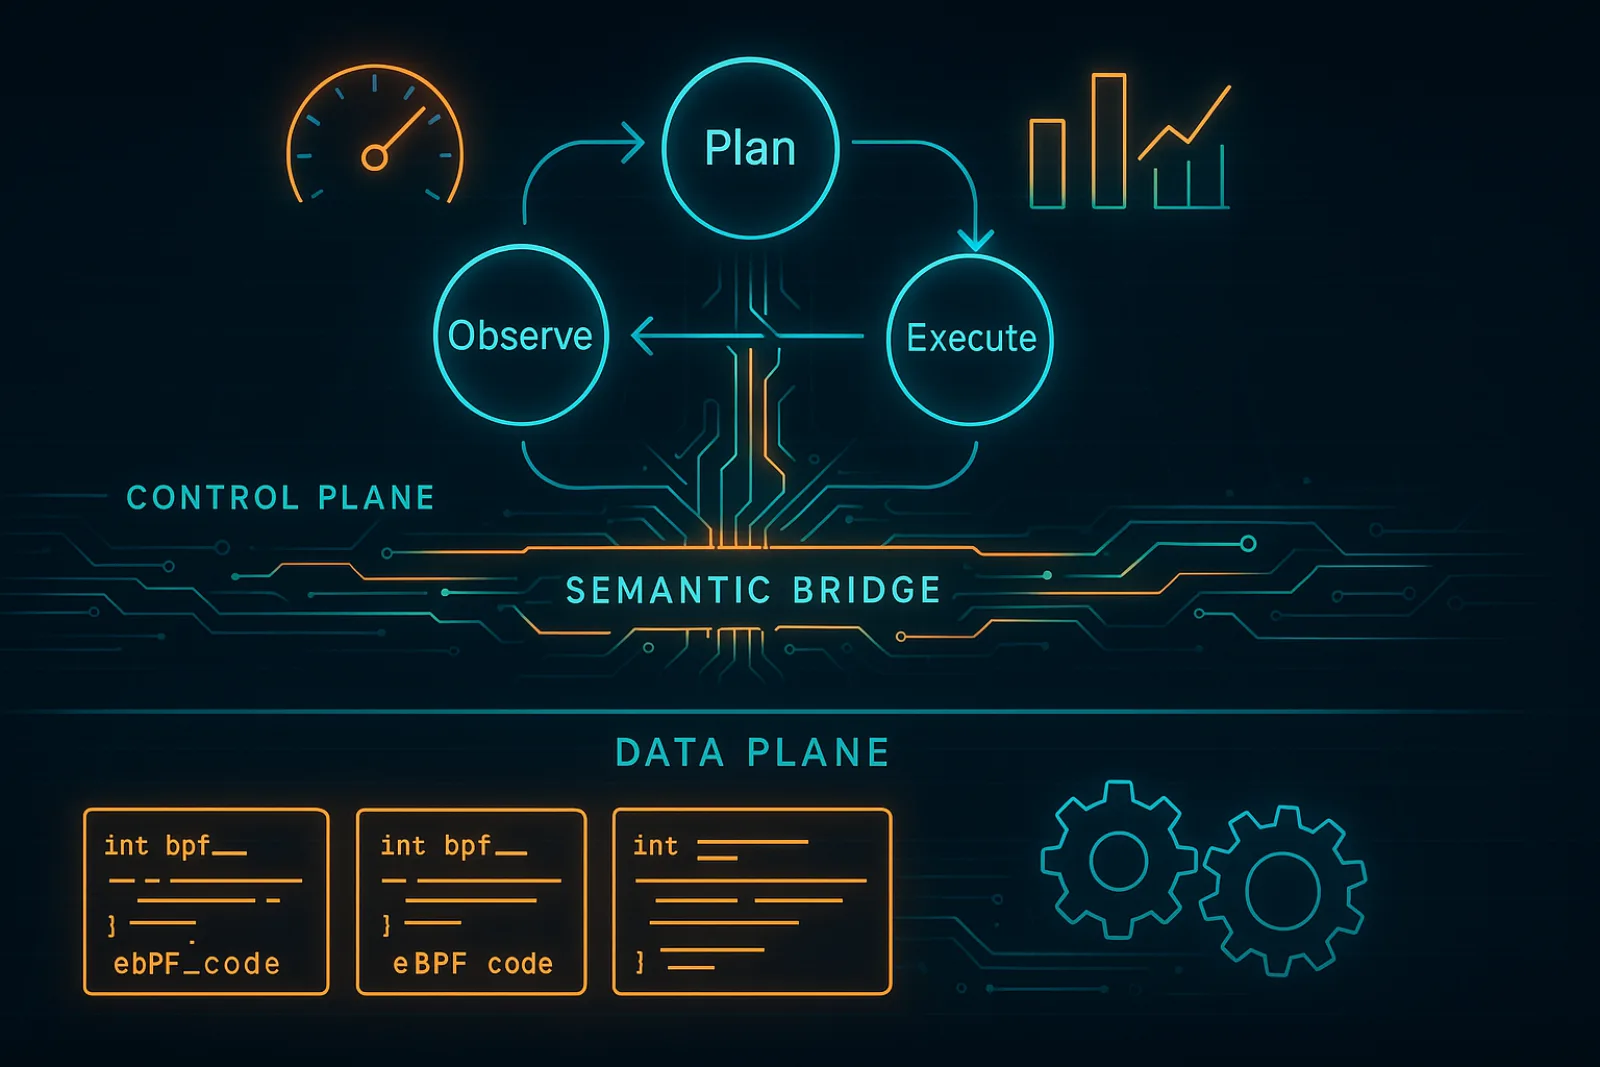
A scheduler is where elegant software abstractions go to meet the unpleasant fact that CPUs are finite. Most businesses do not care which runnable task receives a slice of time first. They care that builds finish faster, services stop coughing at the 99th percentile, batch jobs do not drag the whole estate into a swamp, and nobody has to summon a kernel engineer every time a workload changes shape. ...

September 4, 2025 · 14 min · Zelina
Cover image

Rollouts, Not GPUs: Why AWorld’s 14.6× Speedup Rewires Agent Training

TL;DR for operators AWorld’s useful lesson is not “buy more GPUs”. It is more specific, and therefore more operationally annoying: if an agent learns from interaction, the bottleneck becomes the rate at which it can safely attempt tasks, collect trajectories, score outcomes, and feed those traces back into training. The paper shows three things that matter for builders. First, more rollouts per task sharply raise success rates on GAIA validation: Claude 3.7 Sonnet rises from 47.9% pass@1 to a 76.4% peak, while GPT-4o rises from 27.3% to 65.5% as rollout count increases to 32. Second, AWorld’s distributed executor cuts rollout time for one training cycle from 7,695 seconds to 525 seconds, while training time stays fixed at 144 seconds. That is the paper’s 14.6× speedup, and it is the result that makes the training loop economically less ridiculous. Third, using that loop, Qwen3-32B-AWorld reaches 32.23% GAIA test pass@1, up from 21.59% for the base Qwen3-32B model, and improves xbench-DeepSearch from 12% to 32% without direct training on that benchmark. ...

August 31, 2025 · 15 min · Zelina
Cover image

Judge, Jury, and Chain‑of‑Thought: Making Models StepWiser

TL;DR for operators StepWiser is a judge for multi-step reasoning systems. Its practical claim is simple: do not wait until the final answer is wrong before discovering that the model fell off a cliff three paragraphs earlier. The paper turns process supervision into a three-part mechanism. First, the solver is taught to divide its reasoning into coherent “chunks-of-thought” rather than arbitrary line breaks. Second, each chunk is labelled by estimating whether continuing after that chunk improves or harms the probability of eventually reaching a correct answer. Third, a separate judge is trained with online reinforcement learning to reason about each chunk before deciding whether it is valid.1 ...

August 27, 2025 · 18 min · Zelina