Cover image

The Sequencing Pipeline Finished. The Judgment Did Not.

TL;DR for operators A DNA sequencing pipeline can finish every computational stage successfully and still produce results that warrant investigation. BaseCamp1 illustrates this problem with a scenario in which individual processing metrics appear acceptable, yet their combined results show an unusually high rate of reported genetic differences. Completing the workflow does not establish that its scientific conclusions are credible. ...
October 22, 2026 · 8 min · Zelina

From Editorial Memory to Evidence-Linked Publication Readiness

A mid-sized publisher redesigns manuscript, rights, editorial, production, metadata, and release coordination around six bounded agents while preserving human control over editorial, legal, creative, commercial, and publication decisions.

October 15, 2026 · 8 min · Vox
Cover image

Policy Has to Run Somewhere: What Policy-as-Skill Changes in Governed LLM Systems

TL;DR for operators A policy-aware LLM has to do more than retrieve the right document. It must know what evidence is mandatory, when evidence is insufficient, when a case requires human review, which policy version governed the decision, and what information must be retained so the decision can later be reconstructed. Policy-as-Skill: Governed LLM Decision Support with Evidence, Deterministic Control, and Audit1 turns those obligations into explicit runtime components rather than leaving them inside prompts or application glue code. ...

October 9, 2026 · 6 min · Zelina
Cover image

The First Scribble Does Most of the Work

TL;DR for operators When an automated system can be corrected repeatedly, the product question is not simply whether correction helps. It is how many corrections are worth asking a user to make. Sherif and colleagues test that question in interactive multitracer PET/CT lesion segmentation.1 Mean Dice rises from 0.5539 with no correction to 0.7223 after one scribble and 0.7512 after five. Lesion-level F1 follows the same pattern: 0.5281, then 0.7036, then 0.7326. Roughly 85% of the five-round gain arrives after the first correction. ...

October 1, 2026 · 6 min · Zelina

From Fragmented Reports to a Match-Ready Operating Picture

A composite professional football club redesigns its between-match preparation cycle around six coordinated agents that retrieve, reconcile, and refresh evidence while coaches and clinicians retain all consequential decisions.

September 30, 2026 · 8 min · Vox
Cover image

From Pre-Audit to Proof: How Technical AI Earns More Decision Rights

TL;DR for operators Do not assign technical AI authority from a headline accuracy number. Use AI freely for repeatable first-pass checks where the rule is explicit and the cost of a false flag is low. Keep human experts responsible when the decision depends on system context, feasibility, architecture, necessity, or trade-offs. Where a claim can be rerun, make execution part of the evidence standard: a reproduced calculation deserves more weight than an unsupported model judgment. Even then, preserve review for interpretation, setup choices, and citations. ...

September 2, 2026 · 8 min · Zelina
Cover image

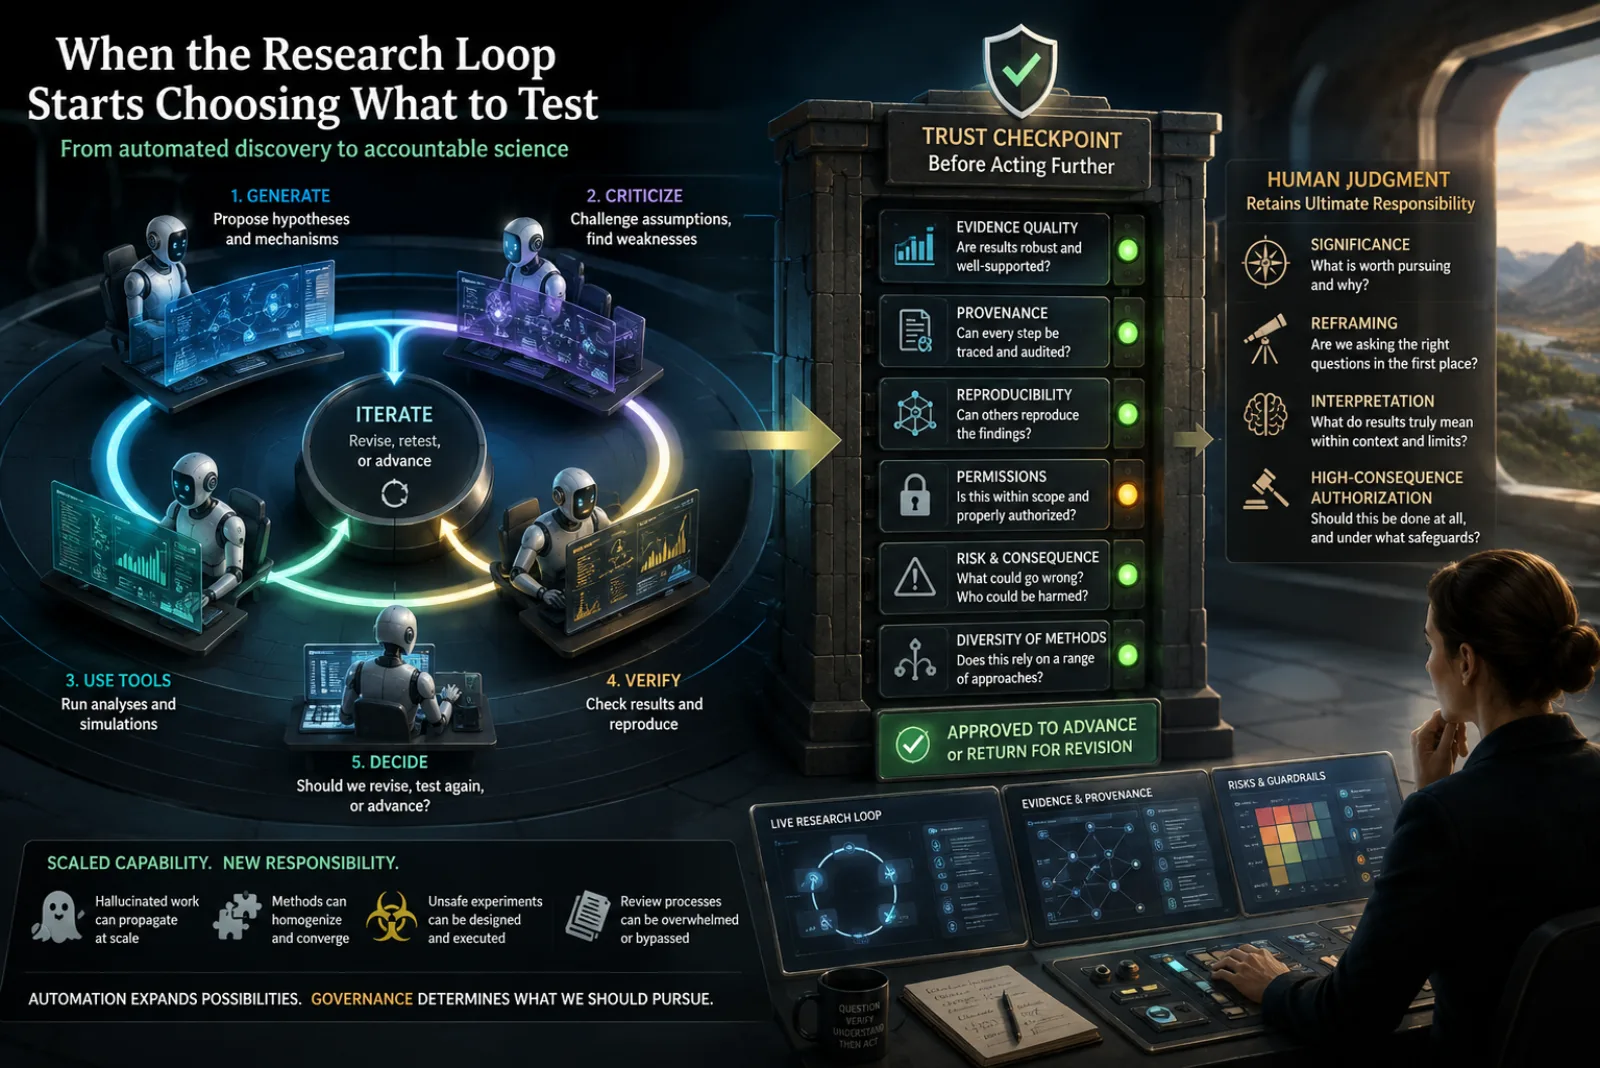
When the Research Loop Starts Choosing What to Test

TL;DR for operators A research assistant answers a question you give it. A more autonomous scientific system can propose a hypothesis, criticize it, run analyses, compare outcomes, and decide whether another iteration is warranted. Once these functions are coordinated, the operational unit is no longer a model call. It is a discovery loop. ...

September 2, 2026 · 7 min · Zelina

From Ticket Chasing to Evidence-Grounded Change Control

A regional colocation provider redesigns its change-control workflow around six specialized agents that assemble evidence and coordinate reviews while engineers retain all production authority.

August 30, 2026 · 9 min · Vox
Cover image

Take Over, Then Let Go: AutoIntervene Makes Robot Recovery a Training Signal

TL;DR for operators When an imitation-learned robot drifts outside the situations represented in its demonstrations, detecting that something looks unusual solves only half the operational problem. A deployment system must also decide when human takeover is warranted, when the recovery has progressed far enough to return control, and whether that intervention can improve the next policy rather than disappear as one-off operational labor. ...

August 22, 2026 · 8 min · Zelina

From Fab War Room to Evidence Loop: A Semiconductor Yield-Investigation Agent

A composite 300 mm specialty fab redesigned yield-excursion investigations around six evidence-grounded agents while retaining human authority over equipment, recipes, lot disposition, corrective actions, and production release.

August 15, 2026 · 8 min · Vox