TL;DR for operators
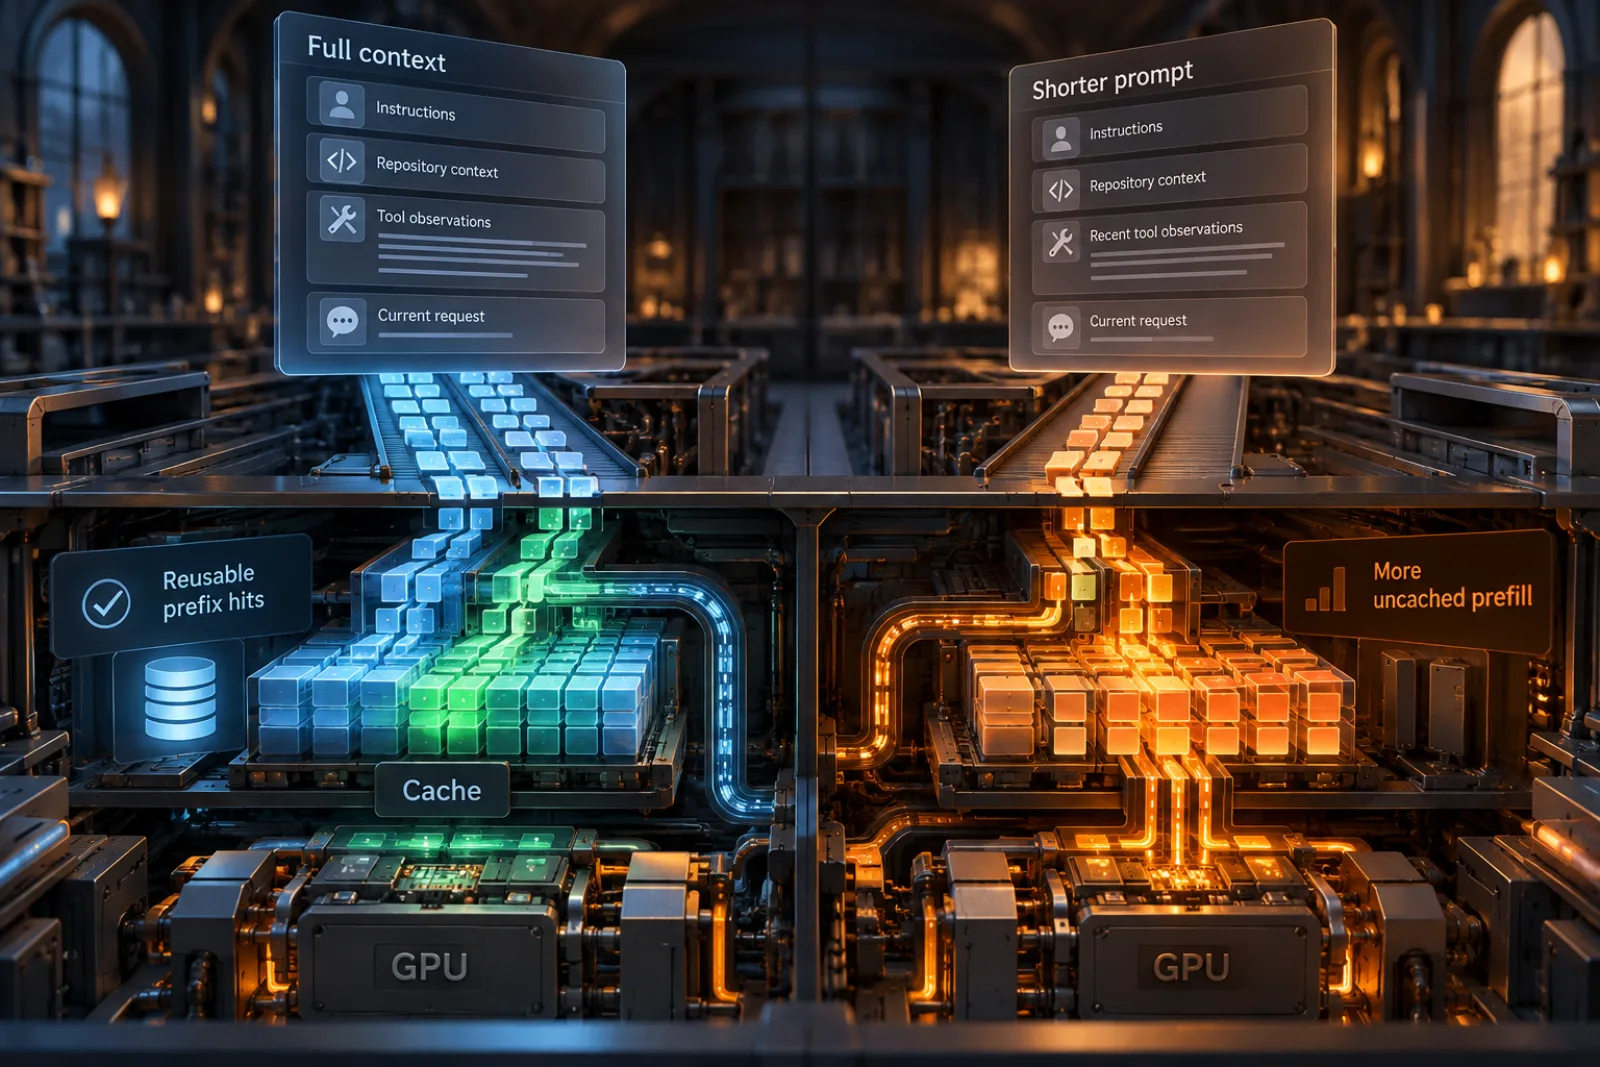
Reducing the conversation history sent to a coding agent can increase the computational work required to execute it. In one experiment, retaining only the five latest tool observations reduced logical prompt tokens by 33.3% but increased uncached input processing by 608.5% and the measured GPU-energy proxy by 125.6%.
Two mechanisms explain why token counts can mislead: context policies change how many model calls an agent makes, and editing earlier conversation content can eliminate computations that the serving system would otherwise reuse.
For coding-agent operators, the relevant efficiency measures include completed-task quality, model-call counts, uncached prefill, reusable-prefix hits, execution time, and GPU resources. Earlier delivery of useful repository evidence may save more work than aggressive history compression. Resource savings should also pass a predefined task-quality test before being accepted as improvements.
A shorter conversation that consumed more resources
A development team wants its coding agent to resolve repository issues faster. One proposed optimization removes old tool observations from the conversation. The model receives fewer tokens, so the team expects inference to become cheaper.
That expectation depends on how the model-serving system processes successive requests. Coding agents repeatedly submit overlapping conversation histories, and a serving runtime may reuse computations from earlier requests. Removing historical content changes not only the number of tokens submitted but also which computations remain reusable.
Zhongming Yu and colleagues examine this distinction in The Physical Cost of Context: Quality-Constrained Resource Accounting for Coding Agents.1
In an experiment covering 100 SWE-bench Verified software issues, the researchers compared an agent receiving ten initially retrieved repository code blocks (Eager) with one additionally retaining only its latest five tool observations (Mask-5).
Mask-5 reduced average logical prompt volume from 225,600 to 150,500 tokens per attempt. Yet the number of input tokens requiring fresh computation increased from approximately 10,000 to 70,800. Average execution time rose from 122.7 to 167.9 seconds, while the idle-subtracted GPU-energy proxy increased from 1.956 to 4.412 kJ.
| Metric | Mask-5 versus Eager |
|---|---|
| Logical prompt tokens | −33.3% |
| Uncached prefill | +608.5% |
| Wall-clock execution time | +36.9% |
| GPU-energy proxy | +125.6% |
| Resolved issues | 26 versus 29 of 100 |
Source: Section 4.3, Table 2. These comparisons concern patch generation under the external mini-SWE-agent configuration, not the paper’s separate localization experiments.
The smaller prompt was computationally more expensive to process. Understanding that reversal requires distinguishing logical context length from executed input work.
Prefix reuse changes the economics of prompt compression
When a language model processes input tokens, it constructs internal key-value (KV) representations used during attention. A serving runtime can cache these representations and reuse them when subsequent requests contain a matching prefix.
Coding agents are particularly relevant to this mechanism because successive requests often preserve most earlier messages while appending new observations.
The paper expresses the relationship as:
Here, $T_{\mathrm{prompt}}$ is the aggregate number of logical input tokens, $T_{\mathrm{hit}}$ counts tokens served through reusable cached prefixes, and $T_{\mathrm{uncached}}$ represents the remaining input tokens requiring prefill computation.
The equation applies across all requests in an agent trajectory. It accounts for executed input prefill, not every component of inference or system energy.
Consider what happens when an agent repeatedly removes observations from the middle of its accumulated history. Although the resulting prompt is shorter, the unchanged beginning shared with previous requests may also become shorter. A large amount of previously cached work can become unusable.
In the external experiment, Mask-5 removed approximately 75,100 logical prompt tokens per attempt, relative to Eager, but sacrificed approximately 135,900 reusable-prefix-hit tokens. The net difference was approximately 60,800 additional tokens requiring computation.
Reusable prefixes accounted for approximately 96% of Eager’s logical prompt tokens but only 53% of Mask-5’s.
This accounting directly explains the increase in uncached prefill. It does not establish that cache invalidation alone caused the entire energy increase: changes in agent trajectories and request composition can also contribute.
A controlled test confirms the importance of caching
The researchers separately conducted a 600-cell experiment using the same Qwen3.6-35B-A3B-FP8 model and vLLM runtime, changing only the prefix-caching setting.
Enabling caching for Eager reduced uncached prefill by 67.7%, with a paired 95% interval indicating reductions between 63.8% and 71.0%.
Logical prompt volume changed by an estimated +8.3%, but its confidence interval included zero. The experiment therefore supports a substantial caching benefit without establishing a corresponding change in logical token volume.
This same-model intervention strengthens the physical interpretation of prefix reuse. It should not be treated as a direct replication of the external masking experiment, which used a different model and serving stack.
Earlier evidence delivery can shorten the entire agent trajectory
Context management also influences agent decisions. A policy that supplies relevant evidence earlier may eliminate subsequent searches and model interactions, even when the initial prompt becomes longer.
The researchers tested three repository-localization policies:
- Grep: The agent searches repository code on demand.
- Eager: The agent begins with ten retrieved function or class blocks.
- Compact: The agent receives the same initial retrieved blocks as Eager, then performs a one-time anchored history rewrite after its first successful source read.
The retrieval candidates were frozen across the seeded conditions. This makes the Eager–Compact comparison particularly relevant for distinguishing history management from evidence selection.
In a cache-disabled resource experiment spanning 100 tasks, three policies, and three repetitions, Eager substantially reduced total execution work relative to Grep.
| Resource per attempted task | Grep | Eager | Compact |
|---|---|---|---|
| Prompt tokens | 136.8k | 90.5k | 98.2k |
| Successful server calls | 13.02 | 8.38 | 9.49 |
| Wall time | 68.32 s | 48.22 s | 52.20 s |
| GPU-energy proxy | 2.007 kJ | 1.340 kJ | 1.466 kJ |
Source: Section 4.1, Table 1. Resource measurements use the separate 900-cell localization cohort.
Relative to Grep, Eager reduced model-server calls by 35.7%, wall time by 29.4%, and GPU-energy proxy by 33.2%. Time-integrated KV occupancy also decreased by 35.6%.
The evidence supports an end-to-end benefit from earlier repository information delivery under the tested conditions. It does not establish how much of that benefit comes exclusively from reduced search behavior rather than other changes in agent execution.
Compact did not improve on Eager. It required 13.3% more calls and 9.4% more GPU-energy proxy, despite receiving identical initial retrieval candidates.
The authors suggest that history compaction may encourage renewed evidence retrieval. Because individual call intentions were not directly labeled, this remains a plausible mechanism rather than a separately verified causal result.
Resource savings must survive a quality test
A coding agent can reduce resource consumption by doing less useful work. For that reason, the paper requires candidate policies to demonstrate quality non-inferiority: the lower endpoint of a paired 95% confidence interval for the quality difference must remain above a five-percentage-point loss.
The localization-quality evaluation used 450 Python issues, each drawn from a distinct repository. Grep obtained answer-block Recall@5 of 0.470, compared with 0.478 for Eager and 0.494 for Compact.
Both treatments passed the non-inferiority gate. Their lower confidence endpoints were −2.6 and −0.9 percentage points, respectively. These findings support acceptable quality preservation, not statistically established superiority.
Crucially, the 450-case quality cohort and the 100-task physical-resource cohort were separate. Their results cannot be presented as joint quality-and-cost observations on the same 450 issues.
The external patch-generation experiment presents a different quality outcome. Eager resolved 29 of 100 issues, compared with 26 for Mask-5. Although the point difference was only −3 percentage points, its lower confidence endpoint reached −8.6 points.
Mask-5 therefore failed to establish non-inferiority under the paper’s five-point criterion. This is not proof that its true quality loss exceeds five points; it means the available evidence cannot rule out such a loss.
Its apparent token savings consequently fail both relevant tests: they do not produce physical-resource savings, and they do not satisfy the predefined quality requirement.
What coding-agent operators should measure
For teams managing local coding agents or instrumented inference services, Cognaptus draws three practical inferences.
First, evaluate context policies at the task level. Record successful and failed requests, model calls, logical and uncached input tokens, prefix-cache hits, wall time, and task outcomes. A lower average prompt length is insufficient when the policy changes the number of requests.
Second, test evidence-delivery and history-retention changes separately. Preloading high-value repository evidence can reduce repeated searches, while destructive rewrites of old observations may undermine cache reuse. Neither effect should be assumed without measurements from the intended runtime.
Third, account for retrieval infrastructure outside the inference loop. The study reports that constructing 25 repository indexes required 767.7 seconds and 36.1 kJ. At ten queries per snapshot, the amortized contribution was 3.07 seconds and 0.144 kJ per query. Deployments with lower query reuse would face a different allocation of setup cost.
These recommendations do not imply that all summarization or external-memory approaches are inefficient. The experiments test specific fixed compaction and masking operations, not the broader design space of agent memory.
Where the measurements stop
The experiments ran on a single NVIDIA DGX Spark with 128 GB of unified memory, admitting one measured request at a time. Multi-user serving, batching, and cloud accelerator environments could have different cache pressure and throughput characteristics.
The external patch study also changed the model, agent scaffold, and serving runtime relative to the localization experiments. Within-study comparisons are informative; numerical differences across those stacks cannot be assigned to a single component.
Some physical-resource confidence intervals relied on only three telemetry shards, while peak-memory measurements were too noisy to support firm device-capacity conclusions.
Finally, the reported energy quantities are idle-subtracted GPU estimates derived from sampled power. They exclude CPU and other whole-system consumption. They are not direct measurements of electricity bills or cloud-provider charges.
Optimize executed work, not just transmitted context
The paper changes the appropriate unit of comparison for coding-agent context management. A context policy affects both the sequence of actions an agent performs and the computations its serving runtime can reuse.
The tested results favor early delivery of relevant repository evidence over either on-demand search or the particular compaction policy examined in localization. They also establish a consequential failure mode for aggressive observation masking: fewer logical tokens can coincide with substantially more executed input work.
For coding-agent operators, the more defensible objective is to minimize measured resources among policies that preserve acceptable task quality, using the actual workload and serving environment rather than prompt length as a proxy.
Cognaptus: Automate the Present, Incubate the Future.
-
Zhongming Yu and Yitong Ma and Hengjia Yu and Boqin Yuan and Xiangye Lin and Hejia Zhang and Jishen Zhao (2026). The Physical Cost of Context: Quality-Constrained Resource Accounting for Coding Agents. arXiv:2610.34763. https://arxiv.org/abs/2610.34763 ↩︎