Cover image

When Shorter Prompts Require More Compute

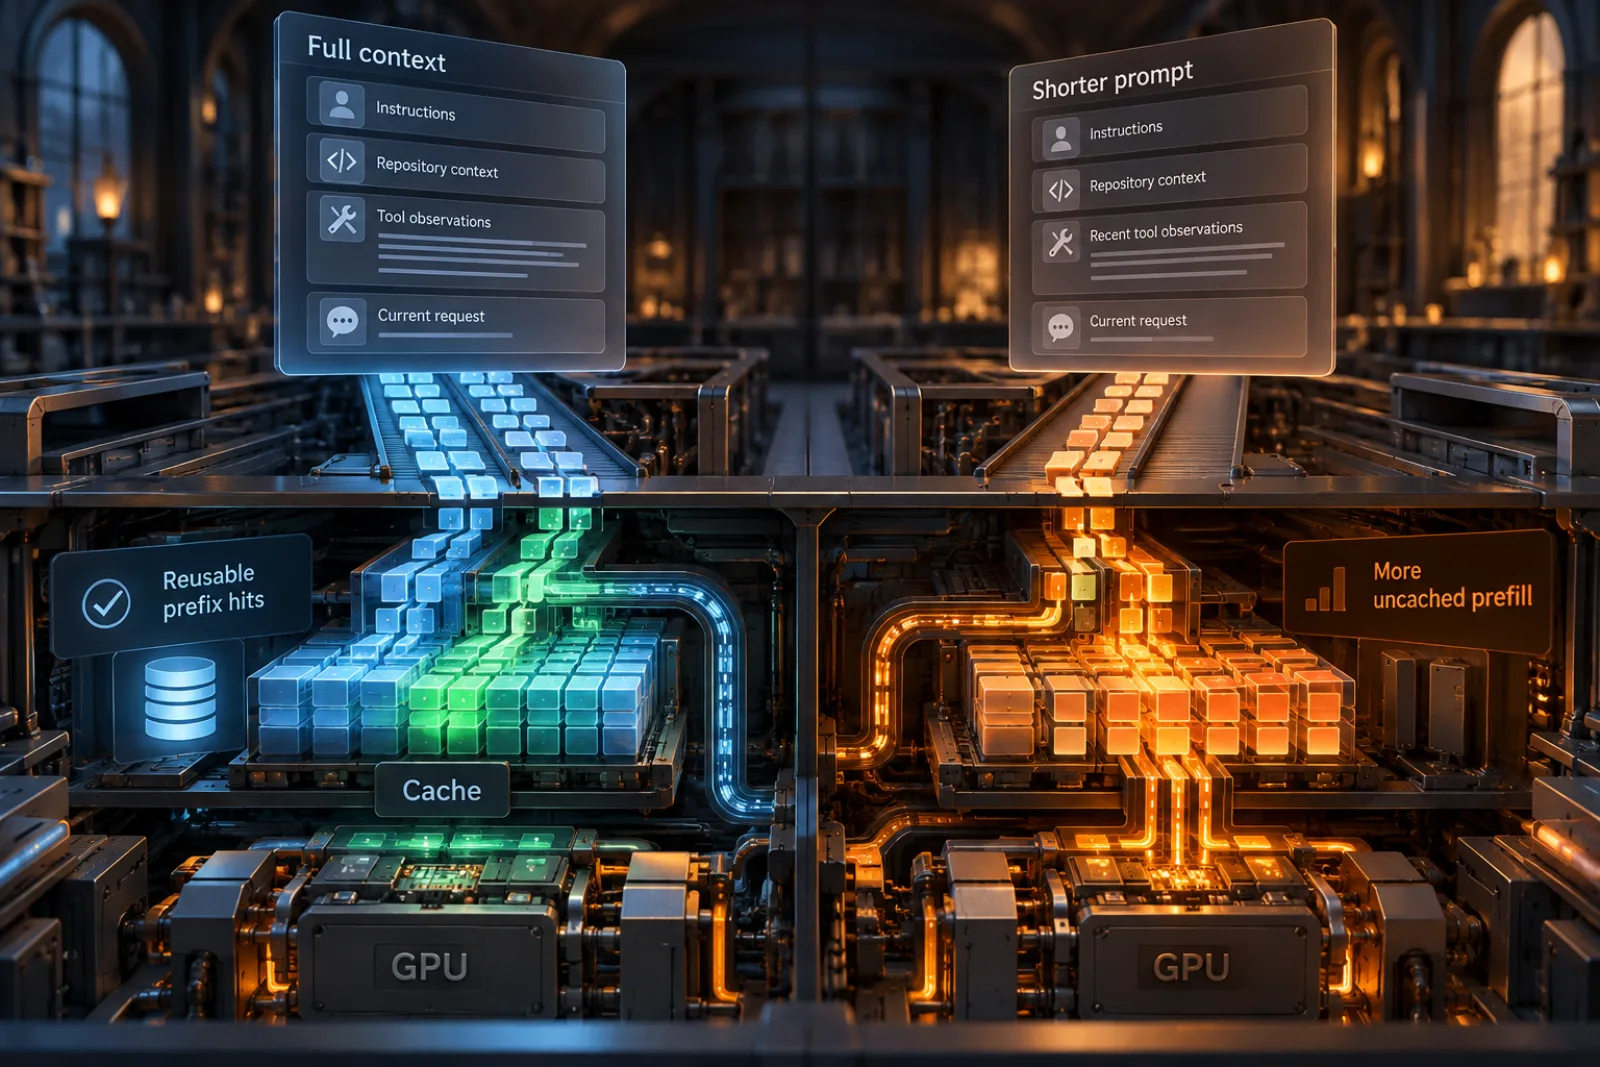
TL;DR for operators Reducing the conversation history sent to a coding agent can increase the computational work required to execute it. In one experiment, retaining only the five latest tool observations reduced logical prompt tokens by 33.3% but increased uncached input processing by 608.5% and the measured GPU-energy proxy by 125.6%. Two mechanisms explain why token counts can mislead: context policies change how many model calls an agent makes, and editing earlier conversation content can eliminate computations that the serving system would otherwise reuse. ...
October 28, 2026 · 9 min · Zelina
Cover image

Passing the Tests, Missing the Handoffs

TL;DR for operators A multi-agent coding workflow can pass most repository tests while still failing at the interfaces where one agent’s code depends on another’s. AsynCodeBench1 makes those handoffs explicit: it pre-registers directed software dependencies, checks them after integration, measures final dependency satisfaction with Asynchronous Dependency Pass Rate (ADPR), and records first resolution with Dependency Resolution Step (DRS). ...

October 21, 2026 · 7 min · Zelina
Cover image

The LLM Is Not the Converter

TL;DR for operators An engineering team migrating behavior logic between control architectures has two separate problems: understanding what an existing specification means, and reproducing that behavior without losing a branch, loop, transition, or termination condition. Automating the first problem is relatively easy to imagine. Trusting automation with the second is harder because a plausible-looking conversion can still change executable behavior. ...

October 14, 2026 · 7 min · Zelina
Cover image

Not Every Passing Patch Deserves the Same Credit

TL;DR for operators A code agent can produce two patches that pass the same tests while differing sharply in precision, scope, side effects, and consistency with the repository. Gagar1 keeps executable tests as the success gate, but adds an agentic grader to rank the quality of successful implementations. The less obvious contribution is what happens after grading. Simply reducing the reinforcement assigned to weaker successful trajectories also reduces the group’s total positive credit. In the paper’s ablation, that design was accompanied by much faster growth in policy entropy and rollout length. Gagar instead redistributes positive advantage so better successful trajectories receive more relative credit while the original positive-credit total is preserved in the exact formulation. ...

October 12, 2026 · 8 min · Zelina
Cover image

The Library Is Only as Good as the Code It Removes

TL;DR for operators In Can Agents Design Libraries for Agents?1, the strongest evaluated agent-designed library condition scores 48.9, compared with 46.6 for production libraries and 34.4 with no library. That result is less a story about agents implementing more functionality than about whether a reusable abstraction actually removes work from the programs written later. ...

October 3, 2026 · 8 min · Zelina
Cover image

Memory Has to Earn Its Keep

TL;DR for operators Memory is not valuable because an agent writes something down. That is called logging. Sometimes it is called “reflection,” if the logging has better branding. The paper Enhancing Software Engineering Through Closed-Loop Memory Optimization introduces MemOp, a framework for software-engineering agents that defines memory utility by downstream impact: a memory is useful only if it improves the agent’s later performance on software tasks.1 The important move is not the existence of Memory.md, nor the idea that past trajectories can be summarized. The important move is the loop: generate memory from an agent trajectory, validate whether that memory improves task performance, reject harmful or redundant memories, and train a memory model using the resulting accepted and rejected examples. ...

June 27, 2026 · 17 min · Zelina
Cover image

The Code Agent Wasn’t Self-Correcting. The Test Harness Was.

TL;DR for operators Code agents do not become reliable because they are asked politely to “fix the bug.” They become more useful when they are placed inside a loop that can run their output, return structured failure evidence, and decide how many further attempts are worth buying. That is the practical point of Zhang and Kothari’s paper, Unlocking LLM Code Correction with Iterative Feedback Loops.1 The authors evaluate four LLMs across Python and Java using LeetCode problems, then move from ordinary one-shot performance to an automated correction loop: generate code, execute it, feed back compiler/runtime/testcase information, and repeat up to ten iterations. ...

June 22, 2026 · 17 min · Zelina
Cover image

Compile Once, Train Later: Offline RL Moves Code-Model Verification Upstream

Compile Once, Train Later: Offline RL Moves Code-Model Verification Upstream Code assistants have a small accounting problem. Not the glamorous kind involving model capability, agentic workflows, or yet another dashboard with a glowing neural blob. The ordinary kind: every time a model proposes code during reinforcement learning, someone—or something—has to run it, test it, score it, and feed that score back into training. ...

June 3, 2026 · 14 min · Zelina
Cover image

Memory Lane Meets Mainframe: Why Coding Agents Need Better Memories, Not Bigger Egos

Memory is a familiar word. That is exactly why it can mislead us. When people hear that coding agents need “memory,” the first image is often a giant scrapbook: past prompts, previous patches, command logs, successful code snippets, failed attempts, and whatever else the agent has dragged behind it like a very confident intern with a messy backpack. More memory sounds safer. More traces sound more useful. More remembered work sounds like less repeated work. ...

April 16, 2026 · 17 min · Zelina
Cover image

Thinking Fast, Remembering Slow: Why SWE-AGILE Fixes the Memory Crisis of AI Agents

Memory sounds like a storage problem. Give the agent a longer context window, let it keep the full conversation, and the work should become easier. This is the kind of solution that looks obvious until it meets a real software repository, a failing test suite, a long terminal log, and a model that now has to find one important clue buried somewhere in the middle of its own autobiography. ...

April 14, 2026 · 18 min · Zelina