When Shorter Prompts Require More Compute
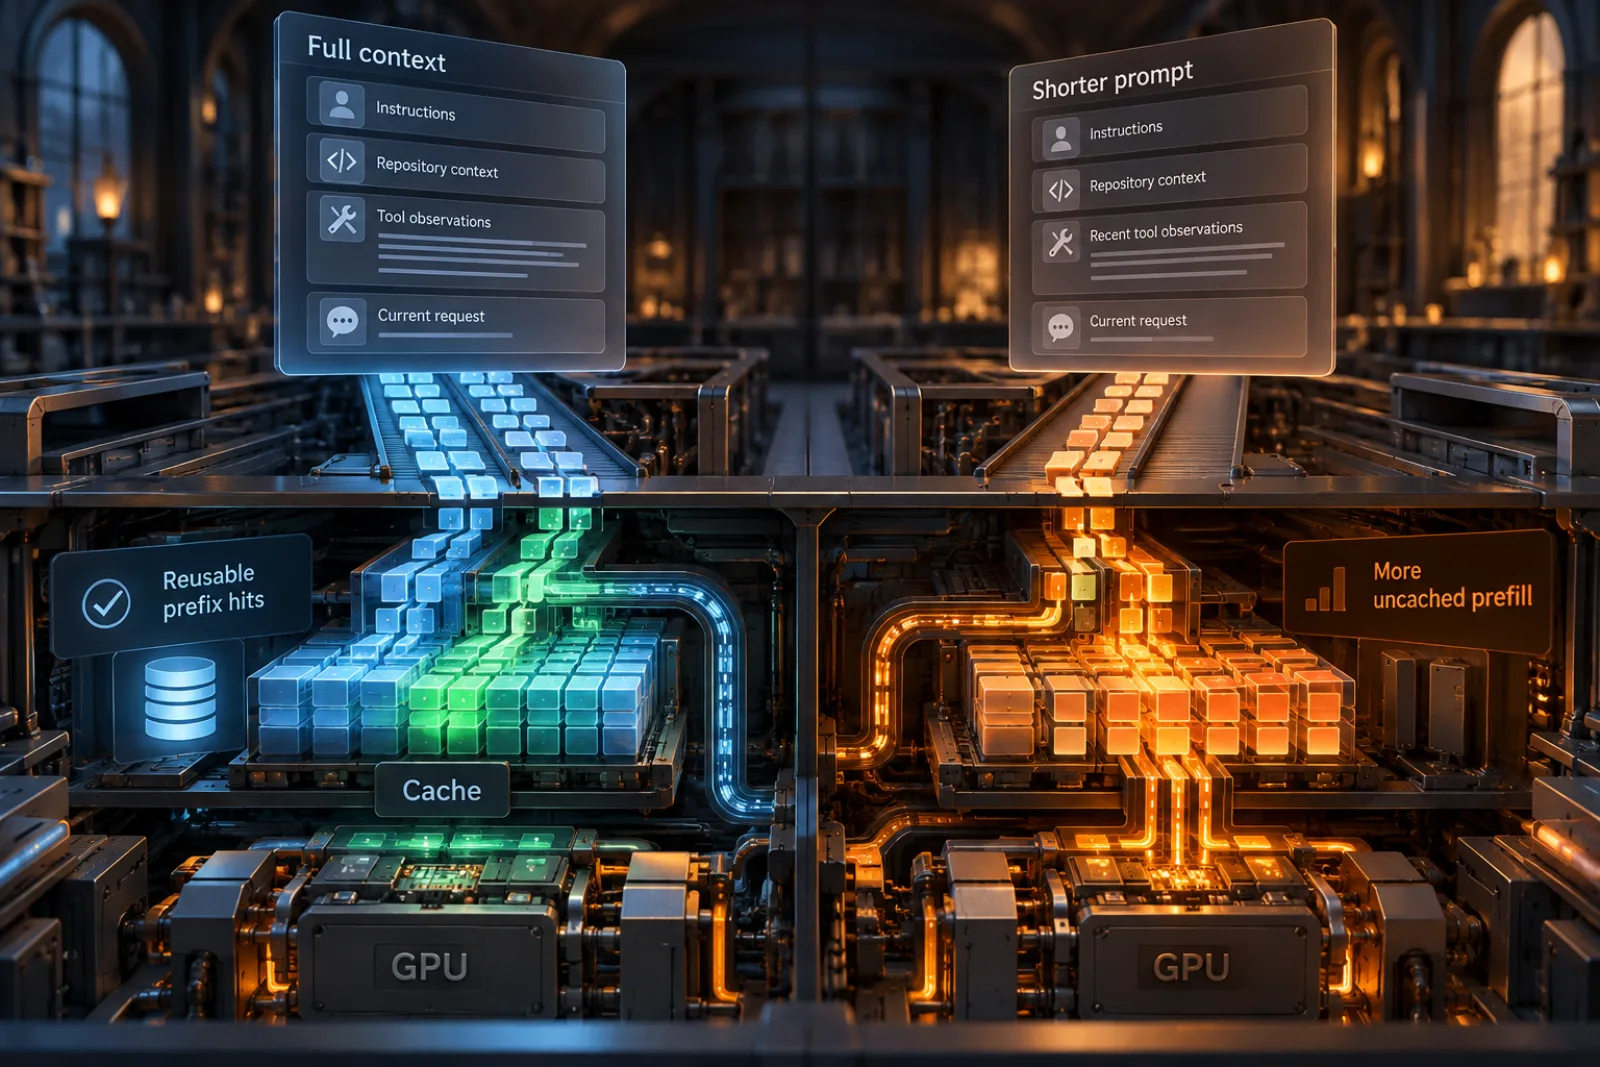
TL;DR for operators Reducing the conversation history sent to a coding agent can increase the computational work required to execute it. In one experiment, retaining only the five latest tool observations reduced logical prompt tokens by 33.3% but increased uncached input processing by 608.5% and the measured GPU-energy proxy by 125.6%. Two mechanisms explain why token counts can mislead: context policies change how many model calls an agent makes, and editing earlier conversation content can eliminate computations that the serving system would otherwise reuse. ...