Cover image

When Shorter Prompts Require More Compute

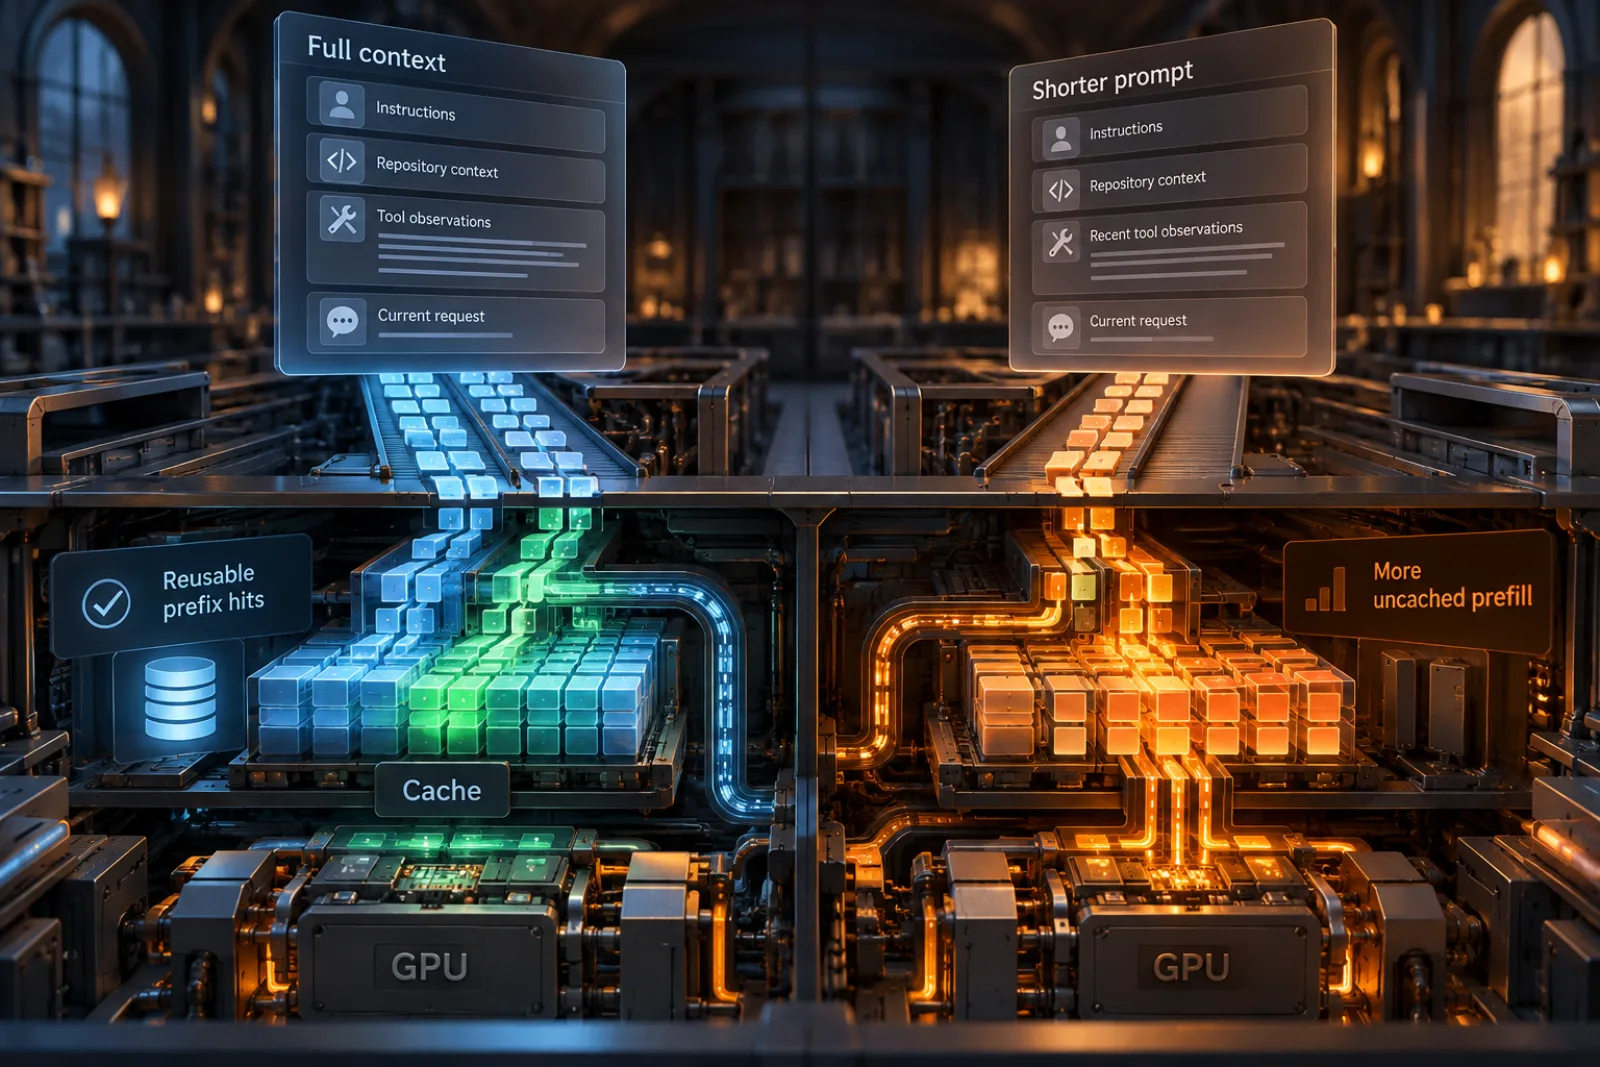
TL;DR for operators Reducing the conversation history sent to a coding agent can increase the computational work required to execute it. In one experiment, retaining only the five latest tool observations reduced logical prompt tokens by 33.3% but increased uncached input processing by 608.5% and the measured GPU-energy proxy by 125.6%. Two mechanisms explain why token counts can mislead: context policies change how many model calls an agent makes, and editing earlier conversation content can eliminate computations that the serving system would otherwise reuse. ...
October 28, 2026 · 9 min · Zelina
Cover image

Same Frame, Different Progress: Why Robot Monitors Need Verified Context

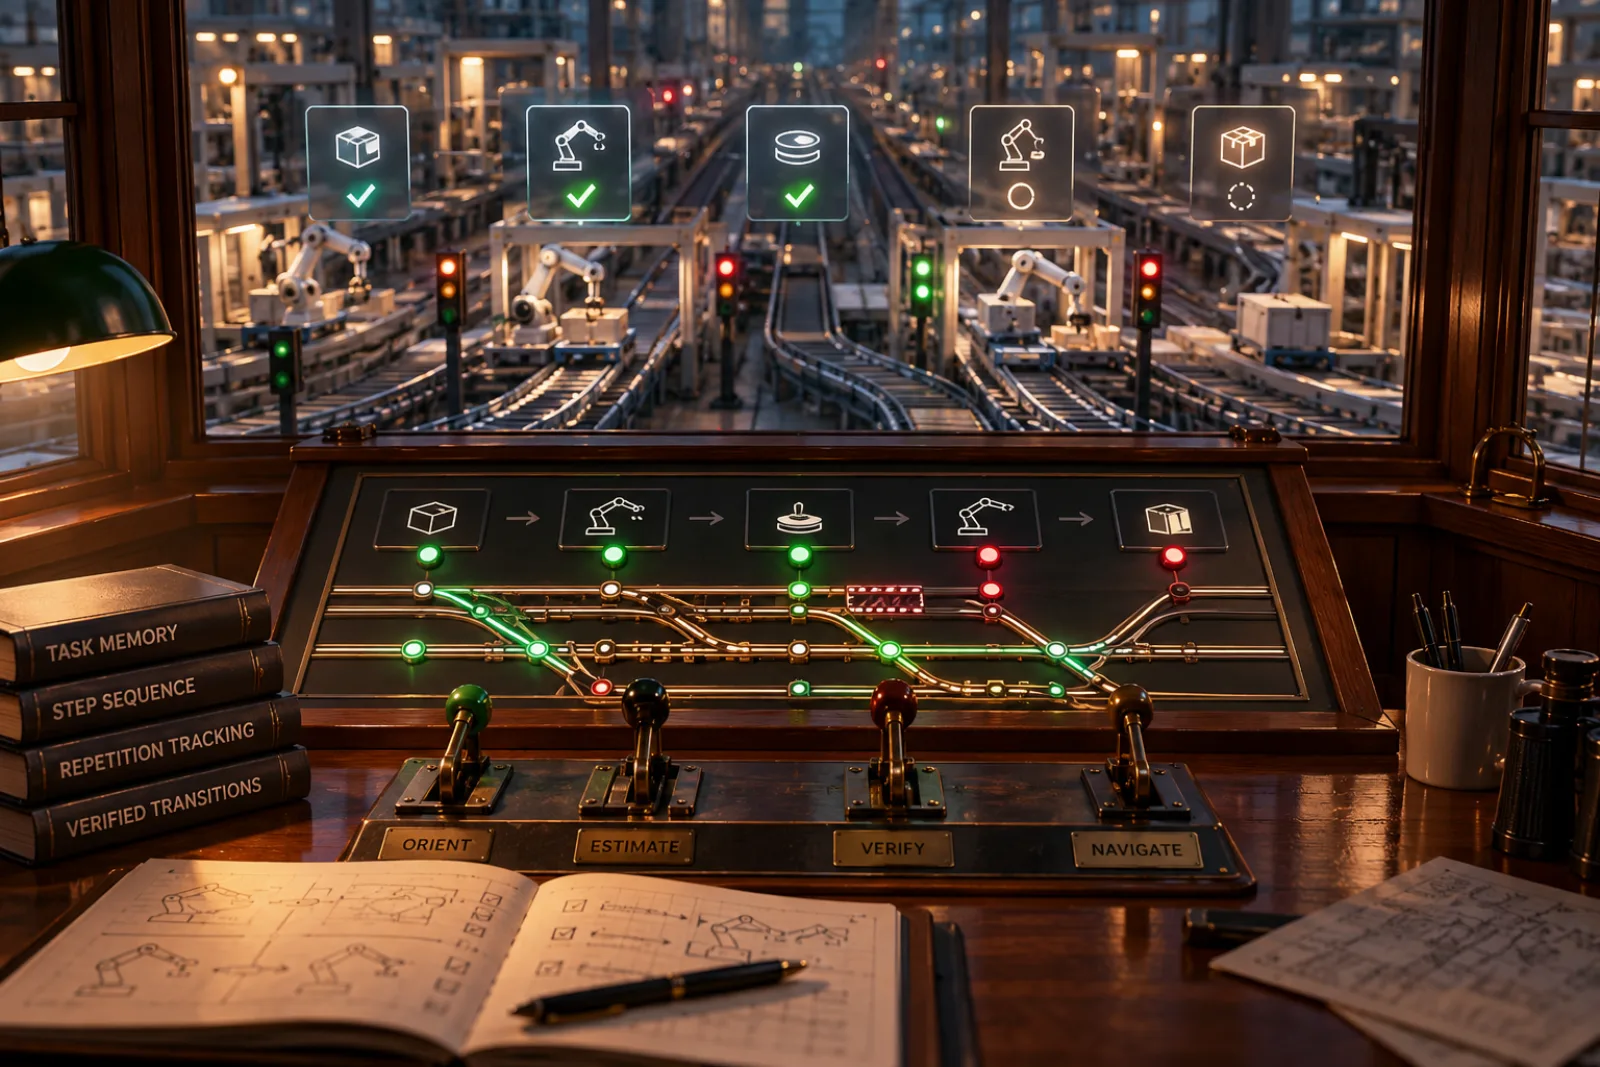
TL;DR for operators A robot’s current camera view may show what it is doing without revealing how much of its assigned task it has completed. In a paired evaluation of five frozen progress reward models, supplying the correct active-subtask context reduced mean absolute progress error by 77–82%. The improvement occurred on 93.3% of annotated subtask intervals. These results come from manually supplied context, not autonomous inference.1 ...

October 24, 2026 · 8 min · Zelina
Cover image

When Silence Is Not a Turn: Voice AI Needs a Control Plane

TL;DR for operators A production voice agent has to decide more than what to say. It has to decide whether a pause means the user finished speaking, whether response pacing should change, which earlier constraints still matter, and how much historical audio is worth sending back to the model. Scalable Context Orchestration for Serving LLMs Over Voice1 treats those decisions as a separate systems layer. Its llmovoice middleware explicitly tracks semantic, speech-delivery, and environmental state; organizes completed interactions into persistent memory structures; and projects only a bounded, relevance-weighted portion of history into the serving model. ...

October 9, 2026 · 8 min · Zelina
Cover image

The Catalog Grew. The Agent Needed a Call Stack.

TL;DR for operators As an agent’s tool catalog grows, it must solve two linked problems: choosing the right capability without carrying every tool schema into each decision, and remembering where to return after several nested actions. The paper’s hierarchy addresses both by showing the model only the options relevant to its current branch and storing nested workflow state explicitly. ...

August 3, 2026 · 9 min · Zelina
Cover image

Mask, Don’t Muse: When Simple Memory Beats Fancy Summaries

TL;DR for operators A coding agent’s memory problem is not philosophical. It is a bill. The paper behind this article compares three ways to manage context in software-engineering agents: keep the full trajectory, summarize old turns with an LLM, or simply mask older environment observations while preserving the agent’s reasoning and actions.1 Across five SWE-agent configurations on SWE-bench Verified, both context-management strategies usually cut cost sharply versus the Raw Agent. The awkward part is that the simple strategy, Observation Masking, is often just as good as LLM-Summary on solve rate and usually cheaper. ...

September 1, 2025 · 17 min · Zelina