Cover image

From Agent Traces to Steering Signals—Without Fine-Tuning

TL;DR for operators A capable AI agent encounters a tool error, adjusts its approach, and eventually completes a workflow. A smaller agent attempting the same task may fail. Improving the smaller agent does not necessarily require training it to imitate the entire successful execution. REVEAL1 converts textual histories of successful and failed frontier-agent runs into activation controls constructed inside a frozen target model. On Terminal-Bench 2.1, it raises Qwen3.6-27B accuracy from 33.71% to 39.33%, compared with 35.96% after trajectory supervised fine-tuning (SFT). Its average online input-token consumption is also 35.60% lower than SFT. ...
November 2, 2026 · 7 min · Zelina
Cover image

When Shorter Prompts Require More Compute

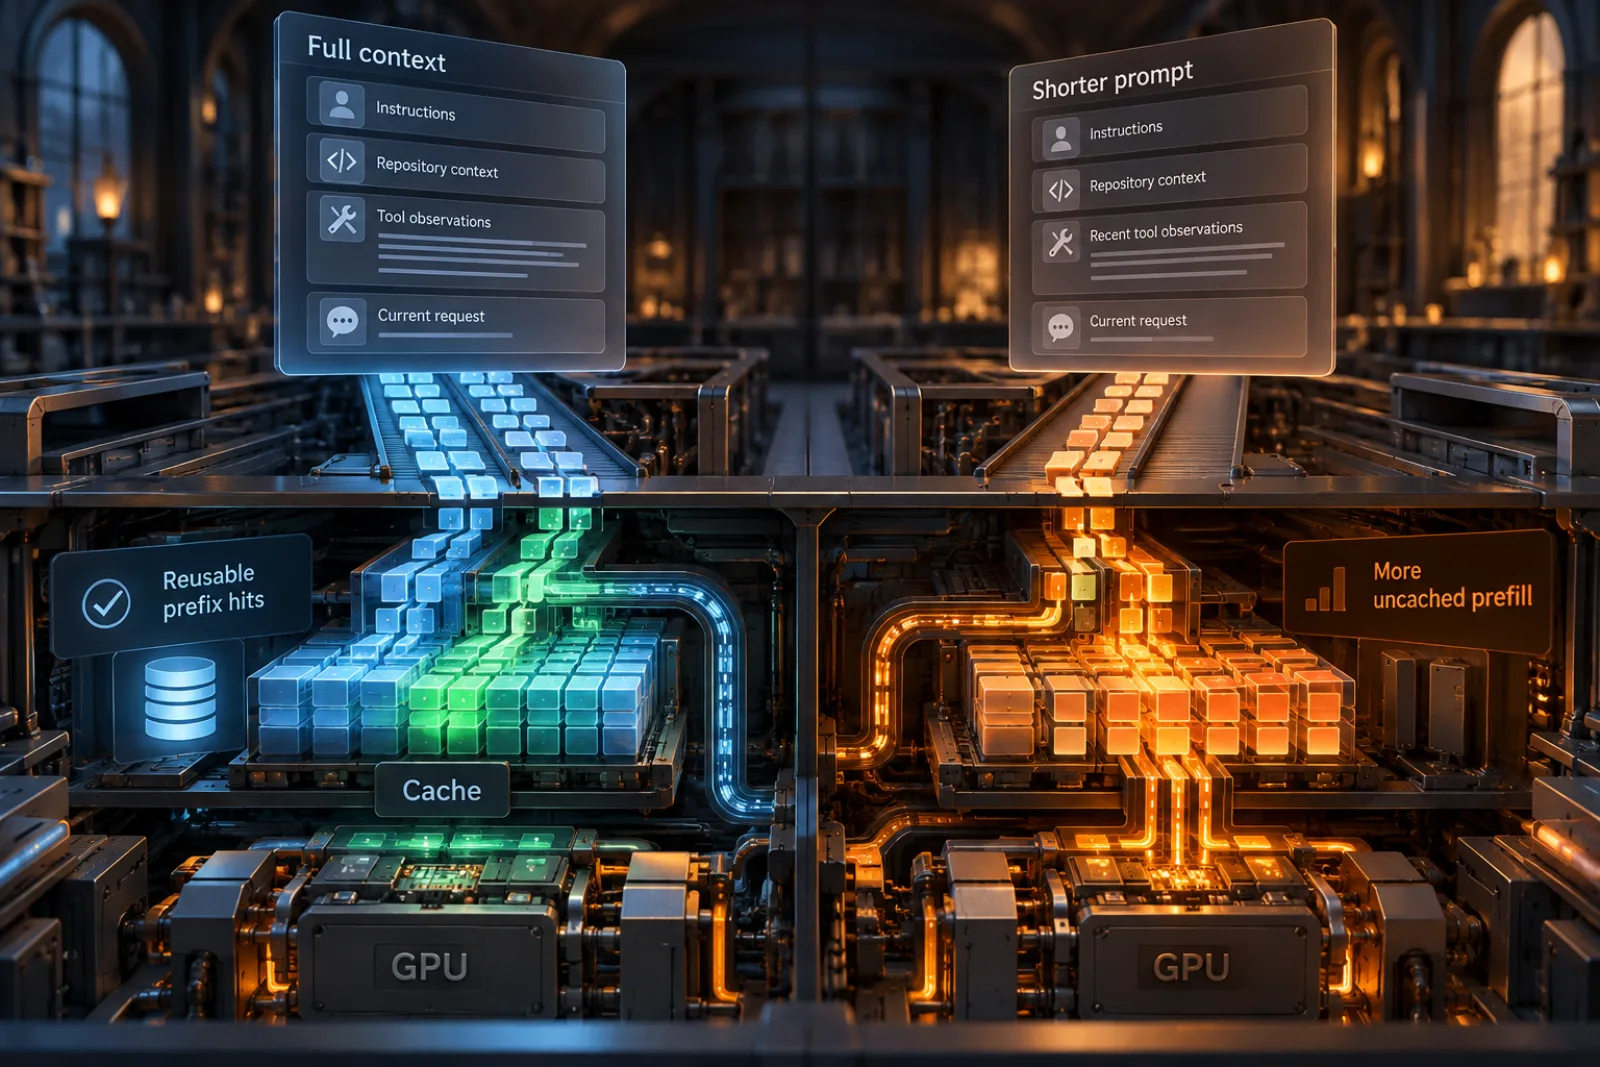
TL;DR for operators Reducing the conversation history sent to a coding agent can increase the computational work required to execute it. In one experiment, retaining only the five latest tool observations reduced logical prompt tokens by 33.3% but increased uncached input processing by 608.5% and the measured GPU-energy proxy by 125.6%. Two mechanisms explain why token counts can mislead: context policies change how many model calls an agent makes, and editing earlier conversation content can eliminate computations that the serving system would otherwise reuse. ...

October 28, 2026 · 9 min · Zelina
Cover image

Five Steps Change the Cost Curve of Crystal Structure Prediction

TL;DR for operators When a materials-screening pipeline must generate structures for thousands of compositions, the practical question is not only which model is most accurate, but how many sequential model calls are required to obtain that accuracy. Dey and colleagues’ uFlowCSP1 shifts that tradeoff sharply. On MP-20 with 20 candidates, five-step uFlowCSP reaches an 83.64% match rate using 100 model calls, compared with 78.34% for CrystalFlow using 2,000 and 77.93% for DiffCSP using roughly 20,000. Even one-step uFlowCSP reaches 78.38% with only 20 calls. ...

October 15, 2026 · 6 min · Zelina
Cover image

Long Context Without a Long Chain

TL;DR for operators Serving longer contexts usually creates an uncomfortable architectural choice. Attention keeps training and inference highly parallel but makes pairwise token interaction increasingly expensive as the sequence grows. Conventional recurrence reduces that interaction cost but makes later positions wait through a sequential chain. The paper studies a third computation pattern. Its AR-GRC model organizes recurrence as a balanced tree, producing all autoregressive prefix representations with $O(\log N)$ computational depth and $O(N)$ total composition work. In the reported measurements, evaluation time grows approximately linearly with context length. The model also preserves stable perplexity when moved from a maximum training context of 512 tokens to evaluation sequences as long as 2,976 tokens. ...

October 10, 2026 · 7 min · Zelina
Cover image

The Guard Is Already in the Draft: Reusing Speculative Decoding for LLM Monitoring

TL;DR for operators Production monitoring often creates an unattractive choice. A small probe is cheap enough to run on every request but may compress away evidence that occurred earlier in a sequence. A stronger position-aware classifier preserves more information but adds computation to an inference path that is already expensive. Speculative Probing: LLM Monitoring at Speculative-Decoding Cost1 asks whether part of that cost has already been paid. Some LLM deployments use a smaller auxiliary prediction component to accelerate generation. Speculative Probing reuses that component—its speculative-decoding head—as a frozen feature extractor for monitoring. The base model and draft head remain unchanged; only a few learned task-specific query vectors and a small classifier are trained. ...

September 28, 2026 · 8 min · Zelina
Cover image

Don’t Give Every Query the Same Context Budget

TL;DR for operators A retrieved prompt can contain one useful sentence or evidence distributed across several passages. Giving both requests the same compressed-context budget assumes that the amount of information worth preserving is constant. The evidence in ATACompressor1 suggests that assumption is costly: on MSMARCO with LLaMA-2-7B, removing adaptive allocation reduced F1 from 50.06 to 47.52 and compression ratio from 27.36x to 19.06x; removing selective compression reduced F1 further to 40.83. ...

September 20, 2026 · 7 min · Zelina
Cover image

Don’t Reason Over Every Token: LycheeMemory Turns Long Context Into a Budget

TL;DR for operators When a system receives hundreds of thousands of tokens, the expensive part is not only fitting the evidence into memory. It is deciding how much reasoning effort each part deserves. Processing every chunk with the same autoregressive budget preserves more opportunity to use evidence, but it also spends latency and GPU time on material that may never matter. ...

September 20, 2026 · 5 min · Zelina
Cover image

Memory Has a Budget: Compress Long-Running Context by Value, Not Age

TL;DR for operators Fofadiya and Tiwari propose a context-management system for long-running LLM interactions that does more than summarize old conversations.1 It scores historical turns by relevance, recency, dialogue dependency, and coherence, then applies a three-level policy: retain high-value turns verbatim, summarize medium-value turns, and remove low-value history when the context budget requires it. ...

September 19, 2026 · 6 min · Zelina
Cover image

More Retrieval Is Not Free: Price Every RAG Component Before You Ship It

TL;DR for operators When a knowledge-grounded assistant needs improvement, adding another retrieval stage is not automatically the safest use of inference budget. In this study, the most expensive retrieval option in the matched comparison—combining semantic and keyword-based search—reduced accuracy by 1.85 percentage points relative to dense retrieval while adding 3,079.69 seconds of runtime across the evaluation run. More machinery produced a worse benchmark result. ...

September 18, 2026 · 7 min · Zelina
Cover image

Give the Quiet Experts More Bits

TL;DR for operators A fixed MoE memory budget does not tell you which experts can safely absorb the lowest precision. Efficient Quantization of Mixture-of-Experts with Theoretical Generalization Guarantees1 argues that the experts most frequently or strongly used are not necessarily the ones that need the most bits. In its theory, experts associated with less-prevalent but still task-relevant features develop weaker activations and smaller router-norm changes, leaving less margin for quantization error. ...

September 11, 2026 · 6 min · Zelina