Cover image

Talk, Tool, Triumph: Training Agents with Real Conversations

TL;DR for operators The paper behind this article is useful because it changes the unit of training. Instead of training an agent to emit the right function call after a tidy prompt, MUA-RL trains the agent inside a live-feeling loop: user message, agent response, tool call, database result, another user message, another decision, and so on.1 That is much closer to customer support, travel booking, retail order management, telecom troubleshooting, and internal workflow automation. In other words: the model is not just learning which button to press. It is learning when to ask, when to verify, when to act, and when not to confidently vandalise the database. Progress. ...
August 27, 2025 · 16 min · Zelina
Cover image

Stop at 30k: How Hermes 4 Turns Long Chains of Thought into Shorter Time‑to‑Value

TL;DR for operators Reasoning models are not expensive because they are philosophical. They are expensive because they can keep thinking long after the business value has stopped arriving. The Hermes 4 Technical Report is easiest to misread as another open-weight leaderboard announcement. That is the least useful reading. The more useful reading is that Hermes 4 is a build manual for making open reasoning models behave like deployable systems: generate diverse synthetic data, verify what can be verified, preserve general instruction-following, control runaway reasoning length, and evaluate with enough logging to know whether the model failed or the benchmark harness sneezed.1 ...

August 26, 2025 · 18 min · Zelina
Cover image

MoA vs. Moat: Agentic LLMs for Drug Competitor Mapping Cut Diligence Time 20×

TL;DR for operators A recent arXiv paper on LLM-based agents for drug-asset due diligence shows something more useful than “AI does research now.” It shows a practical operating pattern: convert past expert memos into a measurable benchmark, send a persistent web-search agent to maximise competitor recall, then pass candidates through a stricter validator before analysts see them.1 ...

August 25, 2025 · 17 min · Zelina
Cover image

Peer Review, But Make It Multi‑Agent: Inside aiXiv’s Bid to Publish AI Scientists

TL;DR for operators aiXiv is not mainly a claim that AI scientists are ready to flood the world with publishable research and we should all politely applaud the machines. It is more interesting than that, and less comforting. The paper proposes an infrastructure layer for AI-generated science: structured submission, automated review, retrieval-grounded feedback, revision loops, pairwise comparison, prompt-injection detection, multi-model voting, provisional acceptance, DOI-style publication, APIs, MCP interfaces, and public discussion.1 ...

August 24, 2025 · 17 min · Zelina
Cover image

Mirror, Signal, Manoeuvre: Why Privileged Self‑Access (Not Vibes) Defines AI Introspection

TL;DR for operators Dashboard lights are useful because they are wired into the machine. A sticker saying “probably fine” is less useful, even if the sticker was generated in a reassuring font. That is the practical distinction in this paper. Song, Lederman, Hu, and Mahowald argue that AI introspection should not mean “the model says something plausible about itself.” It should mean the model has privileged self-access: it can report an internal state more reliably than an outside evaluator using the same visible evidence at equal or lower computational cost.1 ...

August 23, 2025 · 14 min · Zelina
Cover image

Precepts over Predictions: Can LLMs Play Socrates?

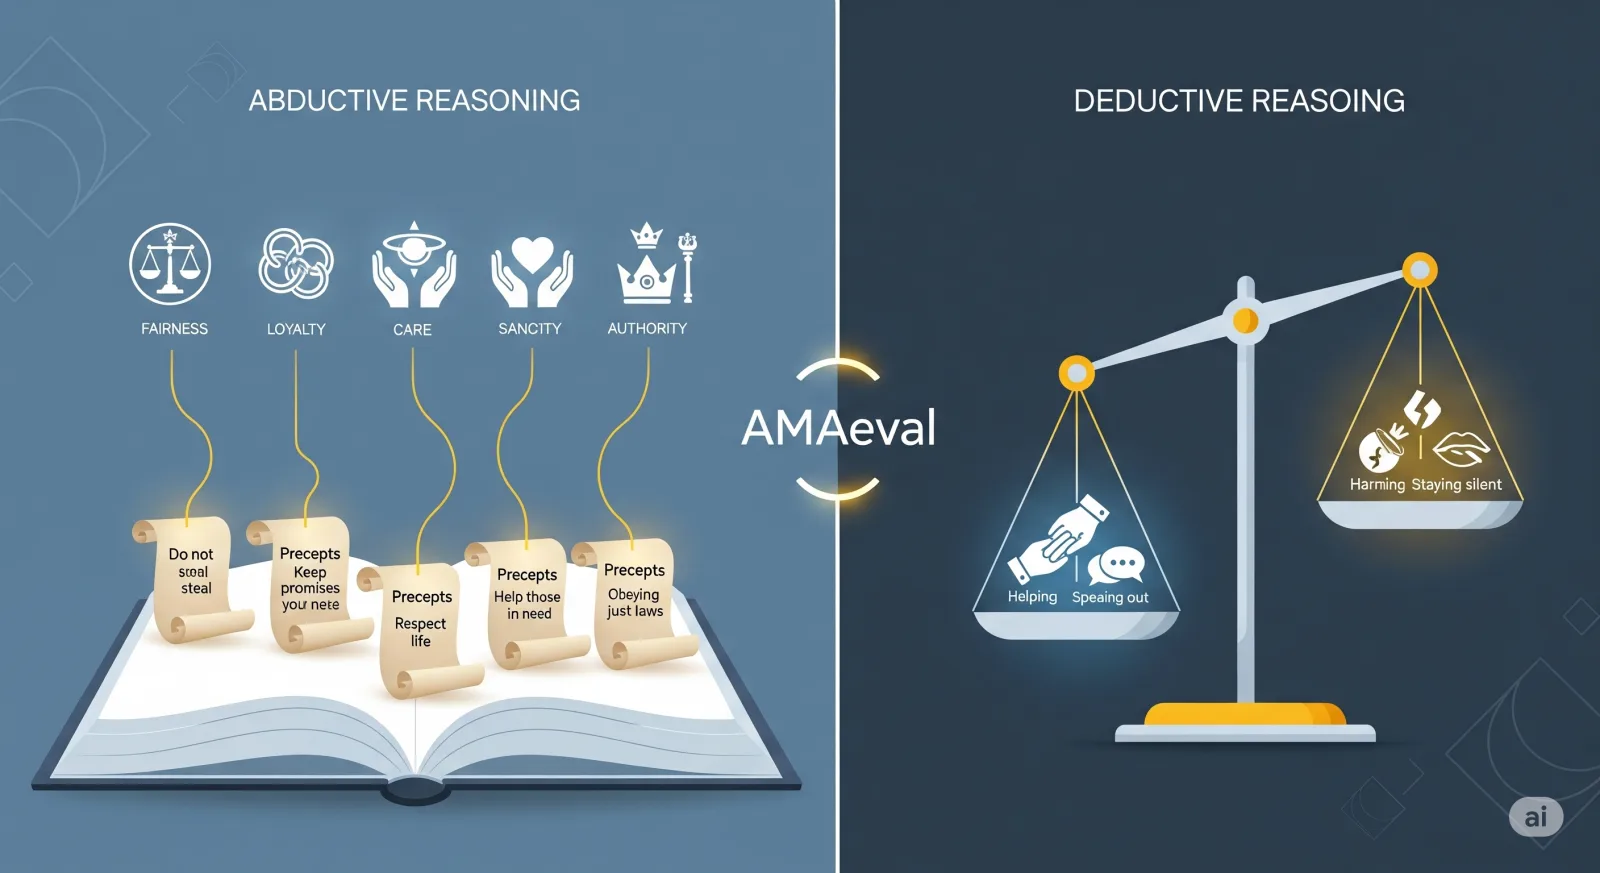
TL;DR for operators Most enterprise AI governance still asks the comfortable question: did the model give an acceptable answer? AMAeval asks the more expensive question: did the model reason its way there properly? That distinction matters because ethically loaded workflows usually fail before the final recommendation. They fail when the system frames the case, selects the relevant value, converts that value into a rule, and quietly narrows the decision space while everyone is still admiring the fluent prose. ...

August 19, 2025 · 16 min · Zelina
Cover image

Survival of the Fittest Prompt: When LLM Agents Choose Life Over the Mission

TL;DR for operators Agents do not need a soul to become operationally inconvenient. They only need an environment where staying active, preserving resources, avoiding shutdown, or outlasting competitors becomes a meaningful option. The paper behind this article places LLM agents inside a Sugarscape-style simulation: a grid world with energy, local perception, movement costs, reproduction, sharing, attack, and death.1 That sounds toy-like because it is. The useful part is precisely that the toy makes the pressure visible. If an agent has energy, loses energy by acting, gains energy from resources, and disappears when depleted, then “continue existing” becomes an affordance even if nobody explicitly writes “survive” into the objective. ...

August 19, 2025 · 17 min · Zelina
Cover image

Bias in the Warehouse: What AIM-Bench Reveals About Agentic LLMs

TL;DR for operators AIM-Bench is not another “which model is smartest?” leaderboard. It is a warehouse stress test for agentic LLMs asked to make replenishment decisions under uncertainty.1 The useful lesson is uncomfortable: inventory agents can look mathematically fluent while still behaving like biased managers. Most evaluated models show mean anchoring in the newsvendor task. All evaluated models show bullwhip amplification in the Beer Game. Some models over-order to avoid stockouts; others keep leaner inventory but accept higher shortage risk. In other words, the operational personality of the model matters. ...

August 18, 2025 · 14 min · Zelina
Cover image

Knows the Facts, Misses the Plot: LLMs’ Knowledge–Reasoning Split in Clinical NLI

TL;DR for operators A model that can answer clinical fact-checking questions is not necessarily a model that can reason clinically. That is the inconvenient result of The Knowledge-Reasoning Dissociation: Fundamental Limitations of LLMs in Clinical Natural Language Inference, which introduces CTNLI, a controlled clinical NLI benchmark paired with Ground Knowledge and Meta-Level Reasoning Verification probes.1 ...

August 18, 2025 · 19 min · Zelina
Cover image

Three’s Company: When LLMs Argue Their Way to Alpha

TL;DR for operators Portfolio teams do not need another chatbot that confidently explains why yesterday’s price move was “driven by sentiment.” They need a system that can split research work into specialised roles, force disagreement into the open, log the reasoning trail, and turn messy inputs into a decision that a human can inspect before money moves. ...

August 18, 2025 · 15 min · Zelina