Cover image

Mind Over Matter: How a BDI Ontology Gives AI Agents an Actual Inner Life

Workflow agents are easy to admire until someone asks a rude but necessary question: why did the agent do that? Not “what prompt did we send?” Not “which tool did it call?” Not “can we replay the logs and hope the compliance team loses interest?” The real question is sharper: what did the agent believe, what did it want, what did it commit to doing, which plan did that commitment specify, and what evidence justified the transition from one step to the next? ...
November 24, 2025 · 18 min · Zelina
Cover image

CLOZE Encounters: When LLMs Start Editing Medical Ontologies

Hospitals already have the raw material for better medical knowledge systems. It is sitting inside discharge summaries, nursing notes, radiology reports, ECG interpretations, and all the other clinical prose that makes electronic health records look deceptively “digital” while still behaving like a very expensive filing cabinet. The awkward part is that clinical notes are both valuable and dangerous. Valuable, because they contain granular observations that structured fields often miss. Dangerous, because they contain protected health information, idiosyncratic phrasing, and enough local context to make naïve automation look clever right up to the moment it quietly corrupts a downstream system. ...

November 23, 2025 · 16 min · Zelina
Cover image

Compression, But Make It Pedagogical: Rate–Distortion KGs for Smarter AI Learning Assistants

Training teams know the ritual. Someone uploads lecture slides, notebooks, policy manuals, onboarding decks, or certification material into an AI tool. The system dutifully produces quiz questions. Some are useful. Some are bland. Some include giveaway answers. Some test trivia. Some hallucinate just enough to be annoying but not enough to be obviously illegal. Everyone nods, calls it “AI-assisted learning,” and then quietly sends the outputs to a human reviewer. Automation, but with adult supervision. So, normal Tuesday. ...

November 20, 2025 · 19 min · Zelina
Cover image

Graph Medicine: When RAG Stops Guessing and Starts Diagnosing

Hospitals do not suffer from a shortage of medical text. They suffer from a shortage of medical text that machines can use without becoming dangerously imaginative. Clinical guidelines are full of thresholds, exceptions, disease associations, diagnostic pathways, and terminology that looks tidy only until someone tries to automate it. A guideline may say one thing about a biomarker in the context of cardiovascular risk, another in renal disease, and something subtly different when age, sex, postoperative status, or treatment history enters the room. This is exactly the sort of nuance that makes large language models useful—and also exactly the sort of nuance that makes them risky. ...

November 18, 2025 · 15 min · Zelina
Cover image

GraphRAG Gone Modular: Why Multi-Agent Cypher Matters More Than You Think

Ask a business user what they want from a data system and the answer is usually charmingly simple: “I want to ask a question and get the right answer.” Then reality arrives, wearing a database-admin badge. The data is not in one neat document. It is in entities, attributes, edges, hierarchies, ownership chains, product dependencies, spatial relations, compliance rules, and asset metadata. In other words, it is a graph. And if that graph lives in a labeled property graph database, the system probably expects a query language such as Cypher, not a cheerful paragraph about “leveraging insights”. ...

November 15, 2025 · 13 min · Zelina
Cover image

Proof, Policy, and Probability: How DeepProofLog Rewrites the Rules of Reasoning

Proofs are supposed to be the respectable part of AI: tidy, inspectable, and resistant to the usual neural-network fog machine. Then reality turns up, as it so often does, carrying a bill. In neurosymbolic AI, the bill is search. A system may know the rules. It may even combine them with neural perception. But if answering a query requires enumerating a vast space of possible proofs, the promise of “interpretable reasoning” quickly becomes a very elegant way to run out of time. ...

November 12, 2025 · 18 min · Zelina
Cover image

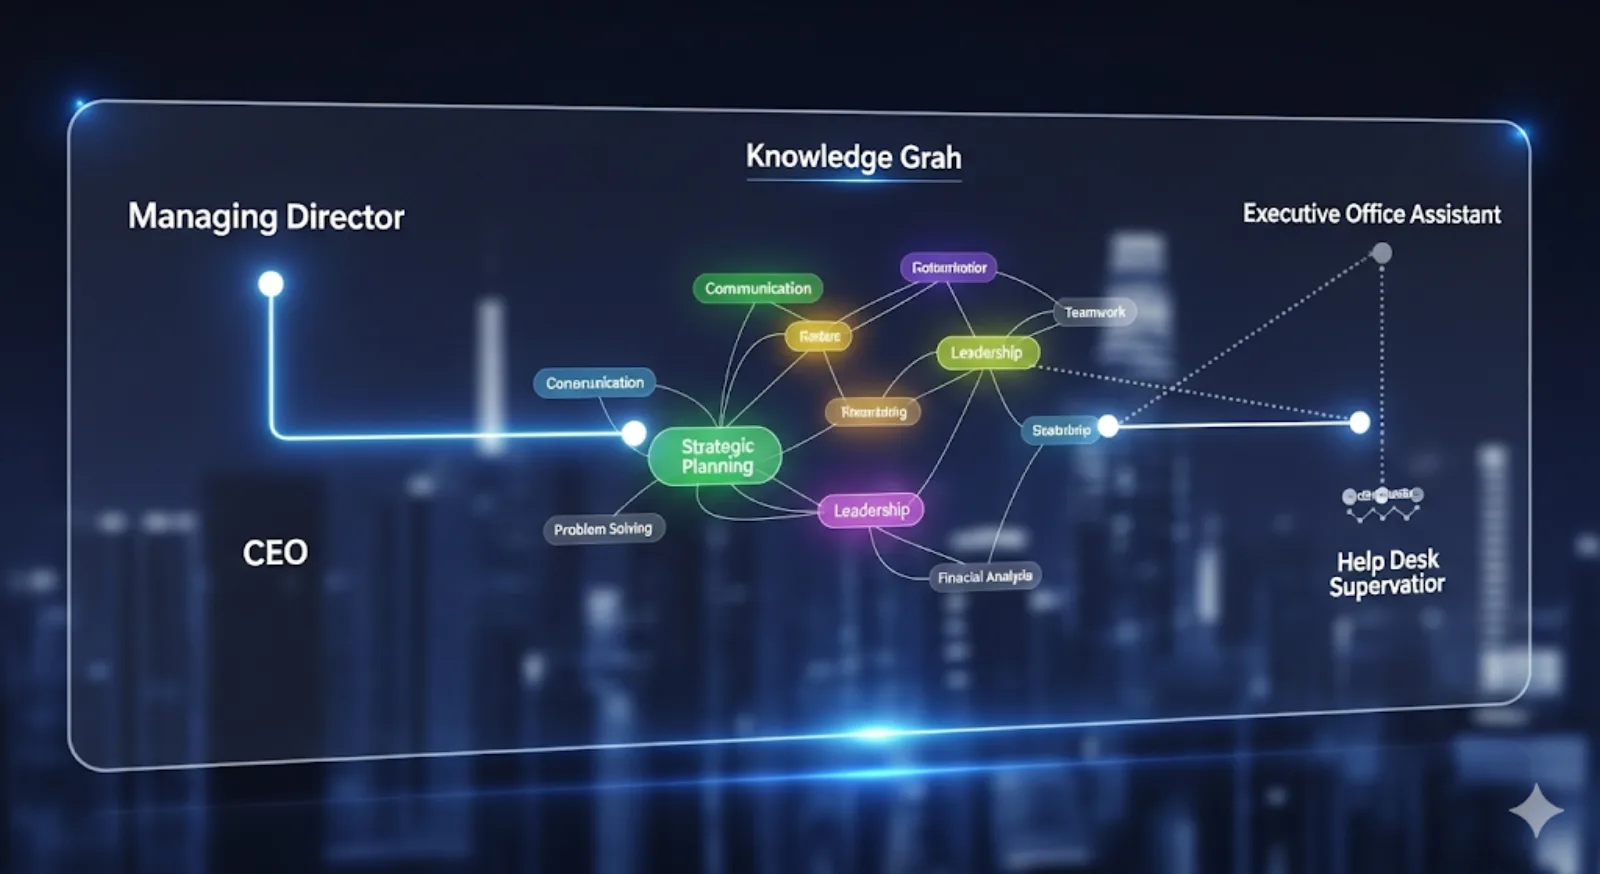
Titles, Not Tokens: Making Job Matching Explainable with STR + KGs

Recruiters do not match job titles the way search boxes do. A search box sees “Chief Executive Officer” and “Managing Director” and notices the obvious problem: almost no shared words. A recruiter sees the less obvious truth: these can be functionally close roles. Then the same recruiter sees “Director of Sales” and “Vice President, Marketing” and understands a different kind of relationship: not identical, but adjacent enough to matter. ...

September 17, 2025 · 13 min · Zelina
Cover image

RAGulating Compliance: When Triplets Trump Chunks

TL;DR for operators Compliance teams do not mainly need a chatbot that sounds more confident. They already have enough people sounding confident in meetings. They need answers that can be traced back to the rule text, checked against related provisions, and updated when the regulatory corpus changes. The paper behind this article proposes a multi-agent system that turns regulatory documents into subject–predicate–object triplets, embeds those triplets alongside their source sections, retrieves triplets for question answering, and shows users the relevant subgraph behind the answer.1 That matters because regulatory work is not just “find me a paragraph.” It is “show me the applicable rule, the linked requirement, the exception, the deadline, and the neighbouring clause that will embarrass us later.” ...

August 16, 2025 · 14 min · Zelina
Cover image

Cite Before You Write: Agentic RAG That Picks Graph vs. Vector on the Fly

TL;DR for operators Most enterprise RAG failures are not generation failures. They are retrieval-routing failures wearing a very convincing blazer. The paper behind this article proposes an open-source agentic hybrid RAG framework for scientific literature review: bibliographic metadata and citation relationships go into a Neo4j knowledge graph; full-text PDF chunks go into a FAISS vector store; an LLM-based agent decides whether a user’s question should be answered through GraphRAG or VectorRAG; a Mistral-based generator produces the final answer; DPO is used to improve grounding; and bootstrap resampling is used to report evaluation uncertainty.1 ...

August 11, 2025 · 20 min · Zelina
Cover image

Graphs, Gains, and Guile: How FinKario Outruns Financial LLMs

TL;DR for operators FinKario is useful because it attacks a dull but expensive problem: financial research is rich, long, inconsistent, and usually trapped inside documents that models can quote more easily than they can use. The paper’s answer is not “ask a better LLM.” It is “turn research reports into a dynamic financial knowledge graph, then retrieve graph context before asking the LLM to reason.” Small difference. Large operational consequences. ...

August 5, 2025 · 19 min · Zelina