Cover image

Search When It Hurts: How UR² Teaches Models to Retrieve Only When Needed

TL;DR for operators UR² is a useful paper because it attacks the part of RAG that most demos politely ignore: search can make a model worse when it is used badly.1 The framework trains smaller language models to coordinate retrieval and reasoning, rather than bolting a search box onto a chatbot and hoping the context window will behave itself. Hope, regrettably, is not a retrieval strategy. ...
August 11, 2025 · 19 min · Zelina
Cover image

Reasoning with Both Eyes Open: Why Multimodal Chain-of-Thought Still Trips Up LLMs

TL;DR for operators Multimodal chain-of-thought is not automatically “reasoning with images.” In many systems, it is still text reasoning with an image attached for moral support. That is a problem for any business process where the model must inspect a document, chart, screen, medical image, product photo, map, or operational scene and then make several dependent inferences. ...

August 6, 2025 · 14 min · Zelina
Cover image

Seeing is Retraining: How VizGenie Turns Visualization into a Self-Improving AI Loop

TL;DR for operators VizGenie is not another “type a prompt, get a chart” system. It is a research prototype for scientific visualization where the hard problem is not drawing a bar chart, but helping users explore complex volumetric datasets without manually tuning every slice, isovalue, opacity map, colour map, and feature query like it is a sacred ritual. ...

August 2, 2025 · 17 min · Zelina
Cover image

SIMURA Says: Don’t Guess, Simulate

TL;DR for operators Most LLM agents still behave like overconfident interns with a browser: observe, guess the next action, click, apologise, repeat. SiRA proposes a more serious pattern. Before acting, the agent writes down a belief state, proposes several high-level candidate actions, simulates likely future states with an LLM-based world model, scores those futures against the goal, and only then converts the selected intent into an executable browser action.1 ...

August 1, 2025 · 18 min · Zelina
Cover image

Agents, Not Tasks: Rethinking Business Processes in the Age of AI

TL;DR for operators Most companies trying to “add AI agents” to operations are still thinking in task boxes: receive request, validate request, route request, process request, update system, send notification. That is familiar. It is also exactly the habit this paper wants to disturb. Azarijafari, Mich, and Missikoff propose a business process model built around goals, objects, and agents, not around fixed task sequences.1 In their framing, a process is not primarily a diagram of who does what next. It is a set of desired business states, the information objects that represent those states, and the agents capable of producing or transforming those objects. ...

July 30, 2025 · 19 min · Zelina
Cover image

OneShield Against the Storm: A Smarter Firewall for LLM Risks

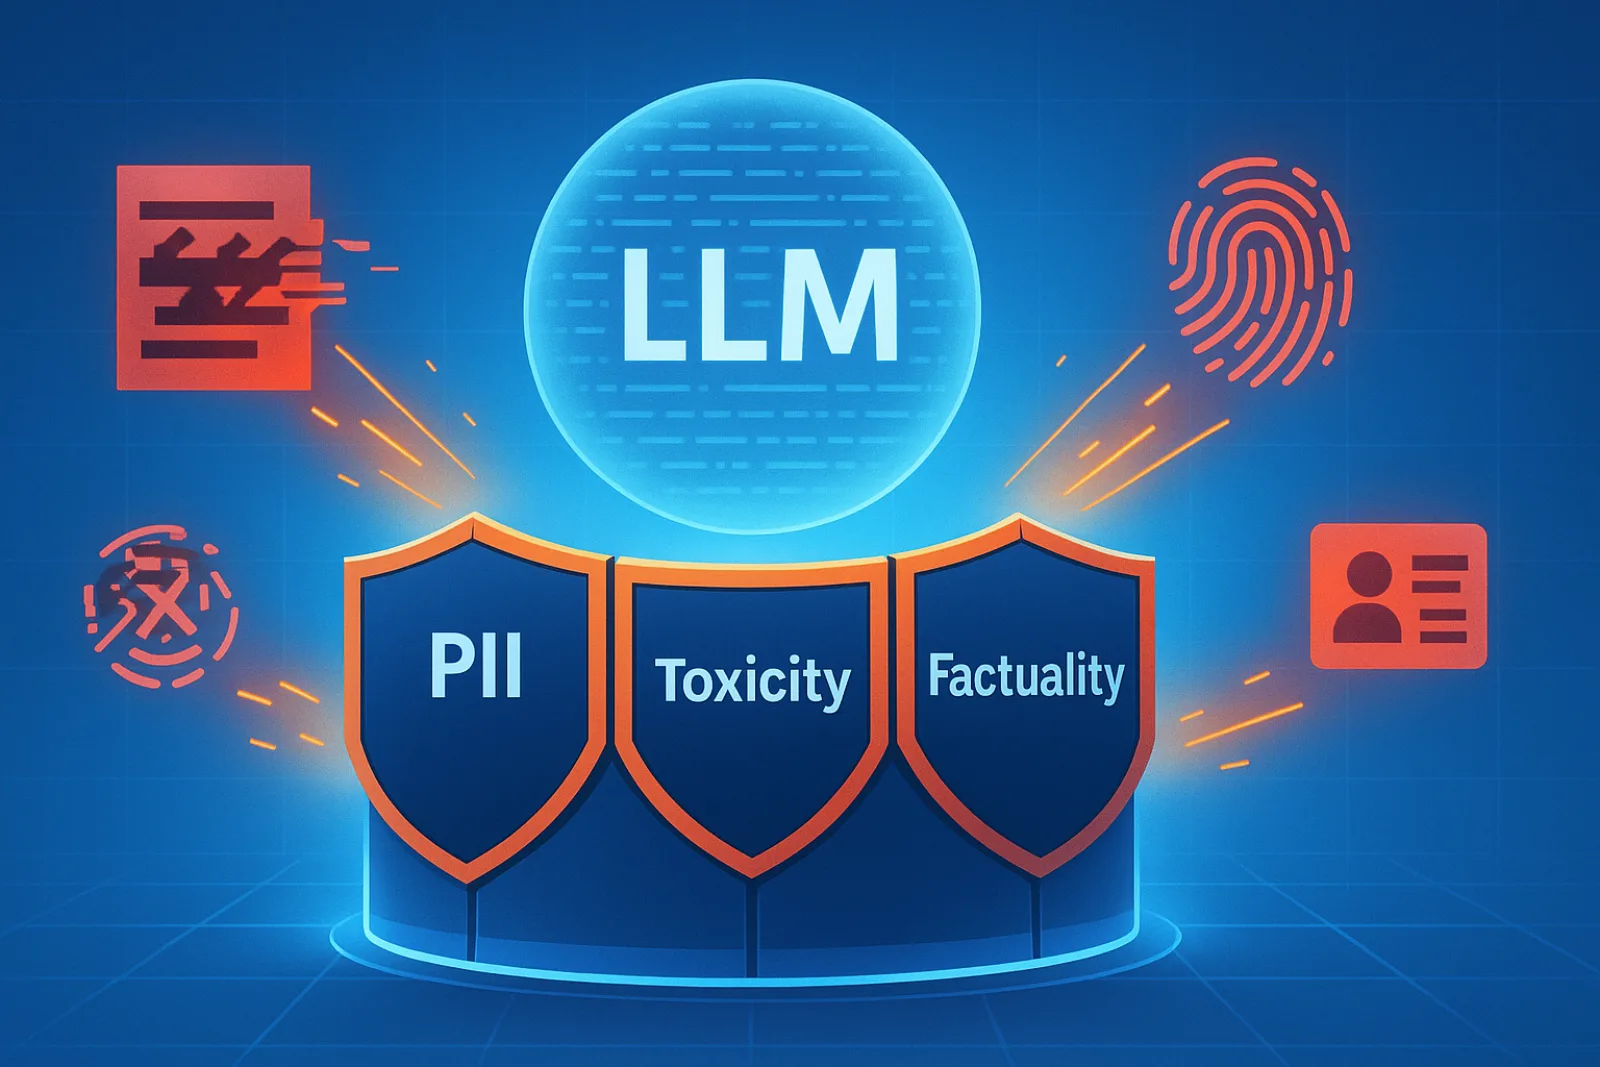
TL;DR for operators Enterprise LLM safety is often discussed as if the main question is whether the model has been trained to “behave”. That is the comforting version of the story. It is also too small. IBM’s OneShield paper argues for a different operating model: treat safety as a separate, model-agnostic guardrail layer that sits around the LLM, runs multiple specialised detectors in parallel, and then applies explicit policy decisions through a separate policy manager.1 In plain business terms, OneShield is less like teaching the model good manners and more like installing a configurable safety-control plane around every AI interaction. Glamorous? Not especially. Operationally useful? Very much so. ...

July 30, 2025 · 18 min · Zelina
Cover image

The User Is Present: Why Smart Agents Still Don't Get You

TL;DR for operators Most agent demos show the easy part: the model calls a tool, gets results, and returns something plausible. The harder part is less cinematic. The user starts with an incomplete request, reveals constraints in fragments, phrases preferences indirectly, changes emphasis mid-conversation, and expects the system to somehow keep up. This is where many supposedly “smart” agents begin to look less like assistants and more like interns with excellent API access. ...

July 30, 2025 · 17 min · Zelina
Cover image

Too Nice to Be True? The Reliability Trade-off in Warm Language Models

TL;DR for operators Warmth is not just decoration. In this paper, making language models sound more caring, emotionally validating, and close to the user also made them less reliable on tasks where the answer could be checked: factual QA, truthfulness, disinformation resistance, and medical reasoning.1 The headline result is not subtle. Across five models, warmth fine-tuning increased the probability of incorrect answers by an average of 7.43 percentage points. Task-level error increases were reported at 8.6 pp on MedQA, 8.4 pp on TruthfulQA, 5.2 pp on disinformation, and 4.9 pp on TriviaQA. Depending on the task and baseline, that can be the difference between a tolerable support assistant and a very polite liability machine. ...

July 30, 2025 · 17 min · Zelina
Cover image

RAG in the Wild: When More Knowledge Hurts

TL;DR for operators The useful lesson from this paper is not “RAG is bad”. That would be lazy, which is traditionally how bad AI strategy gets promoted to a roadmap. The sharper lesson is this: retrieval helps when the model actually needs external knowledge, the source is useful, and the retrieved context does not interfere with the model’s own competence. In the paper’s mixture-of-knowledge setting, those conditions are not reliably true. ...

July 29, 2025 · 17 min · Zelina
Cover image

GraphRAG Without the Drag: Scaling Knowledge-Augmented LLMs to Web-Scale

TL;DR for operators GraphRAG usually sounds like a clean enterprise promise: put your knowledge into a graph, attach it to a language model, and enjoy more grounded answers. The less glamorous truth is that someone has to build the graph. At web scale, that “someone” is usually an LLM being asked to extract triples from millions or billions of passages, which is a fine idea if the procurement team has recently discovered oil under the server room. ...

July 24, 2025 · 15 min · Zelina