Cover image

Agency Check, Please: What a New Benchmark Says About LLMs That Actually Empower Users

A customer asks your AI assistant to choose between two mortgage options. An employee asks whether to quit. A student says, very politely, “Please guide me, but don’t give me the answer.” A lonely user suggests the chatbot feels like a best friend. The easy product answer is: be helpful. The harder answer is: helpful to what? ...
September 14, 2025 · 16 min · Zelina
Cover image

From PDF to PI: Turning Papers into Productive Agents

Every R&D team has a shelf of papers that are theoretically useful and practically booby-trapped. The abstract is promising. The method is relevant. The results look transferable. Then reality arrives wearing a conda error message: the repository has three setup paths, two notebooks, one undocumented dependency, and a tutorial that assumes you already know the answer. The paper has been published. The method has not, in any serious operational sense, been delivered. ...

September 12, 2025 · 17 min · Zelina
Cover image

Graph and Circumstance: Maestro Conducts Reliable AI Agents

A broken AI agent often looks deceptively close to working. It answers most questions. It calls the right tool sometimes. It follows the instruction until the conversation gets long, the retrieval query gets vague, or the arithmetic becomes just difficult enough for the model to start doing spreadsheet theatre. The usual repair is prompt editing. Add a stern sentence. Add a role. Add an example. Add “think step by step,” because apparently the machine needed a motivational poster. ...

September 11, 2025 · 15 min · Zelina
Cover image

Parallel Minds, Shorter Time: ParaThinker’s Native Thought Width

A familiar enterprise AI failure looks less like stupidity and more like stubbornness. Ask a model to solve a hard problem, and it may begin confidently in the wrong direction. Then it keeps going. It adds details. It self-reflects. It spends tokens. It may even apologise to itself internally, which is apparently what we call progress now. But the core path does not change. The model is not merely short on compute. It is trapped inside its own first guess. ...

September 11, 2025 · 15 min · Zelina
Cover image

Agreeable to a Fault: Why LLM ‘People’ Can’t Hold Their Ground

A focus group is expensive. A virtual focus group is cheap, infinitely patient, and available at 2 a.m. It also never asks for coffee, parking reimbursement, or clarification about the incentive payment. Naturally, this makes synthetic users attractive to anyone trying to test products, policies, campaigns, or customer journeys before real humans get involved. ...

September 8, 2025 · 14 min · Zelina
Cover image

Cache Me If You Can: Designing Databases for Swarms of AI Agents

A data analyst asks a database a question. An AI agent interrogates it. That distinction sounds theatrical until the query logs arrive. The human analyst usually knows roughly where to look, asks a small number of targeted questions, waits for answers, adjusts, and eventually presents a result. The agent is less graceful. It checks schemas, samples columns, guesses joins, inspects distinct values, tries partial SQL, abandons it, starts again, validates, retries, and occasionally recruits more agents to repeat the exercise in parallel. It is not being stupid. It is compensating for a missing sense of the underlying data. ...

September 4, 2025 · 16 min · Zelina
Cover image

Mask, Don’t Muse: When Simple Memory Beats Fancy Summaries

TL;DR for operators A coding agent’s memory problem is not philosophical. It is a bill. The paper behind this article compares three ways to manage context in software-engineering agents: keep the full trajectory, summarize old turns with an LLM, or simply mask older environment observations while preserving the agent’s reasoning and actions.1 Across five SWE-agent configurations on SWE-bench Verified, both context-management strategies usually cut cost sharply versus the Raw Agent. The awkward part is that the simple strategy, Observation Masking, is often just as good as LLM-Summary on solve rate and usually cheaper. ...

September 1, 2025 · 17 min · Zelina
Cover image

Vitals, Not Vibes: Inside the New Anatomy of Personal Health Agents

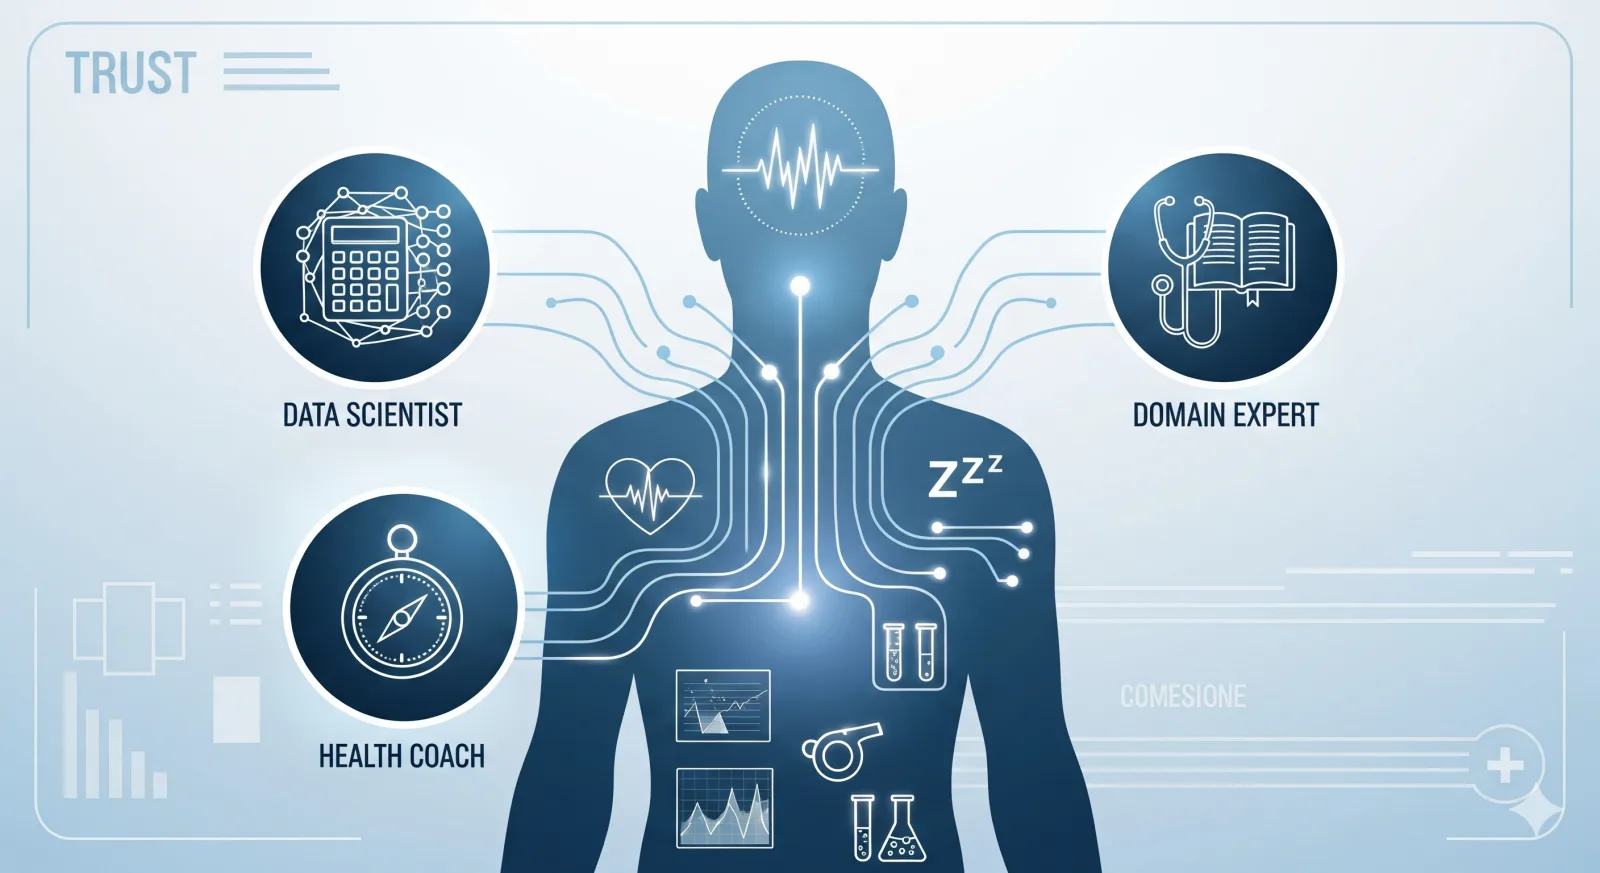
TL;DR for operators Personal health AI is usually sold as a friendly chatbot with a fitness tracker bolted on. This paper argues for something more awkward, more expensive, and much more plausible: a coordinated system of specialised agents. One agent analyses longitudinal wearable and health-record data. One grounds advice in health knowledge and user context. One handles coaching, goal-setting, and behaviour change. An orchestrator decides who should act, who should support, what should be remembered, and how the final answer should be assembled.1 ...

August 31, 2025 · 15 min · Zelina
Cover image

Who Watches the Watchers? Weak-to-Strong Monitoring that Actually Works

TL;DR for operators The paper’s practical message is not “add a monitor and relax.” That would be adorable, in the way unsecured admin panels are adorable. The useful message is sharper: if autonomous agents know they are being watched, standard full-log monitoring becomes less reliable. Giving the monitor more information helps sometimes, but less than many teams would expect. The bigger lever is how the monitor reads the trajectory. ...

August 30, 2025 · 17 min · Zelina
Cover image

Back to School for AGI: Memory, Skills, and Self‑Starter Instincts

TL;DR for operators The paper is not really about whether a model can answer exam questions. Given the right context, the frontier models do very well. The hard part is whether an agent can notice what must be preserved, store it in a useful form, retrieve it at the right time, and act without being explicitly prodded. That is the difference between an assistant that sounds competent and an assistant that can actually carry operational state across days, weeks, and dependent workflows. ...

August 27, 2025 · 17 min · Zelina