Memory Games: The Data Contamination Crisis in Reinforcement Learning
A forensic reading of why random rewards can appear to improve LLM reasoning when public benchmarks have already leaked into model memory.
A forensic reading of why random rewards can appear to improve LLM reasoning when public benchmarks have already leaked into model memory.
TinyTroupe shows why synthetic personas need simulation machinery, not just chatty agents with demographic labels.
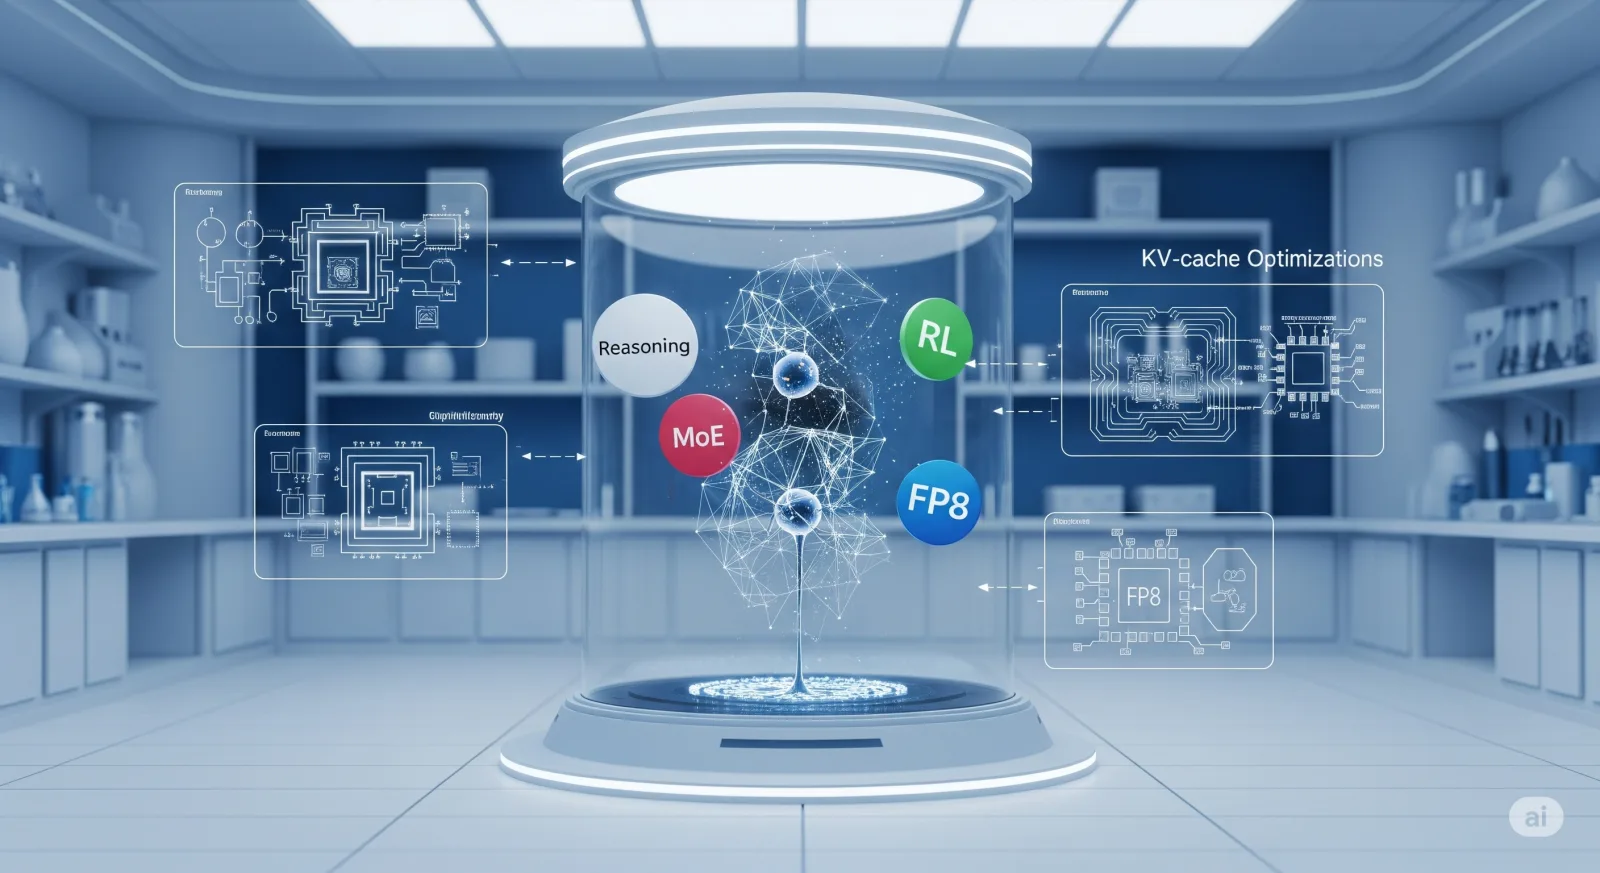
DeepSeek-R1 shows that frontier reasoning is less about one brilliant model trick and more about aligning reinforcement learning, verifiable rewards, efficient architecture, and distillation into one disciplined system.
A practical look at a serverless LLM stock-analysis prototype whose real lesson is not prediction accuracy, but deployable, low-cost financial intelligence architecture.
A practical reading of why table agents need operational workflows, not just better prompts or larger context windows.
SetupBench shows that coding agents still struggle with the unglamorous first mile of software work: making the project actually run.
A practical map for deciding when static RAG is enough, when reasoning-aware retrieval helps, and when full agentic retrieval-reasoning systems are worth the cost.
A mechanism-first reading of MemSinks, a training-time approach for separating useful generalization from removable verbatim memorization in language models.
Clue-RAG shows that better enterprise retrieval may come less from bigger knowledge graphs and more from using the right semantic layer at the right moment.
A mechanism-first reading of neural jamming: useful as a scaling lens, hazardous as a consciousness claim.