TL;DR for operators
Coding agents can now construct robotics simulations that would traditionally require substantial specialist engineering. Whether the resulting environments are physically reliable, and whether autonomous controllers can perform the simulated work, are separate questions.
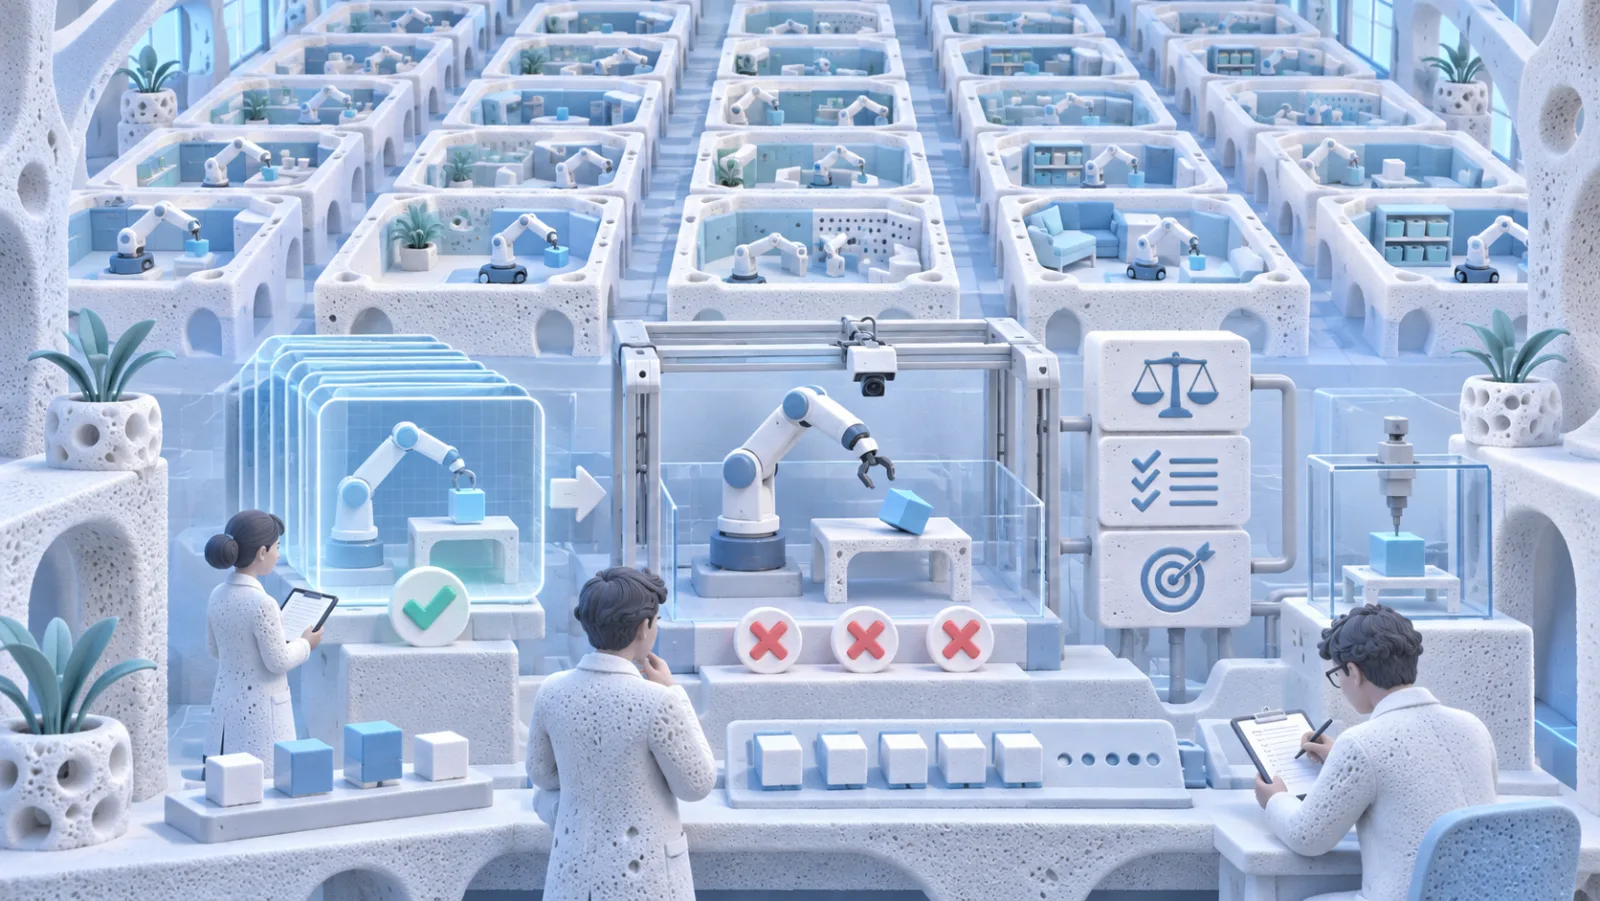
In Gym-Anything for Robotics, researchers build 25 simulations containing 200 reinforcement-learning environments. Three frontier coding agents achieve zero success on all 25 official test tasks, although they complete some easier tasks. Independent auditing exposes physical defects in approximately three quarters of the generated simulations before repair.
The more encouraging results concern learning. Access to internal simulator information improves agent performance, and demonstrations generated by privileged code policies train a vision-language-action model from 0% to 53% success on two simulated gift-box tasks.
For robotics R&D leaders, the operational opportunity is an auditable pipeline: select economically relevant physical capabilities, generate simulations, verify their dynamics and completion conditions, and train policies using information unavailable during deployment. Each stage requires separate validation. The paper demonstrates progress inside simulation, not physical-robot deployment or measurable labor savings.
A simulated task is not yet an executable capability
A robotics team planning to automate a physical operation needs to test more than whether its controller can issue the right commands. The environment must respond plausibly when objects collide, deform, spill, or resist manipulation. It must also distinguish genuinely completed work from an action sequence that merely appears successful.
Building these environments is expensive in engineering effort because physical behavior, robot interfaces, task conditions, and evaluation logic must work together.
Pranjal Aggarwal and Sean Welleck address this development bottleneck in Gym-Anything for Robotics: Scaling physical simulations with digital agents.1
Their framework creates virtual physical environments using coding agents, then subjects the generated systems to independent verification.
Its accompanying benchmark, RoboWorld, exposes an immediate capability gap: under a three-hour wall-clock budget per evaluation attempt, GPT-6 Astra, GPT-6.1 Terra, and Claude Opus 5.5 complete none of the 25 official test tasks.
This result does not establish that the simulations are unusable. It shows that generating an environment and controlling a robot successfully within it are distinct engineering achievements.
From economic activities to reusable physical simulations
The framework starts by asking which physical capabilities deserve simulation coverage.
Its selection process combines U.S. occupational information, employment and wage data, national accounts, and everyday time-use activities. It decomposes activities into physical actions and identifies the robotic and physics capabilities needed to execute them.
The resulting pipeline processes 1,016 occupations, 18,796 occupational task statements, and 465 everyday activities. It identifies 31,961 atomic-action occurrences, grouped into 2,330 candidate action groups.
From these, the researchers select 120 groups for potential simulation construction and implement 25 simulations.
The selection principle emphasizes reusable capability coverage, rather than building an independent environment for every occupational task. A capability involving force control, material deformation, or liquid handling may support several different operations.
The implemented simulations include liquids, cloth, chemistry, molten metal, soft tissue, and acoustics. They use different physics engines and custom solvers behind a common robot interface.
RoboWorld contains 200 reinforcement-learning environments organized across those 25 simulations: 25 official test environments and 175 training environments.
For an industrial automation team, this suggests organizing simulation investments around the physical capabilities shared by multiple candidate workflows.
However, the economic weighting is a prioritization proxy. Occupational wages and time spent performing activities do not directly measure robotic feasibility, achievable cost savings, or deployment profitability.
Generated physics needs independent verification
A coding agent can produce a technically executable simulation without correctly modeling the physical process.
Gym-Anything addresses this through a creation-audit loop.
One agent constructs the simulation, researching physical mechanisms, writing code, configuring robots, and producing supporting evidence. Four independent auditing roles then inspect physical realism, dynamics and solvability, infrastructure, and potential exploits through permitted robot actions.
Verified defects return to the creator for repair, with up to three auditing rounds.
The need for this process is supported by the study’s adversarial findings: approximately three quarters of generated simulations contain a defect discovered before repair.
Examples include physically impossible motion and inconsistent behavior between simulated components.
Task verification receives a separate layer of scrutiny. Six task-auditing roles evaluate whether instructions are meaningful, initial settings are appropriate, verification is correct, rewards reflect progress, tasks are solvable, and difficulty is adequately distributed.
These checks matter because a simulator can fail in two different ways. It can model physical behavior incorrectly, or it can assign an incorrect success label to otherwise correctly simulated behavior.
The framework therefore defines task success using deterministic conditions over simulated physical state, alongside continuous rewards for partial progress.
Audits reveal both false acceptance of incomplete work and rejection of valid outcomes.
The paper also reports that its simulations win 80% of visual-quality judgments and 76% of physics-quality judgments against selected prior simulators. These are blinded, order-swapped comparisons across 25 pairs, judged by Claude Opus 5.5.
That comparison is supporting evidence about perceived simulation quality, not comprehensive measurement of physical fidelity. Likewise, finding and repairing reported defects does not establish that every remaining exploit has been eliminated.
Zero test completions do not mean zero learning
The main benchmark evaluates coding agents controlling simulated robots through restricted observations and legal commands.
The results differ materially between official test tasks and a separate, easier subset drawn from the training split.
| Model | Official test success, 25 tasks | Easier-task success, 25 tasks | Easier-task mean reward |
|---|---|---|---|
| GPT-6 Astra | 0% | 24% | 0.41 |
| GPT-6.1 Terra | 0% | 12% | 0.17 |
| Claude Opus 5.5 | 0% | 32% | 0.48 |
Source: Section 6.2, Figure 6. Mean reward is continuous progress on a 0–1 scale, not a task-completion percentage.
On official test tasks, reported mean rewards range from approximately 0.002 to 0.06. Agents occasionally make partial progress, but none reaches the required completion conditions.
The easier-task results show measurable capability under a different difficulty setting. They should not be substituted for official test performance.
An additional analysis associates more complex robot configurations with lower success rates, but robot types and task composition change together. It does not isolate degrees of freedom as the cause.
For benchmark operators, these findings support evaluating both binary completion and intermediate progress, while preserving clear distinctions between difficulty levels and evaluation splits.
Simulator knowledge improves restricted-agent learning
A physical robot observes the world through cameras and other sensors. A simulator can additionally reveal exact object positions, contact forces, and internal material states.
The paper calls this additional information privileged simulator state.
Across 11 simulations, Claude Opus 5.5 improves its mean reward over three repeated attempts without changing model weights.
| Learning condition | First attempt | Third attempt |
|---|---|---|
| Restricted observations | 0.14 | 0.22 |
| Privileged simulator access | 0.34 | 0.41 |
| Restricted execution after privileged experience | 0.17 | 0.29 |
Source: Sections 5 and 6.3, Figure 7. Values are mean continuous rewards across the reported learning experiments.
The first-attempt advantage of privileged access indicates that internal physical information helps agents diagnose task state and select actions.
A separate coaching experiment tests whether some of this advantage can reach a restricted observer. A privileged teacher supplies at most ten qualitative hints, without transmitting numerical commands or directly controlling the student.
The coached student’s first-attempt reward reaches 0.29, compared with 0.14 without coaching.
This establishes an improvement under the reported simulated conditions. It does not require giving the student direct access to hidden physical state.
The self-transfer experiment investigates another route: retaining an agent’s prior privileged experience, code, and workspace after removing privileged access.
Together, the experiments identify a practical role for simulation as a source of diagnostic information, even when the most difficult benchmark tasks remain unsolved.
From privileged code to faster robot policies
The study also examines whether privileged information can produce training examples for a controller that does not require it during execution.
For two gift-box tasks, privileged Python code policies achieve 96.7% success across 2,048 varied initial states.
The researchers collect 1,000 successful demonstrations and use them to train a pi_0.5 vision-language-action model, which converts visual observations and robot state into actions.
The trained policy’s success rises from 0% to 53% on the studied simulated tasks, with 55% success on previously unseen simulated variations.
It also completes the evaluated tasks in approximately two minutes, compared with approximately 29 minutes for Claude Opus 5.5 controlling the robot step by step.
These results support a specific development sequence: use a privileged controller to generate successful demonstrations, then train a faster controller that acts through restricted observations.
The evidence covers two related tasks within one gift-box simulation. The trained model has not demonstrated 53% success across RoboWorld, and the unseen variations remain simulated rather than physical environments.
Four approval gates for industrial robotics development
The Cognaptus inference is that simulation generation should be treated as one stage in a controlled robotics development pipeline, rather than as proof of autonomous operational capability.
| Approval gate | Decision owner | Required evidence |
|---|---|---|
| Simulation validity | Robotics simulation engineers | Physical measurements, independent audits, repaired defects, and robustness checks |
| Task completion validity | Benchmark and quality engineers | Deterministic verification, valid rewards, and resistance to exploitable success conditions |
| Restricted-policy readiness | Robot-control developers | Completion rates, failure analysis, and generalization under realistic observation constraints |
| Physical deployment | Operations and safety management | Physical-robot testing, safety evidence, operational reliability, and deployment economics |
These gates distinguish decisions that the paper sometimes evaluates together but that an industrial operator must approve separately.
A simulation-platform provider may reasonably use coding agents to expand prototype coverage while keeping physics validation mandatory. A robotics developer may use privileged information to generate demonstrations while evaluating the resulting policy without that access. A manufacturing operator should not infer deployment readiness until physical tests establish acceptable performance under actual operating conditions.
There are additional unresolved economic questions. The study does not quantify total simulation-generation cost savings, human-equivalent engineering effort avoided, production reliability, or return on investment. Its 25 implemented simulations also represent only part of the 120 selected physical-action groups.
The next milestone is verified physical transfer
Gym-Anything contributes an implemented architecture for building and auditing physical simulations with coding agents, alongside evidence that those environments can support improved simulated learning.
Its main benchmark exposes how far frontier coding agents remain from completing the difficult physical tasks selected for evaluation. Its learning experiments show that privileged simulator information can improve reasoning, coaching, and trained policy performance under narrower conditions.
For robotics operators, the next consequential question is whether those advantages survive physical deployment: whether simulated forces, contacts, and material interactions are sufficiently accurate, and whether trained controllers retain reliable performance on real equipment.
Until that evidence exists, the framework is best understood as an emerging method for creating and validating robotics development infrastructure, not as a demonstrated solution for autonomous industrial work.
Cognaptus: Automate the Present, Incubate the Future.
-
Pranjal Aggarwal and Sean Welleck (2026). Gym-Anything for Robotics: Scaling physical simulations with digital agents. arXiv:2610.40565. https://arxiv.org/abs/2610.40565 ↩︎