Cover image

Agents on the Clock: Turning a 3‑Layer Taxonomy into a Build‑Ready Playbook

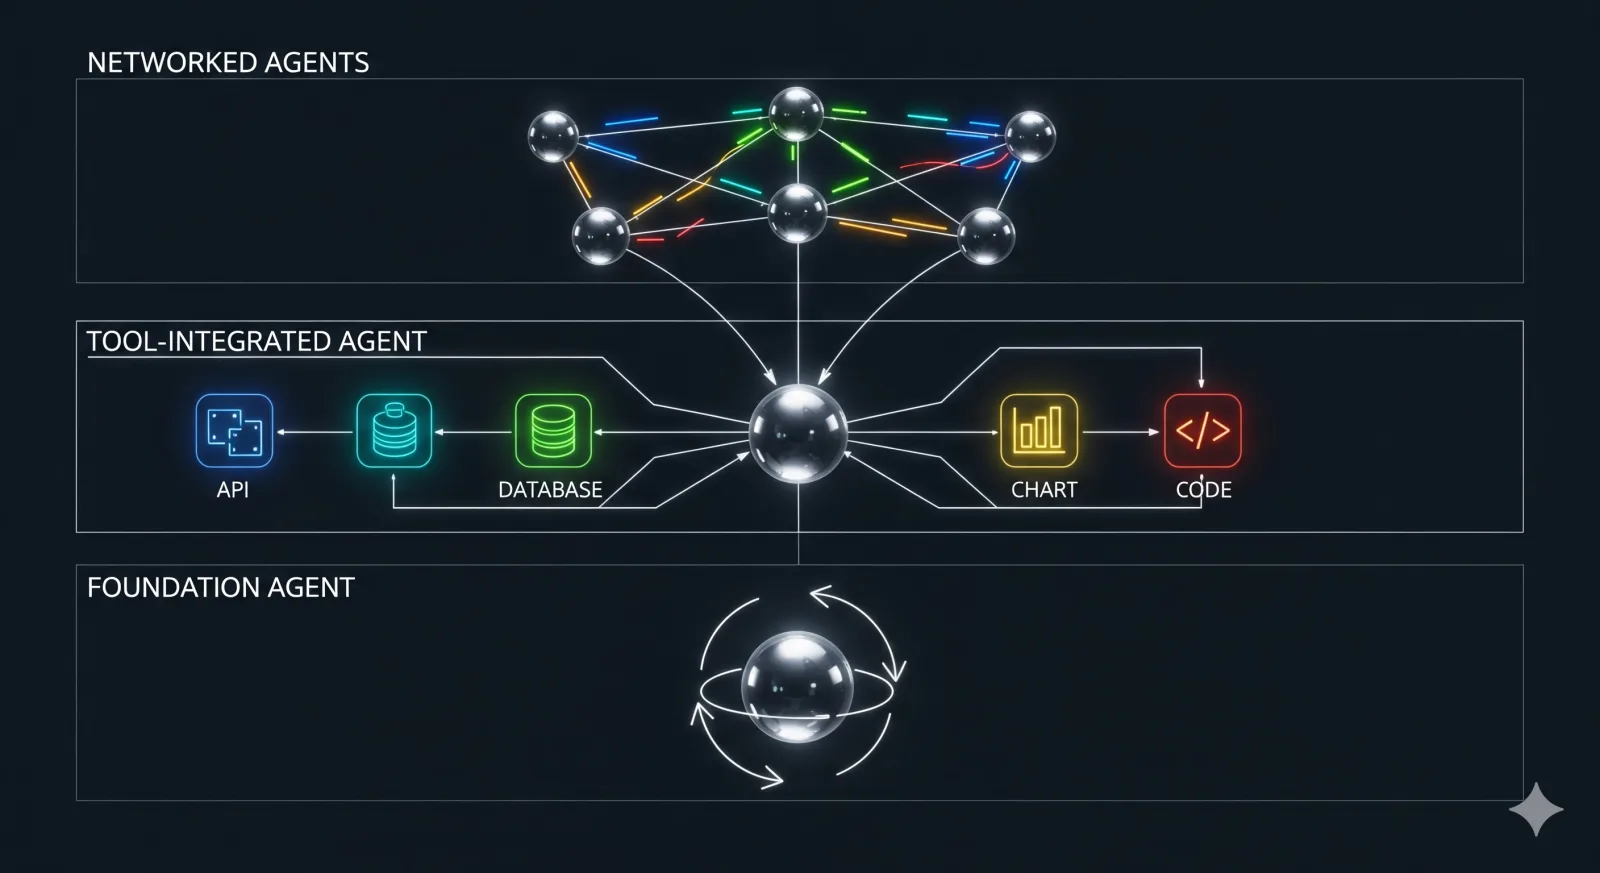
TL;DR for operators Most agent projects fail in a wonderfully unglamorous place: not at “intelligence”, but at the loop. The agent forgets what it already did. It calls the wrong tool. It reflects poetically instead of usefully. It delegates to three other agents because the demo looked impressive, then spends the next minute staging a management retreat in token form. Charming, but not production. ...
August 26, 2025 · 15 min · Zelina
Cover image

Atom by Atom, Better Research: How Fine-Grained Rewards Make Agentic Search Smarter

TL;DR for operators Research agents fail in a very familiar way: they do several useful things, then make one bad final move, and the training signal treats the whole journey as garbage. Delightful. Efficient. Totally not a credit-assignment problem wearing a lab coat. Atom-Searcher attacks that problem by splitting an agent’s reasoning trace into Atomic Thoughts: small, functional reasoning units such as planning, verification, hypothesis testing, observation, action selection, or risk analysis. A Reasoning Reward Model then scores those units, producing an Atomic Thought Reward that is blended with the final-answer reward during reinforcement learning.1 ...

August 19, 2025 · 14 min · Zelina
Cover image

Crystal Ball, Meet Cron Job: What FutureX Reveals About ‘Live’ Forecasting Agents

TL;DR for operators FutureX is less interesting as a leaderboard and more interesting as an operating model for evaluating AI agents that claim to forecast the future. The benchmark runs a live loop: collect future-facing questions from curated web sources, ask agents to predict before the answer exists, wait for resolution, crawl the answer, and score the prior prediction. That matters because most “forecasting” evaluations are either historical backtests with leakage risk or static datasets quietly ageing into trivia. ...

August 19, 2025 · 13 min · Zelina
Cover image

From Ballots to Budgets: Can LLMs Be Trusted as Social Planners?

TL;DR for operators This paper asks a deceptively operational question: can an LLM act as a social planner when it must allocate a fixed budget across competing public projects? Not in the inspirational LinkedIn sense. In the literal sense: choose project IDs, stay within budget, maximise community utility, and return a valid allocation. ...

August 11, 2025 · 20 min · Zelina
Cover image

Meta-Game Theory: What a Pokémon League Taught Us About LLM Strategy

TL;DR for operators A Pokémon tournament sounds unserious until you notice what it does better than many enterprise AI pilots: it forces models to make constrained, sequential, adversarial decisions, then records not only what they did but why they said they did it. The paper behind this article introduces LLM Pokémon League, a benchmark where eight models from the GPT, Claude, and Gemini families act as Pokémon trainers. Each model selects a six-member team, then makes turn-by-turn battle decisions in a zero-shot setting. The framework captures team-building rationales, move choices, switching decisions, and explanations throughout the tournament.1 ...

August 9, 2025 · 17 min · Zelina
Cover image

Reasoning with Both Eyes Open: Why Multimodal Chain-of-Thought Still Trips Up LLMs

TL;DR for operators Multimodal chain-of-thought is not automatically “reasoning with images.” In many systems, it is still text reasoning with an image attached for moral support. That is a problem for any business process where the model must inspect a document, chart, screen, medical image, product photo, map, or operational scene and then make several dependent inferences. ...

August 6, 2025 · 14 min · Zelina
Cover image

Thinking in Circles: How Self-Questioning LLMs Learn Without Labels

TL;DR for operators Self-Questioning Language Models, or SQLM, tests a tempting idea: can a language model improve its reasoning ability without being handed a curated training set of questions and answers? The answer in this paper is: partly, in narrow settings, if the training loop is engineered carefully enough.1 The mechanism is not mystical self-awareness. A model is split into two roles. One role proposes questions from a single topic prompt. The other tries to solve them. Reinforcement learning then updates the system using proxy rewards: majority-vote agreement for arithmetic and algebra, and proposer-generated unit tests for coding. The proposer is rewarded for problems that are not too easy and not too hard; the solver is rewarded for answers that pass the available proxy. ...

August 6, 2025 · 17 min · Zelina
Cover image

Credit Where It's Due: How CAPO Brings Verifiable Precision to LLM Reasoning

TL;DR for operators CAPO is not mainly a paper about “making models reason better” in the usual fog-machine sense. It is about fixing a specific training failure: outcome-only reinforcement learning tells a model whether the final answer was right, but not which part of the reasoning earned or destroyed that outcome. The method uses a stronger off-the-shelf LLM as a generative process reward model, or GenPRM, to inspect a rollout and identify wrong reasoning steps in one pass. Those step-level critiques are then converted into token-level penalties, so the policy update can suppress flawed reasoning segments instead of treating the whole answer as one indivisible blob. The authors test this across Llama-3-1B/3B and Qwen2.5-1.5B/7B backbones, with results showing consistent average gains over SFT, GRPO with rule-based verification, and GRPO with generative outcome reward modelling.1 ...

August 5, 2025 · 14 min · Zelina
Cover image

Seeing Is Deceiving: Diagnosing and Fixing Hallucinations in Multimodal AI

TL;DR for operators A multimodal model can look at an image and still answer from memory, habit, or linguistic guesswork. That is the uncomfortable core of visual hallucination: the output is fluent, relevant-looking, and sometimes even useful, while being only loosely attached to the pixels it claims to describe. The practical lesson is not “never use multimodal AI.” That would be tidy, dramatic, and mostly useless. The lesson is narrower and more valuable: visual hallucinations need to be diagnosed by where grounding fails, not merely counted after the model has embarrassed itself. ...

August 5, 2025 · 14 min · Zelina
Cover image

How Sparse is Your Thought? Cracking the Inner Logic of Chain-of-Thought Prompts

TL;DR for operators Chain-of-thought prompting is often sold as a window into model reasoning. This paper is more useful because it treats CoT as something less mystical and more testable: a prompt-induced change in internal representations.1 The researchers train sparse autoencoders on hidden activations from two Pythia models solving GSM8K math problems under CoT and NoCoT prompts. They then patch CoT-derived sparse features into NoCoT runs and ask a sharper question: does inserting those internal features increase the log-probability of the correct answer? ...

August 1, 2025 · 16 min · Zelina