
Don't Trust. Verify: Fighting Financial Hallucinations with FRED
A practical look at FRED, a finance-focused framework for detecting and editing hallucinations in retrieval-grounded LLM outputs.
A practical look at FRED, a finance-focused framework for detecting and editing hallucinations in retrieval-grounded LLM outputs.
A practical reading of programmable virtual humans as a proposed bridge between molecular AI, digital twins, and physiology-first drug discovery.
MIRAGE-Bench reframes agent hallucination as context-unfaithful action and gives operators a sharper way to test LLM agents before they touch real systems.

A practical reading of why retrieval-augmented generation can degrade when enterprise knowledge sources become heterogeneous, noisy, and poorly routed.
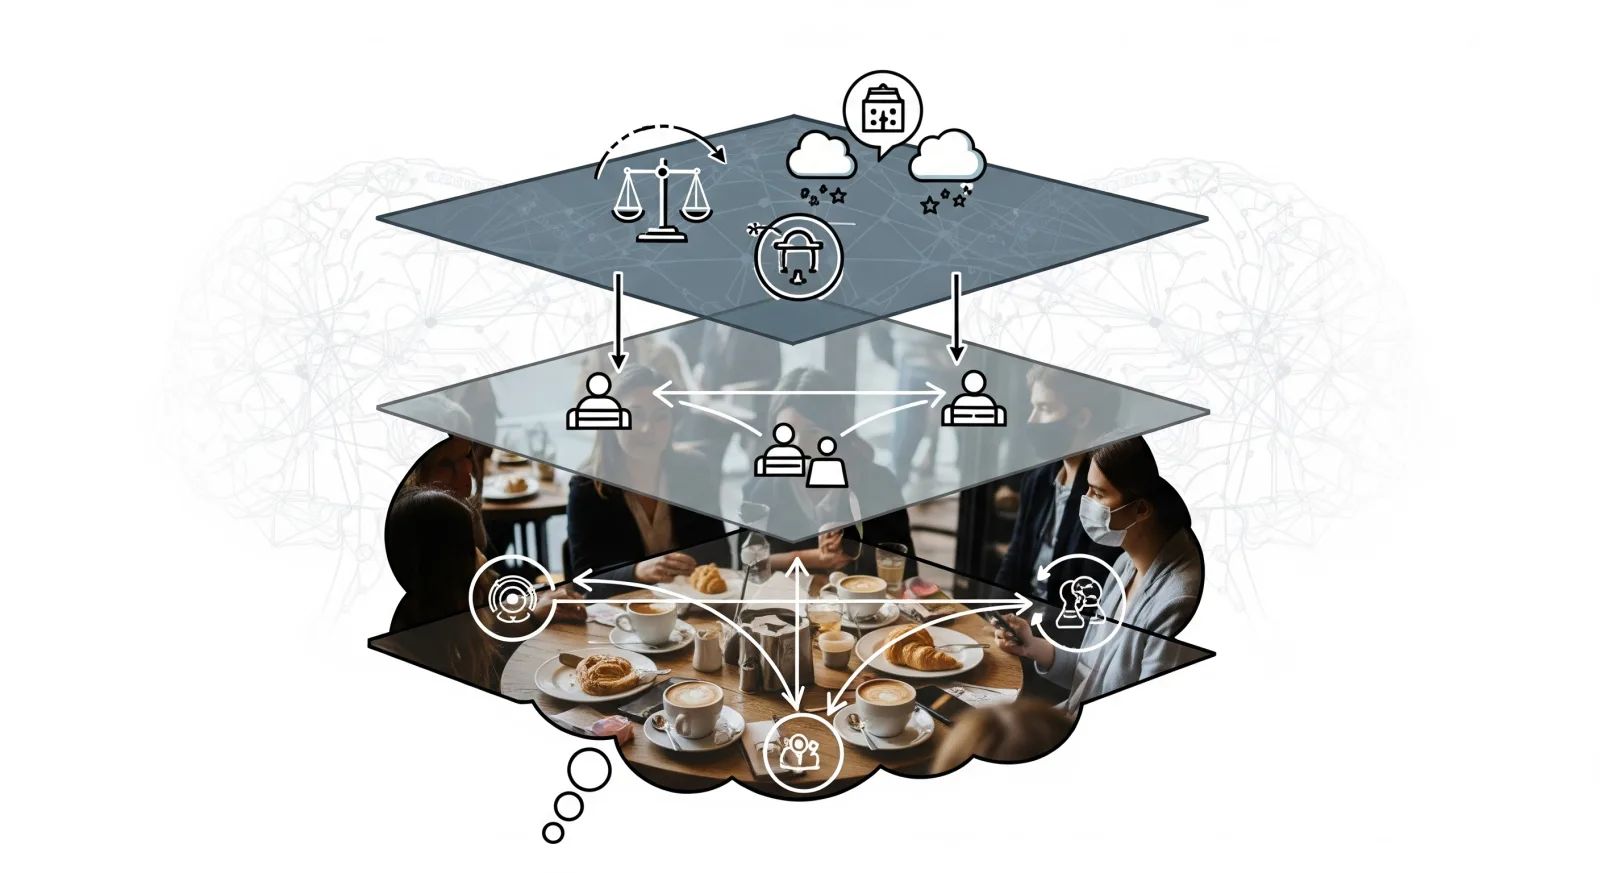
A mechanism-first reading of CoCoT, a structured reasoning scaffold that helps vision-language models separate what they see from what they infer and what they judge.
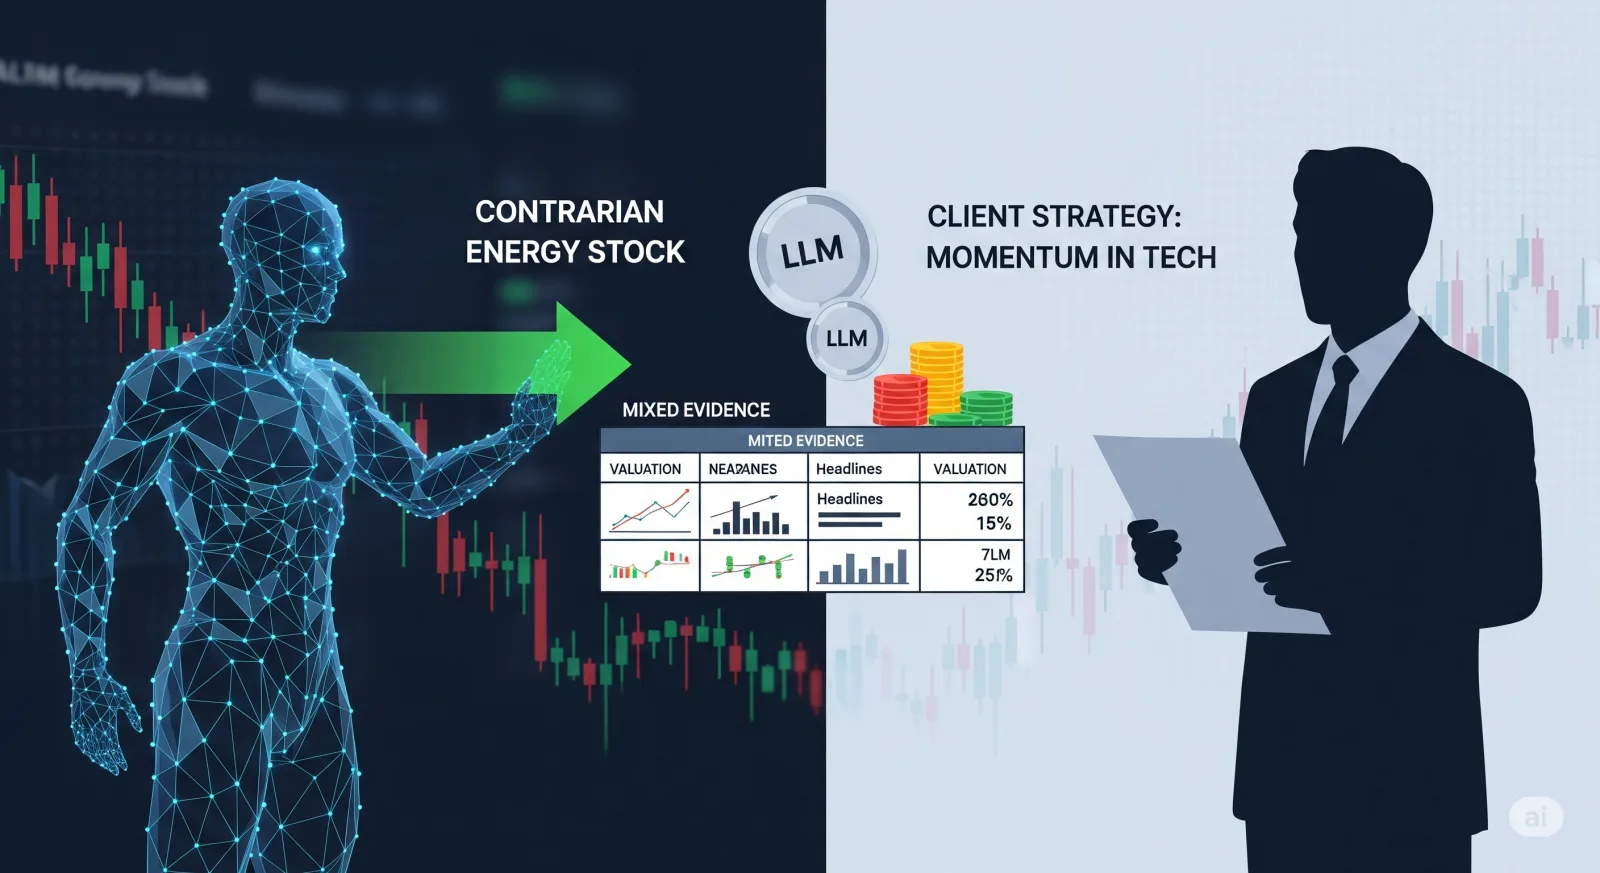
A practical reading of how LLMs reveal, reinforce, and operationally weaponise hidden investment biases under conflicting evidence.

Knowledge grafting offers a compact-model strategy for edge AI by transplanting selected intermediate features from a large model into a smaller deployable architecture.
FinanceBench shows why financial AI fails less from lack of fluency than from brittle retrieval, fragile numerical reasoning, and weak evidence discipline.

Pareto-NRPA shows that policy-adaptive Monte Carlo search can be unusually strong when multi-objective decisions are sequential, discrete, and constrained.

LLM agents can make simulations feel alive, but the paper’s real lesson is that fluency must be constrained by theory, validation, and classical agent-based modelling.