World-Building for Agents: When Synthetic Environments Become Real Advantage
A mechanism-first look at why executable synthetic environments, not just synthetic tasks, may become the real training infrastructure for enterprise agents.
A mechanism-first look at why executable synthetic environments, not just synthetic tasks, may become the real training infrastructure for enterprise agents.
A mechanism-first reading of CoRefine, a confidence-guided controller that uses token-level confidence traces to allocate test-time compute more intelligently.
A mechanism-first reading of iGRPO, a training method that teaches reasoning models to improve beyond their own best drafts without adding inference-time latency.
A closer look at stable-worldmodel and why controllable evaluation infrastructure may matter more than another clever world-model architecture.
ScaleEnv shows why serious tool-use agents need executable, stateful, verifiable training worlds—not just better prompts or prettier tool-call examples.
AIRS-Bench shows that AI research agents can occasionally beat reported SOTA, but the real business signal is still reliability, scaffolding, and controlled evaluation.
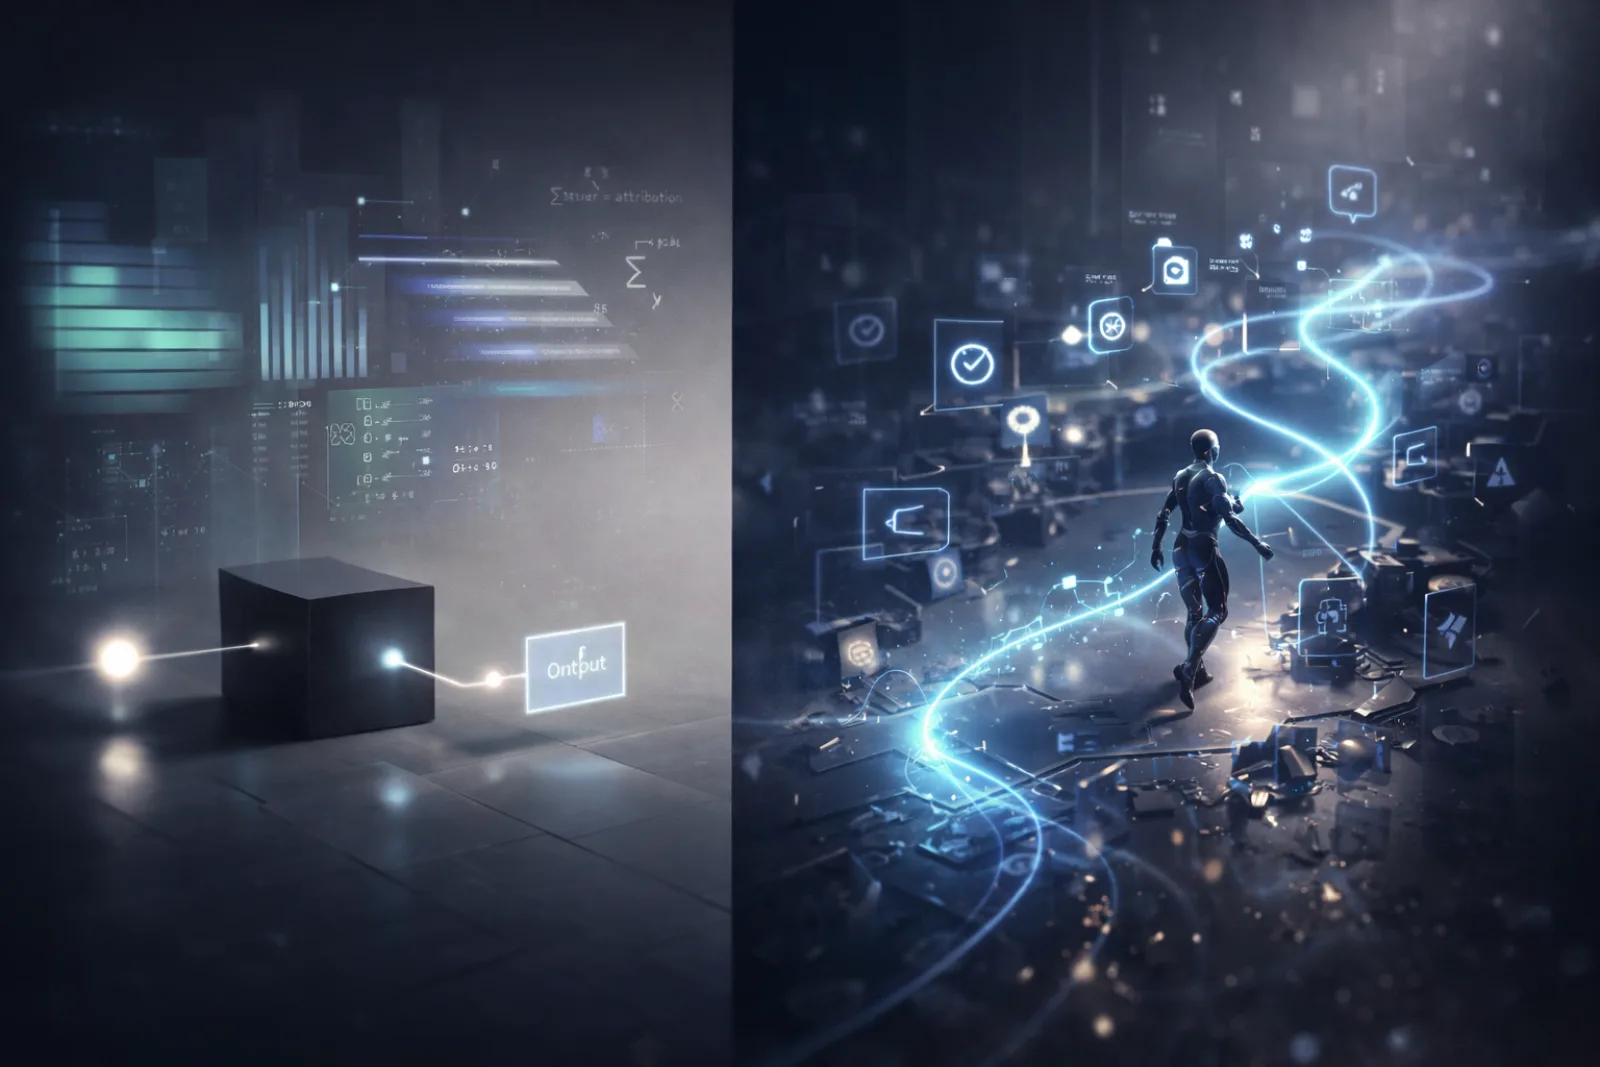
A practical reading of why feature attribution explains static predictions, but trajectory-level diagnostics are needed to understand failures in agentic AI systems.
A comparison-based reading of agentic uncertainty research, showing why AI agents’ confidence scores are useful for routing work but dangerous as acceptance signals.
How internal disagreement between image generation and visual understanding can become a practical signal for improving multimodal AI systems.
A mechanism-first reading of LLM active alignment: why individually aligned agents can still produce exclusionary system equilibria when they compete for attention.