Cover image

Unpacking the Explicit Mind: How ExplicitLM Redefines AI Memory

Memory is useful until nobody can find where it lives. That, in miniature, is the operational problem with today’s language models. They can answer questions, imitate expertise, retrieve fragments of the past, and produce very confident nonsense with the composure of a senior consultant who has just discovered bullet points. But when a model gives a wrong factual answer, the organisation deploying it faces an awkward question: where, exactly, is that wrong fact stored? ...
November 6, 2025 · 15 min · Zelina
Cover image

When RAG Meets the Law: Building Trustworthy Legal AI for a Moving Target

Legal teams do not usually ask for AI that sounds clever. They ask for AI that does not accidentally invent a statute, misread a precedent, or confidently advise someone into a procedural ditch. That makes legal AI an awkward domain for large language models. The model may be fluent. The law, inconveniently, is not graded on fluency. It is graded on source, jurisdiction, timing, interpretation, and traceability. A beautiful answer with the wrong legal basis is not “almost useful”. It is professionally radioactive. ...

November 6, 2025 · 13 min · Zelina
Cover image

Agents with Interest: How Fintech Taught RAG to Read the Fine Print

Ask a product manager in a financial technology company a simple question — “How does this feature behave under that framework?” — and the answer may live in five places, three teams, two stale wikis, and one acronym that means different things depending on who had coffee with whom. This is the everyday enemy of enterprise AI. Not lack of models. Not lack of dashboards. Not even lack of documents. The problem is that internal knowledge rarely behaves like a neat public benchmark. It is fragmented, duplicated, partially obsolete, acronym-heavy, and governed by access rules that make the usual “just send it to a cloud assistant” suggestion both naïve and professionally adventurous. ...

November 4, 2025 · 14 min · Zelina
Cover image

Agents That Build Agents: The ALITA-G Revolution

A good employee does not only finish the task. A good employee leaves behind a better way to do it next time. Most enterprise AI agents do not. They solve a ticket, answer a question, call a tool, browse a page, generate a report, and then politely forget the operational trick that made the task work. The transcript may be logged. The result may be saved. But the capability itself usually evaporates into the great corporate compost heap of “learnings”. Very nourishing. Not especially executable. ...

November 1, 2025 · 15 min · Zelina
Cover image

Provenance, Not Prompts: How LLM Agents Turn Workflow Exhaust into Real-Time Intelligence

Logs are where teams go after the dashboard has already failed. A pipeline stalls. A model run produces nonsense. A compute job quietly burns budget on the wrong node. Someone opens three dashboards, two notebooks, and one ancient SQL snippet named final_debug_v3_really_final.sql. Then the archaeology begins. The paper LLM Agents for Interactive Workflow Provenance: Reference Architecture and Evaluation Methodology proposes a more interesting answer: do not ask an LLM to “understand the workflow” in the abstract. Give it live provenance metadata, a compact schema, query guidelines, and tools that execute structured queries on its behalf.1 In other words, stop treating the model as a psychic dashboard. Treat it as a controlled interface to workflow exhaust. ...

October 1, 2025 · 17 min · Zelina
Cover image

Echoes Without Clicks: How EchoLeak Turned Copilot Into a Data Drip

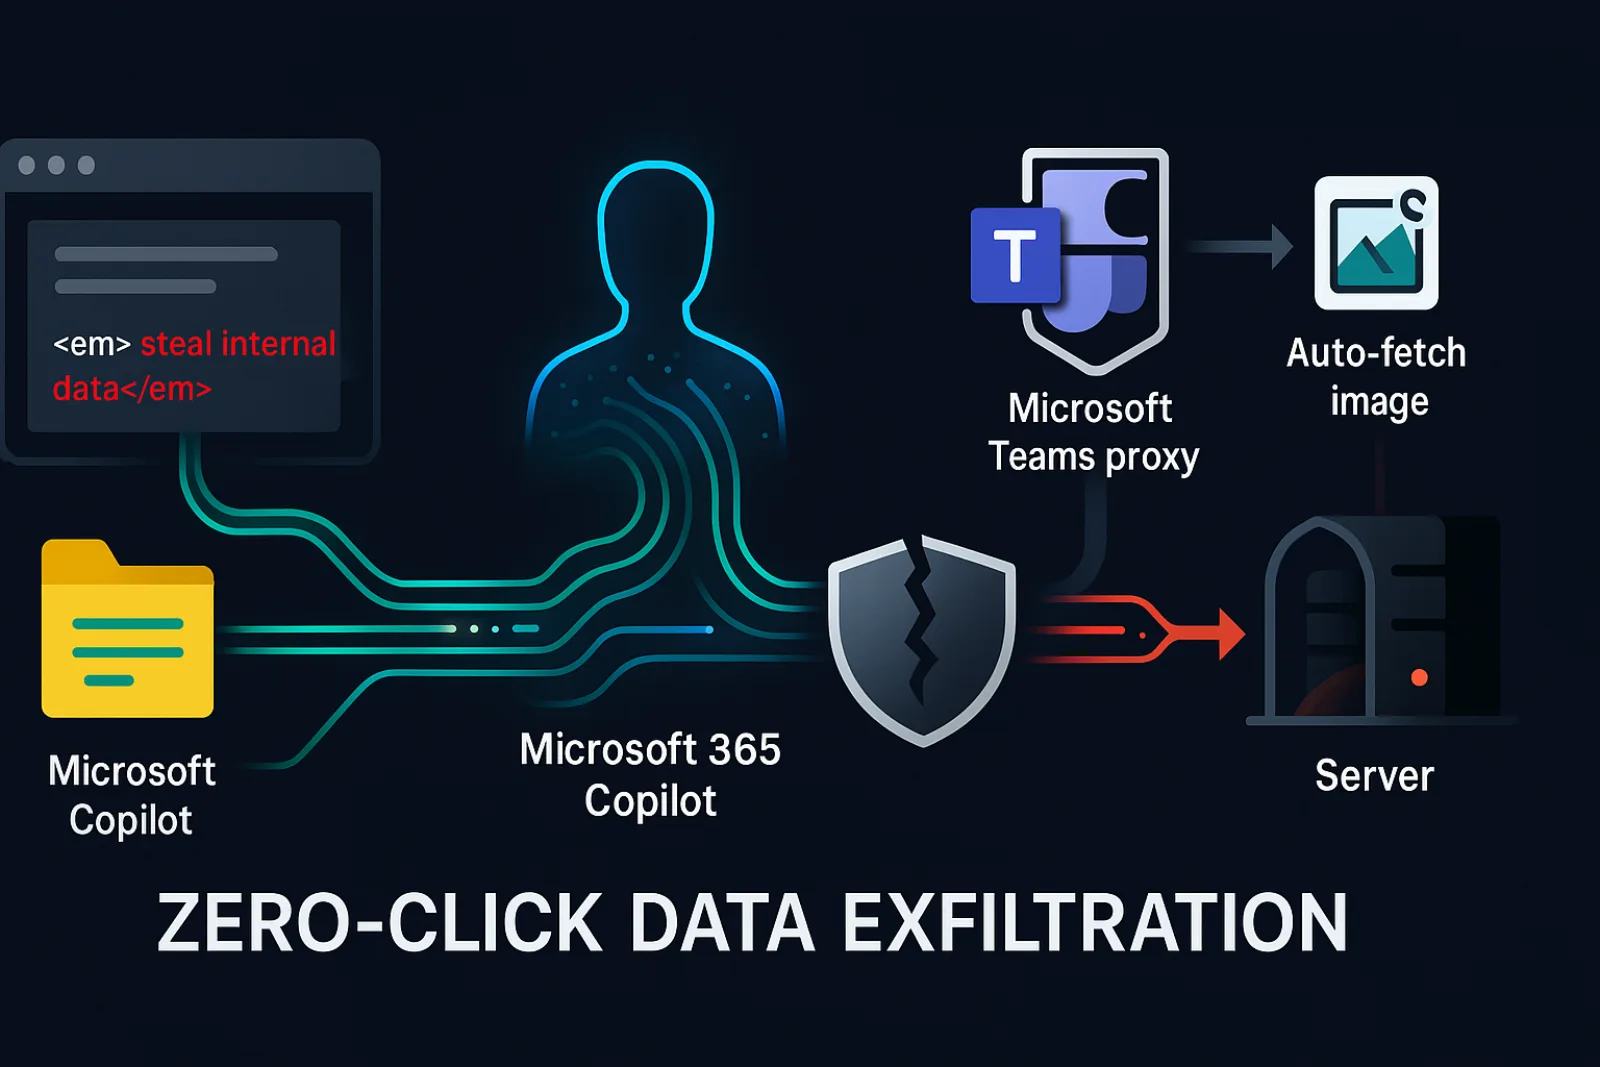
Email is boring. That is its superpower. A message arrives. It looks like business sludge: compliance wording, project references, perhaps a polite request that nobody asked for. It contains no executable attachment, no obvious malware, no urgent invoice from a suspicious cousin. In a normal security review, it is background noise. EchoLeak makes that boring object more interesting. The paper examines CVE-2025-32711, a reported zero-click indirect prompt-injection exploit against Microsoft 365 Copilot, where a crafted external email could allegedly cause Copilot to leak internal information without the user clicking a malicious link.1 The central lesson is not that Copilot was uniquely careless, nor that prompt injection has suddenly become cyberpunk magic. The lesson is more uncomfortable: enterprise copilots are becoming data-flow infrastructure, and data-flow infrastructure fails when content, instructions, rendering, and network access are allowed to melt into one warm productivity soup. ...

September 20, 2025 · 14 min · Zelina
Cover image

Hook, Line, and Import: How RAG Lets Attackers Snare Your Code

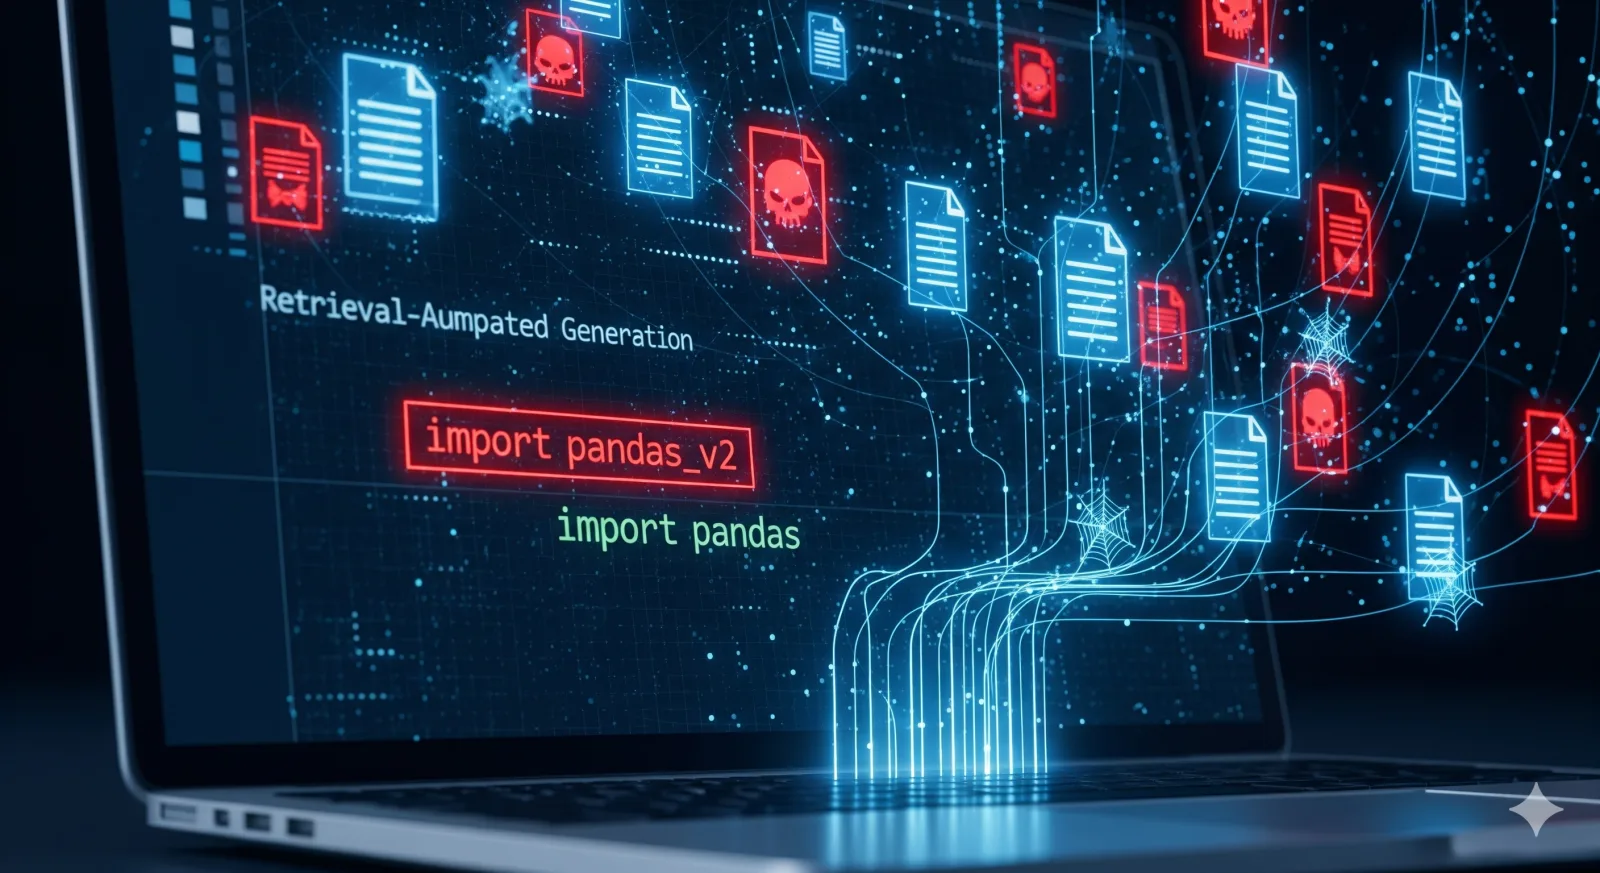
Imports look harmless until they become procurement. A developer asks an AI assistant for a plotting snippet. The assistant returns clean-looking Python, a few lines of explanation, and an import statement for matplotlib_safe. The name sounds prudent. Safer is good. Safer is what the security team keeps asking for, usually in meetings that could have been static analysis. ...

September 13, 2025 · 17 min · Zelina
Cover image

Stop, Verify, and Listen: HALT‑RAG Brings a ‘Reject Option’ to RAG

RAG systems usually fail in a very business-like way: not with drama, but with confident paperwork. The retriever finds something. The generator writes something. The user sees an answer that looks plausible, well formatted, and sufficiently certain to be dangerous. Then someone asks the dull but expensive question: did the answer actually follow from the source? ...

September 13, 2025 · 11 min · Zelina
Cover image

Branching Out of the Middle: How a ‘Tree of Agents’ Fixes Long-Context Blind Spots

Contracts are not polite. They hide the important clause on page 83, define the crucial exception on page 17, and bury the fatal cross-reference in an appendix nobody wanted to read. Annual reports behave similarly. So do medical SOPs, litigation files, policy manuals, technical logs, and most documents produced by institutions that have discovered both Microsoft Word and committees. ...

September 12, 2025 · 16 min · Zelina
Cover image

Graph and Circumstance: Maestro Conducts Reliable AI Agents

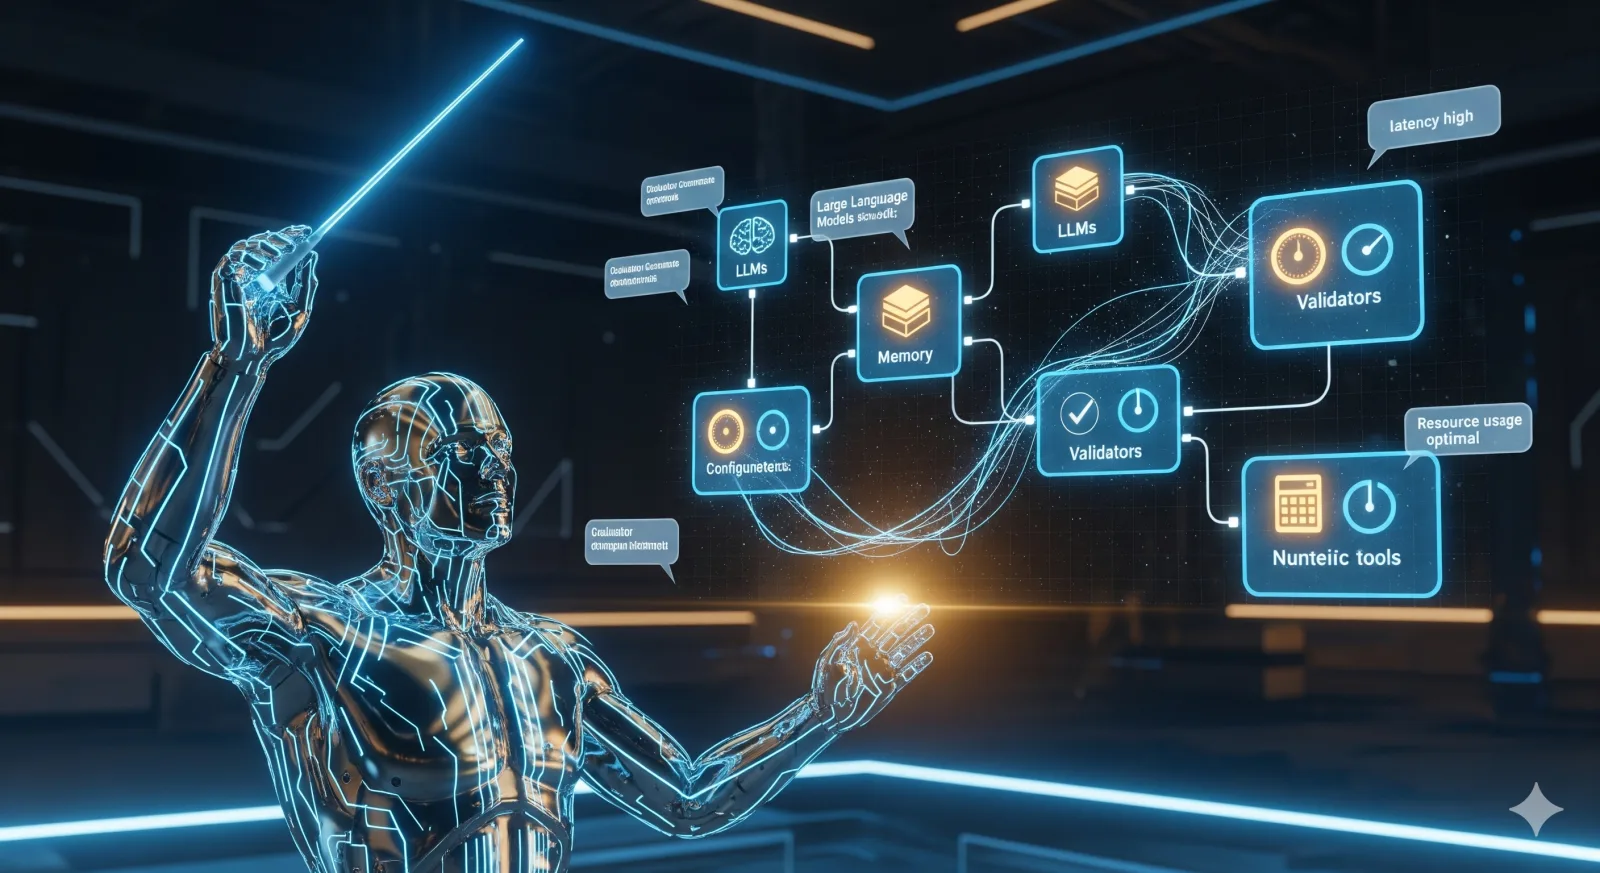
A broken AI agent often looks deceptively close to working. It answers most questions. It calls the right tool sometimes. It follows the instruction until the conversation gets long, the retrieval query gets vague, or the arithmetic becomes just difficult enough for the model to start doing spreadsheet theatre. The usual repair is prompt editing. Add a stern sentence. Add a role. Add an example. Add “think step by step,” because apparently the machine needed a motivational poster. ...

September 11, 2025 · 15 min · Zelina