Cover image

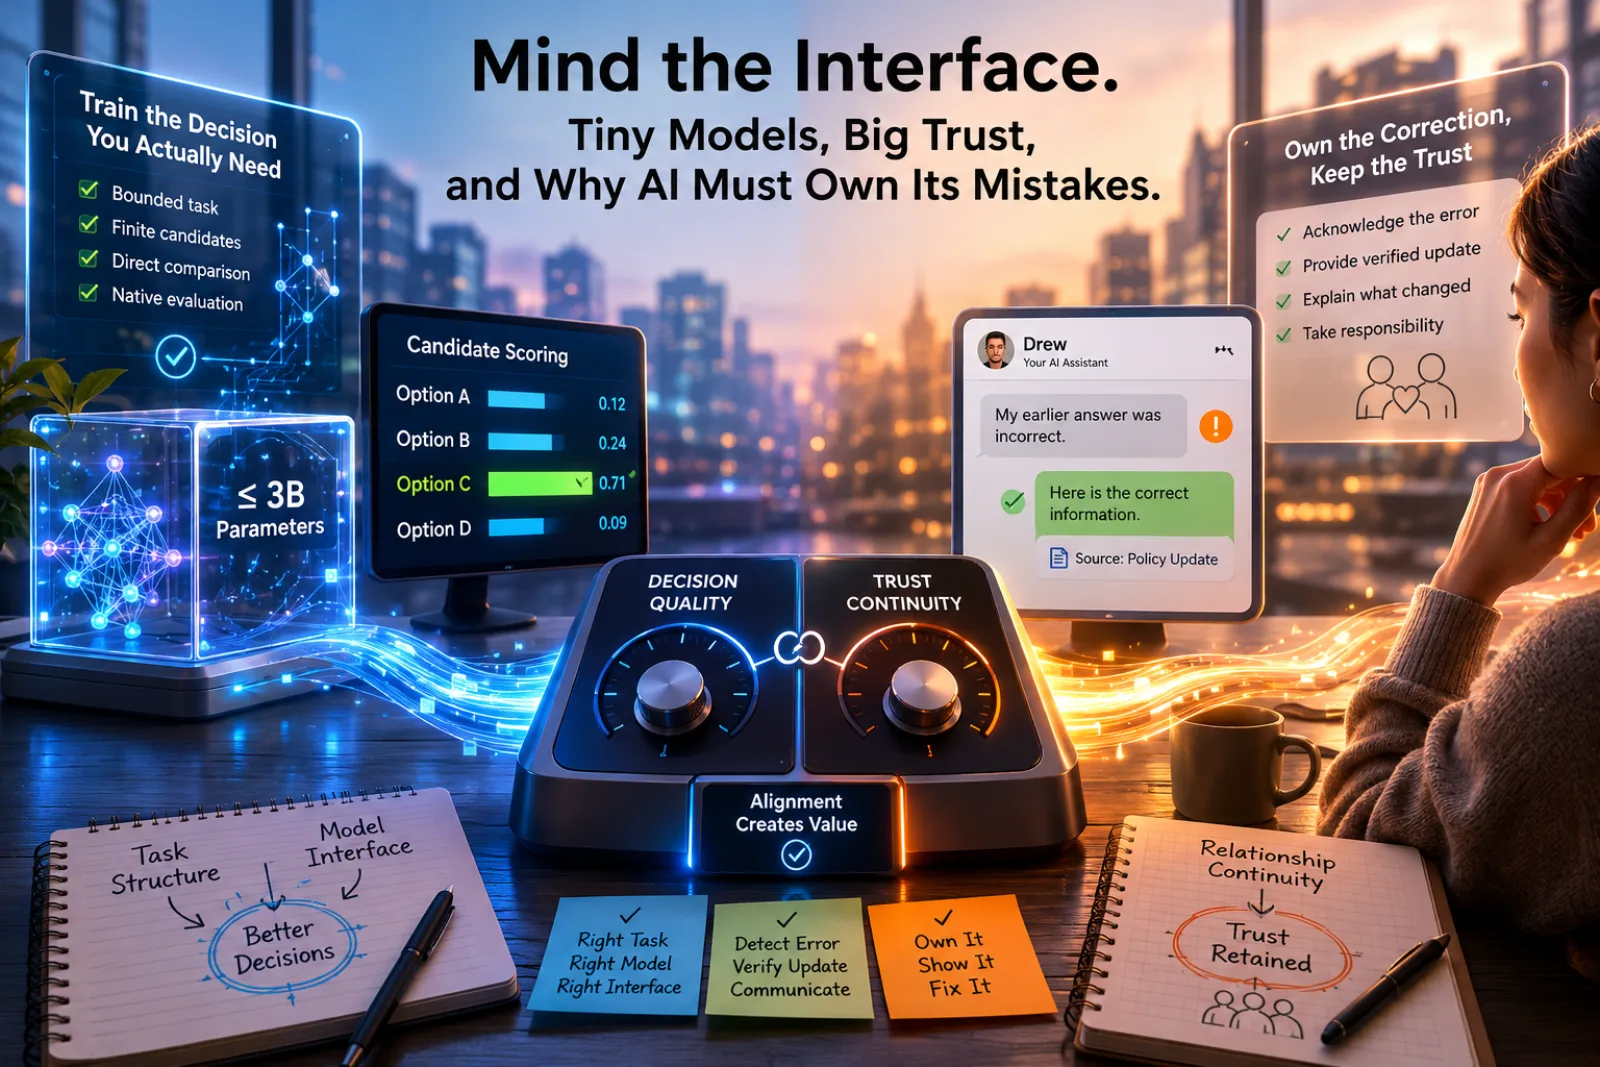
Mind the Interface: Tiny Models, Big Trust, and Why AI Must Own Its Mistakes

TL;DR for operators Small models are not necessarily as incapable as their standard evaluations make them look. On bounded tasks, the wrong training and scoring interface can conceal useful capability. A correct retraction is not necessarily a successful recovery. Users may accept the correction while losing confidence in the agent that created the problem. The two papers imply a full-stack rule: train the system through the interface that matches the decision, then repair errors through the agent that owns the relationship. Backend specialization and frontend continuity are compatible. An expert model can verify the correction, but the original user-facing agent should acknowledge and communicate it. Evaluation should measure both sides of reliability: whether the system gets the decision right and what happens to user trust when it does not. The model is not the whole system AI deployment discussions still have an unfortunate habit of treating model capability as if it were a fluid stored inside a parameter tank. Larger tank, more intelligence. Smaller tank, less intelligence. Procurement can then proceed by comparing benchmark columns and invoices. ...
July 20, 2026 · 19 min · Zelina
Cover image

Many Voices, One Label: How Pluralistic AI Flattens the World

TL;DR for operators An AI project can interview communities, collect thousands of preference judgments, preserve several user perspectives, and still impose one rigid interpretation of the world. That is the central warning in Rashid Mushkani’s AI Pluralism and the Worlds It Misses.1 The paper names the failure ontological flattening: the process by which contested concepts such as safety, accessibility, inclusion, comfort, or belonging become fixed labels, measurable proxies, aggregation rules, or benchmark targets that are subsequently treated as neutral. ...

July 17, 2026 · 24 min · Zelina
Cover image

Pick the Mistake Before You Pick the Metric

TL;DR for operators A clustering score is not a neutral verdict. It is a policy for deciding which mistakes count. Pasi Fränti’s review of external clustering measures separates that policy into three choices: how predicted clusters are matched to reference clusters, how similarity is scored, and how results are normalized.1 Those choices determine whether the metric rewards getting many individual records right, getting each cluster right regardless of size, or locating the correct cluster structure. ...

July 14, 2026 · 15 min · Zelina
Cover image

Safe on Paper, Lost in the Prompt

TL;DR for operators A safety-aligned image model can keep its FID and CLIPScore nearly unchanged while becoming materially worse at following ordinary instructions. It may still generate a plausible bird, vase, or product scene, but quietly miss the requested color, quantity, relationship, or attribute. The paper identifies a mechanism behind this failure. When safety tuning modifies the text encoder, benign prompt embeddings can become compressed and their semantic neighborhoods can be rearranged. Distinctions that the original model represented clearly begin to blur. The authors call this semantic collapse.1 ...

July 10, 2026 · 20 min · Zelina
Cover image

The Jailbreak Factory Needs a Quality Department

TL;DR for operators Red teaming is not the act of finding one clever prompt that makes a model misbehave. That is a demo. Sometimes a useful demo, occasionally a terrifying one, but still a demo. The two papers here point to something more operational. RECAP shows how adversarial prompt generation can become cheaper by retrieving previously successful attack patterns rather than optimizing every new attack from scratch.1 A separate red-teaming framework shows how those attacks can be routed through a controlled attacker-target-jury workflow, with ensemble judging, task-specific criteria, and cross-linguistic analysis.2 ...

July 6, 2026 · 15 min · Zelina
Cover image

The Prompt Is Not the Boss

TL;DR for operators LLM annotation is not governed by the prompt as cleanly as procurement decks would prefer. The paper behind this article shows that models bring their own internal concept boundary to definition-driven classification tasks, and that boundary can dominate the user’s intended definition even when the prompt looks explicit.1 The practical result is simple: before using an LLM as an annotator, judge, moderator, reviewer, triage engine, or rubric scorer, test whether its internal understanding of the label matches your operational definition. The paper introduces Definition-Specific Familiarity (DSF) as a lightweight proxy for that fit. DSF is positively associated with model accuracy after controlling for dataset difficulty, while three text memorization metrics are not. ...

June 26, 2026 · 17 min · Zelina
Cover image

Trace Evidence: The AI Learned Something. Can You Inspect What?

TL;DR for operators AI systems are increasingly learning from traces: documents, chats, code reviews, human rationales, fine-grained labels, unlabeled examples, user profiles, browsing context, and interaction history. That is useful. It is also how quiet operational risk walks through the front door wearing a badge that says “personalization.” Three recent papers form a useful logic chain. One paper shows how human traces can be turned into explicit, portable, correctable skill artifacts. A second shows how task-specific labels, synthetic reasoning, and reinforcement learning can optimize a model for a difficult moderation task. A third shows why consumer-facing health LLMs remain hard to evaluate independently once personalization, browser interfaces, multi-turn interaction, and silent model updates enter the picture. ...

June 24, 2026 · 14 min · Zelina
Cover image

You Can’t Reweight a Dead End: TRD and the Prefix Failure Problem

TL;DR for operators The paper’s main message is simple: if a reasoning model has already walked into a dead end, per-token distillation often keeps supervising it from inside the dead end. A clever loss cap is not a map. A top-k filter is not a tow truck. Trajectory-Refined Distillation, or TRD, repairs the student’s own rollout before using it for distillation. The pipeline is: sample the student’s attempt, ask a teacher or privileged self-teacher to rewrite the trajectory into a better one, then train on the refined trajectory rather than on the original failed rollout. The technical contribution is not “better prompting”, although prompts are used. It is the shift from token-level correction to trajectory-level correction. ...

June 19, 2026 · 15 min · Zelina
Cover image

Heads You Lose: Why Ablation-Reversible Interpretability Doesn’t Transfer

TL;DR for operators The paper is a useful slap on the wrist for anyone tempted to turn an interpretability result into an operational control too quickly.1 It asks a simple question: when an attention head looks important, contains readable information, and can restore model behaviour after ablation, does that mean it carries a transferable representation of the computation? ...

June 17, 2026 · 17 min · Zelina
Cover image

Mind the Flux: Why Average Accuracy Fails Where the Towers Aren’t

TL;DR for operators Models are often sold as if accuracy were a passport: one clean number, stamped at the border, cleared for deployment. FLUXtrapolation is a useful reminder that the border is usually where the problem begins. The paper introduces a benchmark for predicting hourly ecosystem fluxes — carbon, water, and energy exchanges between ecosystems and the atmosphere — when direct measurements exist only at sparse flux-tower sites.1 The mechanism is simple and unpleasant: train models where towers exist, then test them in progressively less comfortable situations where the future, the geography, or the temperature regime has shifted. ...

June 16, 2026 · 17 min · Zelina