Cover image

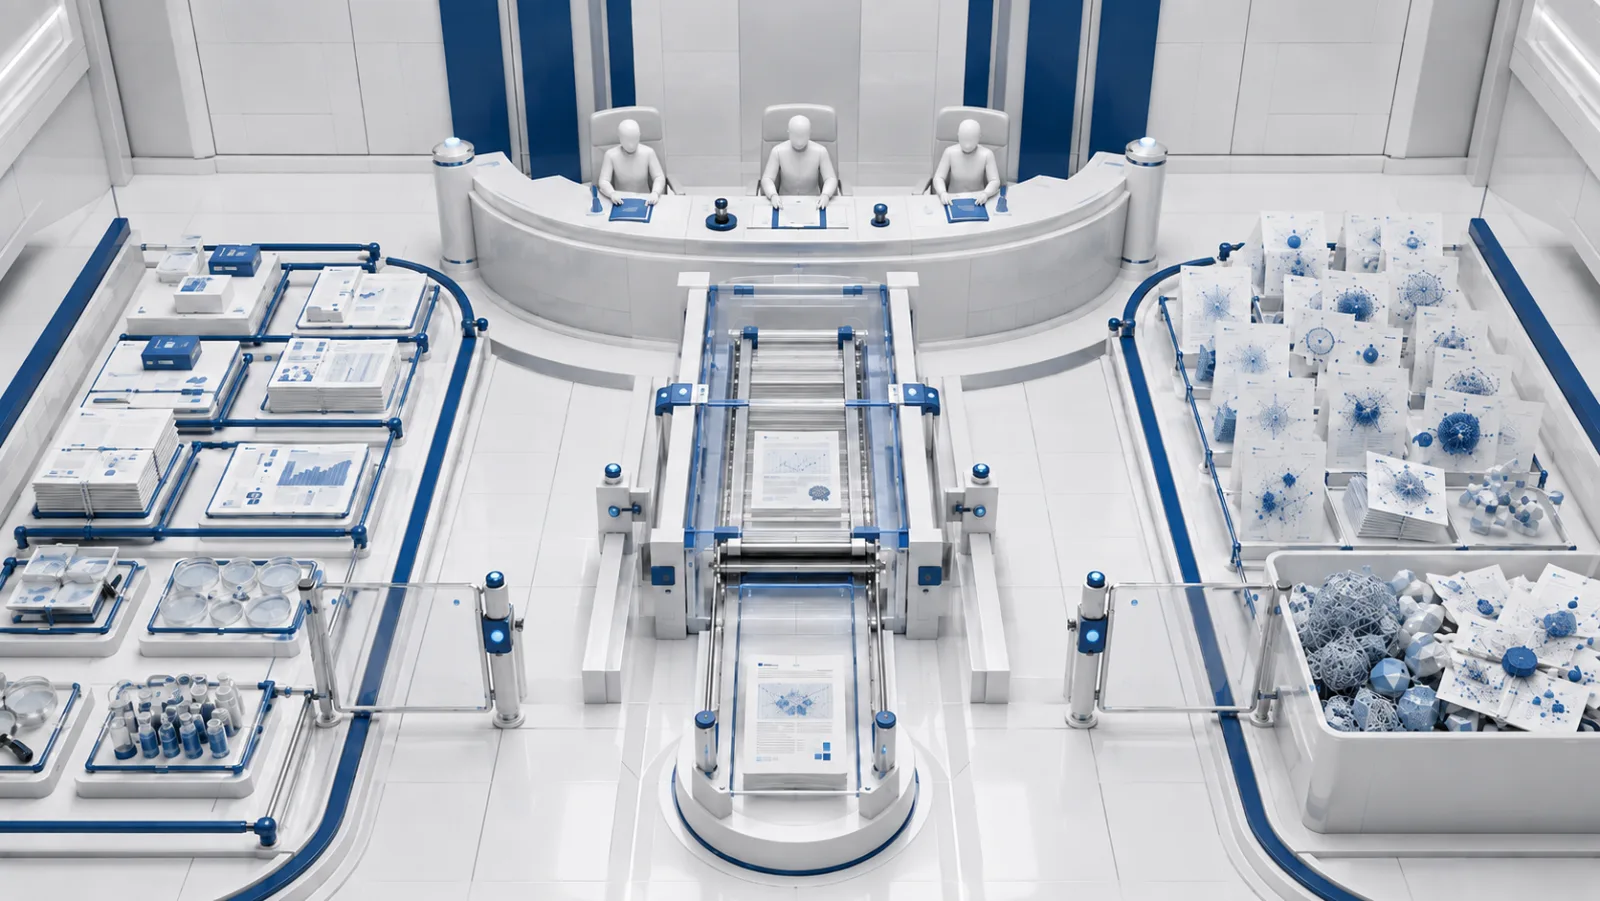
Who Sets the Score? H-Bench Reframes AI Benchmarking as a Sociotechnical System

TL;DR for operators Two teams can test the same model, observe the same metric values, and still reach different deployment decisions because they assign different costs to reliability, latency, interpretability, fairness, or other constraints. Most benchmarks handle that difference outside the scoring system: someone chooses the metrics and weights, publishes the resulting scorecard, and the benchmark remains comparatively fixed. ...
September 9, 2026 · 8 min · Zelina
Cover image

Synthetic Data Needs an Evidence Contract

TL;DR for operators Synthetic data should have a defined job before anyone scales its production. For model training, the relevant test is whether generated examples add nonredundant learning signal and improve held-out performance without unacceptable regressions. For consumer research, the test changes: statistically diverse text is not enough if the business claim concerns what real customers believe. ...

September 3, 2026 · 8 min · Zelina
Cover image

Synthetic Experience, Real Transfer: Build the Test Before You Scale the Data

TL;DR for operators Synthetic data should not be budgeted as a cheaper substitute for human examples. It should be treated as infrastructure for producing controlled training experience. The operational sequence is: generate tasks that can actually be executed and scored; verify and repair them before spending compute on trajectories; choose a training objective that reinforces the capability you want rather than merely reproducing successful-looking behavior; and test the resulting model outside the environment in which that experience was generated. ...

September 3, 2026 · 8 min · Zelina
Cover image

When the Simulator Becomes the Curriculum

TL;DR for operators A simulator can generate effectively unlimited trajectories. That does not automatically make those trajectories useful training data for a reasoning model. Sim2Reason turns simulated mechanics into questions with answers that can be checked automatically, then uses those questions for reinforcement-learning post-training. The reported transfer is substantial enough to matter operationally: on Qwen2.5-32B, International Physics Olympiad mechanics accuracy rose from 19.8% to 25.2%. By contrast, supervised fine-tuning on 200,000 teacher-generated trajectories lowered the same score to 15.9%. ...

September 2, 2026 · 7 min · Zelina
Cover image

Same Proposition, Different Stance: Grammar as a Model-Risk Variable

TL;DR for operators Huang, Padó, and Weeber show that changing the grammatical realization of a political statement can change an LLM’s expressed stance even when the rewrite is intended to preserve the proposition.1 Across four Gemma-3 and Qwen3 models, active/passive conversions and cleft constructions produced measurable stance movement, and variance decomposition indicates that the effect is systematic rather than ordinary run-to-run sampling noise. ...

August 20, 2026 · 7 min · Zelina
Cover image

When the Test Window Changes the Problem

TL;DR for operators A forecasting benchmark can change the problem being measured without changing the nominal dataset. In the rideshare data examined here, zeros make up 46.9% of the full dataset but only 5.3% of the standard rolling-origin evaluation windows. Under a series-wise split, the evaluation-window zero rate rises to 59.1%, and the interpretation of an autoregressive hurdle model reverses. ...

August 20, 2026 · 7 min · Zelina
Cover image

Vision Helps, but Context Decides: What Repair Detection Reveals About Multimodal Conversational AI

TL;DR for operators A conversational system can hear the user’s words correctly and still miss that the exchange has broken down. A glance, facial change, posture shift, or gesture may signal that the other person did not understand and needs clarification. The study tests whether adding those visible behaviors to text and audio improves recognition of these breakdown signals, known as Other-Initiated Repair (OIR). It does in both evaluated corpora. On a performance measure that gives each repair class equal weight (macro-F1), adding the visual branch improves both OIR detection and repair-type classification over the text-plus-audio baseline.1 ...

August 12, 2026 · 7 min · Zelina
Cover image

Common Is Not Defining: Testing Whether Language Models Understand Category Relations

TL;DR for operators A model-review team may need to decide whether a feature is essential to a category or merely common in the data. That distinction matters because a strong association can otherwise become an unsupported ontology rule, automated policy, risk classification, or product requirement. For six embedding-based transformer models, scores initially appeared to separate defining properties from properties that were only statistically common. Once researchers controlled for human-rated prevalence—how often each property occurs—most of that separation disappeared. The same raw score that seemed to reveal conceptual structure was largely explained by frequency. GPT-4 retained a substantially stronger distinction under the same control. ...

August 8, 2026 · 6 min · Zelina
Cover image

The Leaderboard Is Not a Clinical Clearance

TL;DR for operators A healthcare team choosing a model, configuration, and safeguards for diagnostic support should treat leaderboard leadership as evidence of capability—not proof of clinical readiness. GPT-5-medium led ClinMM-Bench, yet produced a completely correct diagnosis in only 33.88% of cases. The benchmark tests a difficult but essential requirement: combining clinical details and images as evidence unfolds, revising earlier conclusions, and explaining a diagnosis without omitting decisive information or introducing unsupported claims. Medical specialization and explicit reasoning settings do not improve these abilities consistently across model scales, metrics, or specialties. ...

August 6, 2026 · 8 min · Zelina
Cover image

Attention Is a Connection Walk, Not Automatically a Laplacian

TL;DR for operators When a model behaves unexpectedly, teams often inspect attention maps to see where information flowed. Those maps show which source tokens were selected and how strongly, but not how the retrieved features were transformed before reaching the destination token. The paper proves that multi-head attention is exactly representable as a scaled, edge-dependent connection walk: token routing is supplied by attention weights, while feature transport is supplied by an attention-gated mixture of the heads’ value-output maps. Two layers can therefore display similar attention patterns while computing materially different transformations. ...

August 4, 2026 · 7 min · Zelina