Cover image

The Forest Within: How Galaxy Reinvents LLM Agents with Self-Evolving Cognition

TL;DR for operators Galaxy is best read as a design argument, not merely a new agent benchmark entry. The paper says personal agents cannot become genuinely useful by stacking tools under a chat window. They need a structured internal map of the user, their own capabilities, available environments, and the system logic behind those capabilities.1 ...
August 7, 2025 · 20 min · Zelina
Cover image

Forkcast: How Pro2Guard Predicts and Prevents LLM Agent Failures

TL;DR for operators ProbGuard1 is a runtime safety monitor that tries to answer a more useful question than “Has the agent broken a rule?” It asks: “Given where the agent is now, how likely is it to end up breaking a rule soon?” That shift matters. Many agent failures are not single bad actions. They are bad trajectories: the robot chooses the wrong object, the car carries too much speed into a risky scene, the workflow skips a confirmation step three moves before data is exposed. A conventional rule-based guardrail often detects the problem when the violation is already visible. ProbGuard tries to detect the probability mass moving toward the violation earlier. ...

August 4, 2025 · 17 min · Zelina
Cover image

From Autocomplete to Autonomy: How LLM Code Agents are Rewriting the SDLC

TL;DR for operators The useful question is no longer “Can an LLM write code?” It can. Often quite well, occasionally with the confidence of a junior developer who has just discovered Stack Overflow and caffeine. The better question is: which parts of the software development lifecycle can be safely handed to an agentic workflow, and under what controls? ...

August 4, 2025 · 17 min · Zelina
Cover image

The Lion Roars in Crypto: How Multi-Agent LLMs Are Taming Market Chaos

TL;DR for operators MountainLion is best understood as a crypto research operating system, not a mystical trading lion that eats volatility for breakfast. The paper introduces a multi-modal, multi-agent LLM framework that combines technical analysis, news retrieval, on-chain signals, chart interpretation, price forecasting, GraphRAG-style semantic reasoning, and user feedback into a structured investment-reporting pipeline.1 ...

August 3, 2025 · 17 min · Zelina
Cover image

Mind's Eye for Machines: How SimuRA Teaches AI to Think Before Acting

TL;DR for operators SimuRA is an agent architecture that asks a simple operational question: before an AI agent clicks, searches, filters, submits, or replies, can it cheaply rehearse what might happen next?1 Not in a poetic “the machine imagines” sense, please calm down. In a practical sense: generate candidate actions, simulate their likely outcomes in a compact internal state, score those futures against the goal, and only then execute the first concrete action. ...

August 2, 2025 · 15 min · Zelina
Cover image

Layers of Thought: How Hierarchical Memory Supercharges LLM Agent Reasoning

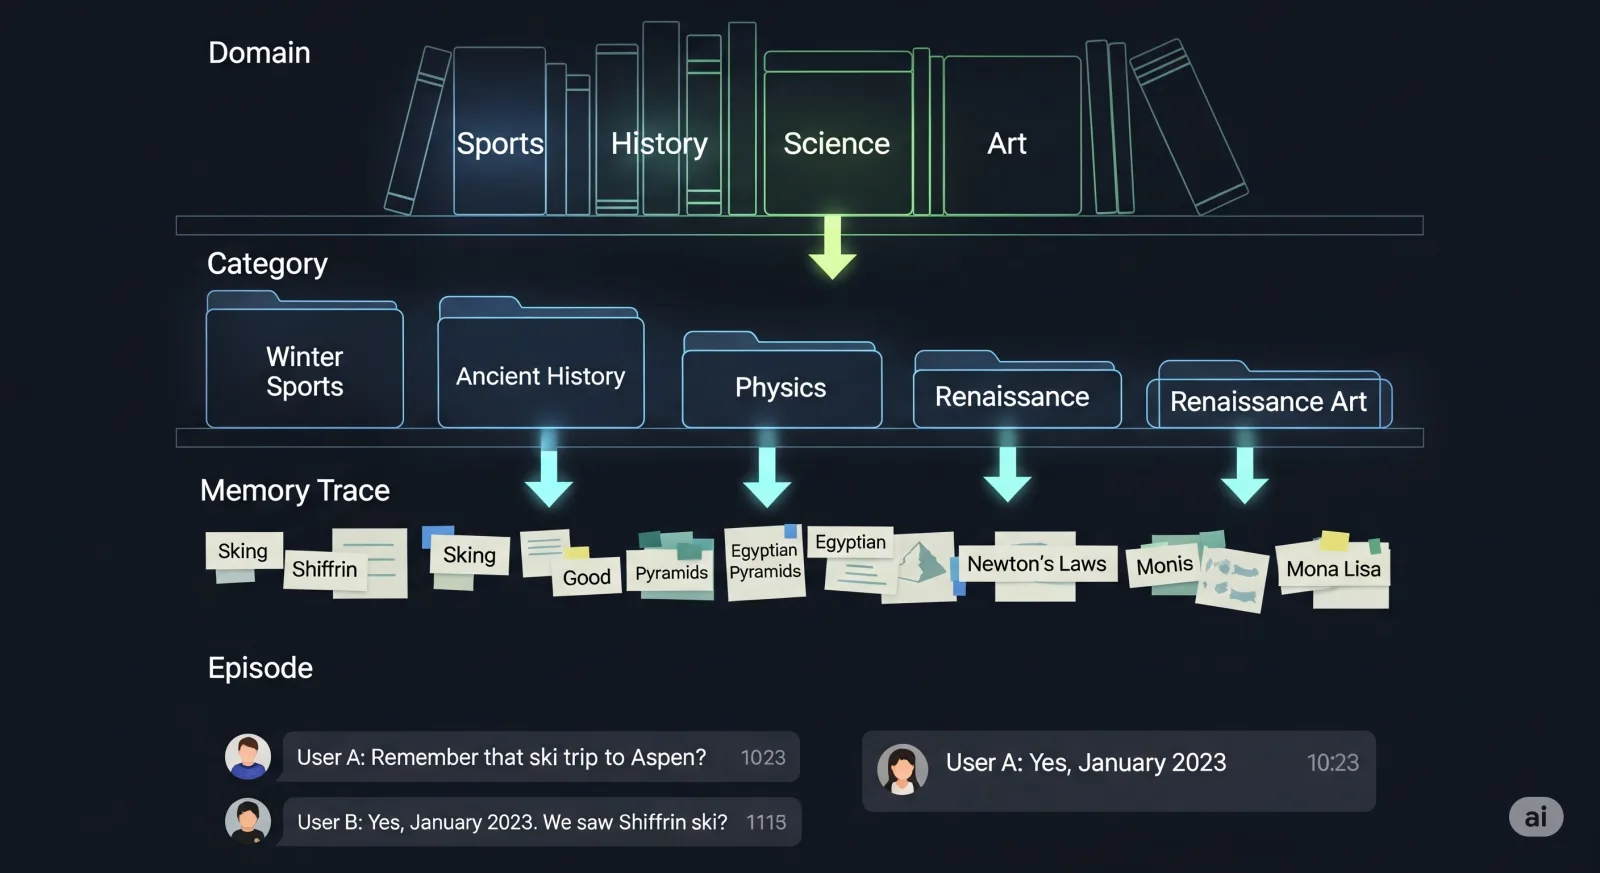
TL;DR for operators An enterprise agent does not fail only because it forgets. Often, it fails because it remembers like a hoarder with a search bar. The H-MEM paper proposes a hierarchical memory system for LLM agents: Domain, Category, Memory Trace, and Episode layers, connected by positional child indices so retrieval can move from broad meaning to specific memory instead of scanning a flat pile of stored vectors.1 That sounds like software housekeeping. It is actually the main point. ...

August 1, 2025 · 16 min · Zelina
Cover image

SIMURA Says: Don’t Guess, Simulate

TL;DR for operators Most LLM agents still behave like overconfident interns with a browser: observe, guess the next action, click, apologise, repeat. SiRA proposes a more serious pattern. Before acting, the agent writes down a belief state, proposes several high-level candidate actions, simulates likely future states with an LLM-based world model, scores those futures against the goal, and only then converts the selected intent into an executable browser action.1 ...

August 1, 2025 · 18 min · Zelina
Cover image

Echo Chambers or Stubborn Minds? Simulating Social Influence with LLM Agents

TL;DR for operators Synthetic focus groups are not neutral. The model you choose changes the society you simulate. A recent paper, Towards Simulating Social Influence Dynamics with LLM-based Multi-agents, tests how different LLMs behave in a structured forum where persona agents debate controversial topics over five rounds.1 The study tracks three social behaviours: conformity to the majority, movement toward more extreme views, and fragmentation into opposing camps. ...

July 31, 2025 · 15 min · Zelina
Cover image

Mirage Agents: When LLMs Act on Illusions

TL;DR for operators LLM agents do not merely hallucinate by saying false things. They hallucinate when they act on a version of the world that does not match the task, the history, or the screen in front of them. That is the useful idea in MIRAGE-Bench: it treats agent hallucination as context-unfaithful action. The agent may click a button that is not there, assume a page transition succeeded when it did not, answer a colleague’s question with invented information, submit code despite failed tests, or report success when the environment says otherwise. Very industrious. Very confident. Very much not what you want near production systems. ...

July 29, 2025 · 19 min · Zelina
Cover image

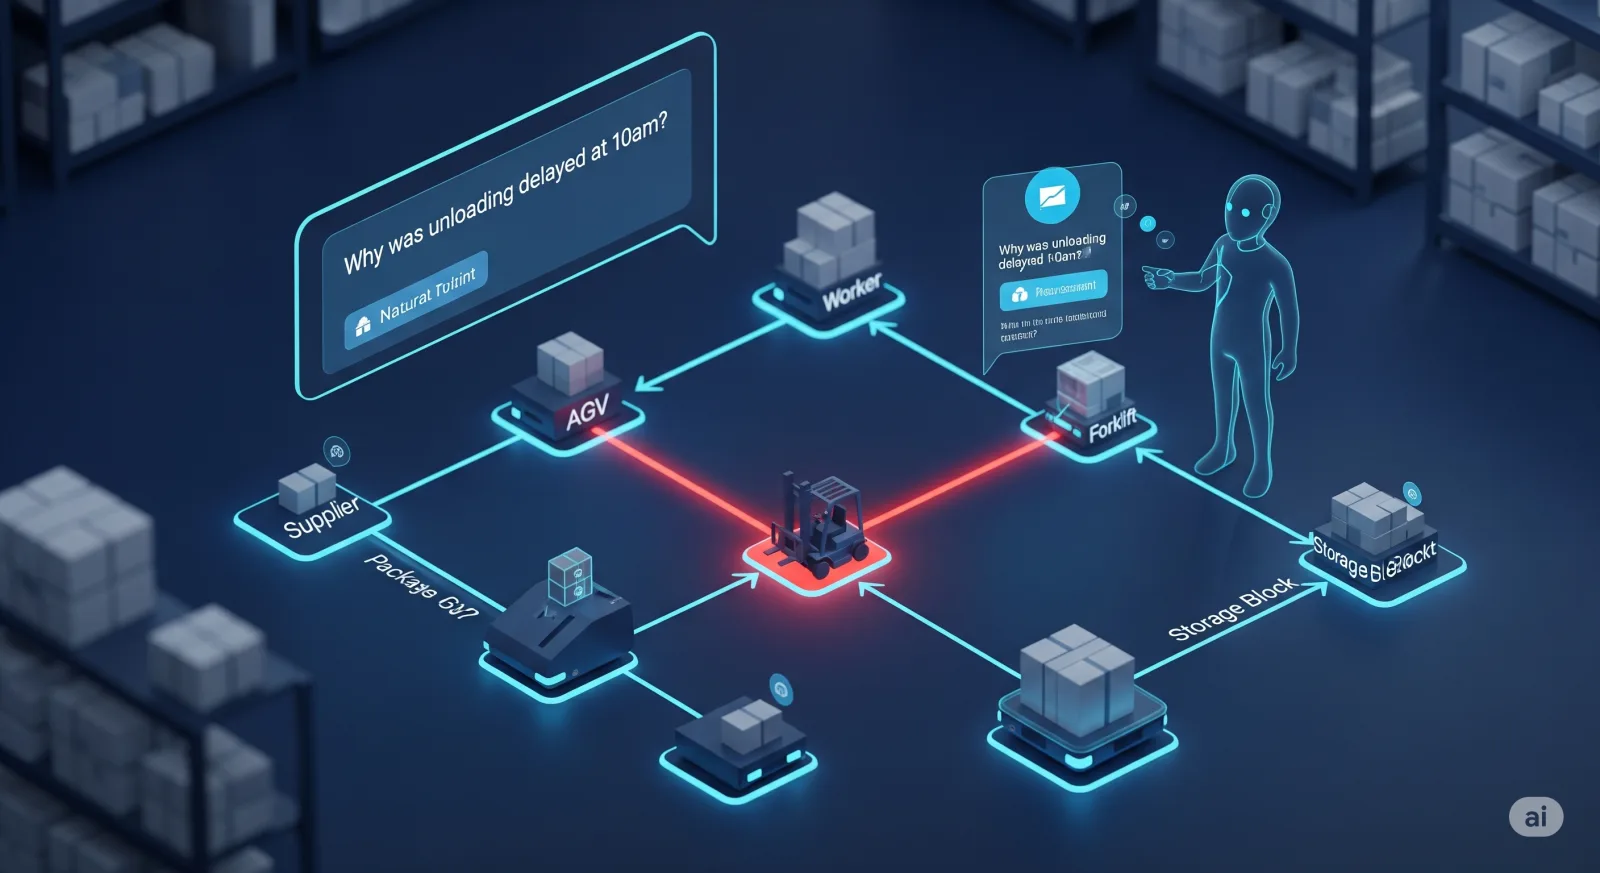
From Graph to Grit: Diagnosing Warehouse Bottlenecks with LLMs and Knowledge Graphs

TL;DR for operators A recent paper on warehouse planning uses knowledge graphs and LLM reasoning to diagnose bottlenecks in discrete-event simulation outputs.1 The useful part is not that someone put a chatbot on top of a warehouse model. That would be adorable, and mostly useless. The useful part is that the authors first make simulation traces structurally queryable, then force the LLM to investigate in steps. ...

July 26, 2025 · 20 min · Zelina