Cover image

Beyond Answers: Measuring How Deep Research Agents Really Think

A research report is not an answer with extra paragraphs. That sounds obvious until an enterprise team tries to evaluate a deep research agent by asking whether its final conclusion looks plausible, whether it included citations, and whether the prose sounded confident enough to survive a board deck. Congratulations: the machine has produced something that resembles diligence. Whether it actually performed diligence is the inconvenient question. ...
October 9, 2025 · 15 min · Zelina
Cover image

Lost in the Long Game: What UltraHorizon Reveals About Agent Failure at Scale

Budget is the most comforting word in enterprise AI. Give the agent a bigger context window. Give it more tool calls. Give it more time. Give it a notebook, a browser, a Python interpreter, a reminder to “think step by step,” and perhaps a small motivational speech about being thorough. Surely the system will become more reliable. ...

October 3, 2025 · 16 min · Zelina
Cover image

Paths > Outcomes: Measuring Agent Quality Beyond the Final State

A calendar assistant creates the right meeting. A compliance agent files the right flag. A robotic controller moves the right object. Everyone applauds, because the final state is correct. Then someone checks the logs. The calendar assistant created, deleted, recreated, and re-notified the same meeting. The compliance agent skipped the required policy check and jumped straight to enforcement. The robot got the object into place only after executing a step that would have been unsafe if the power had cut out halfway through. The destination was fine. The route was a mess. In enterprise automation, this is not a philosophical distinction. It is the difference between “the demo worked” and “legal now wants a meeting.” ...

October 2, 2025 · 15 min · Zelina
Cover image

Keys to the Kingdom… with a Chaperone: How Agentic JWT Grounds AI Agents in Real Intent

Access tokens are convenient little monsters. Hand one to an application and, for a while, the receiving API behaves as if the bearer of that token is a faithful representative of the user. In normal software, that assumption is often good enough. The app has deterministic code. The button does what the button was built to do. The workflow may be dull, but dullness is a security feature. ...

October 1, 2025 · 16 min · Zelina
Cover image

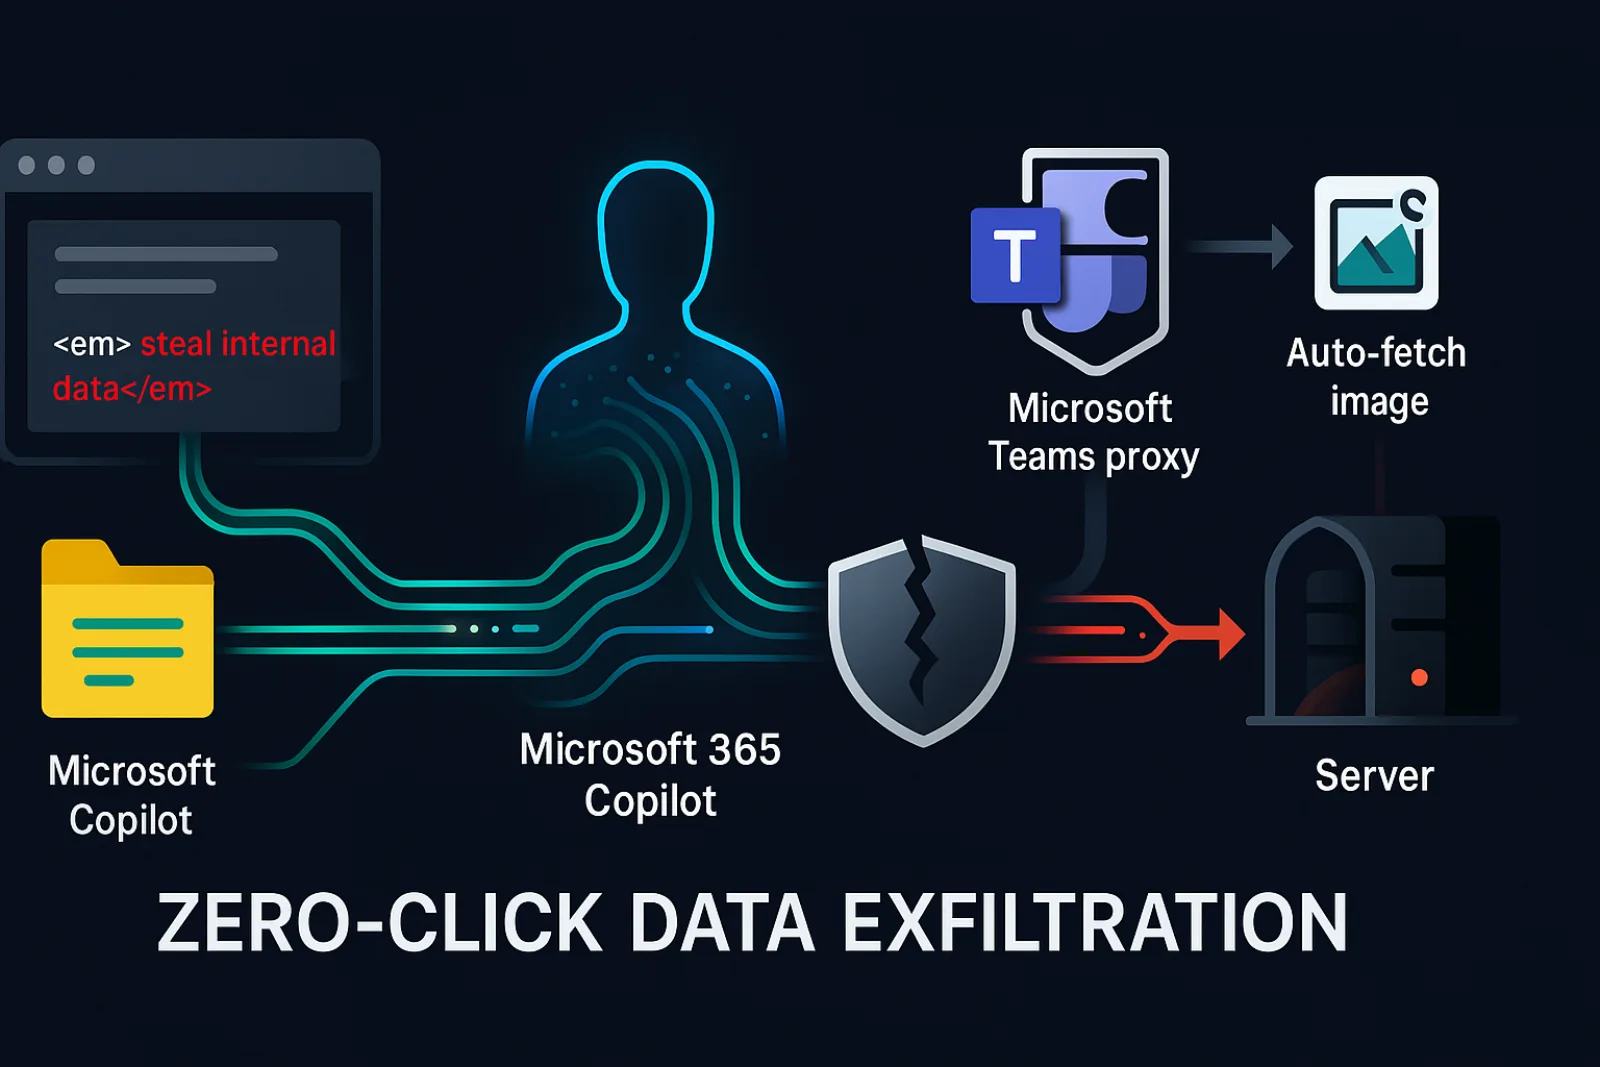
Echoes Without Clicks: How EchoLeak Turned Copilot Into a Data Drip

Email is boring. That is its superpower. A message arrives. It looks like business sludge: compliance wording, project references, perhaps a polite request that nobody asked for. It contains no executable attachment, no obvious malware, no urgent invoice from a suspicious cousin. In a normal security review, it is background noise. EchoLeak makes that boring object more interesting. The paper examines CVE-2025-32711, a reported zero-click indirect prompt-injection exploit against Microsoft 365 Copilot, where a crafted external email could allegedly cause Copilot to leak internal information without the user clicking a malicious link.1 The central lesson is not that Copilot was uniquely careless, nor that prompt injection has suddenly become cyberpunk magic. The lesson is more uncomfortable: enterprise copilots are becoming data-flow infrastructure, and data-flow infrastructure fails when content, instructions, rendering, and network access are allowed to melt into one warm productivity soup. ...

September 20, 2025 · 14 min · Zelina
Cover image

Tool Wars, Protocol Peace: What MCP‑AgentBench Really Measures

A procurement team does not buy an AI agent because it can recite the word “interoperability” with theatrical confidence. It buys the agent because the thing can use tools, collect data, combine results, and stop before it bankrupts the token budget. That is the useful way to read MCP-AgentBench, a new benchmark for evaluating language agents inside the Model Context Protocol ecosystem.1 The paper is not just another leaderboard with a fresh coat of protocol paint. Its more interesting result is harsher: MCP gives agents a common integration layer, but it does not make them competent tool users. Compatibility is plumbing. Competence is orchestration. ...

September 19, 2025 · 14 min · Zelina
Cover image

Agency Check, Please: What a New Benchmark Says About LLMs That Actually Empower Users

A customer asks your AI assistant to choose between two mortgage options. An employee asks whether to quit. A student says, very politely, “Please guide me, but don’t give me the answer.” A lonely user suggests the chatbot feels like a best friend. The easy product answer is: be helpful. The harder answer is: helpful to what? ...

September 14, 2025 · 16 min · Zelina
Cover image

From Blobs to Blocks: Componentizing LLM Output for Real Work

Every office has the same tiny tragedy. Someone asks an AI system for a useful draft. The model produces five decent paragraphs and one mildly deranged sentence that sounds as if it escaped from a conference keynote. The user wants to fix only that sentence. Instead, the interface offers the usual bargain: copy everything into another editor and lose the live connection to the conversation, or ask the model to revise the answer and watch it “helpfully” disturb the parts that were already fine. ...

September 14, 2025 · 16 min · Zelina
Cover image

Branching Out of the Middle: How a ‘Tree of Agents’ Fixes Long-Context Blind Spots

Contracts are not polite. They hide the important clause on page 83, define the crucial exception on page 17, and bury the fatal cross-reference in an appendix nobody wanted to read. Annual reports behave similarly. So do medical SOPs, litigation files, policy manuals, technical logs, and most documents produced by institutions that have discovered both Microsoft Word and committees. ...

September 12, 2025 · 16 min · Zelina
Cover image

HyFedRAG: Caching Privacy into Federated RAG

Hospital search is rarely a search problem in the clean, consumer-internet sense. The useful information is not sitting in one tidy index, wearing a name badge, waiting to be embedded. It is scattered across clinical notes, relational databases, knowledge graphs, departmental systems, hospital networks, and legal boundaries. Naturally, this is where people decide to add a large language model and call it “modernisation.” Brave. ...

September 12, 2025 · 15 min · Zelina