TL;DR for operators
A production voice agent has to decide more than what to say. It has to decide whether a pause means the user finished speaking, whether response pacing should change, which earlier constraints still matter, and how much historical audio is worth sending back to the model.
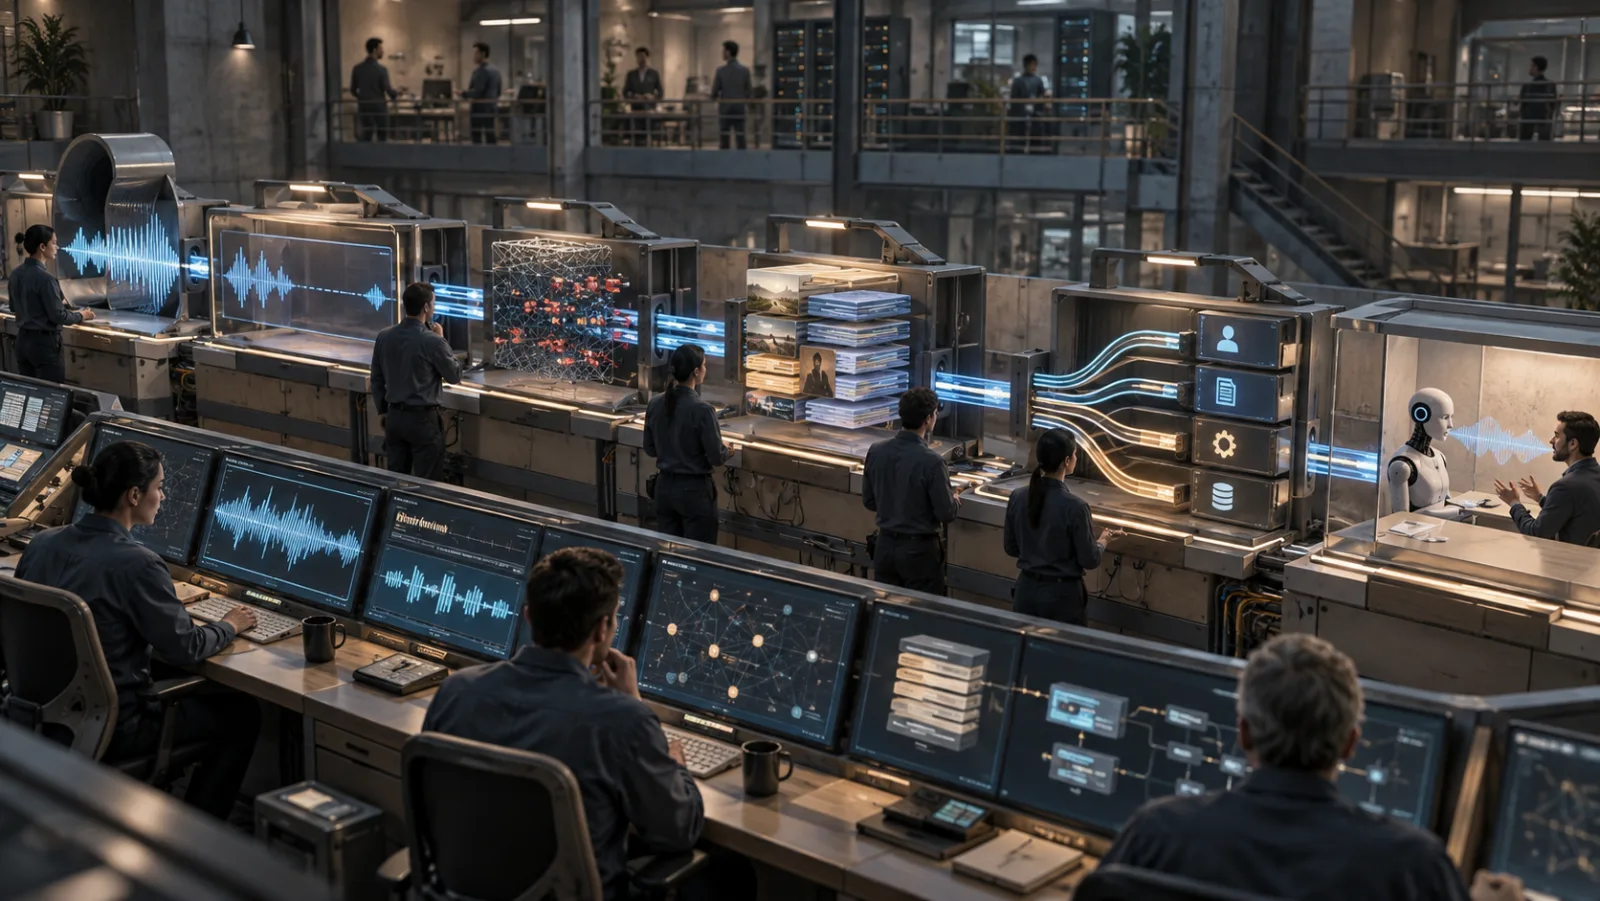
Scalable Context Orchestration for Serving LLMs Over Voice1 treats those decisions as a separate systems layer. Its llmovoice middleware explicitly tracks semantic, speech-delivery, and environmental state; organizes completed interactions into persistent memory structures; and projects only a bounded, relevance-weighted portion of history into the serving model.
The strongest operational evidence is not that the system produces more natural conversation in general. It is narrower and more concrete. Under packet-loss traces, a responsive fixed turn threshold produced a 46.0% false-interruption rate. A highly conservative fixed setting reduced false interruptions to 0% but pushed endpoint latency to 4021.4 ms. Llmovoice reached 0.9% false interruptions at 1830.7 ms. The architecture also reduced long-session model cost substantially, although summary compression sometimes removed answer-critical information and LLM-generated runtime controls added a separate mean decision latency of 790.2 ms when invoked.
For teams building long-running assistants, telephone agents, coaching products, or customer-service voice systems, the decision is therefore architectural: whether context should remain passive conversation history, or become an explicit runtime control plane with its own state, memory, and fidelity budget.
A pause can be network loss rather than a turn boundary
Consider a long voice session. The user speaks quickly for several turns, changes topics, encounters a degraded connection, and later returns to an earlier constraint. The transcript alone does not tell the system everything it needs to know.
A period of silence may mean the user has finished. It may also be an artifact of packet loss. Responding immediately in the second case produces a false interruption; waiting conservatively after every pause avoids that failure but makes every interaction slower.
The paper’s packet-loss experiment makes this tradeoff visible. Fixed-500, a responsive policy, recorded a 46.0% false-interruption rate with 1286.1 ms endpoint latency. Static-Max eliminated false interruptions but increased latency to 4021.4 ms. Llmovoice reduced the false-interruption rate to 0.9% while keeping endpoint latency at 1830.7 ms.
That result changes the framing. Turn detection is not always a parameter-tuning exercise in which one silence threshold can be optimized globally. If network condition, conversational intent, and current voice behavior change during a session, the appropriate response can change with them.
Llmovoice makes voice context an explicit runtime state
Llmovoice is middleware, not a new speech foundation model. It sits between a streaming voice application and the serving LLM and represents three categories of state: semantic context, paralinguistic information, and environmental conditions.
The evaluated paralinguistic signal is speaking rate. The system estimates recent user pace and maps it into the provider’s supported response-speed range. In a controlled RT2 comparison holding query audio, selected context, model, prompt, and voice constant, enabling this orchestration reduced speaking-rate alignment MAE from 38.26 to 18.23, a 52.4% relative reduction.
That metric needs a precise interpretation. It shows that the response rate tracked the user’s speaking rate more closely. It does not establish that users found the conversation more natural, preferable, or emotionally appropriate.
The evaluated environmental signal is packet loss. Here, the system can delay response generation and adapt the voice-activity-detection silence threshold when later speech indicates that an earlier endpoint was premature. Preventing those premature responses reduced network-induced model cost from $0.003344 to $0.000695 per trace relative to Fixed-500, a 79.2% reduction.
The wider architectural contribution is the separation itself: the model reasons over explicit current states, while typed runtime functions constrain how that reasoning affects operational behavior.
VoicePages and VoiceThreads preserve conversational locality
Current state solves only part of the problem. A long conversation also contains older information that may become relevant again after many intervening turns.
Llmovoice stores completed interactions as VoicePages containing audio, transcript, summary, and retrieval metadata. Related pages can belong to VoiceThreads, including non-adjacent interactions that share a topic or task. A page can belong to multiple threads.
This matters because conversational evidence is often distributed. Treating every past turn as an independent retrieval item can recover a locally relevant passage while missing the surrounding thread needed to answer a multi-turn question.
The paper reports that page-level retrieval becomes markedly weaker for multi-page questions: Page-RAG’s hit rate falls from 81.7% to 55.3% on RT2 and from 47.8% to 20.4% on MSP-PODCAST when moving from single-page to multi-page retrieval. The paper attributes llmovoice’s stronger cross-page recovery to the explicit thread organization.
For an operator, the design implication is narrower than “use RAG.” The retrieval unit itself should match the structure of the interaction. In voice applications where goals recur across non-adjacent turns, topic-level memory can preserve relationships that flat turn retrieval discards.
Bounded context is a fidelity-allocation problem
Retrieving the right history does not solve serving cost if every retrieved interaction is replayed as full audio.
Llmovoice therefore gives each historical item several possible representations: audio, transcript, summary, or omission. It reserves part of the model context for output, then uses a relevance-ordered degradation heuristic to lower the fidelity of historical items until the selected history fits the remaining budget.
The cost results are substantial. Average per-turn model cost was $0.005799 on RT2 and $0.005634 on MSP-PODCAST, reported as 4.4× and 24.9× cheaper than the evaluated full-history OpenAI baseline. On the longer MSP-PODCAST workload, llmovoice was also 1.8× cheaper than the paper’s idealized 100%-cached OpenAI condition.
This distinction matters operationally. Caching reduces the cost of processing context already selected. Llmovoice changes which historical information enters the model and at what representation fidelity.
The tradeoff is measurable. The bounded context retained 98.7% of the full-history OpenAI answer-quality level on RT2 but 88.7% on MSP-PODCAST. More importantly, transcript-to-summary compression had a reported 14.6% failure rate under the paper’s definition: cases existed where the transcript retained answer-relevant evidence that the loaded summary did not.
Compression therefore cannot be treated as lossless memory.
The orchestration layer is cheap on one path and expensive on another
The memory path itself contributes relatively little to end-to-end time to first audio. Retrieval, embedding, vector search, projection, and context construction added 78.4 ms on RT2, or 3.8% of TTFA, and 50.9 ms on MSP-PODCAST, or 2.7%.
Runtime control is different. When the serving LLM produced a control function call, the state-to-control path had a mean decision latency of 790.2 ms, a median of 698.8 ms, and a 95th percentile of 1286.6 ms.
For product teams, this creates a concrete design boundary. Dynamic orchestration is most defensible where the state being managed can materially change user experience, inference waste, or session reliability. Using an LLM-mediated decision path for every minor control would carry a latency cost that the paper’s own measurements make difficult to ignore.
What operators can infer—and what remains untested
The paper directly supports several system-level conclusions within its evaluated setup:
| Operational decision | Paper evidence | Boundary |
|---|---|---|
| Adapt turn handling to network state | False interruptions fell from 46.0% to 0.9% versus Fixed-500 | Packet loss is the primary evaluated environmental condition |
| Adapt response pace to user speech | Speaking-rate MAE fell 52.4% | This measures pacing alignment, not subjective naturalness |
| Bound long-session history | 4.4× and 24.9× lower cost than full-history OpenAI on RT2 and MSP-PODCAST | Answer retention fell to 88.7% on the longer MSP workload |
| Compress memory selectively | Audio, transcript, summary, and omission can share one fixed budget | Summary conversion lost answer-critical information in 14.6% of evaluated cases |
| Put an LLM in the control loop | Current states can be jointly resolved into typed runtime actions | Function-call-producing turns incurred 790.2 ms mean control-decision latency |
Cognaptus’s inference is that voice products with long sessions, unreliable connections, recurring goals, or meaningful delivery adaptation have reason to evaluate context orchestration as its own architectural layer rather than relying entirely on longer context windows, caching, fixed VAD settings, or flat retrieval.
The evidence does not yet establish that this architecture transfers unchanged across streaming model providers, every paralinguistic signal, or broad user-experience measures. The main prototype uses the OpenAI Realtime stack; speaking rate and packet loss carry much of the controlled evidence; answer quality relies on GPT-4o judging; and the real-world evaluation consists of three representative unscripted cases rather than a large controlled user study.
Voice systems need to decide what context should do
The central contribution of llmovoice is not simply better memory retrieval. It makes voice context operational.
Some context describes what the user means. Some describes how they are speaking. Some describes what the network is doing. Historical context also varies in both relevance and required fidelity. Treating all of that information as one growing stream leaves runtime decisions implicit and makes long sessions increasingly expensive.
Llmovoice shows that an explicit state-and-control layer can coordinate those signals while keeping model context bounded. Its strongest evidence concerns concrete serving outcomes—turn robustness, pacing alignment, model-input cost, and retrieval behavior—not a general claim that every voice interaction becomes better.
For operators, that is already a meaningful architectural distinction. The next design question is not whether a voice agent has context. It is which parts of that context deserve explicit state, which deserve high-fidelity memory, and which runtime decisions justify the latency of dynamic orchestration.
Cognaptus: Automate the Present, Incubate the Future.
-
Linyi Jiang and Silvery D. Fu and Yifei Zhu (2026). Scalable Context Orchestration for Serving LLMs Over Voice. arXiv:2609.04288. https://arxiv.org/abs/2609.04288 ↩︎