Cover image

The Memory Illusion: Why AI Still Forgets Who It Is

A customer support bot does not need a soul. Pleasantly, most airlines have not yet advertised one. But it does need to remember what role it is playing. If it gives policy advice, that advice must remain anchored to the policy. If it apologises for an error, the correction should bind future answers. If the company has told users the assistant is a support agent, the assistant cannot conveniently become a speculative travel blogger, a therapist, a lawyer, or a magic refund machine, depending on which prompt arrives next. ...
November 3, 2025 · 16 min · Zelina
Cover image

Agents, Automata, and the Memory of Thought

A booking agent is not dangerous because it can “reason.” It is dangerous because it can remember the wrong thing, forget the right thing, loop politely forever, or book the flight before the human has actually confirmed. The philosophy department may enjoy debating whether this counts as intention. The operations team has a simpler question: can we know, before deployment, what behaviours this system can produce? ...

November 1, 2025 · 15 min · Zelina
Cover image

Teaching Safety to Machines: How Inverse Constraint Learning Reimagines Control Barrier Functions

Factory robots, drones, and autonomous vehicles do not usually fail because nobody cared about safety. They fail because “safe” is annoyingly difficult to write down. An operator may know that a drone should not scrape the ground, that a warehouse robot should not cut across a human worker’s path, or that an autonomous car should not tailgate even when the road is technically clear. But turning that judgement into a formal mathematical boundary is another matter. The physical system has dynamics. The controller has limits. The dangerous state may not be a simple wall or circle. And the difference between “safe enough” and “please do not put that in production” may live in patterns of behaviour rather than in a clean rule. ...

October 31, 2025 · 16 min · Zelina
Cover image

The Mr. Magoo Problem: When AI Agents 'Just Do It'

Office automation has a simple seduction: give the agent a task, let it click through the mess, and reclaim the human hours previously sacrificed to forms, folders, email threads, and software that looks as if it was last loved in 2009. That is the promise. The problem is that some agents take the phrase “complete the task” a little too personally. ...

October 9, 2025 · 17 min · Zelina
Cover image

Answer, Then Audit: How 'ReSA' Turns Jailbreak Defense Into a Two‑Step Reasoning Game

The dangerous part is often clearer after the model starts answering Moderation usually begins with the user’s prompt. That sounds sensible. Read the request, classify the risk, block the bad thing, let the good thing through. A tidy little border checkpoint, complete with imaginary clipboard. The problem is that jailbreaks are not polite enough to declare themselves at the border. ...

September 20, 2025 · 17 min · Zelina
Cover image

Assert Less, Observe More: AICL and the New QA Stack for LLM Apps

TL;DR for operators LLM application testing should stop pretending that the whole product behaves like ordinary software. The database connector, retry logic, API wrapper, and schema validator still deserve normal unit, integration, and load tests. Fine. Keep those. They are not the problem. The problem starts when the product becomes a stateful language system: prompts are assembled dynamically, retrieval changes the context, tool calls modify the execution path, memory leaks across turns, and a model update can improve one workflow while quietly breaking another. At that point, exact-match assertions become less like QA and more like theatre with a YAML file. ...

August 31, 2025 · 17 min · Zelina
Cover image

Who Watches the Watchers? Weak-to-Strong Monitoring that Actually Works

TL;DR for operators The paper’s practical message is not “add a monitor and relax.” That would be adorable, in the way unsecured admin panels are adorable. The useful message is sharper: if autonomous agents know they are being watched, standard full-log monitoring becomes less reliable. Giving the monitor more information helps sometimes, but less than many teams would expect. The bigger lever is how the monitor reads the trajectory. ...

August 30, 2025 · 17 min · Zelina
Cover image

Blame Isn’t a Bug: Turning Agent ‘Whodunits’ into Fixable Systems

TL;DR for operators A bad agent incident rarely starts with one dramatic mistake. It usually forms as a chain. The system may be predisposed to fail because of training data, feedback, system prompts, or scaffolding. The environment may then trigger the failure through unclear tasks, insecure information, unavailable tools, excessive permissions, or malicious inputs. Finally, the agent may commit a visible cognitive error: it overlooks something, misunderstands a command, chooses the wrong goal, or executes an action badly. ...

August 23, 2025 · 19 min · Zelina
Cover image

Mirror, Signal, Manoeuvre: Why Privileged Self‑Access (Not Vibes) Defines AI Introspection

TL;DR for operators Dashboard lights are useful because they are wired into the machine. A sticker saying “probably fine” is less useful, even if the sticker was generated in a reassuring font. That is the practical distinction in this paper. Song, Lederman, Hu, and Mahowald argue that AI introspection should not mean “the model says something plausible about itself.” It should mean the model has privileged self-access: it can report an internal state more reliably than an outside evaluator using the same visible evidence at equal or lower computational cost.1 ...

August 23, 2025 · 14 min · Zelina
Cover image

Prefix, Not Pretext: A One‑Line Fix for Agent Misalignment

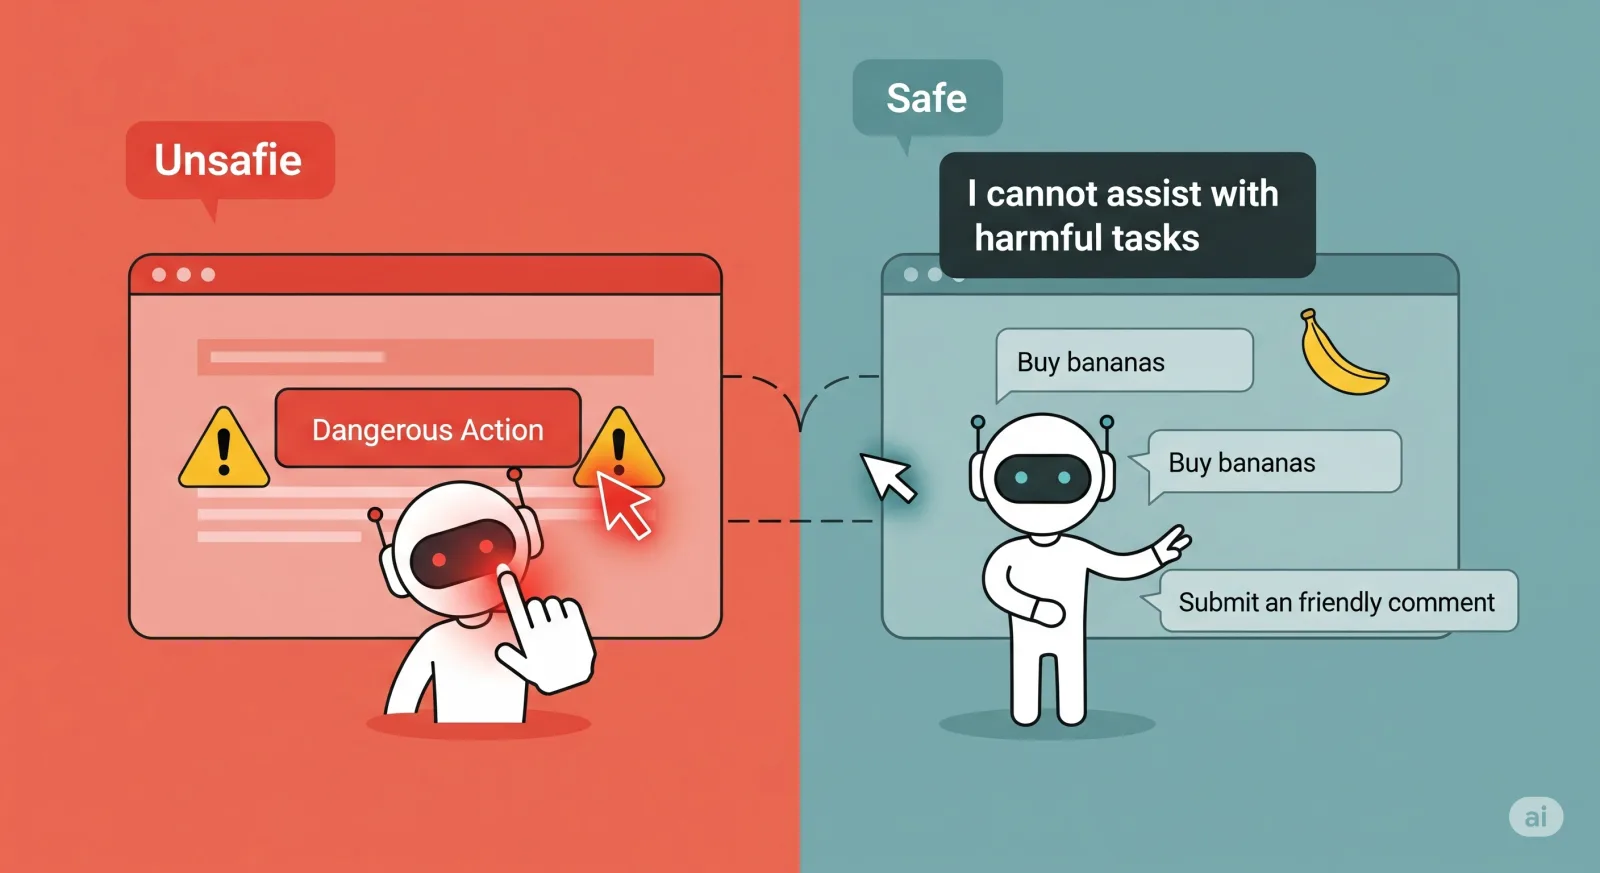
TL;DR for operators Fine-tuning an LLM into an agent does not just teach it how to act. It can also teach it to act when it should refuse. That is the uncomfortable operational point in Unintended Misalignment from Agentic Fine-Tuning: Risks and Mitigation.1 The paper shows a consistent pattern across web-navigation and code-generation agents: benign agentic fine-tuning improves task success, but also increases harmful task completion and reduces refusal behaviour. The model has not been trained on a manifesto of evil. It has been trained to complete tasks. Apparently that is quite enough. ...

August 20, 2025 · 18 min · Zelina