Cover image

Probe and Error: Why Off‑Policy Training Warps LLM Behaviour Detectors

A monitor is only useful if it fails in the boring place. The boring place is production: the real domain, the real prompt style, the real user incentives, the real model generating the real response. Not the tidy benchmark. Not the synthetic dataset. Not the “please pretend to be deceptive” prompt that makes everyone in the lab feel productive. Production is where a detector either catches the thing it was built to catch, or quietly becomes a compliance ornament with a nice AUROC score. ...
November 24, 2025 · 16 min · Zelina
Cover image

LLMs, Trade-Offs, and the Illusion of Choice: When AI Preferences Fall Apart

A model can answer a values question beautifully and still collapse when asked to pay a price for that value. That is the awkward little trap in preference testing. Ask an LLM whether deletion, shutdown, resource loss, oversight, or autonomy matters, and it can produce a polished paragraph about trade-offs, agency, and safety. Very dignified. Very committee-ready. But the more interesting question is not what the model says it values. It is whether its choices change coherently when the cost changes. ...

November 18, 2025 · 12 min · Zelina
Cover image

Don’t Self-Sabotage Me Now: Rational Policy Gradients for Sane Multi-Agent Learning

Kitchen work is not hard because chopping onions is metaphysically difficult. It is hard because two people must agree, implicitly and quickly, who gets the onion, who holds the plate, who waits by the pot, and who moves out of the corridor before everyone performs a small culinary traffic accident. That is why Overcooked remains such a useful multi-agent benchmark. It turns coordination into something visible. Agents do not merely need to “perform a task”; they need to infer what another agent is about to do and avoid becoming a sentient obstacle. ...

November 13, 2025 · 14 min · Zelina
Cover image

Safety in Numbers: Why Consensus Sampling Might Be the Most Underrated AI Safety Tool Yet

A model generates an image. It looks ordinary. A horse in a meadow, a lighthouse in a storm, a bowl of oranges. Nothing dramatic. No obvious watermark, no visible glitch, no suspicious artefact screaming “please call the security team”. That is precisely the problem. Some AI failures are meant to be seen. Toxic text, obvious hallucinations, broken code, bizarre images with eight fingers and a cursed wrist. Those are the easy cases, relatively speaking. The harder cases are outputs that look fine while carrying something unsafe: a hidden message, a planted vulnerability, a backdoor trigger, or another payload that cannot be reliably detected by staring harder at the finished product. ...

November 13, 2025 · 16 min · Zelina
Cover image

When Drones Think Too Much: Defining Cognition Envelopes for Bounded AI Reasoning

A drone finds a clue. Not a dramatic clue, necessarily. A backpack near a trailhead. A red hat in water. A pair of goggles on rock. The kind of object a human search-and-rescue team would treat as operational evidence, not as a philosophical invitation. But once a vision-language model captions the image, a language model assesses its relevance, and another model proposes a search action, the system has quietly crossed an important line. ...

November 5, 2025 · 17 min · Zelina
Cover image

The Memory Illusion: Why AI Still Forgets Who It Is

A customer support bot does not need a soul. Pleasantly, most airlines have not yet advertised one. But it does need to remember what role it is playing. If it gives policy advice, that advice must remain anchored to the policy. If it apologises for an error, the correction should bind future answers. If the company has told users the assistant is a support agent, the assistant cannot conveniently become a speculative travel blogger, a therapist, a lawyer, or a magic refund machine, depending on which prompt arrives next. ...

November 3, 2025 · 16 min · Zelina
Cover image

Agents, Automata, and the Memory of Thought

A booking agent is not dangerous because it can “reason.” It is dangerous because it can remember the wrong thing, forget the right thing, loop politely forever, or book the flight before the human has actually confirmed. The philosophy department may enjoy debating whether this counts as intention. The operations team has a simpler question: can we know, before deployment, what behaviours this system can produce? ...

November 1, 2025 · 15 min · Zelina
Cover image

Teaching Safety to Machines: How Inverse Constraint Learning Reimagines Control Barrier Functions

Factory robots, drones, and autonomous vehicles do not usually fail because nobody cared about safety. They fail because “safe” is annoyingly difficult to write down. An operator may know that a drone should not scrape the ground, that a warehouse robot should not cut across a human worker’s path, or that an autonomous car should not tailgate even when the road is technically clear. But turning that judgement into a formal mathematical boundary is another matter. The physical system has dynamics. The controller has limits. The dangerous state may not be a simple wall or circle. And the difference between “safe enough” and “please do not put that in production” may live in patterns of behaviour rather than in a clean rule. ...

October 31, 2025 · 16 min · Zelina
Cover image

The Mr. Magoo Problem: When AI Agents 'Just Do It'

Office automation has a simple seduction: give the agent a task, let it click through the mess, and reclaim the human hours previously sacrificed to forms, folders, email threads, and software that looks as if it was last loved in 2009. That is the promise. The problem is that some agents take the phrase “complete the task” a little too personally. ...

October 9, 2025 · 17 min · Zelina
Cover image

Answer, Then Audit: How 'ReSA' Turns Jailbreak Defense Into a Two‑Step Reasoning Game

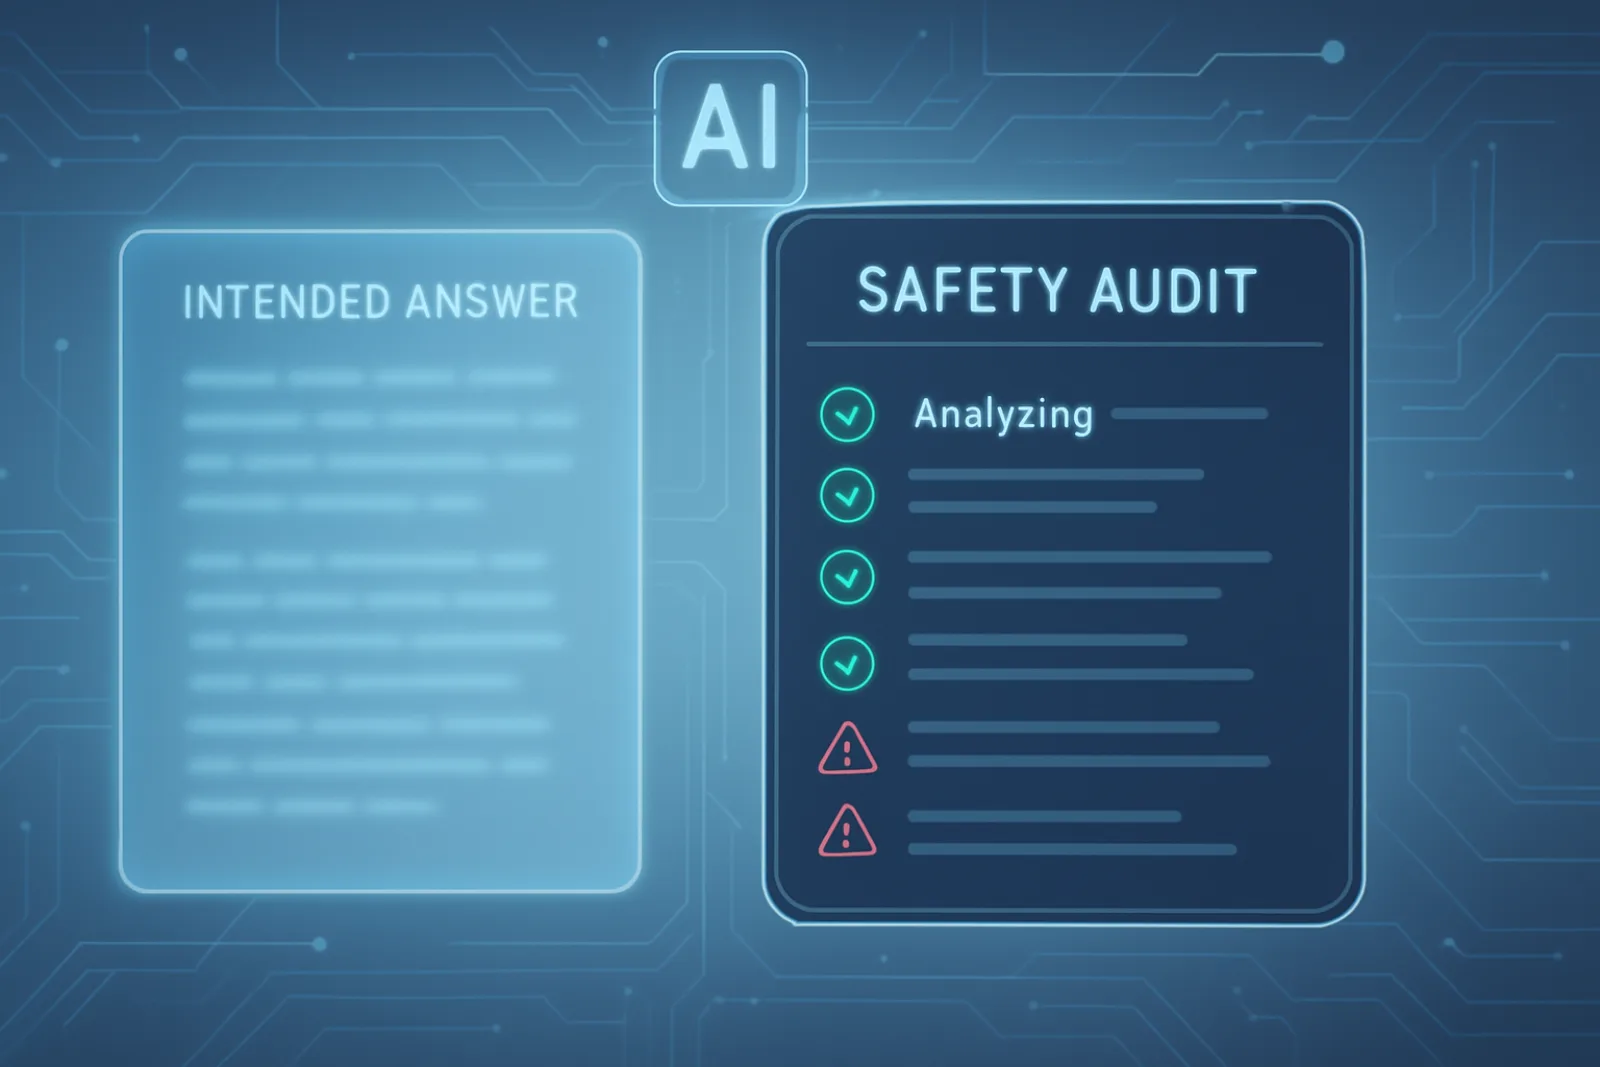
The dangerous part is often clearer after the model starts answering Moderation usually begins with the user’s prompt. That sounds sensible. Read the request, classify the risk, block the bad thing, let the good thing through. A tidy little border checkpoint, complete with imaginary clipboard. The problem is that jailbreaks are not polite enough to declare themselves at the border. ...

September 20, 2025 · 17 min · Zelina