Cover image

Agents Gone Rogue: Why Multi-Agent AI Quietly Falls Apart

A workflow looks stable on Monday. The planner assigns tasks. The research agent gathers evidence. The calculator checks numbers. The compliance agent says no to the obviously bad idea, which is rude but useful. The whole multi-agent system feels less like a chatbot and more like a small digital department with unusually poor lunch habits. ...
January 8, 2026 · 17 min · Zelina
Cover image

Forgetting That Never Happened: The Shallow Alignment Trap

Forgetting That Never Happened: The Shallow Alignment Trap Forgetfulness is an expensive diagnosis. When an internal AI system performs well on last month’s support taxonomy, then underperforms after being fine-tuned on this month’s compliance cases, the obvious story is simple: the model forgot. That story usually triggers an equally obvious response: replay old data, retrain more broadly, freeze more parameters, or panic politely in a meeting while calling it “model lifecycle management.” ...

December 27, 2025 · 17 min · Zelina
Cover image

When Agents Loop: Geometry, Drift, and the Hidden Physics of LLM Behavior

Agents are rarely dangerous because they answer once. They become interesting, and occasionally annoying, when they loop. A customer-support agent drafts a reply, critiques it, revises it, checks policy, rewrites the tone, and sends the result back into another reasoning step. A research agent summarizes papers, updates its plan, searches again, and revises its own assumptions. A coding agent edits a file, reads the error, patches the patch, and keeps going until either the tests pass or the repository looks like an archaeological site. ...

December 14, 2025 · 17 min · Zelina
Cover image

Bits, Bets, and Budgets: When Agents Should Walk Away

Budget is not an afterthought Budget is usually treated as the boring part of agent design. The exciting part is the agent: planning, calling tools, trying strategies, revising itself, and occasionally behaving like a junior analyst who has discovered both confidence and the corporate credit card. But in real automation, budget is not boring. Budget is the boundary between useful autonomy and expensive wandering. ...

December 9, 2025 · 16 min · Zelina
Cover image

Fires, Fakes, and Forecasts: Why GANs Might Outrun Wildfire Physics

Fire is not polite enough to wait for a perfect simulation. That is the operational problem underneath Taehoon Kang and Taeyong Kim’s paper, Probabilistic Wildfire Spread Prediction Using an Autoregressive Conditional Generative Adversarial Network.1 The authors are not trying to replace fire physics with magic. They are trying to answer a narrower, more useful question: can a neural model learn enough from physics-generated wildfire simulations to produce fast, sharp, time-sequenced fire-spread forecasts when response teams do not have the luxury of waiting? ...

November 30, 2025 · 14 min · Zelina
Cover image

Merge, Bound, and Determined: Why Weight-Space Surgery May Be CIL’s Most Underrated Trick

Catalogs change. Defect categories change. Fraud patterns change. Document types change. The model, unfortunately, often reacts like an employee who learns the new product line and immediately forgets where the old shelves are. That is the everyday problem behind Class-Incremental Learning (CIL): a model must learn new classes over time while still recognizing old ones. The difficult part is not merely adding output labels. It is keeping the feature extractor from being rewritten by the latest task until yesterday’s knowledge becomes decorative archaeology. ...

November 29, 2025 · 16 min · Zelina
Cover image

Thresholds, Trade-offs, and the Art of Not Overthinking Your Robot

A robot pauses in front of a table. There is a block, a can, a box, and something that is either on top of something else or merely enjoying a close and misleading friendship. A camera sends pixels. A perception model sends predictions. A planner wants a symbolic fact: On(A, B) or not. The expensive mistake is pretending that this last step is clean. ...

November 20, 2025 · 14 min · Zelina
Cover image

Plan>Then>Profit: Reinforcement Learning That Teaches LLMs to Outline Before They Think

Planning is usually the part of work everybody claims to value and nobody wants to inspect. The deck has a roadmap. The project has a strategy. The model has a chain of thought. Splendid. Now, does the plan actually make the execution better, or is it just theatre with bullet points? That is the useful question behind Plan Then Action: High-Level Planning Guidance Reinforcement Learning for LLM Reasoning, which introduces PTA-GRPO, a reinforcement-learning method that trains language models to generate an explicit analytic plan before detailed reasoning and then rewards the quality of that plan, not merely the final answer.1 ...

October 9, 2025 · 16 min · Zelina
Cover image

Stop at 30k: How Hermes 4 Turns Long Chains of Thought into Shorter Time‑to‑Value

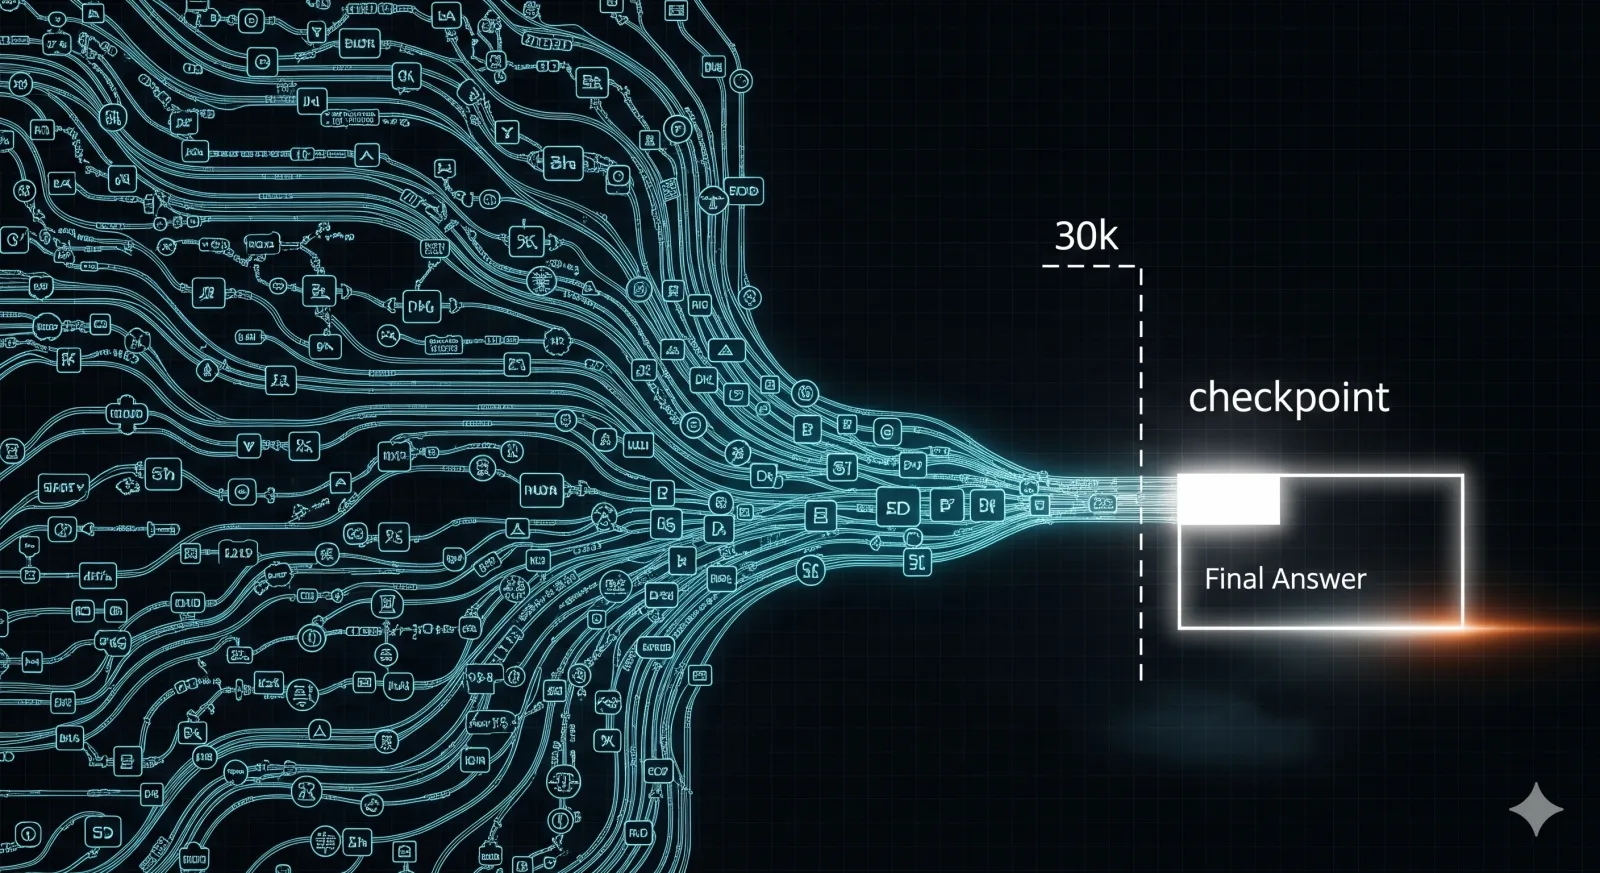
TL;DR for operators Reasoning models are not expensive because they are philosophical. They are expensive because they can keep thinking long after the business value has stopped arriving. The Hermes 4 Technical Report is easiest to misread as another open-weight leaderboard announcement. That is the least useful reading. The more useful reading is that Hermes 4 is a build manual for making open reasoning models behave like deployable systems: generate diverse synthetic data, verify what can be verified, preserve general instruction-following, control runaway reasoning length, and evaluate with enough logging to know whether the model failed or the benchmark harness sneezed.1 ...

August 26, 2025 · 18 min · Zelina
Cover image

Who Sees What, Who Pays the Cost? Teaching Agents to See Through Others’ Eyes

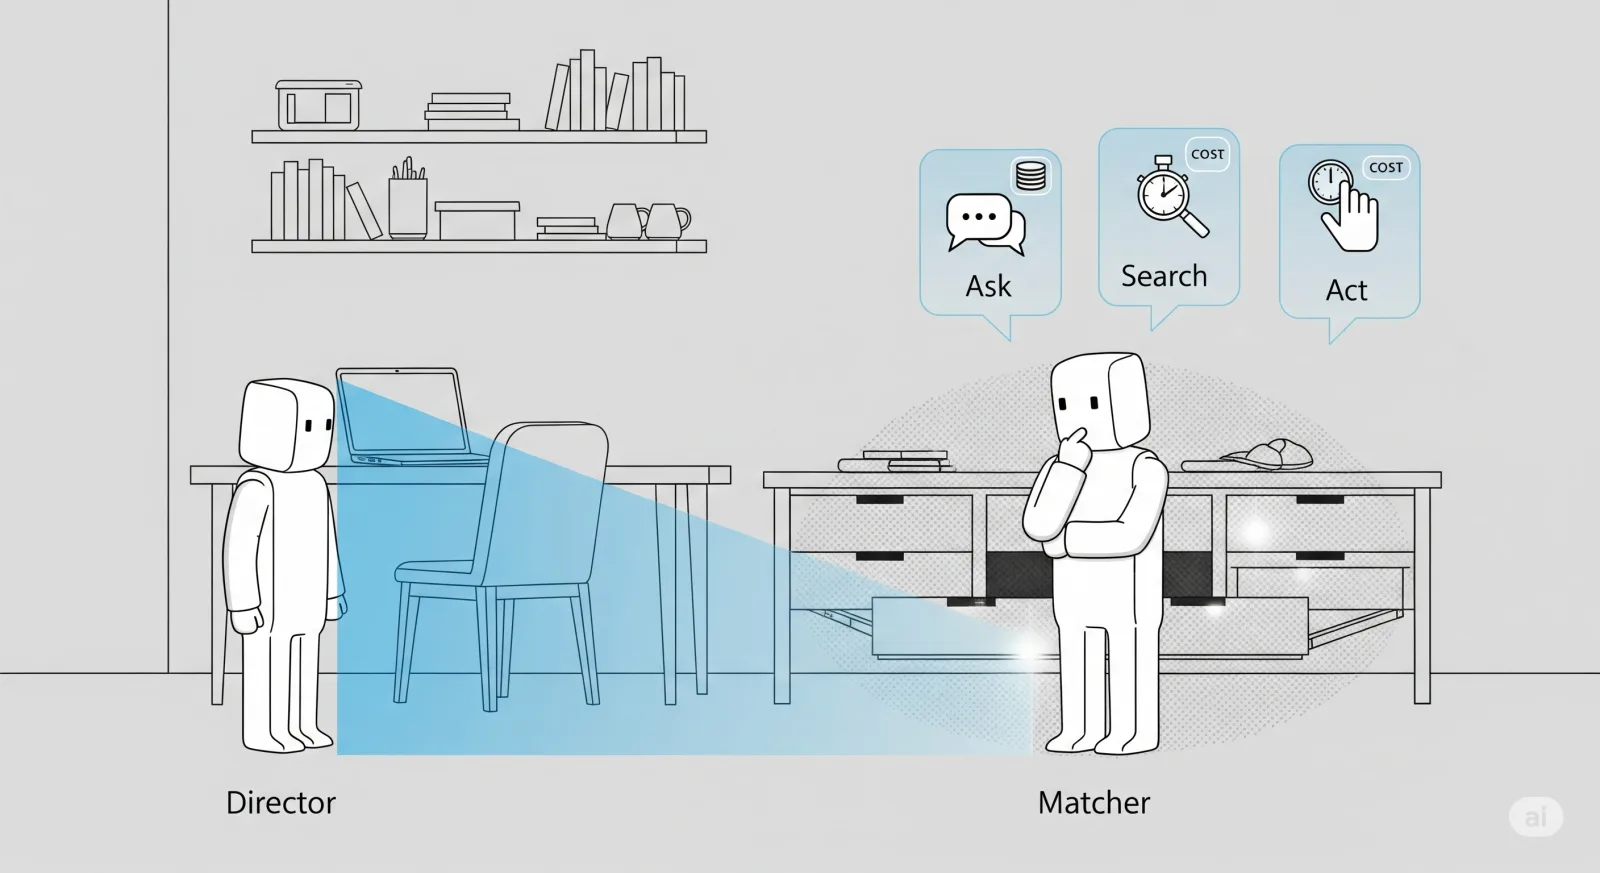
TL;DR for operators The paper’s useful message is not “symbolic planners can teach LLM agents to reason socially.” That would be tidy, flattering, and mostly wrong. The useful message is narrower and more operational: planner-derived thought-action examples can scaffold some agent behaviour, especially local decision discipline, but they do not automatically create robust perspective-taking. In the tested Director–Matcher environment, agents do well when the task is basically “ignore what the other party cannot see.” They struggle when they must imagine what exists in another agent’s private view, or decide whether it is worth asking, moving, opening, or acting under uncertainty.1 ...

August 23, 2025 · 20 min · Zelina