The Atomic Price of Saving Memory
Why a theoretically memory-optimal attention kernel initially ran slower on GPUs, and how hardware profiling recovered its performance advantage.
Why a theoretically memory-optimal attention kernel initially ran slower on GPUs, and how hardware profiling recovered its performance advantage.
A hospital multi-agent simulation finds that coordinating patient routing matters more for congestion reduction than accelerating individual departments, but clinical deployment remains unproven.
A benchmark of encrypted LLM traffic shows how packet patterns can expose model identities, prompt categories, and multi-agent workflows without revealing message contents.
ReCAST shows how image-model training can redistribute reward influence across denoising steps without changing the importance assigned to each objective.
A study of 1,056 businesses shows how website accessibility relates to AI-agent recommendations, factual completeness, and retrieval costs beyond search visibility.
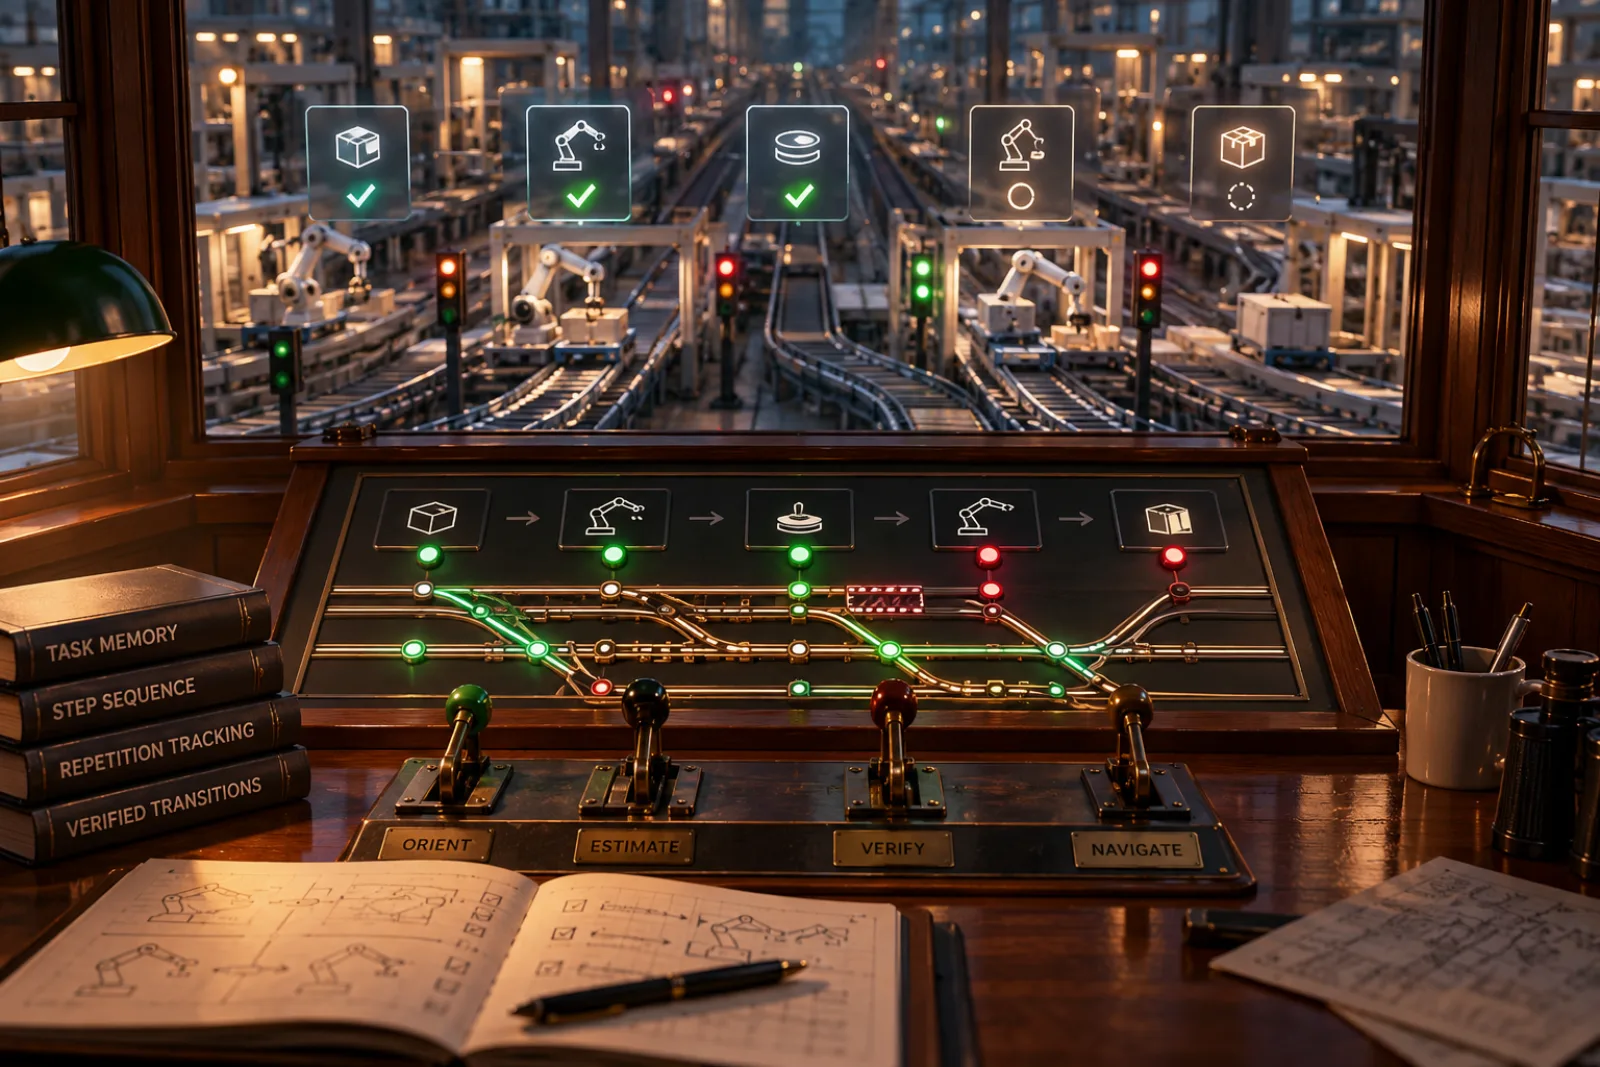
ProgressCompass shows how identifying and verifying task context can improve robotic progress estimation without retraining the underlying reward model.
CHARM shows how structured task memory, synthetic data, and inference choices jointly shape the performance and true footprint of recurrent reasoning systems.
A CARLA driving study shows why verified demonstrations, accurate action predictions, and autonomous-driving reliability require separate evidence.
AlphaDiverse shows how a quantitative research agent can improve prediction while narrowing its research, and how diversity-aware reinforcement learning can address that tradeoff.
Voice-Light shows how a full-duplex voice agent can remain responsive through reversible actions and speculative generation, even when learned turn detection underperforms a simple timing baseline.