The Same Graph Topology, Three Different Results
Graph topology improves classification when added as information, but using it to constrain training or select nodes produces less consistent benefits.
Graph topology improves classification when added as information, but using it to constrain training or select nodes produces less consistent benefits.
ACLArena shows how sequential agent training can degrade earlier capabilities, and why isolated low-rank experts may preserve them better than shared-model consolidation.
Why better LLM confidence prediction does not necessarily mean better error awareness, and what organizations should validate before relying on confidence scores.
PeerPen shows why preserving human intent and control matters when AI helps people write emotionally sensitive messages.
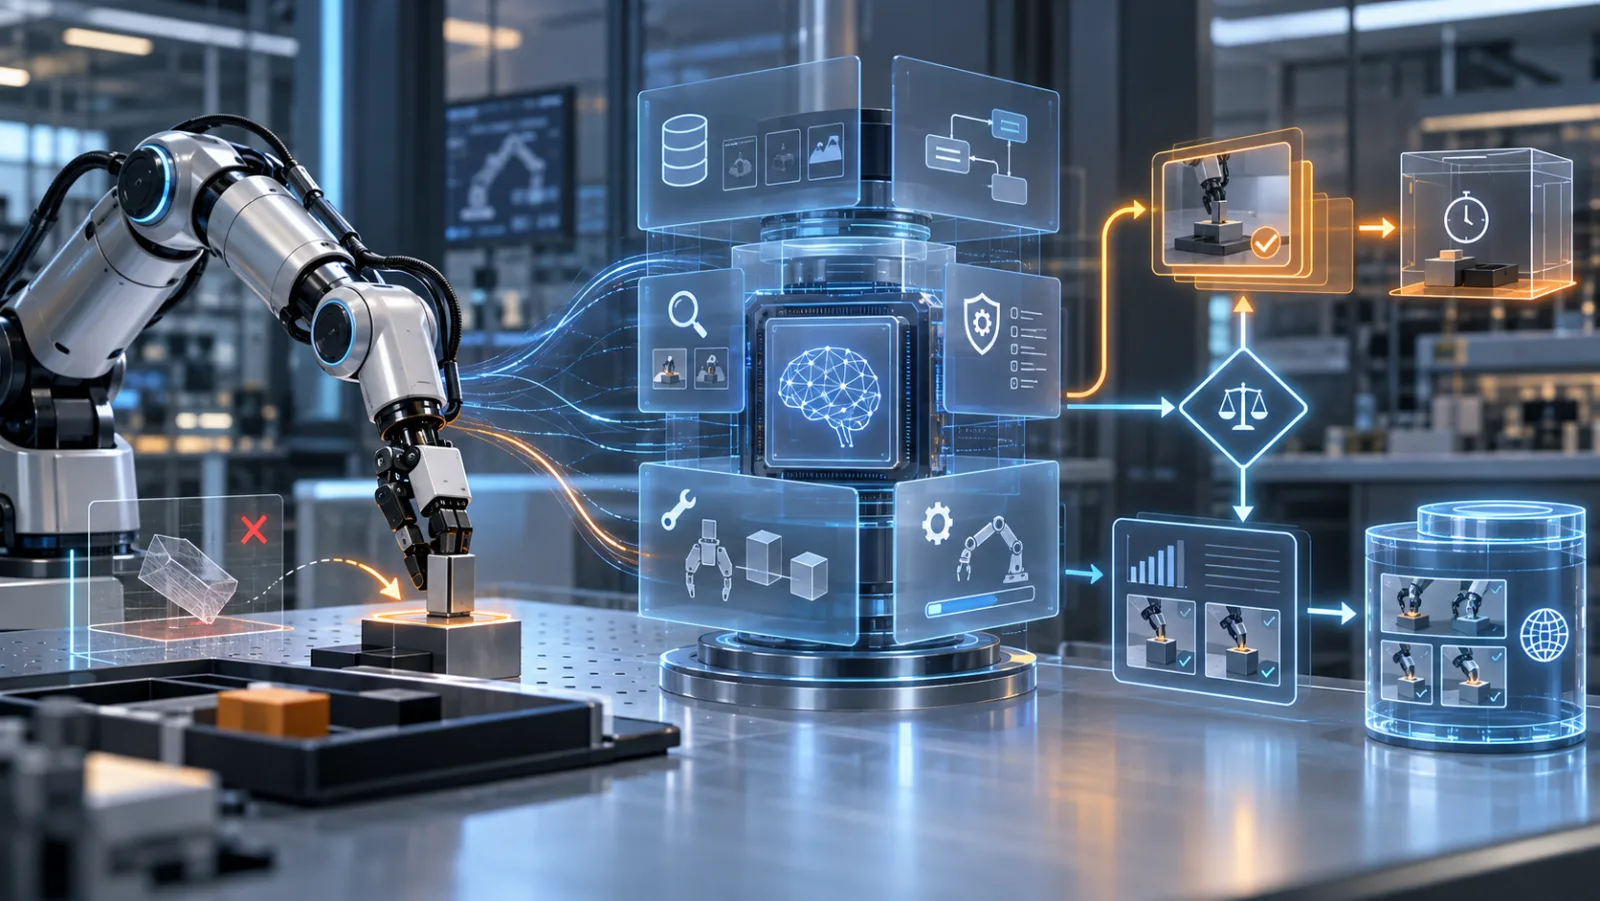
RoboFoundry shows how robotic agents can improve without retraining their foundation models, while raising a critical question about which repairs deserve persistent reuse.
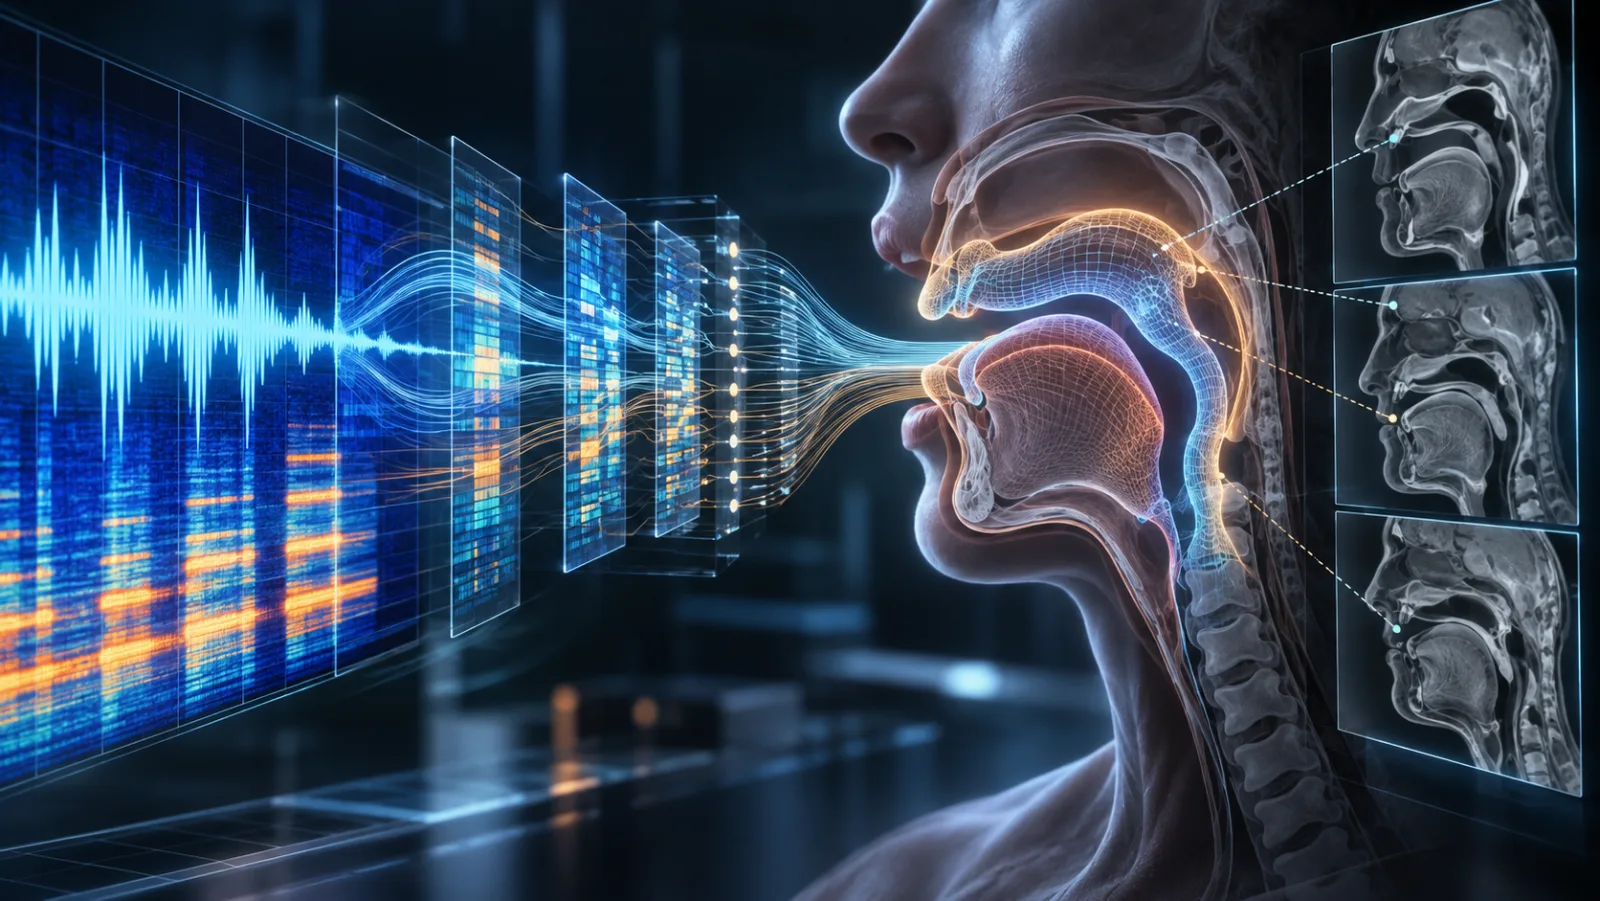
A fast differentiable acoustic simulator reconstructs speech and plausible vocal tract geometry without paired anatomical measurements, but acoustic fidelity does not establish anatomical correctness.
Why identical prompts can produce different greedy-decoded responses across numerical precisions, and when selective FP32 correction improves reproducibility.
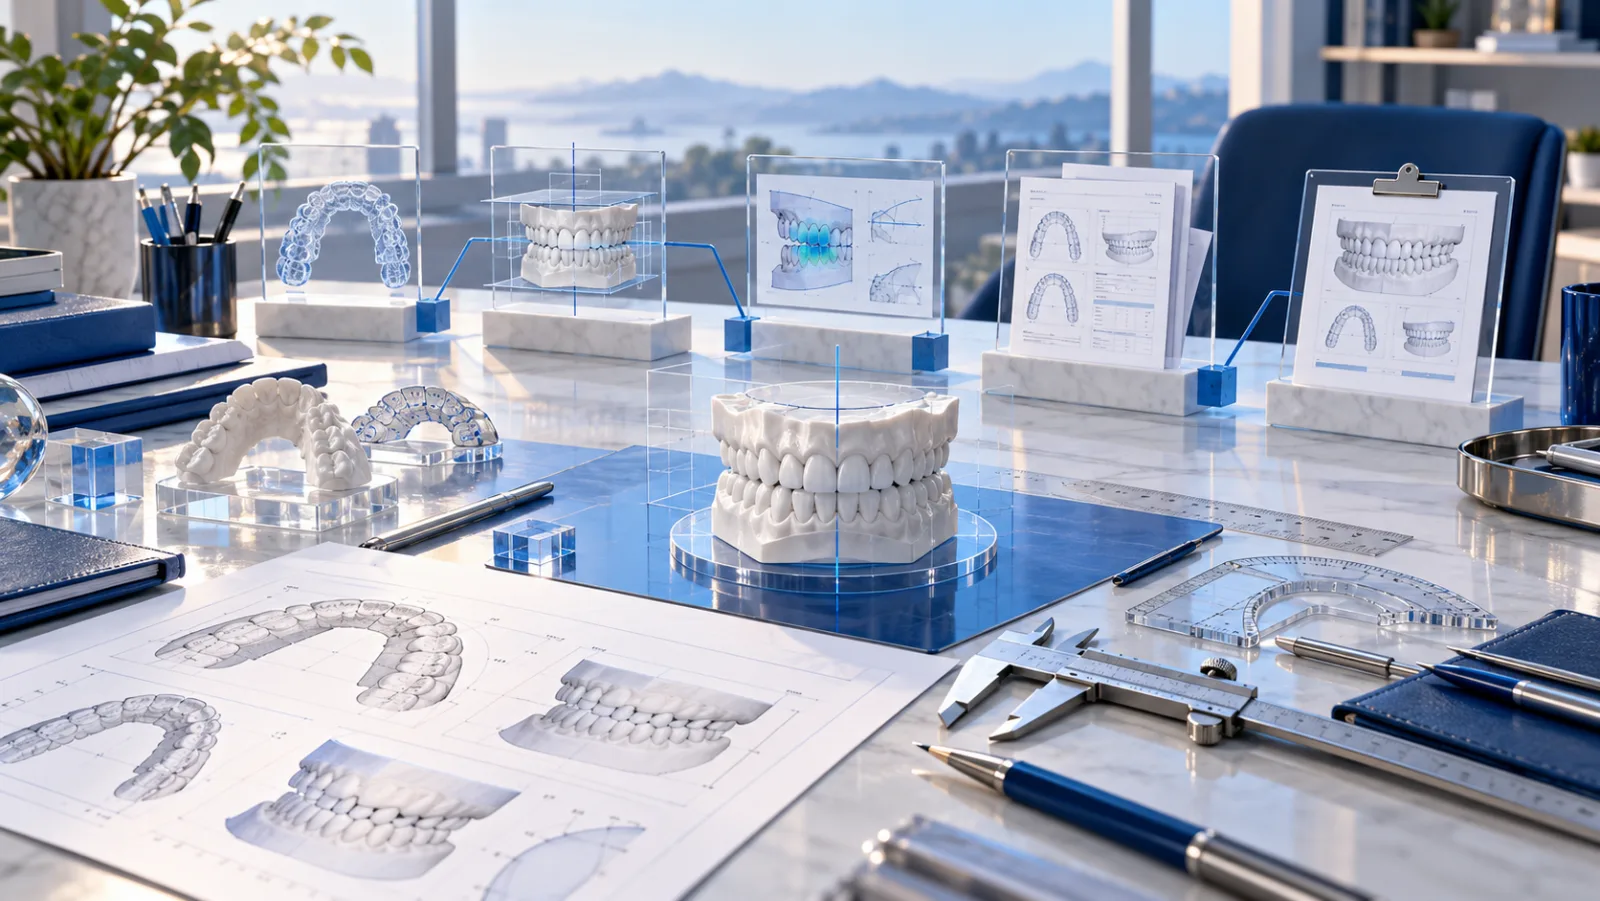
How a geometry-first orthodontic reporting system allocates decisions between measurement, machine learning, and deterministic language while exposing the limits of clinical text metrics.
Why hierarchical AI agents can lose information at a fixed workload yet improve persistent-context integrity and cost efficiency under specific conditions.
Carryover Drafting reuses rejected speculative-decoding states to improve inference speed, but its production value depends on whether additional acceptance offsets recycling and training costs.