TL;DR for operators
A robot asked to identify an unfamiliar object, pick it up without damage, and place it accurately must do more than understand the instruction. It must translate that instruction into movements, adapt to changing sensory feedback, and avoid unsafe physical outcomes.
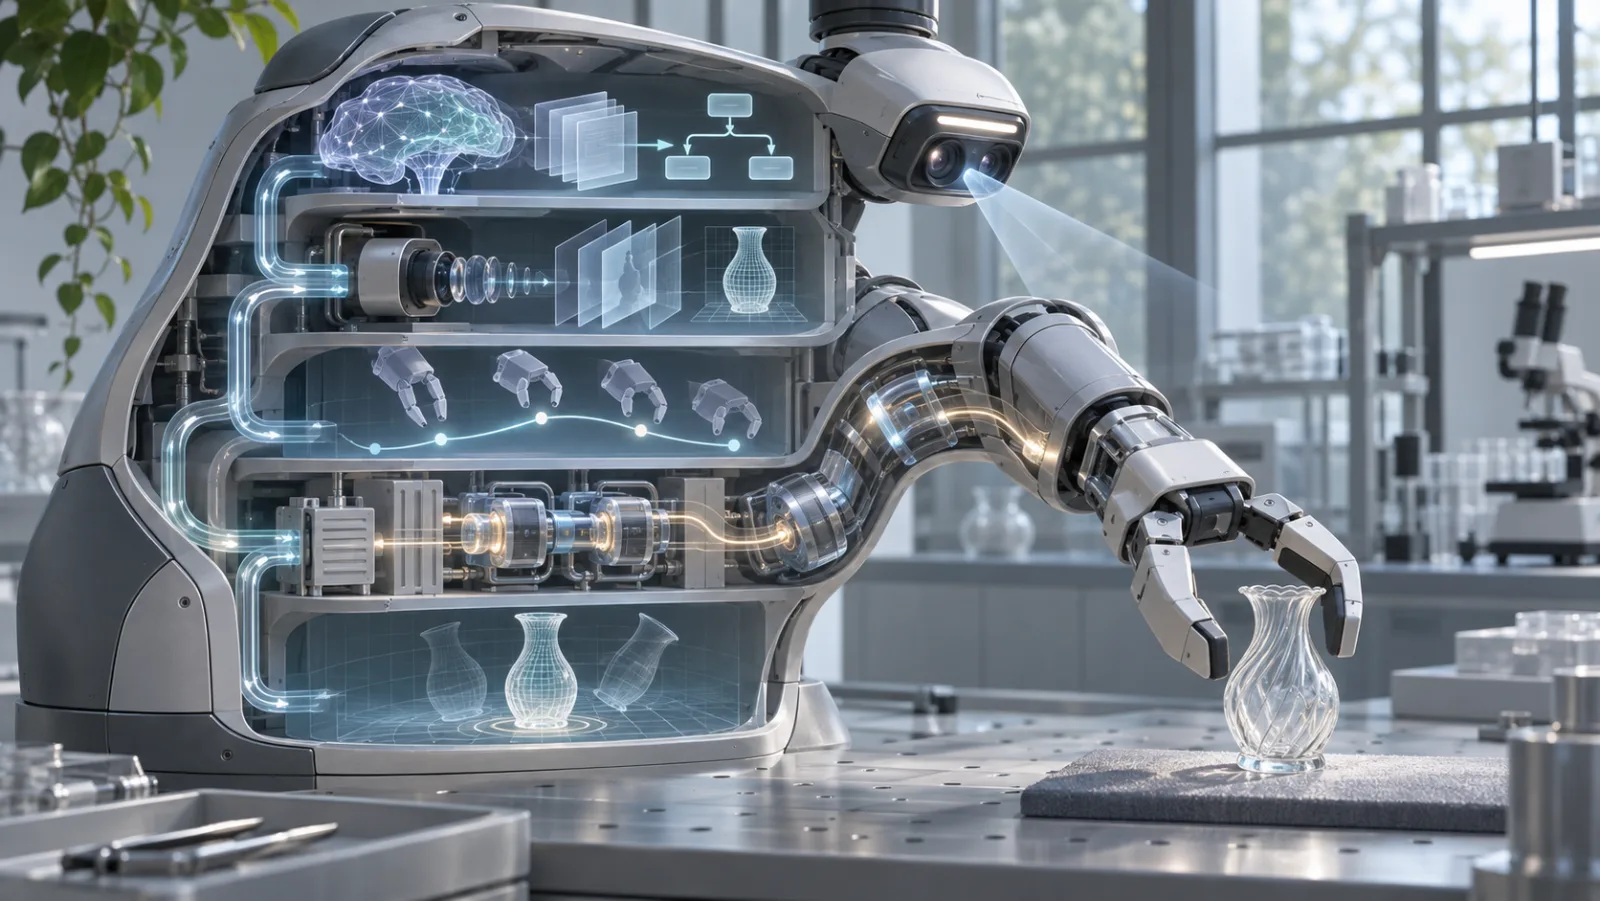
A comprehensive review by Gaba and colleagues organizes generative physical AI into five complementary model families, each emphasizing a different capability.1 The resulting taxonomy helps explain why improving a general-purpose foundation model does not automatically solve motion control, environmental prediction, or physical safety.
For manufacturers, warehouse operators, and robotics developers, this changes how candidate systems should be evaluated. Model selection should begin with the physical task and its constraints, then examine whether the proposed architecture delivers the necessary capabilities within available hardware, timing, and safety limits.
The review supplies a framework for making those distinctions. It does not experimentally establish which architecture produces the best operational performance or return on investment.
One robotic instruction contains several different problems
Consider a warehouse robot instructed to move a fragile, unfamiliar package into a designated container.
The robot must recognize the package, interpret the instruction, select a feasible grasp, control its movement, and respond if the object slips or another object enters its path. Understanding the requested destination does not specify the necessary contact forces or a safe movement trajectory.
These requirements involve different representations, training data, computational demands, and failure modes.
Section III of the review makes that distinction explicit. Instead of treating generative physical AI as one increasingly capable model architecture, the authors classify systems according to their primary functions.
The classification is particularly relevant when evaluating demonstrations. A robot may understand instructions that were absent from its training examples, yet still struggle with unfamiliar object geometry, contact dynamics, or precise manipulation.
Success at semantic interpretation and success at physical execution therefore need separate evidence.
Five model families address different parts of the task
The review identifies five families, compared qualitatively in its Table III.
| Model family | Primary function | Representative systems |
|---|---|---|
| Robot Foundation Models (RFMs) | Learn transferable capabilities for planning and generalization across tasks or embodiments | PaLM-E, Gato |
| Vision-Language-Action models (VLAs) | Convert visual observations, language instructions, and robot-state information into executable actions | RT-1, RT-2, OpenVLA |
| Large Behavior Models (LBMs) | Generate complex learned behaviors, including whole-body and human-like interactions | Meta Motivo |
| Diffusion Policy Models (DPMs) | Produce coherent action trajectories through iterative generative refinement | Diffusion Policy |
| World Foundation Models (WFMs) | Predict environmental changes and generate simulated experience for training or planning | NVIDIA Cosmos |
Source: Section III and Table III. These are functional categories, not mutually exclusive architectures or performance rankings.
The differences are substantial.
RFMs emphasize generalization: transferring learned competencies between tasks, environments, or robotic embodiments. VLAs address a more specific interface problem, translating what a robot perceives and is instructed to do into actions.
LBMs concentrate on learned behavior generation. The review describes Meta Motivo as an example involving reinforcement learning and multiple interacting networks for behavior and control.
DPMs address the movement-generation problem. Rather than producing only a high-level command, they iteratively denoise candidate action sequences conditioned on observations. This can represent alternative plausible movements and generate temporally structured trajectories.
WFMs focus on what might happen next. Conditioned on current environmental representations and candidate actions, they predict possible future states that can inform planning, simulation, or training.
These capabilities may overlap within an integrated system. The taxonomy describes architectural responsibilities, not five products from which an organization must select exactly one.
Why combining models can help, but does not finish the job
Suppose a VLA interprets an instruction and identifies an appropriate action. A specialized diffusion controller could generate the corresponding movement sequence. A world model could predict the consequences of alternative actions before execution.
That is the architectural rationale behind the hybrid systems discussed in Sections III-D through III-F.
The review formalizes world-model prediction as a mapping from a current environmental representation and a candidate action to a predicted next representation. Its finite-horizon extension generates hypothetical future trajectories over multiple actions.
Such predictions can support planning, but they are not guaranteed representations of physical reality. Prediction errors may accumulate over longer horizons, making frequent observation and replanning relevant.
Integration also introduces a timing problem. Large multimodal backbones and iterative diffusion inference can demand substantial computation, while the physical system may require rapid responses to changing conditions.
An architecture that produces an excellent action sequence too late for the robot’s control requirements remains operationally inadequate.
The review consequently treats general-purpose reasoning, specialized action generation, embodiment-specific control, and closed-loop feedback as complementary system components.
It identifies hybrid integration as an emerging direction, not an experimentally established winner over every alternative.
Reported performance gains do not establish an architecture ranking
The survey cites notable results from earlier research.
RT-2 reportedly achieved 62% success on unseen tasks, compared with 32% for RT-1, under the cited evaluation conditions. This illustrates the potential contribution of transferable semantic knowledge to robotic action.
The original Diffusion Policy research reported an average success-rate improvement of 47% across 12 robotic tasks in four benchmark suites. That is a reported relative improvement, not an assertion of a 47-percentage-point gain.
Both numbers are results from prior work. The review did not independently reproduce them, and the two studies do not constitute a controlled comparison between VLAs and diffusion policies.
The evaluation infrastructures themselves serve different purposes. LIBERO emphasizes lifelong manipulation learning; RLBench provides vision-guided manipulation tasks; Open X-Embodiment contains more than one million trajectories across 22 embodiments to support cross-embodiment research.
For world models, the review discusses WorldScore, WorldModelBench, and WorldSimBench as approaches to evaluating generated environments. Their assessment extends beyond perceptual quality toward physical plausibility, conditioning fidelity, temporal consistency, and downstream usefulness.
A visually convincing simulated manipulation may still encode incorrect friction, contact behavior, or object dynamics.
Consequently, neither a high manipulation success rate nor a realistic-looking simulation is sufficient to establish safe performance in an organization’s actual physical environment.
Real-world deployment exposes nine distinct constraints
Table IV consolidates nine challenge categories: data scarcity, bias and ethics, hardware and real-time limitations, simulation-to-real transfer, generalization and reasoning, scalability, safety and robustness, transparency, and energy efficiency.
Several directly influence architecture decisions.
Data availability determines what can be learned. Collecting physically grounded demonstrations requires hardware access and controlled interactions. Rare, hazardous events are especially difficult to capture. Synthetic data and simulated interactions can expand coverage, but their usefulness depends on how well they represent relevant real conditions.
Control timing determines what can be executed. Model compression, distillation, edge computing, and specialized hardware may reduce computational demands. Each intervention must still be assessed for its effects on action quality, latency, memory, and reliability.
Physical mismatch determines where simulation fails. Friction, contact forces, material properties, actuator behavior, and sensor noise can differ between simulated and deployed environments. Digital twins and learned world models may help characterize those differences, but successful simulation does not establish successful transfer.
Safety constraints determine which actions are permitted. The review notes that task-success benchmarks often omit contact forces, recovery time, unusual disturbances, and operational constraints. It discusses runtime filtering, including control-barrier-function approaches, as a potential safeguard for enforcing defined state-space constraints.
These proposed remedies are engineering directions discussed by the review. They are not independently validated deployment solutions within this paper.
Match the architecture to the operating requirement
For procurement and system development, Cognaptus infers a more discriminating evaluation approach from the taxonomy.
A manufacturer automating variable-object manipulation should first determine whether failures arise from object recognition, instruction interpretation, grasp selection, or motion execution. Those diagnoses may point toward different model capabilities or combinations.
A warehouse operator evaluating a flexible picking system should measure not only task completion but also throughput, failure recovery, execution latency, and performance under changes to objects, sensors, or surroundings.
A robotics developer using world models for rare-event simulation should test whether generated scenarios preserve the physical behavior relevant to downstream controllers. Increasing synthetic-data volume alone does not establish training value.
Across these settings, vendor claims about zero-shot generalization or cross-embodiment transfer require testing on the intended hardware and operating conditions.
The relevant procurement question is not simply which system uses the most capable foundation model. It is which components address the task’s actual failure modes, and whether their integration satisfies measured control and safety requirements.
That interpretation follows from the review’s architectural synthesis. The paper does not provide comparative deployment costs, validated investment returns, or controlled evidence that a particular combination minimizes operating expenses.
What the review establishes, and what it cannot certify
The paper’s strongest contribution is organizational. It connects previously fragmented research on generalist robotic models, action-generation policies, behavior learning, and predictive simulation within a coherent embodied-system framework.
Its evidence is predominantly narrative synthesis, architectural comparison, and reported findings from external studies.
The authors do not provide a reproducible systematic literature-selection protocol, independent experimental benchmark, pooled effect-size estimates, or a common statistical comparison across the five families.
That limits conclusions about comparative model superiority. It also means industrial application examples cannot consistently isolate the incremental benefit of their generative components.
The taxonomy can clarify architectural choices, but it cannot certify that a proposed system will tolerate unusual contact dynamics, sensor failures, environmental shifts, or safety-critical situations.
Those questions remain deployment-specific and require evidence beyond this review.
Physical intelligence is a system property
The review makes a consequential distinction for organizations investing in embodied AI: improving a model’s understanding of a task is only one part of improving the physical system that performs it.
Generalization, instruction grounding, behavior generation, movement control, and environmental prediction can reinforce one another. Their combination must still respect the robot’s mechanical characteristics, computational resources, feedback requirements, and operational constraints.
For manufacturers and robotics developers, the resulting approach is to define the physical failure modes first, identify the model functions that address them, and validate the integrated system under the conditions in which it will operate.
The five-family taxonomy helps organize that work. Reliable execution must still be demonstrated.
Cognaptus: Automate the Present, Incubate the Future.
-
Satyam Gaba and Krutiksinh Rana and Siva Sai and Vinay Chamola and Dusit Niyato (2026). A Comprehensive Review of Generative Physical Artificial Intelligence. arXiv:2609.18111. https://arxiv.org/abs/2609.18111 ↩︎