TL;DR for operators
Translating a user’s question into the language of a document collection can make multilingual information accessible without translating every document. But successful question answering also requires finding relevant passages, recognizing what kind of answer is requested, and extracting the correct information.
A modular Amharic-English system illustrates both the opportunity and the difficulty. In its original 2019 evaluation, Amharic questions searching English documents achieved 72% precision and 79% recall, while English questions searching Amharic documents achieved 65% precision and 70% recall. The same architecture performed differently depending on language direction.
For organizations building multilingual knowledge systems, this suggests three evaluation priorities: test each language direction separately, measure final-answer correctness independently of retrieval relevance, and preserve diagnostic information across processing stages.
The evidence is historical. The 2026 publication revisits the 2019 system without new experiments and does not establish superiority over modern multilingual models.
One Language Pair, Two Different Retrieval Results
Consider an employee who asks, in Amharic, when an event occurred. The relevant information exists in an English-language document collection. The system must interpret the question, locate supporting text, and identify the date.
Now reverse the languages. An employee asks in English, but the relevant documents are in Amharic. Both situations involve the same two languages, yet the translation and downstream document-processing tasks differ.
Emebet Bekele and Fekade Getahun examine this problem in Amharic-English Cross-Language Question Answering Using Statistical Machine Translation, Named Entity Recognition, and Semantic Indexing.1 The article, published in 2026, reorganizes research originally conducted in a 2019 master’s thesis.
The original evaluation reveals a directional difference:
| Retrieval direction | Precision | Recall | Derived F1 |
|---|---|---|---|
| Amharic questions → English documents | 72% | 79% | 75.3% |
| English questions → Amharic documents | 65% | 70% | 67.4% |
Source: Section 6.2, Table 2, pages 8–9. Precision and recall come from the original 2019 evaluation; F1 scores were calculated for the 2026 revision.
The Amharic-to-English direction exceeded the reverse by 7 percentage points in precision and 9 percentage points in recall.
This matters because multilingual access is not necessarily symmetric. A system that supports both directions architecturally may deliver different levels of retrieval effectiveness in each.
The results also raise a diagnostic question: which processing stages account for the difference?
Translating a Query Leaves Several Problems Unsolved
The system uses cross-language question answering (CLQA): a question is expressed in one language, relevant documents are written in another, and the system attempts to return an answer rather than merely a document list.
Its design translates the incoming question into the target document language. That avoids the need to translate the entire document collection, although the paper does not measure the resulting computational savings.
Translation is performed using Moses, a classical statistical machine translation (SMT) toolkit. Its translation models are trained from Amharic-English parallel sentences collected across religious, legal, and news domains, supported by monolingual language-modeling data.
But translation is only one part of the architecture.
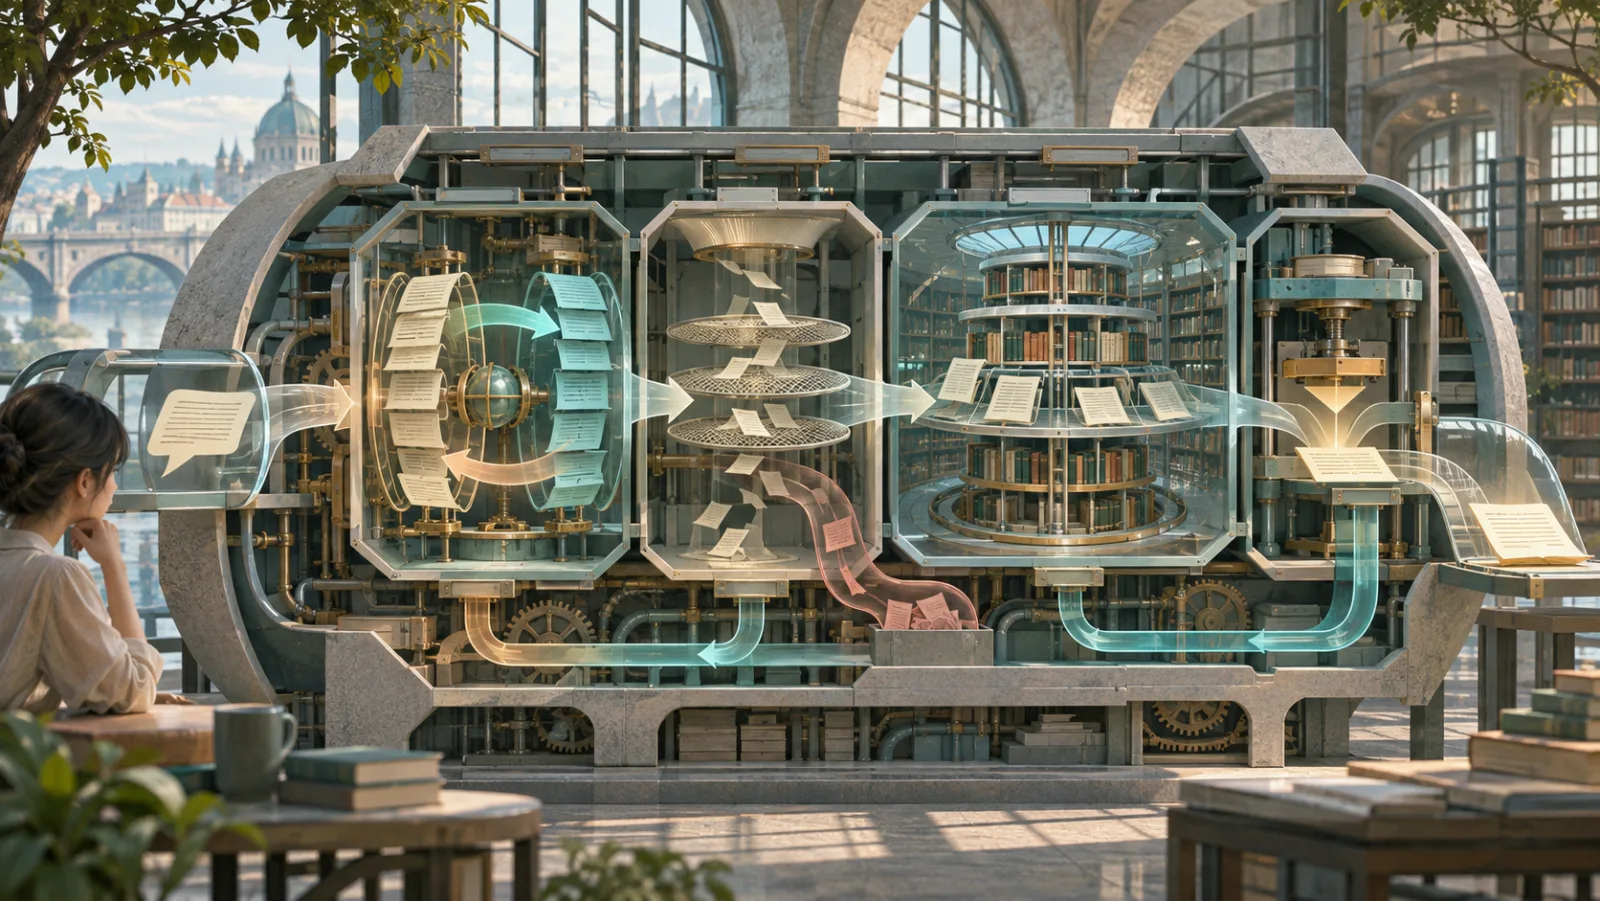
Sections 4 and 5 describe six principal components:
- Document acquisition: A Web crawler collects Amharic and English documents into separate collections.
- Indexing: Language-specific preprocessing normalizes, tokenizes, removes stop words, and stems text. Apache Lucene supports searchable indexes enriched with semantic annotations.
- Question translation: The incoming question is translated into the language of the target document collection.
- Question analysis: The system identifies informative terms and predicts an expected answer category, such as person, location, time, or quantity.
- Passage retrieval: Candidate passages are retrieved and ranked using lexical relevance and semantic compatibility.
- Answer extraction: Candidate answers are checked against the expected answer type and ranked.
The distinction between lexical relevance and semantic compatibility deserves attention.
Suppose a question asks when an event occurred. A passage may contain several words matching the translated query but no date or time information. Another passage may contain the relevant event and a recognized time expression.
The system uses named entity recognition (NER) to identify categories including persons, locations, organizations, and times. Maximum-entropy classifiers support entity recognition and expected-answer classification. These annotations allow the system to favor candidates with an appropriate semantic type.
The mechanism is straightforward: matching the topic of a question is not necessarily the same as locating the kind of information needed to answer it.
This is an architectural design claim, not a measured improvement attributable to NER. The study does not report a controlled ablation showing how much performance changes when semantic indexing or entity recognition is removed.
Errors Can Propagate Beyond Translation
The architecture creates several possible failure points.
Translation ambiguity can change the terms used to retrieve passages. Language-specific normalization or stemming can affect which documents match those terms. Entity recognition errors can prevent a relevant passage from being associated with the correct answer category. Limited corpus coverage can leave the relevant evidence unavailable altogether.
These problems can interact.
For example, even if a question is translated adequately and a relevant passage is retrieved, incorrect entity classification may still interfere with answer extraction. Conversely, a strong answer-extraction component cannot recover information that the retrieval stage never returns.
The authors identify translation ambiguity, NER errors, and corpus coverage as recurring constraints (Section 7.2).
They also interpret the stronger Amharic-to-English results as consistent with richer English-language resources and greater difficulty in downstream Amharic processing.
That explanation is plausible, but the experiment does not identify its causal contribution.
The study reports integrated-system outcomes, not controlled comparisons that independently vary translation quality, preprocessing, entity recognition, and indexing. The directional gap is directly observed; its decomposition across modules remains unresolved.
For a system maintainer, the value of the modular architecture is that these stages can be examined separately. That provides a basis for diagnosing failures, even though the paper does not quantify a diagnostic advantage over alternative architectures.
Retrieval Precision Is Not Answer Accuracy
The numerical results require a further distinction.
The paper defines precision as the proportion of retrieved items judged relevant, and recall as the proportion of all relevant items successfully retrieved:
The revised article also calculates their harmonic mean:
This produces the reported F1 values of 75.3% and 67.4%. They summarize the original aggregate precision and recall; they are not additional experimental observations.
More importantly, these metrics concern retrieved-item relevance. They do not establish that the final extracted answer is correct.
A system may retrieve a relevant document but select an incorrect date, person, or quantity. Document relevance and answer correctness therefore require separate evaluation.
The available research record also lacks the original evaluation sample counts, complete question-level results, confidence intervals, and relevance judgments. Consequently, the reported differences cannot be accompanied by a reliable statistical uncertainty assessment.
These limitations matter when comparing systems. A retrieval precision score from a study-specific evaluation cannot be treated as interchangeable with exact-match accuracy or answer-level F1 on a contemporary benchmark.
What an Enterprise Deployment Test Should Measure
For organizations providing multilingual access to internal knowledge, the architecture offers a practical way to organize evaluation.
First, evaluate language directions independently. A company supporting questions in one language over documents in another should maintain separate test sets for each pairing. Aggregate multilingual scores can conceal the kind of asymmetry observed here.
Second, record intermediate outputs. Retaining the original question, translated query, retrieved passages, recognized entities, expected answer type, and extracted answer would help distinguish translation failures from retrieval or extraction failures.
Third, measure the final answer. Representative questions should have reference answers and supporting evidence. Evaluation should test whether the system returns the correct information, not only whether retrieved passages are relevant.
Fourth, compare replacements under controlled conditions. Neural machine translation, dense retrieval, and transformer-based answer readers are plausible alternatives to classical modules. Substituting one component while holding evaluation data and other stages fixed would provide stronger evidence about which replacement improves quality.
These are Cognaptus implementation inferences, not experiments performed in the paper.
The deployment decision should also consider latency, maintenance requirements, domain coverage, and computational cost. The original study does not measure these sufficiently to support claims about production efficiency or return on investment.
The Historical Baseline Has Clear Boundaries
The research establishes that an integrated classical CLQA system operated in both Amharic-English retrieval directions and achieved the reported precision and recall under its original study-specific conditions.
Its broader comparative evidence is limited.
The 2026 article introduces subsequent multilingual research, including neural architectures and later Amharic benchmarks, but does not experimentally evaluate those alternatives. Nor does it provide the original corpora, configuration files, source code, and relevance judgments needed for full replication.
Without controlled ablations, standardized evaluation, or answer-level accuracy measurements, the findings cannot establish which component deserves credit, whether the architecture generalizes to specialized organizational documents, or whether it meets a modern deployment threshold.
The lasting contribution is therefore the system decomposition and its historical quantitative reference point.
A translated question can connect users to documents written in another language. Whether it produces a correct answer depends on the processing stages that follow—and those stages must be evaluated separately before a multilingual system can be trusted for operational use.
Cognaptus: Automate the Present, Incubate the Future.
-
Emebet Bekele and Fekade Getahun (2026). Amharic-English Cross-Language Question Answering Using Statistical Machine Translation, Named Entity Recognition, and Semantic Indexing. arXiv:2610.14756. https://arxiv.org/abs/2610.14756 ↩︎