TL;DR for operators
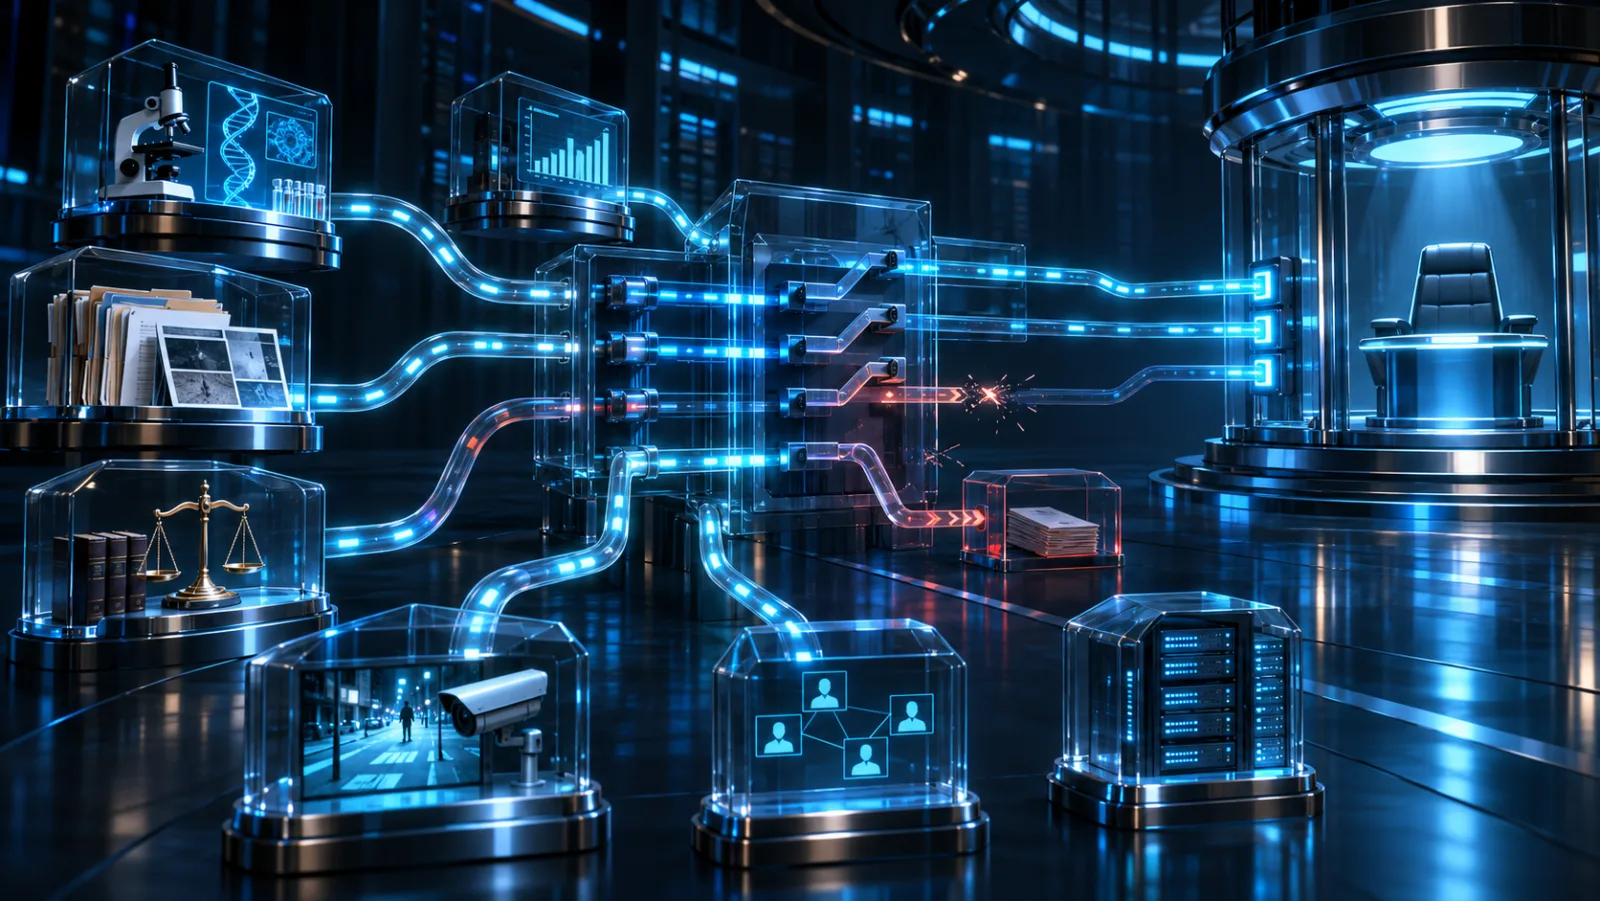
An AI team can possess every fact needed for a decision and still reach the wrong conclusion. TeamGym, a benchmark for distributed-information decision-making, reports an average 22.9-percentage-point loss in decision success when necessary facts are distributed among agents instead of given to one agent. Requiring those agents to retrieve the facts from source documents introduces a further 19.9-point loss.1
For enterprise teams building multi-agent research, due diligence, or compliance workflows, the distinction changes what needs to be measured:
- Retrieval: Did each agent find the evidence it was responsible for?
- Transmission: Did decision-critical evidence reach the other agents or final decision maker?
- Synthesis: Was that evidence correctly integrated into the final conclusion?
- Orchestration: Did the communication rules elicit the right information without introducing harmful distractions?
The paper also shows that communication structures perform differently depending on where evidence resides. More participation can improve coordination without increasing the proportion of necessary facts communicated. Reinforcement learning offers a possible improvement path, but its performance gains do not consistently transfer between task families.
These are findings from a constructed benchmark, not measured improvements in deployed business operations.
A team can know everything collectively and still decide incorrectly
Consider several specialist AI agents preparing an investment recommendation. One examines financial statements, another reviews contractual obligations, and a third checks regulatory constraints. A coordinator receives their reports and produces the recommendation.
Each specialist might perform its assignment competently. Yet the coordinator can still reach an incorrect decision if an essential qualification never appears in a message, a query requests only part of the available evidence, or the final synthesis combines the reports incorrectly.
TeamGym makes these failures measurable.
The researchers construct decision problems from 12 source corpora covering legal, financial, medical, and software-engineering work. The main evaluation uses 341 problem instances and eight language models.
Central to its construction is a set of pivotal information units (PIUs): evidence that is jointly sufficient to support a decision, but where removing any individual unit makes the remaining set insufficient under the formal criterion.
This is an inclusion-minimal set, not necessarily the unique or smallest possible evidence set. Operational construction uses source grounding and model-assisted sufficiency checks rather than exhaustive verification of every possible alternative problem.
The benchmark allocates these evidence units among agents and changes the rules governing their communication, permitting comparisons that ordinary end-to-end agent benchmarks struggle to isolate.
Two separate losses: communicating evidence and retrieving it
The primary benchmark compares three conditions involving the same underlying decision problems and pivotal evidence.
| Evaluation condition | What changes | Failure being tested |
|---|---|---|
| Single-Agent All-PIU | One agent receives all pivotal facts | Centralized decision baseline |
| Multi-Agent PIU-Only | Facts are distributed and directly supplied to participants | Communication and integration |
| Multi-Agent Full-Context | Participants must find their facts in source materials | Additional retrieval burden |
Under the principal setting—one PIU per participant with coordinator-selected speaking—the average success gap between centralized access and directly supplied distributed evidence is 22.9 percentage points.
Moving from directly supplied PIUs to source-material retrieval produces another 19.9-point decline.
These are sequential comparisons, not alternative estimates of one effect.
The breakdown also differs substantially across tasks. For the eCFR Casebook legal corpus, average success falls from 88.9% with centralized PIUs to 47.9% with distributed PIUs, and then to 18.1% with full-context retrieval. For CUAD contract-analysis problems, the corresponding rates are 90.4%, 72.5%, and 62.9% (Appendix E.1, Table 29).
This variation matters. A business evaluating an agent team cannot infer its communication reliability from the accuracy of its component models. Nor can it assume that improving document search will resolve failures that remain when relevant evidence is already supplied.
Communication rules work differently depending on who holds the facts
TeamGym tests five communication structures, including round robin, simultaneous responses, coordinator-selected speaking, current-speaker selection, and broadcast queries.
The researchers also vary evidence allocation: each agent might hold one pivotal fact, some facts might overlap, one participant might hold most of them, or a participant might hold none.
The principal interaction analysis finds that communication-structure effectiveness depends significantly on information allocation in both the PIU-only and full-context settings (joint tests, p < 0.001). Problem-instance fixed-effects specifications provide additional robustness checks. The regression evidence establishes an interaction within the benchmark, not a unique explanation for it.
Targeted finance experiments help identify one mechanism.
Across 59 instances evaluated with two Qwen3 models, round robin outperforms coordinator-selected speaking by 17.8 points when each participant holds one PIU. When almost all PIUs are concentrated with one participant, the advantage grows to 31.4 points—a 13.6-point interaction.
Why might concentrated information change the result?
A coordinator’s query can restrict what a knowledgeable participant reports. Asking for one narrow fact may leave other pivotal facts unmentioned, even when the participant possesses them.
In a matched finance intervention, adding public PIU-category labels and reporting instructions reduces the estimated communication-structure interaction from 15.5 to 5.9 points. Removing the task-specific coordinator query changes the interaction to -5.4 points without those additions, or -9.3 points with them (Section 4.4.1, Table 4).
The intervention does not establish that removing coordinator queries is universally preferable. It establishes that query design can materially change the relative performance of communication structures under tested evidence allocations.
More messages can also cause problems.
In a SARA legal-task intervention with concentrated evidence, participants assigned no PIUs nevertheless receive source materials. Removing their messages from a frozen transcript increases final-decision success from 21.2% to 68.9%.
When those participants do not receive source material, removing their messages has essentially no benefit: success changes from 69.9% to 68.9% (Section 4.4.2, Table 5).
The result isolates a consequential source-material and message-inclusion interaction. It does not establish whether the damage comes from additional transcript length, contradictory claims, or irrelevant content.
For operators, the relevant design variable is not simply how many agents speak. It is which evidence each contribution adds and how that contribution affects the final decision.
Receiving the facts is not the same as synthesizing them
Even a transcript containing necessary evidence may produce an incorrect conclusion.
TeamGym investigates this distinction using frozen communication trajectories. The researchers modify selected transcript content and regenerate only the final decision, separating the effects of correct synthesis from error uptake.
Adding correct synthesis improves success by 14.6 points for Qwen3-32B and 17.7 points for Qwen3-235B when those models also generate the final decision. With GPT-5.5 as the final decision maker, the respective improvements are 5.7 and 8.2 points.
Removing error uptake produces smaller gains in all four tested conditions, with statistically significant effects for Qwen3-235B participants but not Qwen3-32B participants (Section 4.3, Table 3).
The experiment supports treating synthesis accuracy as a separate quality dimension rather than assuming that correctly transmitted evidence has been correctly understood.
Communication capacity also has limits. In a legal-task token-budget ablation using GPT-5.5, increasing public-message capacity from 32 to 128 tokens raises average success from 55.3% to 78.6%. Raising the budget to 256 tokens yields no further observed improvement.
Capacity can be binding, but unlimited communication is not established as beneficial.
Learning to coordinate helps, but the gains do not transfer uniformly
TeamGym also functions as a training environment.
Using Group Relative Policy Optimization, the researchers train Qwen2.5-7B-Instruct participant and coordinator policies with rewards derived from GPT-5.5 assessments of final decisions. No separate reward is assigned for asking more participants or improving turn-taking.
On 36 CUAD-derived validation instances, joint participant–coordinator training improves the LLM-judged decision score from 11.97% to 22.38%. It also increases the proportion of instances in which every participant is queried from 80.6% to 100%.
But on 26 MAUD-derived transfer instances, the score changes only from 5.12% to 5.58%, despite the learned comprehensive-querying behavior transferring.
A separate shared-participant training experiment under current-speaker selection provides more favorable held-out evidence. On 40 four-participant FinLongDocQA test instances, the LLM-judged score rises from 33.50% to 41.13%.
Cross-replay of communication trajectories and final-decision policies attributes an average 6.95-point gain to the trained trajectory on held-out cases completed by both trajectories. Replacing the final-decision policy alone does not yield a statistically significant improvement.
This suggests that policy training can improve how a team communicates, rather than merely making the final answer generator better.
Yet the communication diagnostics expose another qualification. On held-out FinLongDocQA, the proportion of episodes where every participant speaks rises from 62.5% to 82.5%, while PIU transcript coverage remains unchanged at 63.1%.
More complete participation is not necessarily more complete evidence transmission.
The training demonstrations each use a single run, and the quality metrics are LLM-judged scores rather than the binary success rates used in much of the main benchmark. These results should not be combined into one general training-effect estimate.
What enterprise agent designers can measure differently
Cognaptus inference: TeamGym suggests a more diagnostic acceptance-testing approach for workflows in which specialized agents examine different documents before a shared decision.
A procurement risk team, for example, could identify the contract clauses, financial exposures, and compliance findings required for a recommendation. It could then evaluate a centralized agent, a distributed team with those facts supplied, and a distributed team retrieving from the original documents.
The comparisons would identify whether the largest performance loss occurs during retrieval or after relevant evidence becomes available.
The broader evaluation should record:
- Evidence coverage: Which required facts were found, transmitted, and reflected correctly in the decision?
- Coordinator-query completeness: Did questions elicit all relevant evidence categories held by each participant?
- Message contribution: Did an agent’s response add decision-relevant evidence, repeat known information, or introduce unsupported claims?
- Synthesis integrity: Did the final decision use the evidence correctly, including qualifications and contradictions?
- Generalization: Does performance persist when document families, evidence allocations, participant counts, or communication budgets change?
These measures are more diagnostic than agent participation counts or total message volume alone.
For teams selecting orchestration architectures, the research also argues against choosing a communication topology independently of evidence allocation. A configuration that works with evenly distributed facts may behave differently when one agent holds most of the relevant information.
These are proposed evaluation practices, not independently validated business interventions.
The benchmark measures a controlled problem, not every enterprise team
TeamGym’s strongest evidence comes from matched comparisons across constructed decision problems. Several limitations matter when extending its findings.
The PIU construction procedure depends partly on model-generated reasoning and model judgments. Independent checks on selected MAUD and FinLongDocQA instances report leave-one-out pivotality pass rates of 95.5% and 97.0%, respectively, but validation does not cover every corpus. Some participant-level source-material checks also identify evidence-allocation exceptions.
The environment assumes a shared team objective. It does not experimentally address strategic misreporting, malicious participants, or conflicting organizational incentives.
The communication interventions operate within selected protocols and frozen trajectories. Their measured effects need not match what would happen if an entire adaptive conversation were rerun.
Finally, the training results have limited replication across seeds and base models, and the complete reproducibility code and supplementary archive are reported as forthcoming.
These boundaries do not negate the communication and retrieval gaps. They define what the reported evidence can support.
The final decision needs an evidence trail
TeamGym identifies a reliability problem that individual-agent benchmarks can miss: the collective availability of evidence does not guarantee its successful use.
The research separates failures of retrieval, transmission, and synthesis, then demonstrates why evidence placement, coordinator queries, communication capacity, and policy training can change outcomes.
For enterprise operators, the resulting design principle is specific: establish what evidence a decision requires, trace where that evidence enters the agent system, and test whether it survives into the final conclusion. Measure decision quality alongside evidence coverage, particularly when communication policies are modified or trained.
A team that produces more messages or involves more specialists has not necessarily made a better-informed decision. The relevant evidence must reach the conclusion—and be used correctly.
Cognaptus: Automate the Present, Incubate the Future.
-
Chanwoo Park and Jaywoong Jeong and Zachary Wojtowicz and Yubin Kim and Taekyun Lee and Kaiqing Zhang and Asuman Ozdaglar (2026). TeamGym: A Gym for Team Decision-Making by AI Agents with Distributed Information. arXiv:2610.37571. https://arxiv.org/abs/2610.37571 ↩︎