TL;DR for operators
A maintenance team using bearing vibration data needs accurate estimates of remaining life, but the most accurate model may also be the most expensive to operate. The relevant question is whether improved predictions justify additional computation and produce more reliable maintenance decisions.
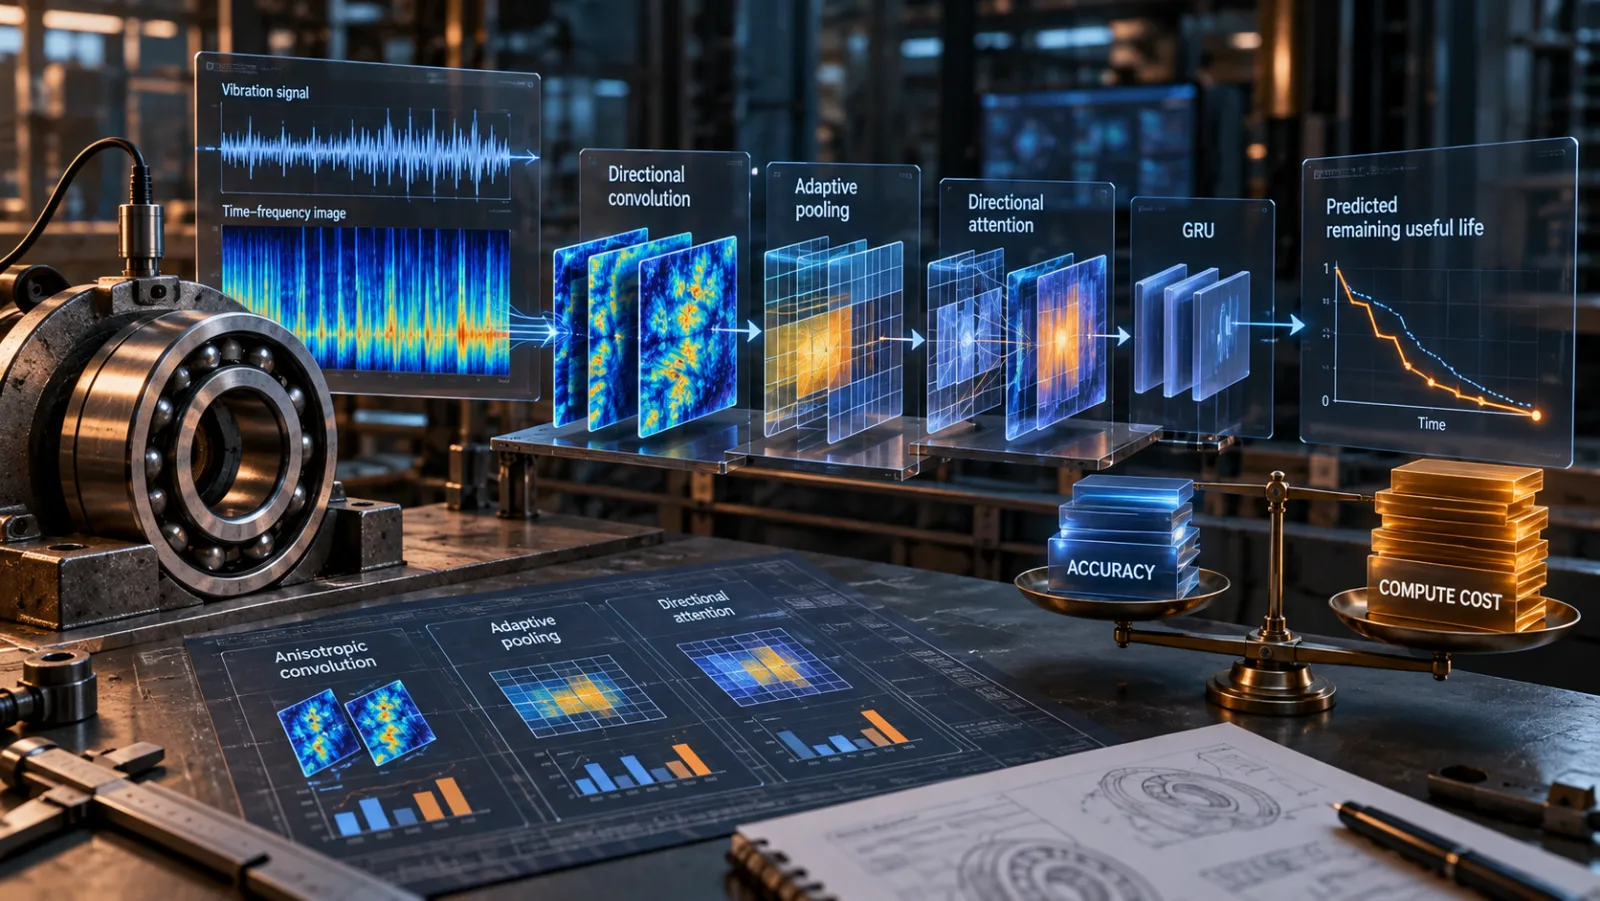
Park, Choo, and Bae’s FAAC-GRU model1 achieves the lowest aggregate prediction errors among six evaluated architectures on two laboratory bearing benchmarks. Its principal innovation is to process vibration time–frequency images using convolutional filters that distinguish the frequency and time directions.
The component tests are especially informative. Directional convolution improves average prediction accuracy consistently across four evaluated operating-condition groups. Adaptive pooling provides stronger benefits on one dataset than the other, while directional attention contributes comparatively modest improvements.
The complete model requires 9.814 GFLOPs and 1.306 milliseconds per sample on an RTX 4080—more than every evaluated baseline. Its uncertainty intervals also lack independent calibration evidence.
For industrial AI teams, the findings support testing directional feature extraction, not automatically adopting the full architecture. Deployment still requires equipment-specific evaluation, actionable maintenance thresholds, and measurement of complete processing costs.
Better predictions do not settle the maintenance decision
Consider a maintenance system monitoring several bearings through vibration sensors. A model estimates how far each bearing is from failure, helping determine which equipment deserves inspection or replacement.
If a more sophisticated model reduces prediction error, that is valuable evidence. But maintenance decisions also depend on the consequences of inaccurate estimates, the consistency of performance across equipment, and the computing resources required to generate predictions.
The FAAC-GRU study provides a concrete example.
Across the FEMTO-ST benchmark, FAAC-GRU records an aggregate root mean squared error (RMSE) of 0.181, compared with 0.234 for the strongest competing model on that metric. On XJTU-SY, the corresponding figures are 0.178 and 0.204.
These represent approximate RMSE reductions of 22.6% and 12.7%, respectively.
The model also achieves the lowest asymmetric prognostic Score on both datasets: 16.246 versus the best competing 19.003 on FEMTO-ST, and 1.915 versus 2.024 on XJTU-SY. This Score penalizes overestimating remaining life more strongly, reflecting the greater potential risk of predicting that equipment will survive longer than it actually does.
These are meaningful benchmark results, but their measurement scale matters.
The model predicts normalized remaining useful life (RUL), which declines linearly from one at the first recorded observation to zero at the recorded failure endpoint. An RMSE of 0.181 therefore does not represent 0.181 hours, days, or maintenance cycles.
The experiments cover 11 FEMTO-ST test bearings under the official PHM 2012 split and seven selected XJTU-SY outer-race-fault bearings evaluated through leave-one-out cross-validation. They establish comparative prediction performance within these laboratory protocols, not a universal improvement across industrial machinery.
Individual results also differ. For FEMTO-ST bearing FB2-4, SAL-CNN achieves RMSE 0.224 while FAAC-GRU records 0.305. Aggregate leadership does not imply leadership on every asset.
Why vibration images benefit from directional filters
The architecture begins with a physical distinction often overlooked in conventional image processing.
A vibration time–frequency representation has two axes describing different quantities. Frequency indicates where spectral energy occurs, while local time indicates how that energy evolves within the measured signal.
Patterns extending along the frequency axis need not resemble patterns extending along the time axis.
Conventional square convolutional filters treat these dimensions symmetrically in their receptive-field geometry. FAAC-GRU instead introduces multi-scale anisotropic convolution (MSAC), using rectangular kernels oriented differently along the two axes.
Its three parallel branches employ paired kernels of dimensions 3×1 and 1×3, 7×3 and 3×7, and 11×5 and 5×11. These configurations capture directional structures at different spatial scales.
The architecture then combines several additional operations:
- Dual-axis attention (DCBAM) combines channel attention with frequency-oriented and time-oriented spatial responses.
- Dynamic adaptive pooling (DAP) compresses feature maps through learned, input-dependent weights rather than uniformly averaging every location.
- A gated recurrent unit (GRU) captures degradation dynamics across successive vibration observations.
Each vibration observation is divided into five contiguous segments, transformed into continuous wavelet transform magnitude scalograms, and processed using a shared feature extractor. The segment embeddings retain their acquisition order before entering the recurrent model.
The frequency and local-time axes within an individual scalogram are distinct from the sequence of successive observations processed by the GRU.
This architecture is plausible because vibration patterns have directional structure. The more consequential question is which components actually improve prediction accuracy.
The ablations identify unequal sources of improvement
The study’s controlled architectural ablations are more informative for model development than the aggregate rankings alone.
The researchers separately replace directional convolutions with isotropic ones, adaptive pooling with alternative aggregation methods, and dual-axis attention with conventional convolutional block attention (CBAM), holding the remaining architectural components fixed.
The following values summarize the reported mean RMSE comparisons. Lower is better.
| Operating-condition group | Isotropic → anisotropic | GAP → DAP | CBAM → DCBAM |
|---|---|---|---|
| FEMTO-ST Condition 1 | 0.138 → 0.102 | 0.139 → 0.102 | 0.105 → 0.102 |
| FEMTO-ST Conditions 2–3 | 0.260 → 0.247 | 0.285 → 0.247 | 0.278 → 0.247 |
| XJTU-SY Condition 1 | 0.220 → 0.190 | 0.194 → 0.190 | 0.200 → 0.190 |
| XJTU-SY Condition 2 | 0.166 → 0.163 | 0.163 → 0.163 | 0.165 → 0.163 |
Source: Section 5, Tables 11–12 and 14–17. Each column represents a separate controlled ablation, not cumulative improvements.
Anisotropic convolution reduces mean errors across all four groups. Its advantage is particularly pronounced under FEMTO-ST Condition 1, although some individual bearings favor isotropic filters.
This is the strongest component-level evidence in the study.
Appendix A provides supplementary, descriptive support for the architectural rationale. Structure-tensor analysis examines directional organization in 64×64 scalograms across 18 bearings, two channels, and five local window sizes. All 180 analyzed combinations show positive frequency-versus-time axis preference and greater coherency than pixel-permuted reference maps.
That analysis establishes directional image structure. It does not establish statistical significance or demonstrate that the measured orientations specifically encode degradation information.
The ablation results, rather than the orientation measurements alone, make the stronger empirical case for directional convolution.
Adaptive pooling helps, but not on every dataset
Dynamic adaptive pooling addresses another representational issue.
Global average pooling (GAP) compresses spatial feature maps by assigning equal weight to every location. Appendix A formally shows that spatially different maps with identical channel-wise means produce the same GAP output.
Consequently, GAP can discard information about where activations occur or how concentrated they are.
DAP replaces fixed averaging with two complementary sequences of learned axis-wise aggregation: frequency-to-time and time-to-frequency. Each pathway produces input-dependent spatial weights that are separable products of its axis-specific weight vectors.
This enables nonuniform weighting, but does not guarantee preservation of diagnostically relevant information.
The empirical differences illustrate that boundary.
On FEMTO-ST Condition 1, replacing GAP with DAP reduces mean RMSE from 0.139 to 0.102. On Conditions 2–3 combined, RMSE falls from 0.285 to 0.247.
The improvements are substantially smaller on XJTU-SY. Under Condition 2, GAP and DAP both report mean RMSE of 0.163, while simple flattening performs slightly better at 0.161.
Directional attention contributes still less consistently. DCBAM improves or matches condition-group mean performance relative to CBAM, but the differences are generally modest and some individual bearings favor the conventional approach.
These tests suggest a practical development sequence: establish whether directional convolution improves the target system, then evaluate whether adaptive pooling and additional attention justify their complexity.
Accuracy gains carry a substantial computing bill
FAAC-GRU’s architectural improvements are not computationally free.
The full model contains 0.939 million parameters and requires 9.814 GFLOPs and 1.306 milliseconds of GPU inference time per input sample.
For comparison, SAL-CNN requires 0.149 GFLOPs and 0.078 milliseconds, while MLP-DT requires 0.451 GFLOPs and 0.109 milliseconds.
FAAC-GRU therefore has approximately 66 times SAL-CNN’s reported floating-point operations and nearly 17 times its measured inference latency.
These are measurements on an RTX 4080, using standardized input dimensions and sequence lengths where applicable. They do not include a comprehensive industrial processing pipeline.
The model’s preprocessing involves segmentation, wavelet transformation, and resizing. Its total operating latency may therefore differ substantially from the reported neural-network inference time.
There is a second deployment consideration: predictive uncertainty.
FAAC-GRU smooths RUL predictions using a causal exponentially weighted moving average with current-observation weight 0.2. It also uses Monte Carlo dropout in the regression head to generate multiple stochastic prediction trajectories and derive pointwise uncertainty intervals.
However, the study does not independently establish interval coverage, sharpness, or calibration. A nominal 95% interval cannot be interpreted as providing 95% empirical coverage merely because its endpoints use the corresponding predictive quantiles.
For maintenance planners, interval reliability must be demonstrated before uncertainty estimates become operational confidence guarantees.
From laboratory accuracy to maintenance value
Cognaptus inference: The study suggests a selective model-development strategy for industrial condition-monitoring teams.
An engineering team could first incorporate anisotropic convolution into a lighter existing architecture, compare it against the unchanged baseline on plant-specific bearings, and introduce adaptive pooling or directional attention only if controlled testing demonstrates additional benefit.
A maintenance team would then need to translate predicted normalized RUL into usable inspection and service thresholds. The relevant economic outcomes include missed failures, unnecessary interventions, downtime, and maintenance scheduling costs—not simply differences in normalized RMSE.
Several boundaries remain unresolved.
The experiments use accelerated laboratory degradation data rather than independent industrial deployment records. XJTU-SY evaluation is limited to selected outer-race faults. Magnitude-only wavelet representations discard phase information, resizing may remove fine-scale details, and the reported comparisons do not establish statistical significance across independent training repetitions.
A deployment evaluation would therefore need to measure predictive performance under actual sensor and operating conditions, end-to-end preprocessing and inference latency, error consequences near intervention thresholds, and empirical uncertainty calibration.
The research provides credible evidence that directional structure can be exploited to improve bearing-life predictions within the tested conditions. Its ablations also show why additional neural-network components should earn their place individually.
For industrial AI, the next advance is not necessarily adopting the entire benchmark-winning architecture. It may be retaining the directional feature extraction that performs consistently while finding a cheaper, sufficiently reliable route from sensor measurements to maintenance decisions.
Cognaptus: Automate the Present, Incubate the Future.
-
Hanbyeol Park and Jungho Choo and Hyerim Bae (2026). Factorized axis convolutional gated recurrent unit with dynamic adaptive pooling for remaining useful life prediction of rolling bearings. arXiv:2609.30972. https://arxiv.org/abs/2609.30972 ↩︎