Cover image

The Extra Molecular Signal Has a Different Job

TL;DR for operators Adding another molecular signal to a diagnostic AI system does not necessarily improve its classification accuracy. MOXAI demonstrates that combining DNA methylation and copy number information can reduce variability across validation folds even when methylation alone remains more accurate. The study also separates two qualities often treated as interchangeable: predictive performance and explanation quality. DINOv2 achieves 81.30% accuracy on an independent glioblastoma cohort, compared with 67.48% for ResNet50, but ResNet50 produces more localized genomic attribution maps. DINOv2’s reported 94.25% accuracy applies only to predictions exceeding a 0.9 confidence threshold. ...
November 1, 2026 · 8 min · Zelina
Cover image

Bearing Life Prediction Has a Direction—and a Compute Cost

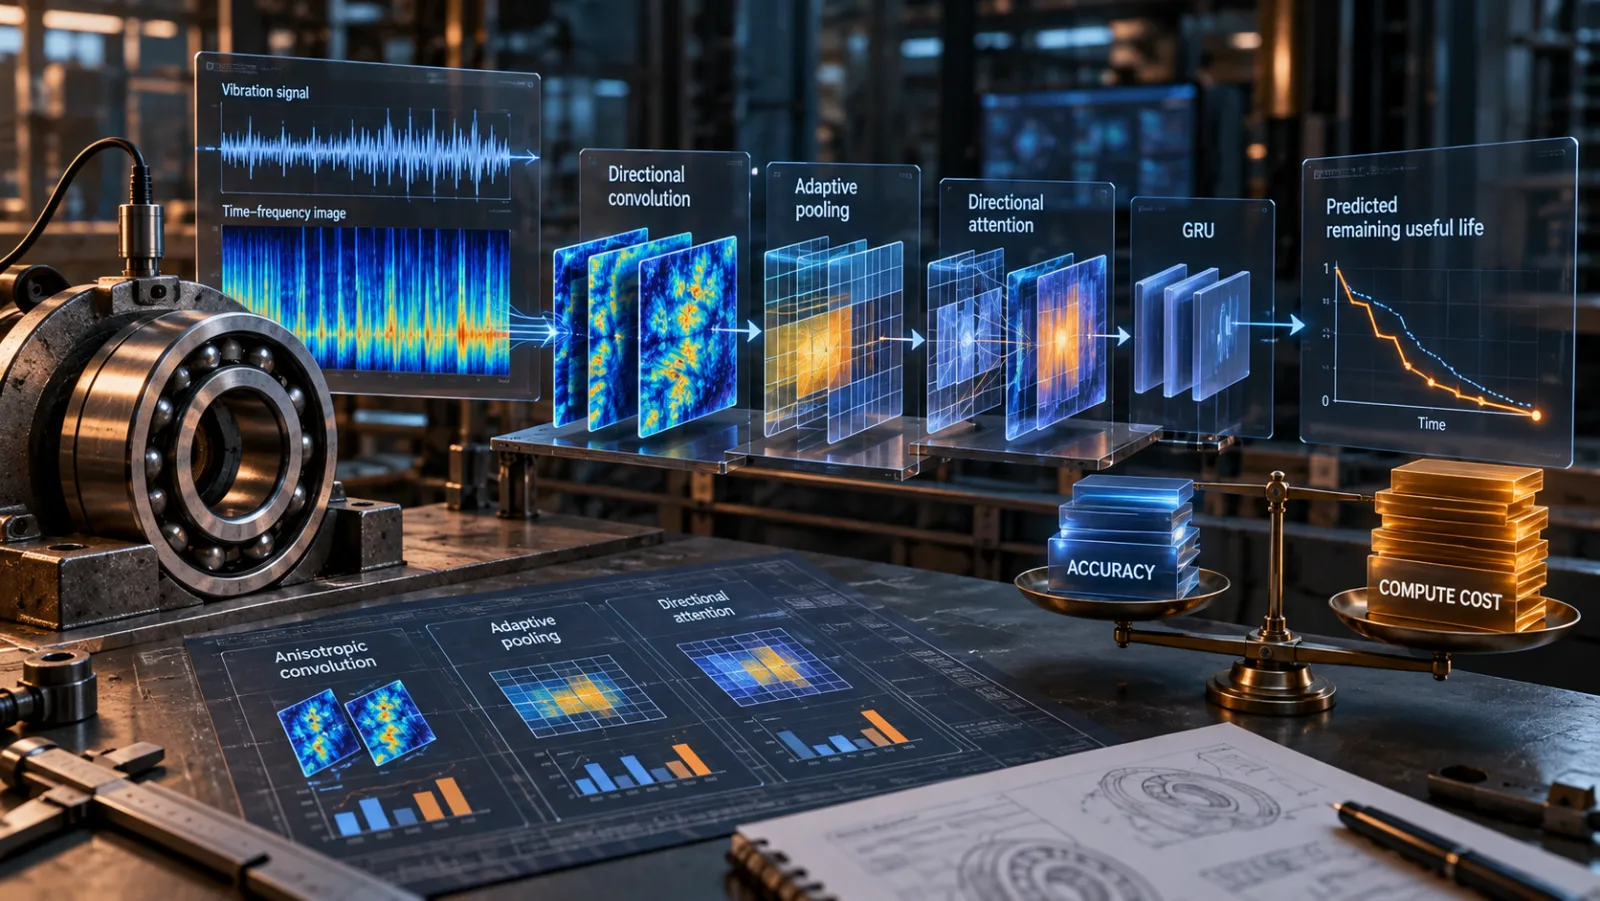
TL;DR for operators A maintenance team using bearing vibration data needs accurate estimates of remaining life, but the most accurate model may also be the most expensive to operate. The relevant question is whether improved predictions justify additional computation and produce more reliable maintenance decisions. Park, Choo, and Bae’s FAAC-GRU model1 achieves the lowest aggregate prediction errors among six evaluated architectures on two laboratory bearing benchmarks. Its principal innovation is to process vibration time–frequency images using convolutional filters that distinguish the frequency and time directions. ...

October 28, 2026 · 8 min · Zelina
Cover image

Regularize What the Network Activates

TL;DR for operators A neural network can be regularized without acting only on its weights or randomly disabling units. Gaussian Neural Networks1 instead teaches hidden layers what their own normal activation patterns look like, then adds a penalty when internal signals become improbable under those learned distributions. That mechanism matters because the simpler implementation performed better than its complexity might suggest. Across ten regression and classification datasets, the sparse Gaussian neural network beat the corresponding basic ANN on nine and tied on one. The denser variance model, despite representing richer dependencies, was less consistent and could spend substantial training time optimizing the auxiliary objective rather than the task itself. ...

October 11, 2026 · 7 min · Zelina
Cover image

The Viscosity Budget: Why Softmax Is Not Just a Knob

TL;DR for operators A new paper by Jose Marie Antonio Miñoza, Erika Fille T. Legara, and Christopher P. Monterola argues that a log-sum-exp neural layer is not merely analogous to a viscous Hamilton-Jacobi equation. Under the paper’s parameterisation, it is exactly the Hopf-Cole solution of one, evaluated at the input point.1 The operational point is not “neural networks are physics now”, although someone will certainly try to put that on a slide. The point is cleaner: one parameter, $\varepsilon$, simultaneously controls softmax temperature, PDE viscosity, and entropy-regularised convex optimisation. That makes smoothness, expressiveness, robustness, attribution sharpness, and scaling behaviour mathematically coupled. ...

June 18, 2026 · 18 min · Zelina
Cover image

Beyond Accuracy: When Forecasts Meet Cash Flow

Inventory is the moment when a forecast stops being a spreadsheet exercise and starts costing money. A demand model can look elegant in validation. It can shave RMSE by a few decimals, win a leaderboard, and make the data science team briefly feel like civilization has advanced. Then the warehouse over-orders slow-moving stock, the store misses fast-moving items, and the finance team discovers that “better accuracy” is not the same thing as better cash flow. ...

March 18, 2026 · 12 min · Zelina
Cover image

When One Heatmap Isn’t Enough: Layered XAI for Brain Tumour Detection

Diagnosis has a simple business problem hiding inside a clinical one: nobody wants a black box that is confident for the wrong reason. That is especially true in medical imaging. A brain MRI classifier that says “tumour” or “non-tumour” is not automatically useful because it crosses a respectable accuracy threshold. The difficult question comes next: did the model look at the clinically relevant region, or did it discover some convenient artefact in the image pipeline? A single heatmap may answer that question. It may also merely look persuasive, which is not quite the same thing. Medicine, regrettably, is one of those domains where aesthetic confidence is still not a validation method. ...

February 7, 2026 · 17 min · Zelina
Cover image

Learning the Fast Lane: When MILP Solvers Start Remembering Where the Answer Is

Queue. That is the least glamorous word in enterprise optimization, which is probably why it matters. A mixed-integer linear programming solver does not usually fail because it lacks mathematical dignity. It fails because the search tree becomes too large, the clock keeps running, and some poor planning system is still deciding which facility to open, which order to allocate, which truck route to approve, or which resource schedule to release before Monday morning starts behaving like Monday morning. ...

January 23, 2026 · 17 min · Zelina
Cover image

Clustering Without Amnesia: Why Abstraction Keeps Fighting Representation

A customer database looks harmless until someone asks for “natural segments.” Then the ritual begins. Export the data. Pick a clustering algorithm. Reduce the dimensions. Make a pretty 2D plot. Give each blob a name. “Premium convenience buyers.” “Budget explorers.” “Dormant loyalists.” Everyone nods, because blobs are comforting. Business strategy has survived on worse. ...

January 20, 2026 · 19 min · Zelina
Cover image

When Prophet Meets Perceptron: Chasing Alpha with NP‑DNN

Accuracy is a dangerous word in finance. It sounds clean. It fits nicely into a slide. It makes a model feel disciplined, measurable, and almost adult. A stock-prediction system with accuracy above 90% sounds like something a hedge fund would guard behind three NDAs and a biometric door. That is exactly why we should slow down. ...

January 9, 2026 · 15 min · Zelina
Cover image

Greedy Enough to Win: When Loss Starts Driving the Learning Rate

Training runs rarely fail with cinematic drama. They do not burst into flames. They simply become expensive, slow, and faintly embarrassing. A fine-tuning job starts with promise, the loss descends, then progress flattens. Another run behaves well for 200 steps, then becomes jumpy after a data shard changes. A third run is rescued by lowering the learning rate, except nobody knows whether the rescue came too early, too late, or by accident. Eventually, the team does what teams do: try cosine decay again, because at least cosine looks mathematically respectable while doing whatever it was going to do anyway. ...

December 17, 2025 · 16 min · Zelina