TL;DR for operators
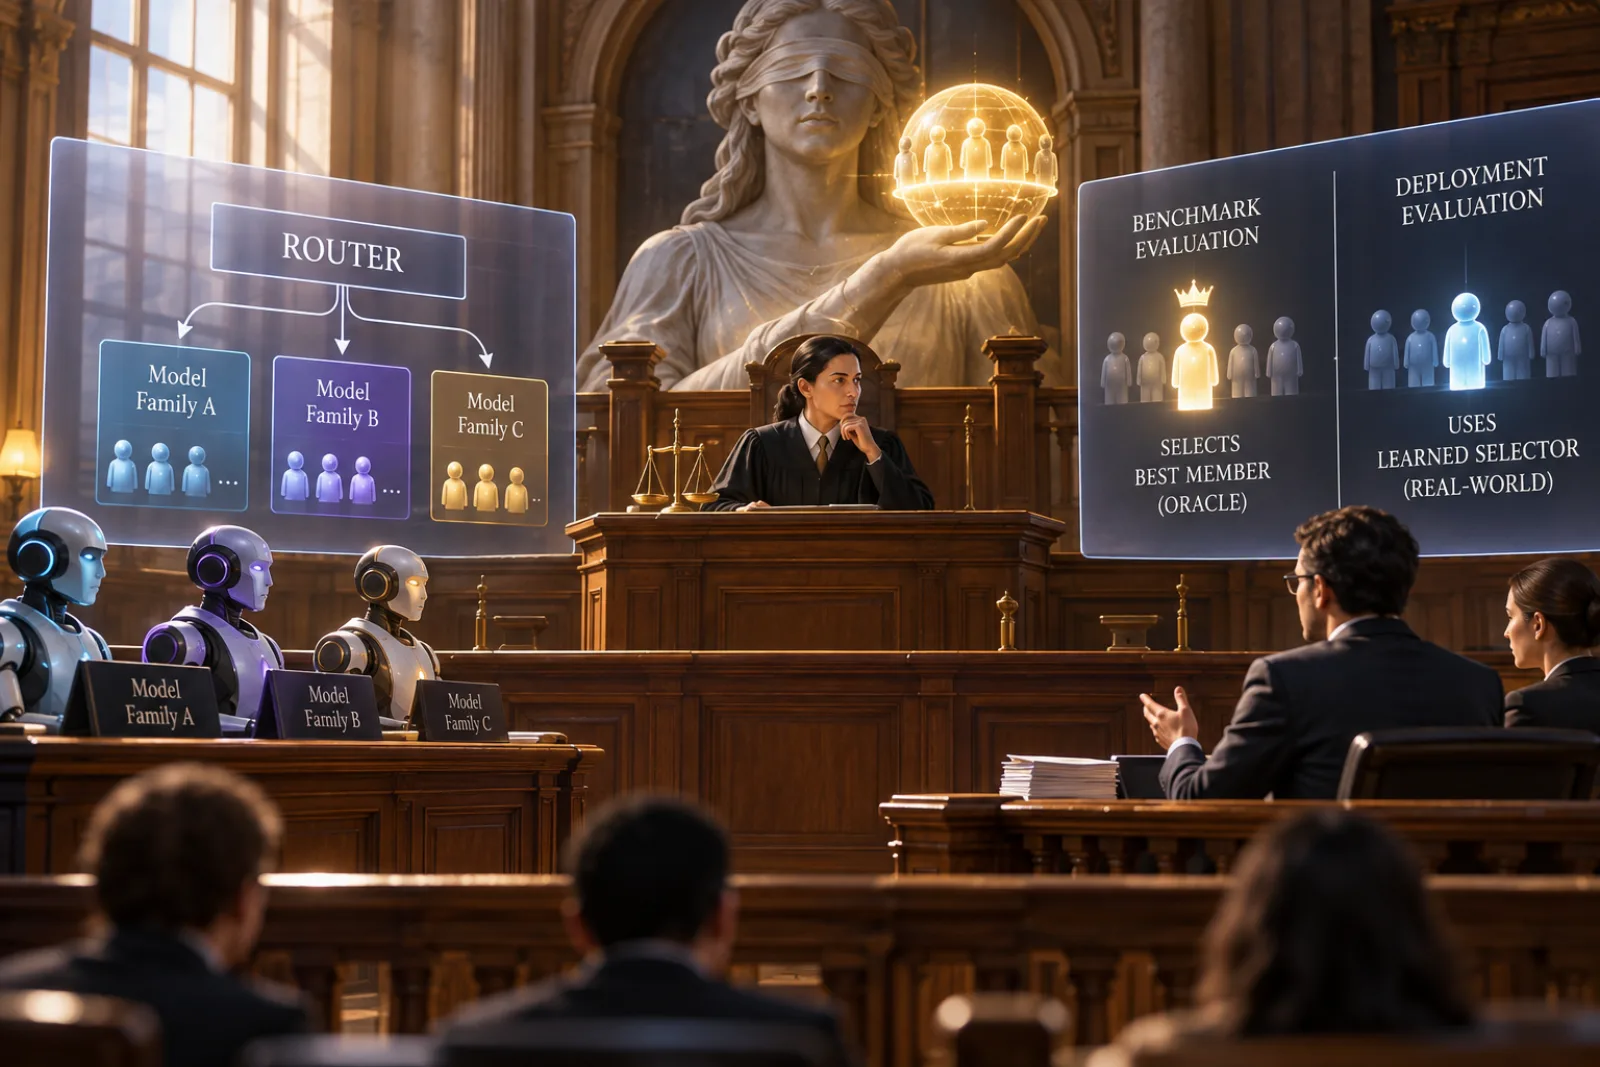
A hierarchical selector makes two decisions: first choose a family of models or solvers, then choose a concrete member of that family. If evaluation scores the first decision by quietly granting it the best possible member of the chosen family, the benchmark is measuring a system that cannot actually be deployed.
Zhang, Tang, and Zhu formalize this mismatch in Partition Scores Are Not System Scores.1 Across five public algorithm-selection benchmarks, every evaluated decomposed pipeline scores worse once its learned second-stage selector replaces the oracle. Four of ten decomposed-versus-flat comparisons even change direction at the point-estimate level.
For architecture selection, the practical rule is simple: compare complete pipelines. A family-level score can remain useful during development, and the paper shows that validation-side correction can make it more informative, but it should not be treated as evidence that a hierarchical system beats a flat alternative in deployment.
The benchmark can give the second stage a capability deployment does not have
Decomposition is attractive because it reduces a large selection problem into stages. An AutoML system might first route a dataset toward a family such as tree-based methods, neural networks, or linear models. A solver portfolio may similarly route an instance into a solver family before choosing the executable solver.
The difficulty is not decomposition itself. It is what happens during evaluation.
A common partition-level score asks whether the outer router chose a promising family and then credits that family with its best algorithm for the instance. The resulting score therefore contains an oracle inside the chosen family. A deployed system has no such oracle. It must use a learned second-stage selector.
The paper names the difference the deployment-fidelity gap:
Here, $S_{\mathrm{part}}$ is the oracle-assisted partition score and $S_{\mathrm{e2e}}$ is the score of the deployable pipeline. The gap is not a measure of whether the outer router chose the globally correct family. It measures the utility lost because the actual inner selector cannot reproduce the best-in-family choice.
That distinction moves second-stage selection error from “implementation detail” into the system evaluation itself.
A routing advantage survives only after paying the inner-selector cost
The paper’s most useful accounting result concerns comparisons between architectures:
An apparent partition advantage therefore transfers to deployment only after subtracting the difference between the two pipelines’ deployment-fidelity gaps.
This matters because second-stage losses need not affect competing architectures equally. A hierarchical system can identify a promising family very well yet have difficulty selecting among similar members inside that family. A competing system can have a weaker-looking partition score but incur less downstream selection regret.
The paper makes this condition more precise at the instance level. A family chosen by the outer router remains optimal after deployment only when its oracle advantage over every competing family is at least large enough to cover the difference in within-family regret.
For operators, this changes what should be diagnosed. Outer-router accuracy alone is insufficient. The relevant question is whether the margin created by routing is large enough to survive the selector that will actually run next.
The missing second stage is large enough to change architecture rankings
The empirical results make the accounting problem concrete. The authors evaluate pairwise and multiclass decomposed selectors on five public benchmarks covering tabular AutoML, MAXSAT, and hierarchical CSP/SAT selection.
All ten decomposed benchmark-pipeline cells have positive deployment-fidelity gaps. The smallest headline gaps are roughly 0.012 on TabZilla. The largest are about 0.136 on PROTEUS-2014.
The comparative consequences are more revealing:
| Setting | Partition advantage | End-to-end advantage | Interpretation |
|---|---|---|---|
| TabZilla, multiclass vs flat | 0.0145 | 0.0024 | Most of the apparent advantage is absorbed |
| TabRepo, multiclass vs flat | 0.0446 | -0.0077 | Point estimate changes sign |
| TALENT, multiclass vs flat | 0.1069 | 0.0316 | Advantage survives, but shrinks materially |
| MAXSAT, multiclass vs flat | 0.0202 | -0.0047 | Small point-estimate sign change |
| PROTEUS, multiclass vs flat | 0.3285 | 0.1919 | Large advantage remains, but about 41% is absorbed |
Both decomposed variants change sign against the flat baseline on TabRepo and MAXSAT, producing four sign-changing comparisons in total. These should not be read as four dramatic reversals: several resulting end-to-end margins are small and sensitive to the inner selector. The stronger conclusion is that partition scores alone do not reliably preserve the ranking.
The same pattern appears in the paper’s identification analysis. Across all fifteen pairwise pipeline comparisons, the partition-only interval for possible deployable advantage crosses zero. Given only the partition result and admissible inner-selector performance ranges, none of those comparisons can certify the end-to-end winner.
Changing the outer router is secondary to evaluating the full pipeline
One useful diagnostic comes from comparing the two decomposed outer selectors. Across all five benchmarks, pairwise-versus-multiclass partition advantages are below 0.005 in absolute value.
Within these experiments, the choice between those outer-routing mechanisms is therefore much smaller than the effect of introducing the real second stage.
The robustness analyses reinforce rather than replace this result. Changing the within-family selector materially changes the gap, as expected, but stronger realistic selectors do not eliminate it. Targeted reruns on the sign-sensitive TabRepo and MAXSAT settings keep the deployment-fidelity gap positive.
This is an important boundary on interpretation. The paper does not claim that every hierarchical architecture is inferior to flat selection. PROTEUS, for example, retains a substantial end-to-end advantage despite losing part of its partition-level lead. The claim is narrower: the partition score is not itself a deployable system score.
Use corrected diagnostics during development, then test what will run
The paper offers two practical responses.
First, a training-side validation estimate of the differential gap can correct the partition comparison:
On the decomposed-versus-flat comparisons for B2 through B5, this reduces mean absolute estimation error by 25% to 88% and recovers the realized point-estimate direction in all four sign-changing cases. TabZilla shows the boundary: correction can overshoot when the true end-to-end difference is small.
Second, the authors train the outer router on cross-fitted deployable family utility rather than oracle family potential. This shrinks the deployment-fidelity gap on every benchmark and improves end-to-end performance on B1 through B4, with a small trade-off on B5.
Cognaptus inference: these are best treated as development and design tools, not substitutes for deployment-faithful evaluation. A benchmarking workflow can use the gap as an escalation signal: when inner-selector regret is large relative to the architectural margin, require a complete end-to-end comparison before promoting a design.
The gap is pipeline-specific, not a universal penalty for hierarchy
The evidence is strong for the evaluation mismatch the paper defines, but its magnitude is not portable as a constant.
The gap depends on the family partition, inner-selector class, feature policy, benchmark, runtime cutoff, and utility transformation. The experiments cover five fixed matrix-style scenarios rather than continuous black-box optimization, and stronger task-specific selectors or more extensive hyperparameter optimization could reduce some observed gaps. The validation correction is also not tested under explicit distribution shift.
So the practical lesson is not to discount every hierarchical score by some standard percentage.
It is to evaluate the system boundary you intend to deploy.
A router followed by a learned selector is one system. A router followed by an oracle is another. If the second one exists only in the benchmark, its score should not decide which architecture goes into production.
Cognaptus: Automate the Present, Incubate the Future.
-
Jiachen Zhang and Yu Tang and Li Zhu (2026). Partition Scores Are Not System Scores: Deployment-Fidelity Gaps in Decomposed Algorithm Selection. arXiv:2609.13785. https://arxiv.org/abs/2609.13785 ↩︎