TL;DR for operators
When a system receives hundreds of thousands of tokens, the expensive part is not only fitting the evidence into memory. It is deciding how much reasoning effort each part deserves. Processing every chunk with the same autoregressive budget preserves more opportunity to use evidence, but it also spends latency and GPU time on material that may never matter.
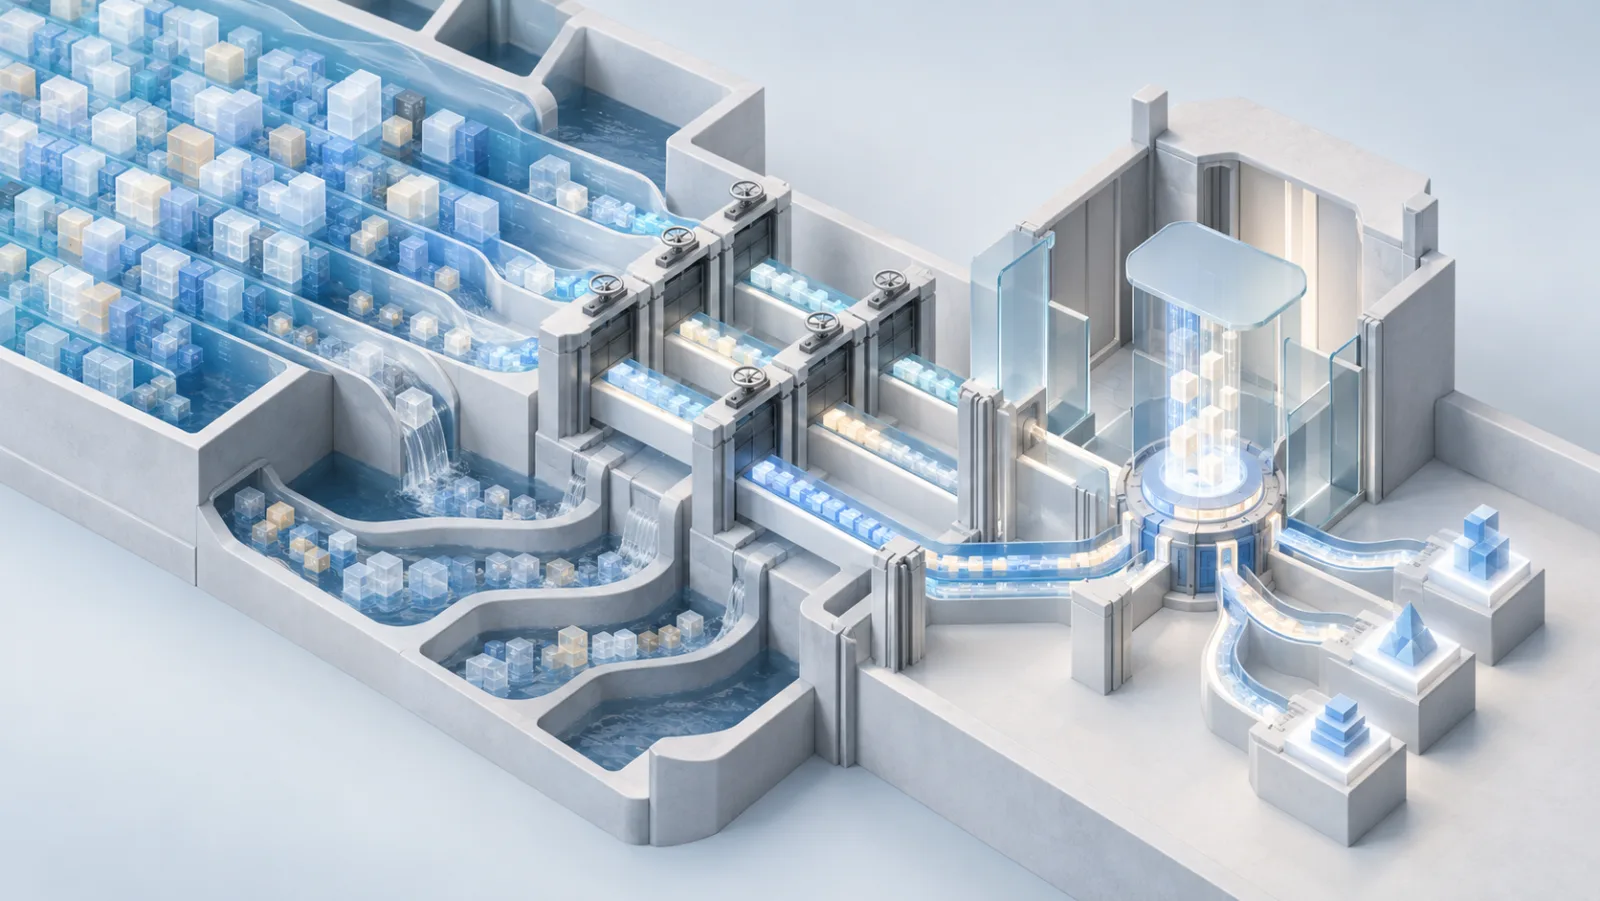
LycheeMemory1 makes that trade-off explicit. It compresses document chunks into smaller latent representations, scans them with a lightweight selector, and performs expensive reasoning only on blocks judged relevant to the query and current intermediate state. In the paper’s 128K efficiency test, the full gated system is reported as 6x faster than MemAgent and 3.5x faster than LycheeMemory without the Gate.
The qualification is central: the Gate buys efficiency, not free accuracy. The no-Gate variant posts stronger QA scores, while aggressive compression and one-pass traversal create distinct fidelity risks. For operators, the paper is best read as a design for allocating inference budget rather than as evidence that every workload should replace retrieval or dense long-context processing.
Long context becomes a reasoning-budget problem
LycheeMemory separates two costs that long-context systems often bundle together: retaining evidence and repeatedly reasoning over it. Documents are split into 4,096-token chunks, then each chunk is converted into a smaller KV-cache-style latent block. A bounded plaintext working state holds intermediate facts and conclusions.
A Gate scores each compressed block using the query plus that evolving state. Only selected blocks trigger the Reasoner, which updates working memory. The Gate still scans blocks linearly; the savings come from making that scan much cheaper than an autoregressive reasoning update and keeping the number of expensive updates small.
That distinction matters for the 1.75M-token result. The system is not densely reasoning over 1.75 million raw tokens. It is chunking, compressing, scanning, selectively recalling, and updating a bounded state.
Retrieval can change after the system learns something
Static retrieval assumes relevance can be judged from the original query. Multi-hop reasoning can violate that assumption: an intermediate fact may introduce an entity that changes which evidence matters.
The paper tests this mechanism under a common top-8 retrieval budget. Query-plus-working-memory gating recalls 86.3% of gold supporting chunks at 112K and 84.1% at 224K. Static embedding retrieval reaches 82.1% and 80.9%; a query-only Gate reaches 76.4% and 74.8%.
This is a mechanism comparison, not the main end-task benchmark. Its purpose is narrower: it supports conditioning retrieval on evolving reasoning state. For production design, that suggests external RAG can narrow a corpus while retrieval within the selected evidence remains dynamic. The paper explicitly treats LycheeMemory as complementary to RAG.
The speedup is purchased with selective omission
The main benchmark shows the cost of gating. At 112K, gated LycheeMemory-7B scores 75.78 normalized sub-EM, versus 80.47 without the Gate. At 1.75M, the scores are 71.09 and 78.12. The full system remains competitive while gaining speed, but the higher-accuracy variant performs more reasoning.
Compression creates a second control surface. In the compression-ratio sensitivity test, 2x and 4x compression preserve above 80% accuracy through 128K, while 16x falls from 71.5% at 2K to 42.0% at 128K. The manual failure analysis links aggressive compression to feature collapse and attribute-binding hallucinations.
| Control surface | Paper evidence | Operational meaning | Boundary |
|---|---|---|---|
| Gate | Lower latency, lower accuracy than no-Gate | Trade Reasoner calls for throughput | Needed evidence may be skipped |
| Compression | Moderate ratios hold up better than 16x | Trade memory footprint for fidelity | Aggressive compression can merge attributes |
| Working memory | Larger capacity does not monotonically improve scores | More state is not automatically better | Bounded state can overflow or anchor errors |
Joint training makes compression task-aware
LycheeMemory trains the Compressor and Reasoner jointly with end-to-end reinforcement learning, while the Gate is trained separately as a classifier. The staged-optimization ablation tests whether that coupling matters.
On the 3B model at 16K, supervised fine-tuning reaches 59.38 average sub-EM, non-joint RL reaches 66.80, and end-to-end RL reaches 68.75. The likely purpose of this ablation is not to establish RL as universally superior, but to show that final-task reward can improve the representation-and-reasoning pipeline when both are optimized together.
For business use, the implication is conditional: if compressed memory becomes part of a reasoning stack, optimizing it only for reconstruction may preserve information differently from what the downstream task needs. This paper provides benchmark evidence for task-aware joint optimization, not a universal training prescription.
One-pass memory creates a structural failure mode
LycheeMemory scans memory in one direction. If an early block is skipped and a later block introduces the bridge entity that would have made it relevant, the system cannot go back.
In the paper’s manual analysis of 128 incorrect cases, about 35% are attributed to this unidirectional dependency mismatch. Premature inference anchoring accounts for about 21%, compression-induced hallucination for 17%, and other causes—including context overflow and instruction misalignment—for 27%.
That failure taxonomy points to concrete controls for consequential deployments: permit revisitation when evidence order matters, validate final answers against source evidence, and monitor compression settings. Storage also remains material at extreme length: the paper estimates about 18.1 GB for a 1.75M-token Qwen2.5-3B context at 4x compression.
What operators can carry into production
What the paper directly shows: in its QA-heavy evaluation, compressed long-term memory plus selective state-dependent reasoning can extrapolate to very long contexts, reduce inference cost materially, and retain competitive accuracy. Retrieval and optimization ablations support the proposed mechanisms.
What Cognaptus infers: assistants working over long reports, case histories, logs, or document bundles can treat reasoning effort as a serving control. A layered system could combine external retrieval, moderate compression, state-dependent gating, and source validation rather than processing every available chunk equally.
What remains uncertain: the evidence is concentrated in multi-hop QA, with zero-shot checks on 2WikiMultihopQA, StreamingQA, and two LongBench summarization tasks. That supports LycheeMemory as a credible design option, not universal superiority across enterprise workloads.
The operational shift is simple: long context is not only a capacity problem. Once storage and reasoning are separated, latency, GPU memory, and fidelity become measurable allocation choices.
Cognaptus: Automate the Present, Incubate the Future.
-
Zhuoen Chen and Dongfang Li and Meishan Zhang and Baotian Hu and Min Zhang (2026). Dynamic Long Context Reasoning over Compressed Memory via End-to-End Reinforcement Learning. arXiv:2602.08382. https://arxiv.org/abs/2602.08382 ↩︎