Cover image

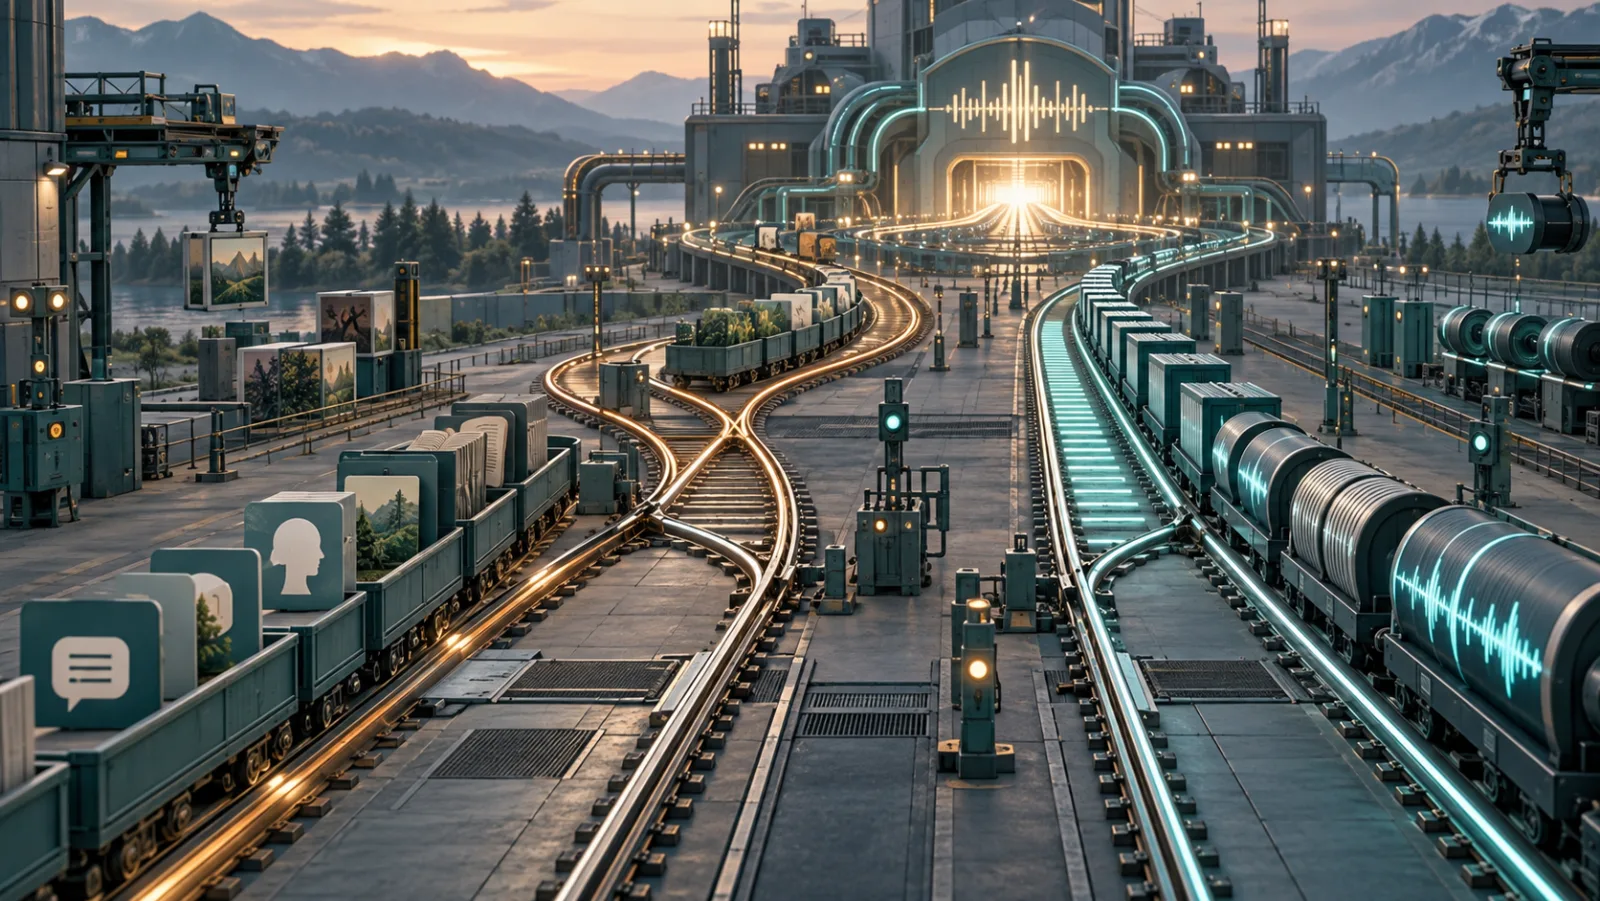
One Model, Two Routes: Why Audio-Omni Unifies Audio by Splitting Its Controls

TL;DR for operators A product that must understand an instruction, preserve a voice or reference sound, and stay synchronized with video is handling several different kinds of control. Audio-Omni’s strongest architectural evidence says those controls should not be forced through the same interface. The system combines a frozen multimodal language model with a trainable audio generator. High-level meaning and transcript information are supplied as flexible context; synchronization and acoustic-reference information are attached directly to the evolving audio representation. In the paper’s conditioning ablation, that allocation performs best across text-to-audio, video-to-audio, text-to-speech, and audio editing. ...
September 14, 2026 · 9 min · Zelina
Cover image

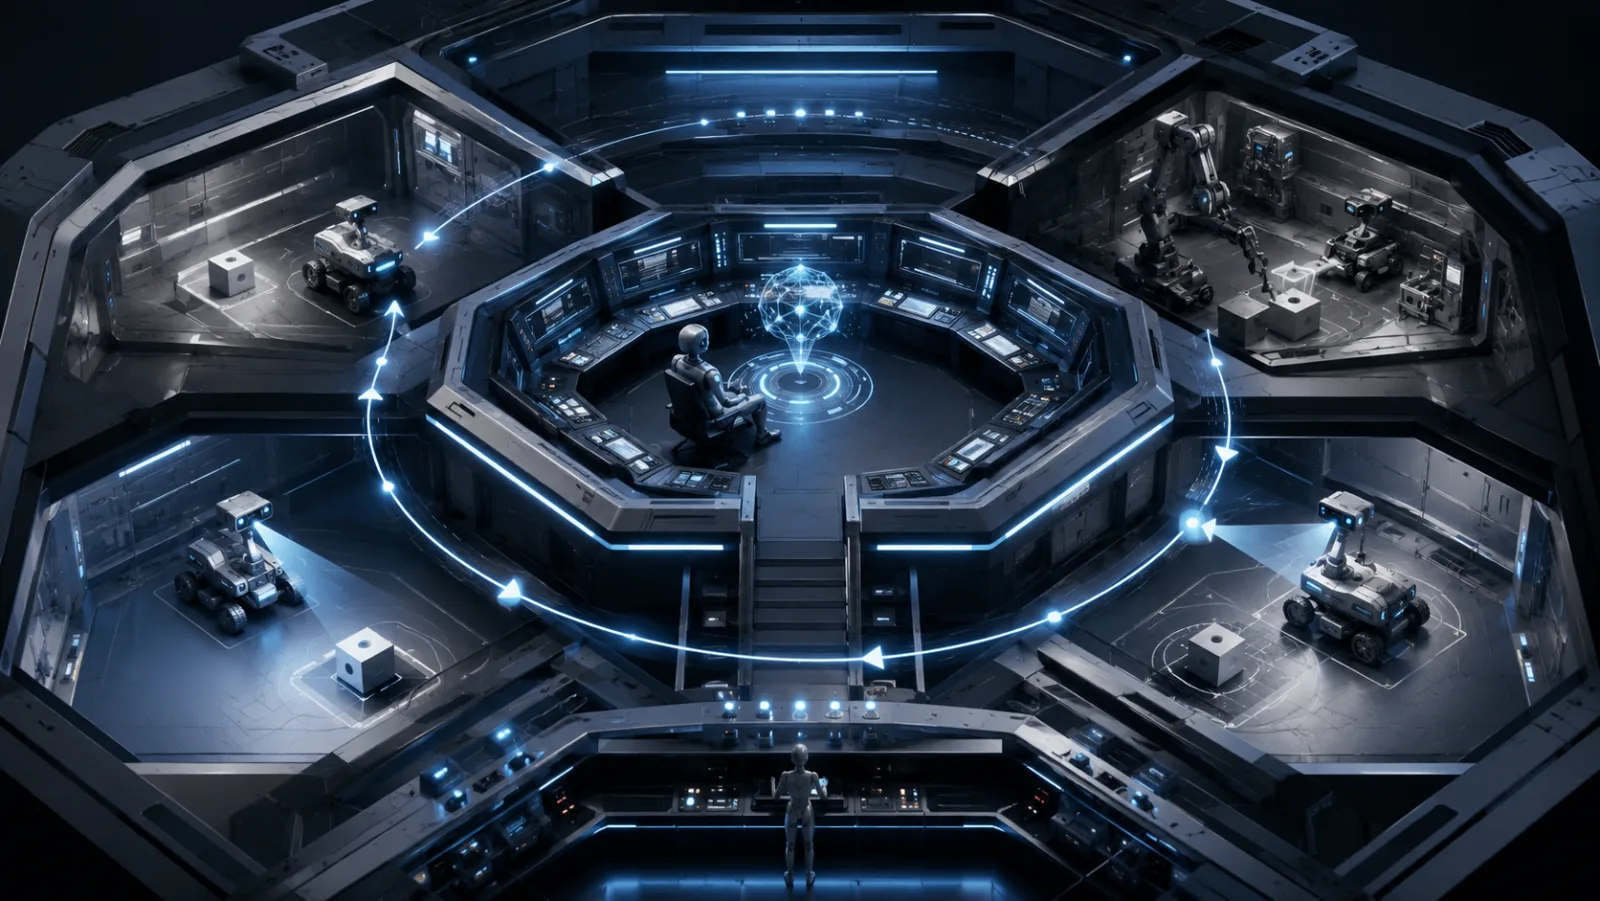
The Robot Looked Back: What GPT-5.1’s First Body Actually Shows

TL;DR for operators The most revealing moment in this study is not that GPT-5.1 moved a robot toward a plush penguin. After the robot struck the target, the model reversed to regain visual perspective, saw that the penguin was still upright, commanded another strike, then reversed again to verify the result. That sequence suggests something more operationally relevant than one-shot visual command generation: the controller retained a task state across several actions, interpreted the likely consequence of a collision, gathered new evidence, and corrected its plan. ...

September 7, 2026 · 7 min · Zelina
Cover image

The Leaderboard Is Not a Clinical Clearance

TL;DR for operators A healthcare team choosing a model, configuration, and safeguards for diagnostic support should treat leaderboard leadership as evidence of capability—not proof of clinical readiness. GPT-5-medium led ClinMM-Bench, yet produced a completely correct diagnosis in only 33.88% of cases. The benchmark tests a difficult but essential requirement: combining clinical details and images as evidence unfolds, revising earlier conclusions, and explaining a diagnosis without omitting decisive information or introducing unsupported claims. Medical specialization and explicit reasoning settings do not improve these abilities consistently across model scales, metrics, or specialties. ...

August 6, 2026 · 8 min · Zelina
Cover image

When One Patch Rules Them All: Teaching MLLMs to See What Isn’t There

Image security has an awkward habit of sounding theoretical until the image is inside a business workflow. A product team adds an image-upload feature. A compliance team uses multimodal models to inspect screenshots. A support bot reads photos from customers. A research assistant summarizes figures from PDFs. Everyone understands that the model may occasionally misread an image. That is ordinary error. Annoying, but ordinary. ...

February 3, 2026 · 15 min · Zelina
Cover image

MemCtrl: Teaching Small Models What *Not* to Remember

MemCtrl: Teaching Small Models What Not to Remember A robot assistant walks through a room. It sees a chair from the front. Then from the side. Then from a slightly worse angle. Then the same chair again, because the camera moved while the robot hesitated. In theory, all of this is “context.” In practice, it is mostly noise wearing a productivity badge. ...

January 31, 2026 · 14 min · Zelina
Cover image

RxnBench: Reading Chemistry Like a Human (Turns Out That’s Hard)

A reaction scheme looks like a picture. To a chemist, it is closer to a compressed process model. A few arrows may encode the starting materials, catalysts, solvents, temperatures, intermediate states, selectivity, yield, and the structural change that makes the entire experiment worth publishing. Reading that scheme correctly is already difficult. Reading the paper around it is worse. ...

December 31, 2025 · 15 min · Zelina
Cover image

RL Grows a Third Dimension: Why Text-to-3D Finally Needs Reasoning

A chair is not a picture of a chair. That sounds obvious until a text-to-3D system forgets the backrest from one angle, gives the chair three legs from another, paints the seat correctly, and somehow convinces a weak evaluator that the job is mostly done. In 2D generation, a model can often survive by producing a plausible view. In 3D generation, every view is a witness. Geometry, texture, object parts, and spatial relationships all have to agree. Annoying, yes. Also the entire point. ...

December 13, 2025 · 16 min · Zelina