Cover image

You Cannot Retrieve What Was Never Stored

TL;DR for operators An AI assistant cannot retrieve information that its memory-writing process failed to preserve. In a controlled study of Self-Keyed In-Parameter Memorization (Skim), 44 of 59 failed recall attempts involved missing or incorrectly selected answer spans, while none were attributed to retrieval routing. The method achieved 63.1% mean recall across five language models storing 32 non-numeric dialogue facts without an external conversation store at inference.1 ...
November 10, 2026 · 9 min · Zelina
Cover image

Reading Between the Generated Lines: What AI Emotion Scores Really Measure

TL;DR for operators A conversational AI assistant may correctly identify a character’s emotions in a benchmark while remaining unreliable when a customer expresses frustration or concern indirectly. In ToMStories, the strongest open-weight model achieves 88.4% multiple-choice accuracy, above a small human baseline of 80.3%. Yet the highest model score on open-ended questions is 58.6%, below the human baseline of 64.2%. ...

November 1, 2026 · 8 min · Zelina
Cover image

Relevant History, Missing Rules: The Retrieval Risk in AI Assistants

TL;DR for operators An AI assistant can retrieve conversation history more efficiently and become less reliable at following instructions. The critical distinction is between standing rules that remain binding and past exchanges whose relevance changes with each question. Role-aware Heuristic Episodic Attention (REA) addresses both requirements through separate instruction and episodic memories. In its experiments, the complete architecture improves long-conversation quality while substantially reducing response latency. Yet removing the dedicated instruction memory causes instruction adherence to deteriorate sharply when similarity-based retrieval is introduced. ...

October 31, 2026 · 9 min · Zelina
Cover image

Memory Has a Budget: Compress Long-Running Context by Value, Not Age

TL;DR for operators Fofadiya and Tiwari propose a context-management system for long-running LLM interactions that does more than summarize old conversations.1 It scores historical turns by relevance, recency, dialogue dependency, and coherence, then applies a three-level policy: retain high-value turns verbatim, summarize medium-value turns, and remove low-value history when the context budget requires it. ...

September 19, 2026 · 6 min · Zelina
Cover image

Global Context Is Not the Same as Affective Context

TL;DR for operators Conversation history helps emotion recognition, but this paper shows that having the whole conversation available is not the same as extracting the affective signal that persists across it. Using the same frozen RoBERTa utterance representations, a structured atmosphere prior scores 71.29 versus 67.86 on IEMOCAP and 69.22 versus 63.63 on MELD; it also improves EmoryNLP and DailyDialog. AtmosERC then reuses that prior inside a lightweight classifier, while a prompt-level variant converts it into a textual cue for LLMs. The lightweight model leads reported baselines on three of four datasets, and the LLM cue improves all three tested general-purpose LLMs on both evaluated datasets. ...

August 29, 2026 · 7 min · Zelina
Cover image

Vision Helps, but Context Decides: What Repair Detection Reveals About Multimodal Conversational AI

TL;DR for operators A conversational system can hear the user’s words correctly and still miss that the exchange has broken down. A glance, facial change, posture shift, or gesture may signal that the other person did not understand and needs clarification. The study tests whether adding those visible behaviors to text and audio improves recognition of these breakdown signals, known as Other-Initiated Repair (OIR). It does in both evaluated corpora. On a performance measure that gives each repair class equal weight (macro-F1), adding the visual branch improves both OIR detection and repair-type classification over the text-plus-audio baseline.1 ...

August 12, 2026 · 7 min · Zelina
Cover image

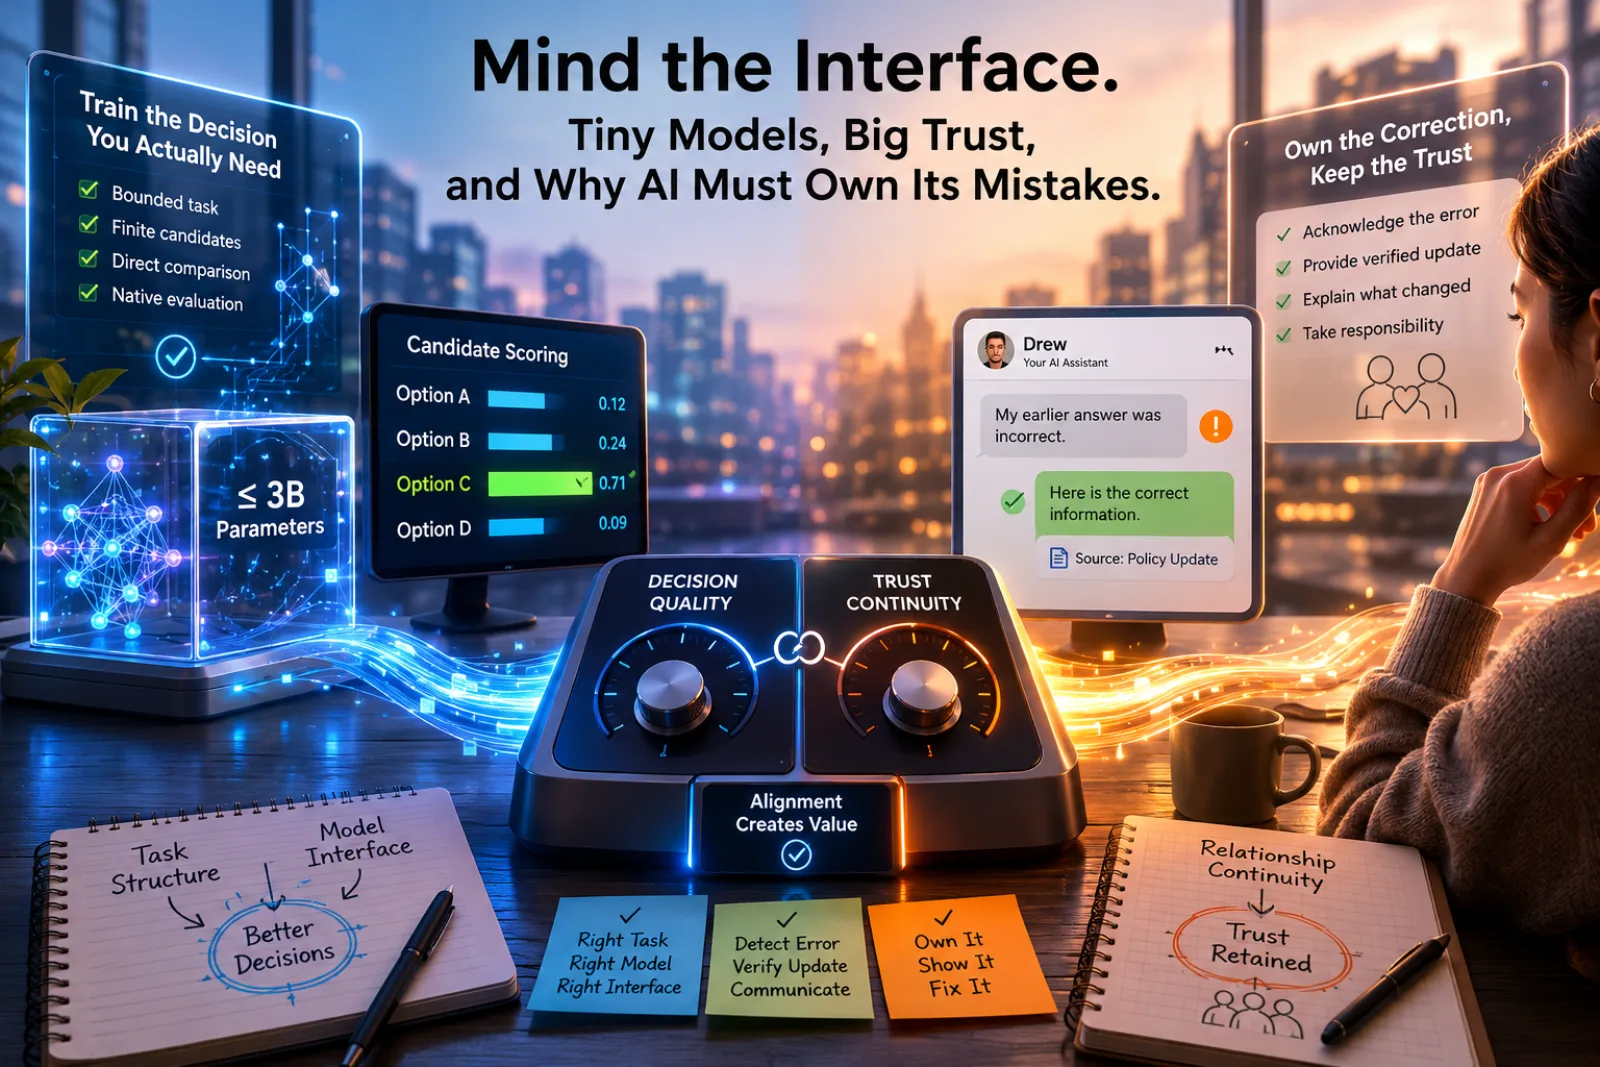
Mind the Interface: Tiny Models, Big Trust, and Why AI Must Own Its Mistakes

TL;DR for operators Small models are not necessarily as incapable as their standard evaluations make them look. On bounded tasks, the wrong training and scoring interface can conceal useful capability. A correct retraction is not necessarily a successful recovery. Users may accept the correction while losing confidence in the agent that created the problem. The two papers imply a full-stack rule: train the system through the interface that matches the decision, then repair errors through the agent that owns the relationship. Backend specialization and frontend continuity are compatible. An expert model can verify the correction, but the original user-facing agent should acknowledge and communicate it. Evaluation should measure both sides of reliability: whether the system gets the decision right and what happens to user trust when it does not. The model is not the whole system AI deployment discussions still have an unfortunate habit of treating model capability as if it were a fluid stored inside a parameter tank. Larger tank, more intelligence. Smaller tank, less intelligence. Procurement can then proceed by comparing benchmark columns and invoices. ...

July 20, 2026 · 19 min · Zelina
Cover image

The Art of Interrupting AI: When Knowing Isn’t Talking

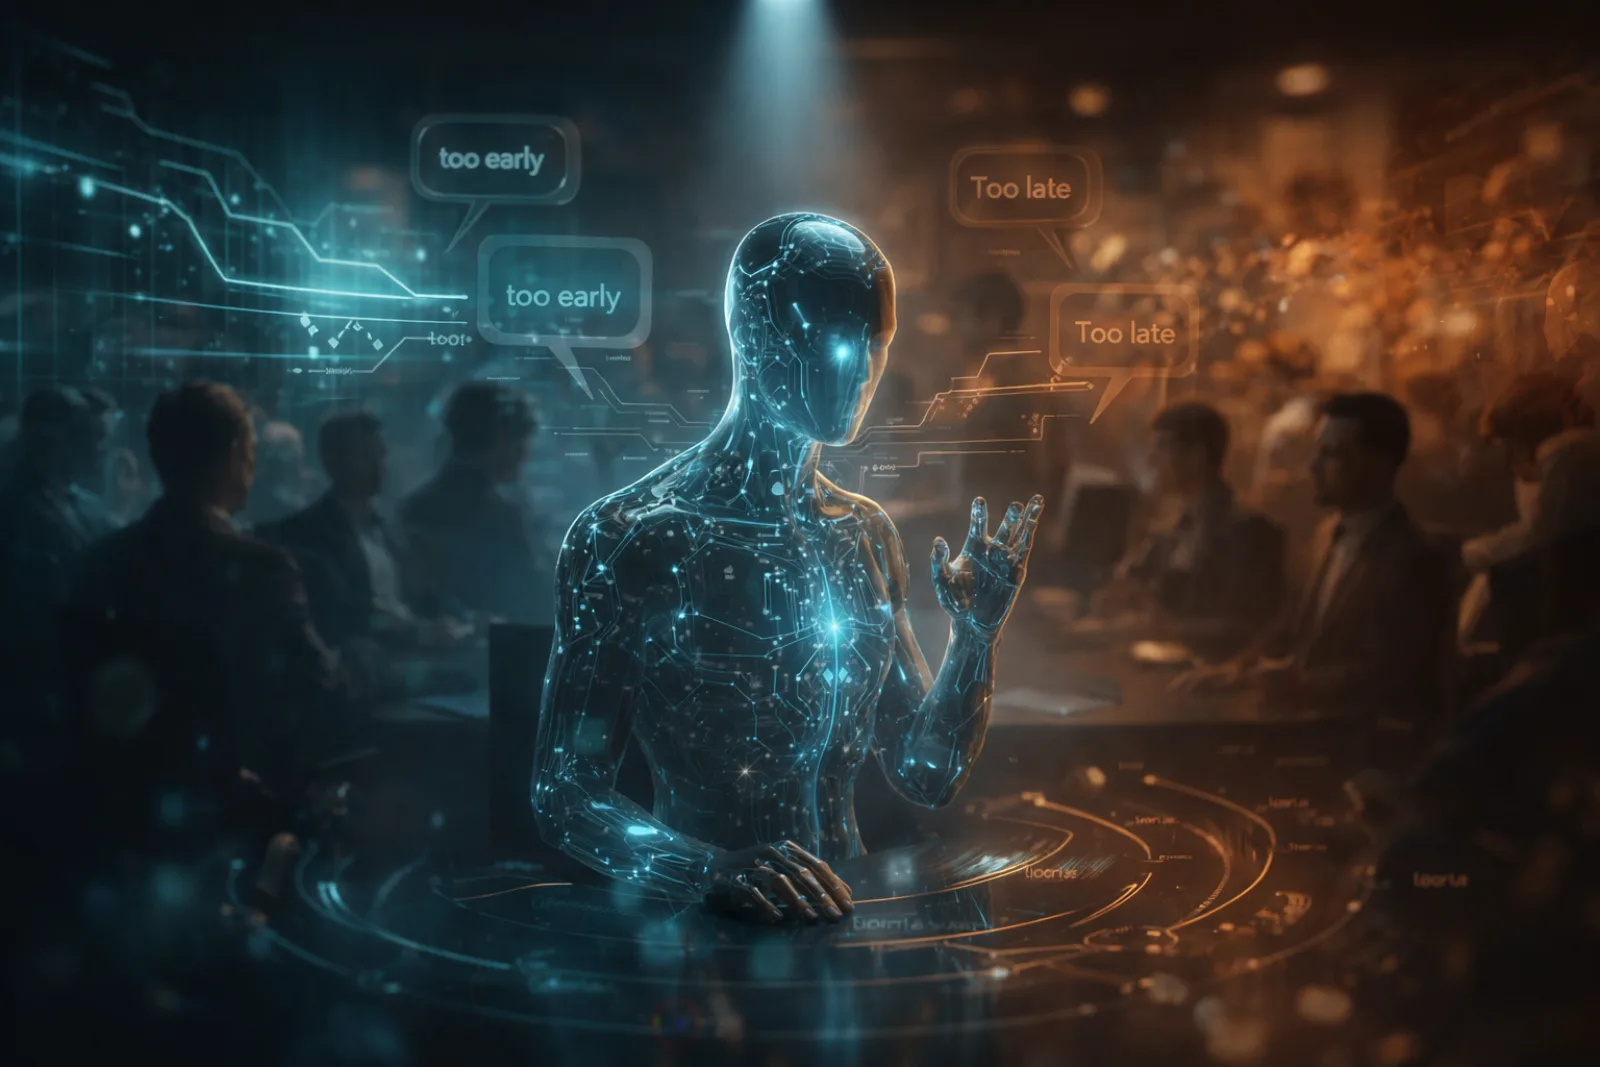
The meeting-room test AI still fails Meeting rooms are unforgiving places for intelligence. A person can know the topic, understand the slides, recognize every face around the table, and still be a terrible participant. Speak too early, and they interrupt. Speak too late, and the moment has passed. Say something factually relevant but socially tone-deaf, and the room quietly deducts points. No spreadsheet records this. Everyone notices anyway. ...

March 18, 2026 · 15 min · Zelina
Cover image

The Long Conversation Problem: How MAPO Teaches AI to Care Over Time

Customer support has a familiar failure mode: the first answer sounds polished, the second answer sounds patient, the third answer sounds as if the system has quietly forgotten what problem it is solving. The user is still there. The emotional state has changed. The unresolved issue has shifted. The model, meanwhile, keeps producing individually acceptable replies, like a waiter bringing one beautifully plated dish at a time to the wrong table. ...

March 10, 2026 · 14 min · Zelina
Cover image

Grid Chat: When Your Battery Negotiates With the Power Market

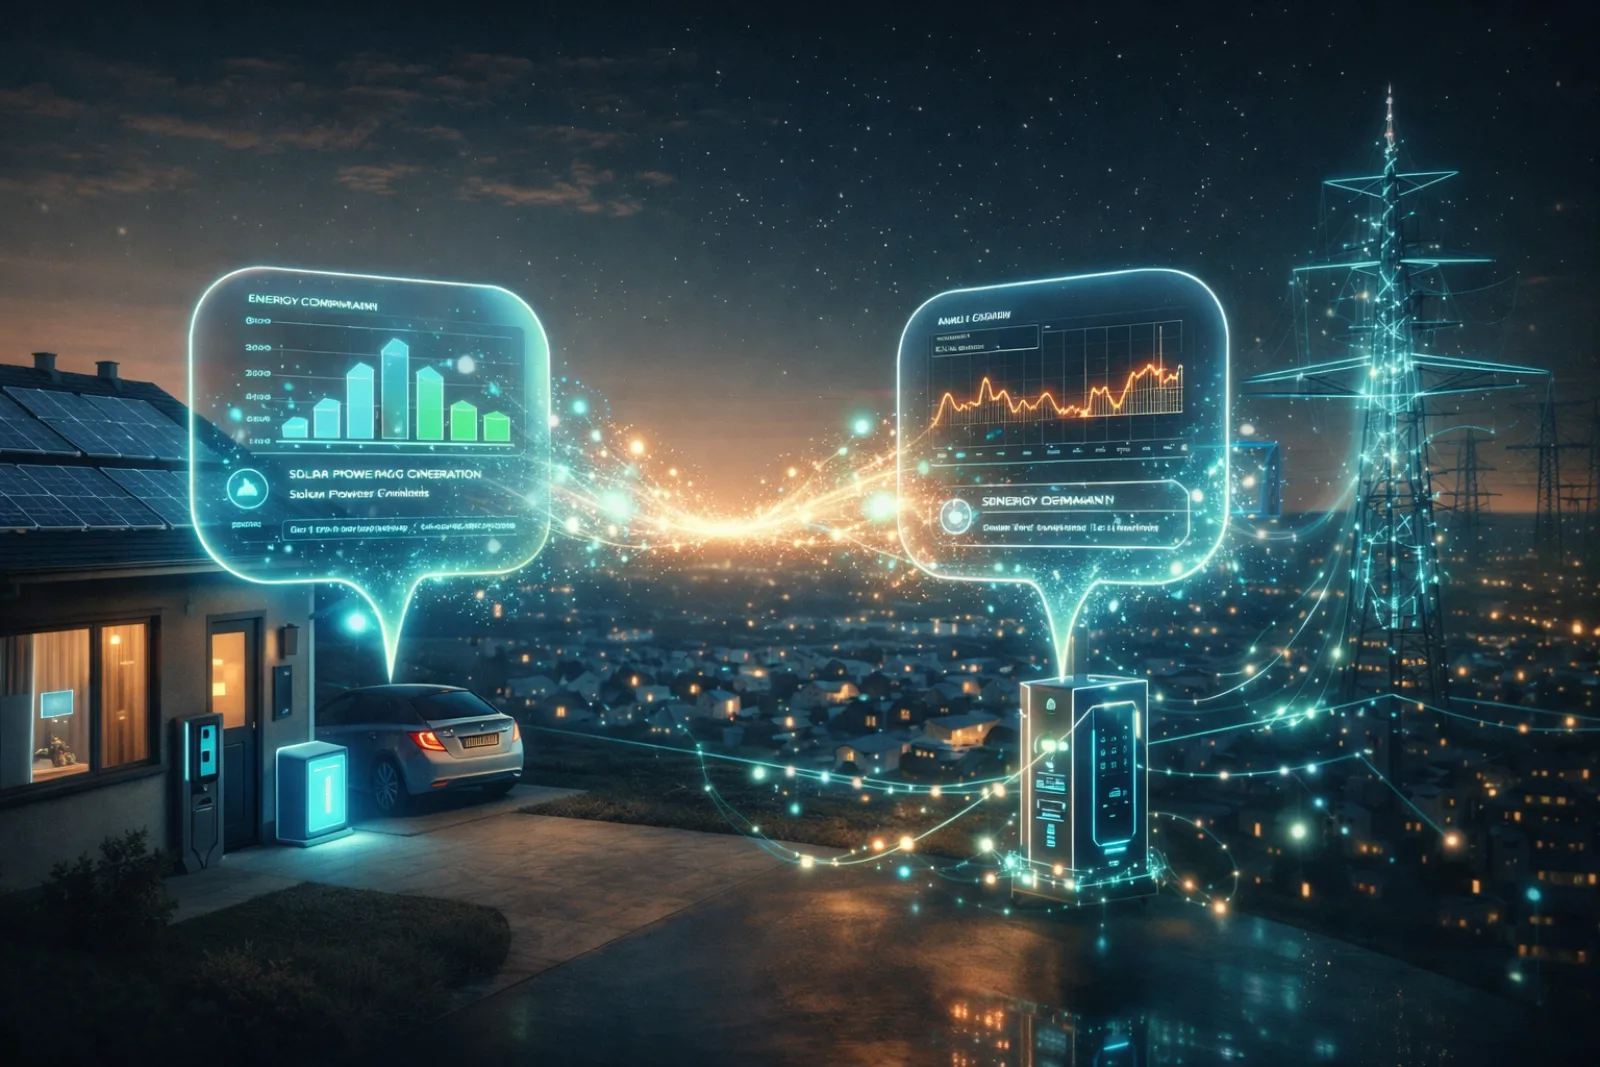
Battery. At 5 p.m., the grid wants help. The evening peak is approaching, the aggregator needs 3 kW of flexibility between 17:00 and 19:00, and one household in the portfolio looks promising. In the old demand-response world, this might become a price alert, an app notification, or a silent automated command. The household either complies, ignores it, or discovers later that the “smart” system has made a decision that feels less smart when dinner, laundry, or comfort is involved. ...

March 9, 2026 · 15 min · Zelina