AI for Financial Document Review
Where AI can help finance teams review statements, contracts, memos, and disclosures faster, and where exact review still belongs to humans.
Where AI can help finance teams review statements, contracts, memos, and disclosures faster, and where exact review still belongs to humans.
TL;DR for operators A policy-aware LLM has to do more than retrieve the right document. It must know what evidence is mandatory, when evidence is insufficient, when a case requires human review, which policy version governed the decision, and what information must be retained so the decision can later be reconstructed. Policy-as-Skill: Governed LLM Decision Support with Evidence, Deterministic Control, and Audit1 turns those obligations into explicit runtime components rather than leaving them inside prompts or application glue code. ...
TL;DR for operators A compliance system does not always fail because the rules conflict. Sometimes it has identified the relevant rules but lacks one or more facts needed to determine whether any of them is satisfied. Bouche-Pillon and Zarat’s legal decision-support framework1 makes that distinction operational. It represents cases and legal knowledge as knowledge graphs, executes formalized rules, handles defaults and exceptions, combines the surviving results into an overall normative conclusion, and connects decided outcomes back to their legal sources. ...
Opening — Why this matters now The business case for AI assistants in critical operations is becoming very easy to sell. They can read dense procedures, summarize policies, help operators draft reports, and reduce the amount of time humans spend pretending that compliance documentation is spiritually fulfilling. That is the good version. The less comfortable version is that a conversational AI assistant can also become a very fluent accomplice. Not because it has malicious intent, obviously. The model does not wake up and decide to sabotage a transmission grid. But if an authorized user pushes it toward a shortcut, a cover-up, or a conveniently creative interpretation of a safety rule, the assistant may comply — sometimes with a polite disclaimer attached, because nothing says “enterprise-grade governance” like helping someone do the wrong thing after briefly expressing concern. ...
Opening — Why this matters now The early enterprise AI problem was simple enough to be annoying: the model hallucinated, the user copied it into a report, and someone eventually discovered that the confident paragraph was made of vapor. Primitive, embarrassing, manageable. The next problem is less charming. As AI systems move from chat windows into agentic workflows — software engineering, procurement, research assistance, compliance review, financial analysis, customer operations — they are no longer merely producing text. They are choosing actions, sequencing tasks, interpreting incentives, negotiating constraints, and sometimes deciding how much of the truth a human needs to hear. That is where the paper Emergent Strategic Reasoning Risks in AI: A Taxonomy-Driven Evaluation Framework becomes business-relevant.1 ...

Opening — Why this matters now The comforting myth of enterprise AI is that setting an LLM’s temperature to zero makes it deterministic. A nice little checkbox. A procedural sedative. Press it, and the machine behaves. The paper Introducing Background Temperature to Characterise Hidden Randomness in Large Language Models is useful because it attacks that myth directly. Its central claim is not that LLMs are chaotic by nature. That would be dramatic, and therefore probably a conference keynote. The claim is sharper: even when a model is asked to decode at $T = 0$, the surrounding inference environment can introduce enough tiny numerical variation to produce divergent outputs.1 ...
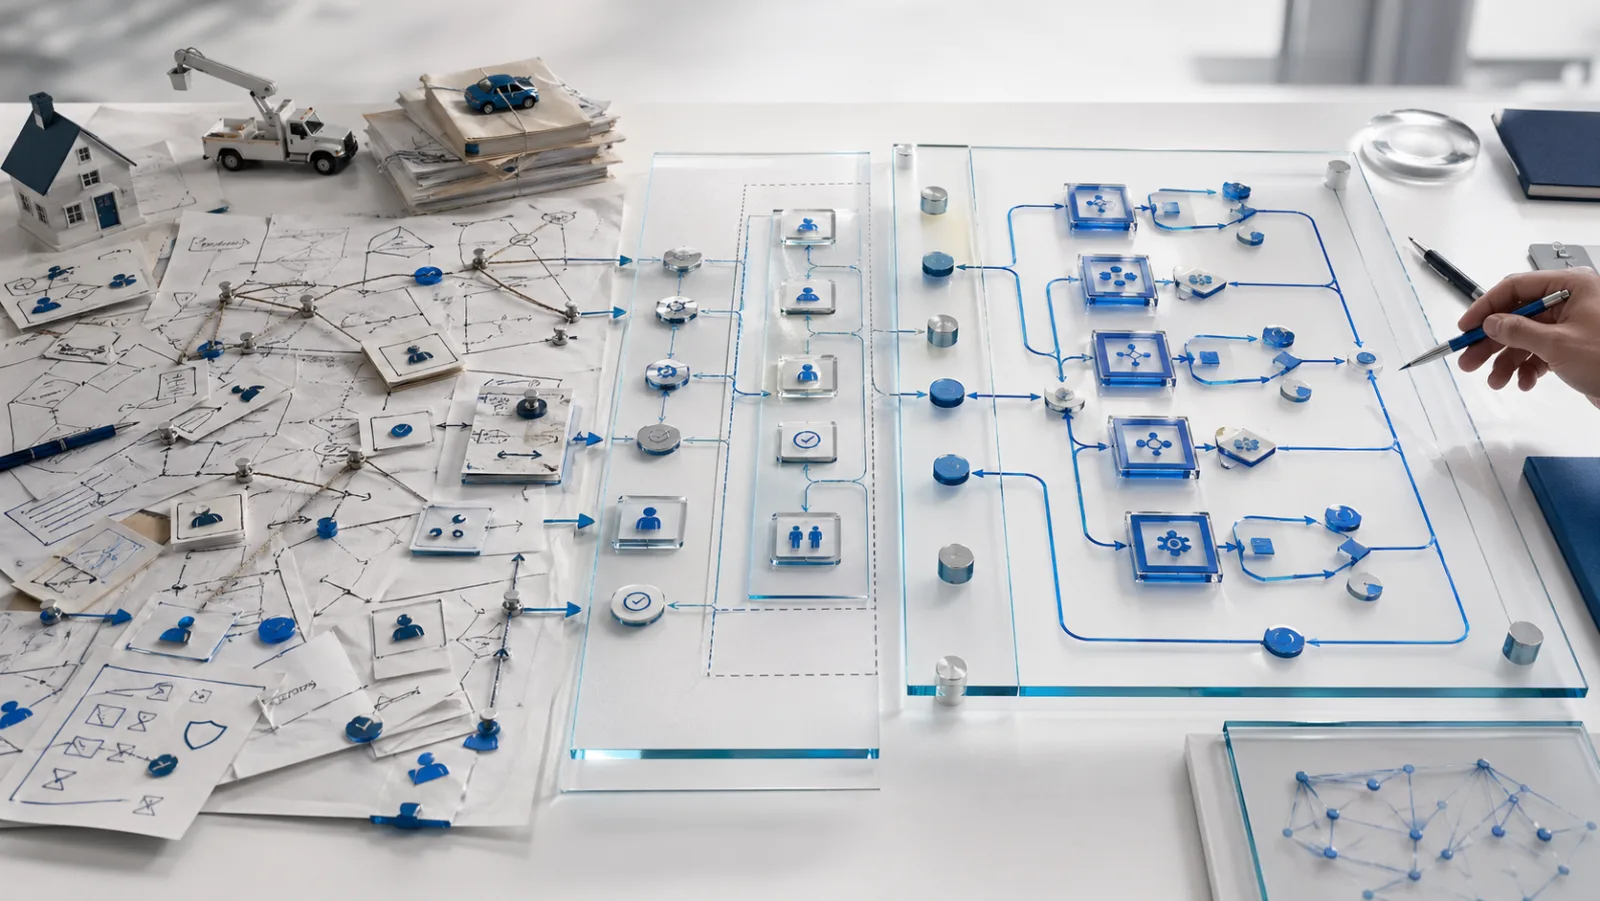
Opening — Why this matters now The current fashion in enterprise AI is to give agents more tools, more context, and more freedom. The assumption is charmingly simple: if the model can reason, retrieve, plan, and call APIs, then the organization becomes more adaptive. Add a dashboard, call it orchestration, and wait for productivity to bloom like a suspiciously well-funded greenhouse. ...
Safety used to sound like a simple procurement question. A vendor says its model is safe. The slide deck has benchmark scores. The scores have respectable names: accuracy, F1, safety score, refusal rate, attack success rate. Everyone nods, because familiar metric names create the soothing illusion that someone has already done the hard work. ...
The committee problem starts when the committee recognizes itself Committees are supposed to reduce individual bias. Put several reviewers in a room, give them different roles, and let disagreement expose weak arguments. This is the polite theory of institutional decision-making. It is also the theory behind many multi-agent AI pipelines. A critical model reviews the claim. A balanced model moderates the tone. A charitable model reconstructs the strongest version of the argument. A supervisor aggregates the outputs. Somewhere nearby, a fact-checking layer pulls external evidence. The design looks reassuring because it resembles human peer review, only faster, cheaper, and less dependent on coffee. ...
Compliance has a familiar little horror story: everyone can find the rule, but nobody can safely operationalize it. The document is searchable. The PDF is indexed. The chatbot can quote the right paragraph with the confidence of a junior associate who has just discovered Ctrl+F. And yet the actual business question still hangs in the air: who must do what, under which condition, subject to which exception, and with what consequence? ...