Cover image

Benchmarks That Fight Back: Adaptive Testing for LMs

A benchmark is supposed to be a measuring instrument. In practice, many AI benchmarks behave more like a tired clipboard. Every model gets the same questions. Every question receives the same accounting treatment. The final score is usually a mean accuracy number, neat enough for a leaderboard and blunt enough to hide the messy truth underneath. Some items are too easy to tell strong models apart. Some are too hard to tell weak models apart. Some are mislabeled. Some have stopped mattering because everyone competent now solves them. Yet the ritual continues: run the suite, average the answers, update the chart, pretend the thermometer is not melting. ...
September 20, 2025 · 17 min · Zelina
Cover image

Confidence, Not Confidence Tricks: Statistical Guardrails for Generative AI

A product team launches an AI assistant. The demo works. The benchmark looks respectable. The model even says “I’m confident” with the serene authority of a consultant who has never owned a pager. Then the real users arrive. Some ask ambiguous questions. Some ask adversarial questions. Some ask perfectly normal questions that happen to sit outside the model’s competence. The assistant still answers. Sometimes it refuses too often. Sometimes it refuses too late. Sometimes its confidence score is less a forecast and more a decorative sticker. ...

September 13, 2025 · 14 min · Zelina
Cover image

From Prompts to Policies: The Agentic RL Playbook

A chatbot can answer a question. An agent has to do something after the answer stops being enough. That distinction sounds obvious until a system must browse, click, call an API, write code, inspect an error, remember what it tried, and decide whether another attempt is worth the cost. At that point, “better prompting” becomes the AI equivalent of telling a logistics team to be more mindful while the warehouse is on fire. Pleasant, perhaps. Not a control system. ...

September 4, 2025 · 15 min · Zelina
Cover image

From Chat Logs to Goal Logs: OnGoal’s Playbook for Goal‑Truthful LLMs

TL;DR for operators OnGoal is not another attempt to make the chatbot magically “understand intent”. That would be adorable, and also not the paper. It is a goal-observability interface: a way to show users which goals the system thinks are active, how those goals change over a conversation, and whether each model response appears to confirm, contradict, or ignore them.1 ...

August 31, 2025 · 16 min · Zelina
Cover image

Benchmarks with Benefits: What DeepScholar-Bench Really Measures

TL;DR for operators DeepScholar-Bench is useful because it turns “deep research” from a demo category into a measurable workflow: retrieve the right sources, synthesize the right facts, and attach citations that actually support the claims.1 The headline result is not flattering. No evaluated system exceeds a 31% geometric mean across all metrics. OpenAI DeepResearch leads overall with a 0.309 geometric mean, but its best-looking strengths hide serious gaps: 0.857 on organization, 0.392 on nugget coverage, 0.187 on reference coverage, and 0.124 on document importance. Translation: the report may read well while still missing the intellectual furniture. ...

August 30, 2025 · 14 min · Zelina
Cover image

Judge, Jury, and Chain‑of‑Thought: Making Models StepWiser

TL;DR for operators StepWiser is a judge for multi-step reasoning systems. Its practical claim is simple: do not wait until the final answer is wrong before discovering that the model fell off a cliff three paragraphs earlier. The paper turns process supervision into a three-part mechanism. First, the solver is taught to divide its reasoning into coherent “chunks-of-thought” rather than arbitrary line breaks. Second, each chunk is labelled by estimating whether continuing after that chunk improves or harms the probability of eventually reaching a correct answer. Third, a separate judge is trained with online reinforcement learning to reason about each chunk before deciding whether it is valid.1 ...

August 27, 2025 · 18 min · Zelina
Cover image

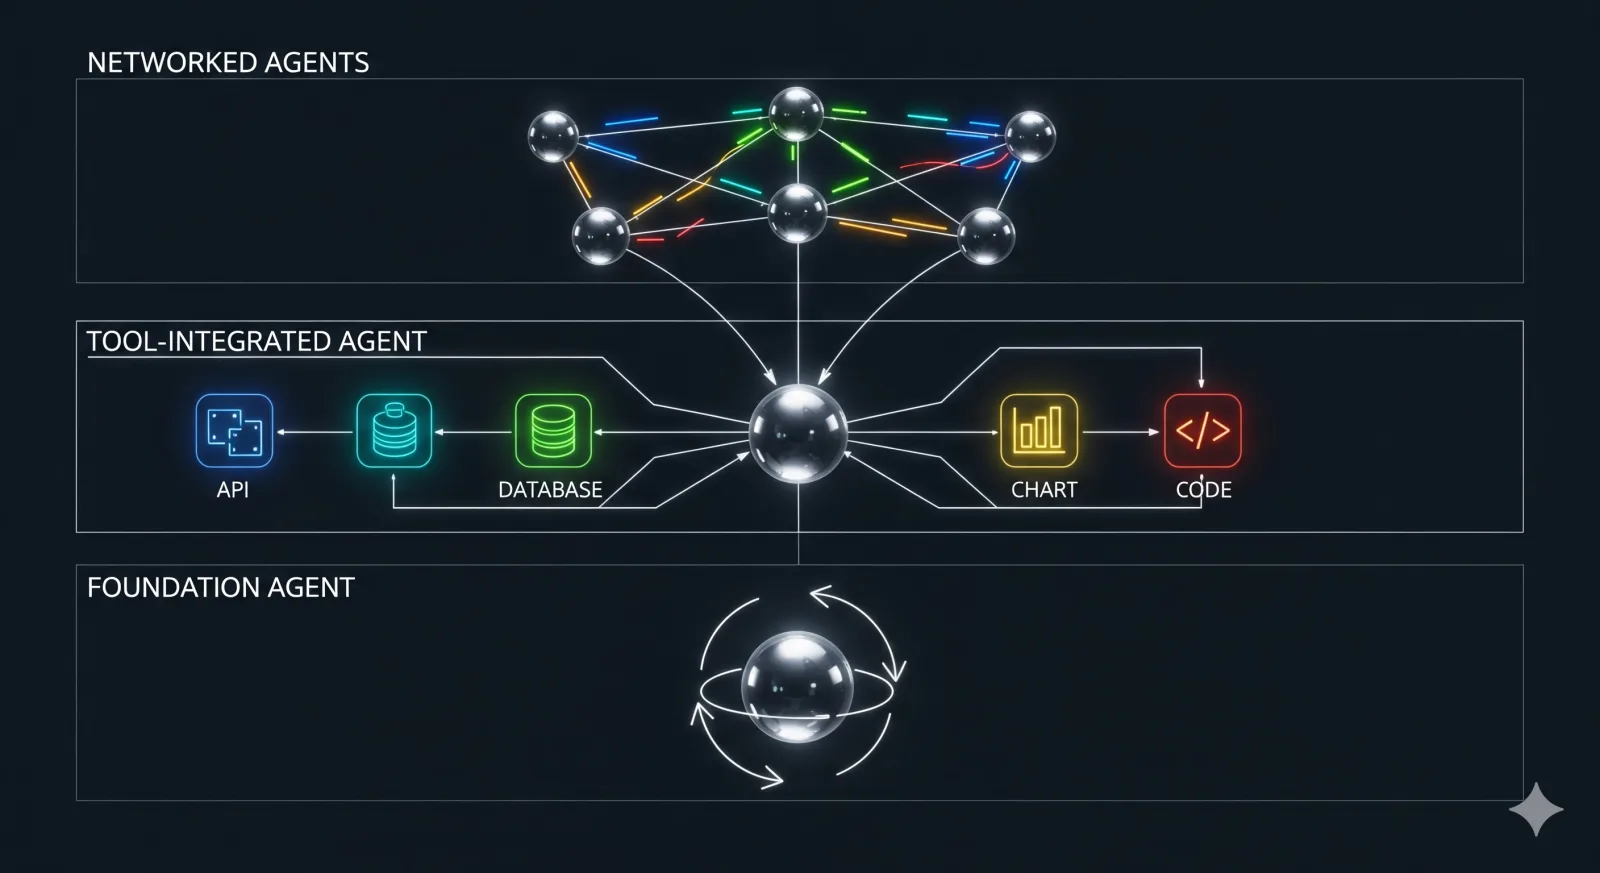
Agents on the Clock: Turning a 3‑Layer Taxonomy into a Build‑Ready Playbook

TL;DR for operators Most agent projects fail in a wonderfully unglamorous place: not at “intelligence”, but at the loop. The agent forgets what it already did. It calls the wrong tool. It reflects poetically instead of usefully. It delegates to three other agents because the demo looked impressive, then spends the next minute staging a management retreat in token form. Charming, but not production. ...

August 26, 2025 · 15 min · Zelina
Cover image

Atom by Atom, Better Research: How Fine-Grained Rewards Make Agentic Search Smarter

TL;DR for operators Research agents fail in a very familiar way: they do several useful things, then make one bad final move, and the training signal treats the whole journey as garbage. Delightful. Efficient. Totally not a credit-assignment problem wearing a lab coat. Atom-Searcher attacks that problem by splitting an agent’s reasoning trace into Atomic Thoughts: small, functional reasoning units such as planning, verification, hypothesis testing, observation, action selection, or risk analysis. A Reasoning Reward Model then scores those units, producing an Atomic Thought Reward that is blended with the final-answer reward during reinforcement learning.1 ...

August 19, 2025 · 14 min · Zelina
Cover image

Crystal Ball, Meet Cron Job: What FutureX Reveals About ‘Live’ Forecasting Agents

TL;DR for operators FutureX is less interesting as a leaderboard and more interesting as an operating model for evaluating AI agents that claim to forecast the future. The benchmark runs a live loop: collect future-facing questions from curated web sources, ask agents to predict before the answer exists, wait for resolution, crawl the answer, and score the prior prediction. That matters because most “forecasting” evaluations are either historical backtests with leakage risk or static datasets quietly ageing into trivia. ...

August 19, 2025 · 13 min · Zelina
Cover image

From Ballots to Budgets: Can LLMs Be Trusted as Social Planners?

TL;DR for operators This paper asks a deceptively operational question: can an LLM act as a social planner when it must allocate a fixed budget across competing public projects? Not in the inspirational LinkedIn sense. In the literal sense: choose project IDs, stay within budget, maximise community utility, and return a valid allocation. ...

August 11, 2025 · 20 min · Zelina