From Laundry Schedules to a Governed Operating Loop

A regional textile-rental operator redesigns its end-to-end service cycle around six coordinated agents, replacing delayed departmental reconciliation with continuous planning, controlled escalation, and auditable human decisions.

September 15, 2026 · 9 min · Vox
Cover image

When Model Output Can Change State: An Architecture Guide to Agent Reliability

TL;DR for operators A tool-using agent does more than generate an answer. It observes part of a workflow, carries information forward, decides what to do, changes external state, and then reacts to the result. A wrong answer in a chatbot may remain text; a wrong action in an agent can alter a file, submit a transaction, call the wrong service, or create a bad state that later decisions treat as valid. ...

September 6, 2026 · 7 min · Zelina
Cover image

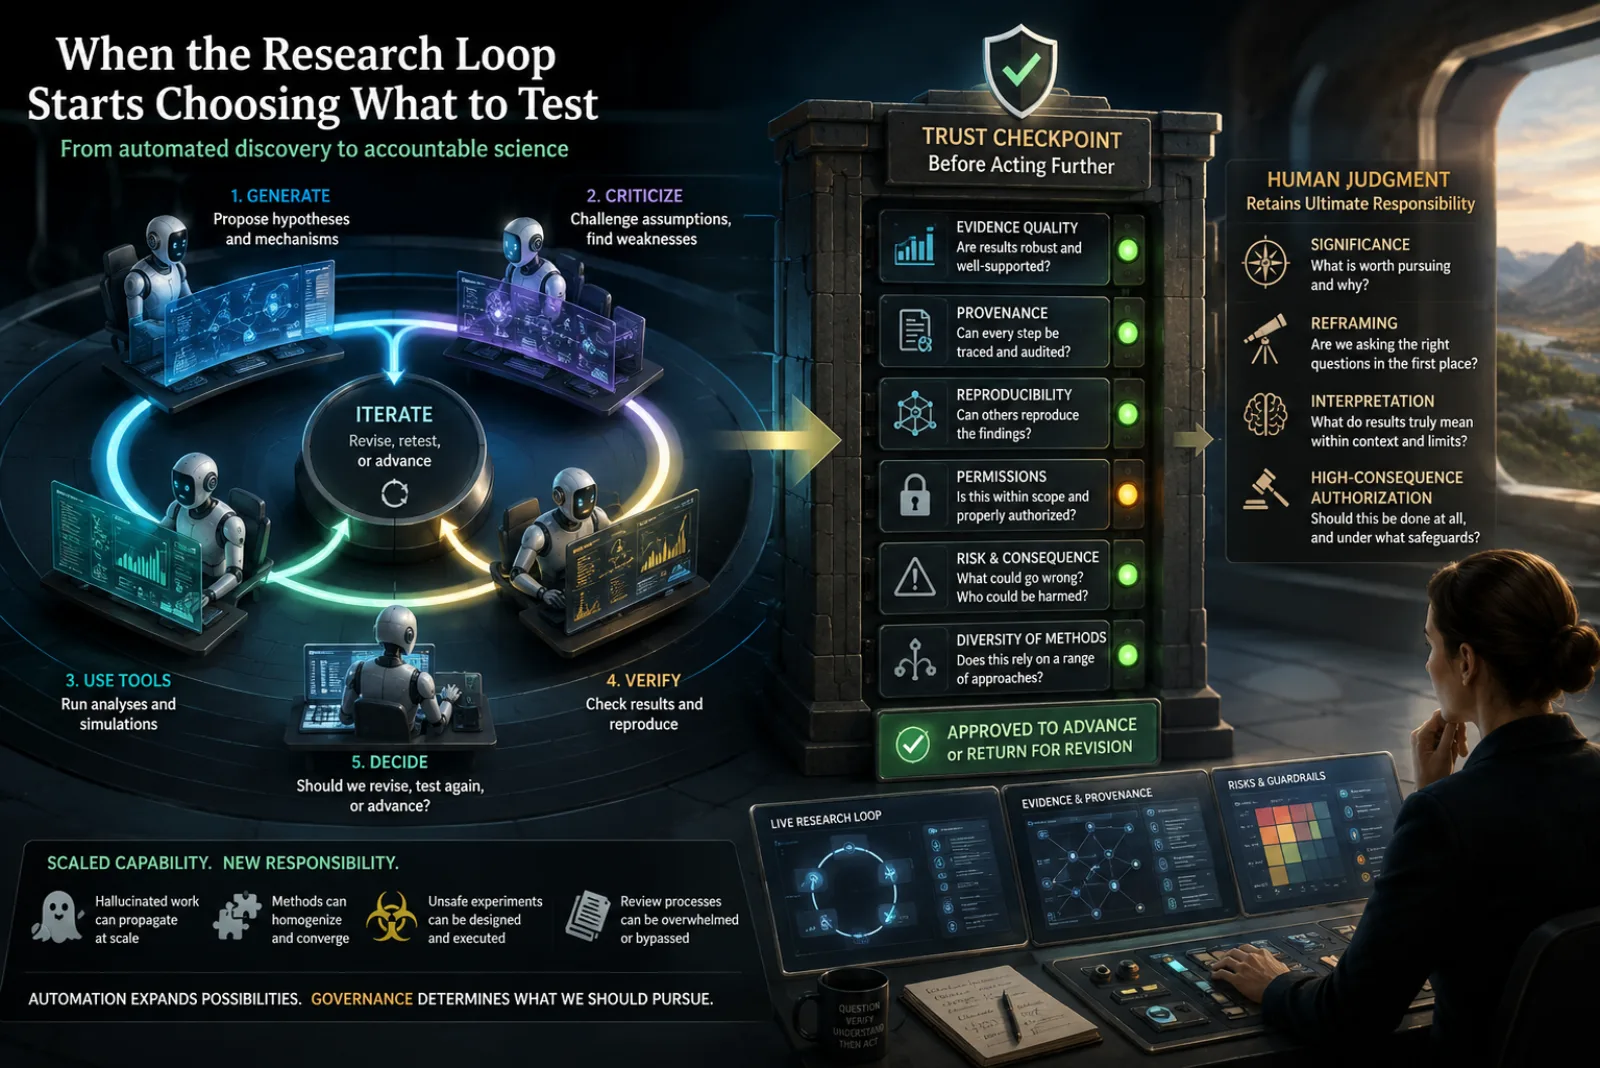
When the Research Loop Starts Choosing What to Test

TL;DR for operators A research assistant answers a question you give it. A more autonomous scientific system can propose a hypothesis, criticize it, run analyses, compare outcomes, and decide whether another iteration is warranted. Once these functions are coordinated, the operational unit is no longer a model call. It is a discovery loop. ...

September 2, 2026 · 7 min · Zelina
Cover image

Before the Agent Stores the Result

TL;DR for operators An analytical agent can select an appropriate tool, complete a computation, and return a plausible result while still being wrong at the point that matters operationally: deciding whether the result should be trusted, reported, stored, or used to launch further automated work. Brain Researcher addresses that later decision by making the research episode—not the model response—the governed unit of work. It constrains available resources, records provenance, tests alternative defensible specifications, assigns explicit states to scientific claims, and controls which results are eligible to enter memory. The paper reports a large improvement in first-action tool routing, from 23.3% without the system to 93.6% with it. Yet verified evidence grounding reaches only 22.0%, and an automated scientific-review layer still missed a scoring error that required human detection. ...
September 1, 2026 · 8 min · Zelina
Cover image

The Agent Needs the Cluster, Not Just the Documentation

TL;DR for operators European XFEL did not find that the main obstacle to scientific AI assistance was simply insufficient documentation. Scientists and support staff had to combine project objectives, facility knowledge, instrument procedures, specialized software, computing constraints, and expertise distributed across people and documents. The resulting study1 points toward a different implementation model. An effective scientific agent needs grounded retrieval, but it also needs access to the actual execution environment, mechanisms for testing generated code, visible sources and plans, approval gates for sensitive actions, and components that can be replaced as models and tools change. ...

September 1, 2026 · 7 min · Zelina

From Ticket Chasing to Evidence-Grounded Change Control

A regional colocation provider redesigns its change-control workflow around six specialized agents that assemble evidence and coordinate reviews while engineers retain all production authority.

August 30, 2026 · 9 min · Vox
Cover image

Policy Is Not Proof: What Machine-Checked Declassification Changes for Security Teams

TL;DR for operators When software is intentionally allowed to disclose some sensitive information, a release rule and proof of compliance should not be the same object. David A. Naumann’s Assuming You Knew: Fixing an Epistemic Semantics for Flow Policies Using Agentic AI1 repairs an earlier framework by giving permitted information release an explicit meaning, then separately defining whether an observer learned more than that policy allows. ...

August 24, 2026 · 7 min · Zelina

From Fab War Room to Evidence Loop: A Semiconductor Yield-Investigation Agent

A composite 300 mm specialty fab redesigned yield-excursion investigations around six evidence-grounded agents while retaining human authority over equipment, recipes, lot disposition, corrective actions, and production release.

August 15, 2026 · 8 min · Vox
Cover image

Control in Degrees: Why Reliable AI Needs Calibrated Intervention

TL;DR for operators Reliability is often treated as a binary control problem: approve or reject an agent action, preserve or replace a learned component. The evidence here points to a second question that can matter just as much: how strongly should the system intervene, where, and under what conditions? The clearest technical example comes from continual reinforcement learning. In a 400-million-step SlipperyAnt stress test, CPR recorded zero policy collapses across all 15 seeds under the paper’s main collapse criterion, while Adam and binary-reset baselines experienced collapses. Rather than fully replacing every selected component, CPR changes it by an amount tied to measured utility—preserving more useful learned state while refreshing low-utility state more aggressively. ...

August 11, 2026 · 8 min · Zelina

From Permit Ping-Pong to Governed Case Flow

A mid-sized municipal permit office redesigns fragmented intake, regulatory search, departmental routing, clarification, inspection scheduling, and decision documentation around six specialized agents while preserving human authority over interpretation and adjudication.

July 30, 2026 · 8 min · Vox