Layers Are Not Independent: Red-Team the Whole AI Safety Stack
Cascade shows why AI safety testing has to include the software and hardware conditions that determine whether model-level defenses actually execute as intended.
Cascade shows why AI safety testing has to include the software and hardware conditions that determine whether model-level defenses actually execute as intended.
A controlled simulation workflow shows how LLMs can expand behavioural and scenario specification without taking execution authority away from a calibrated model.
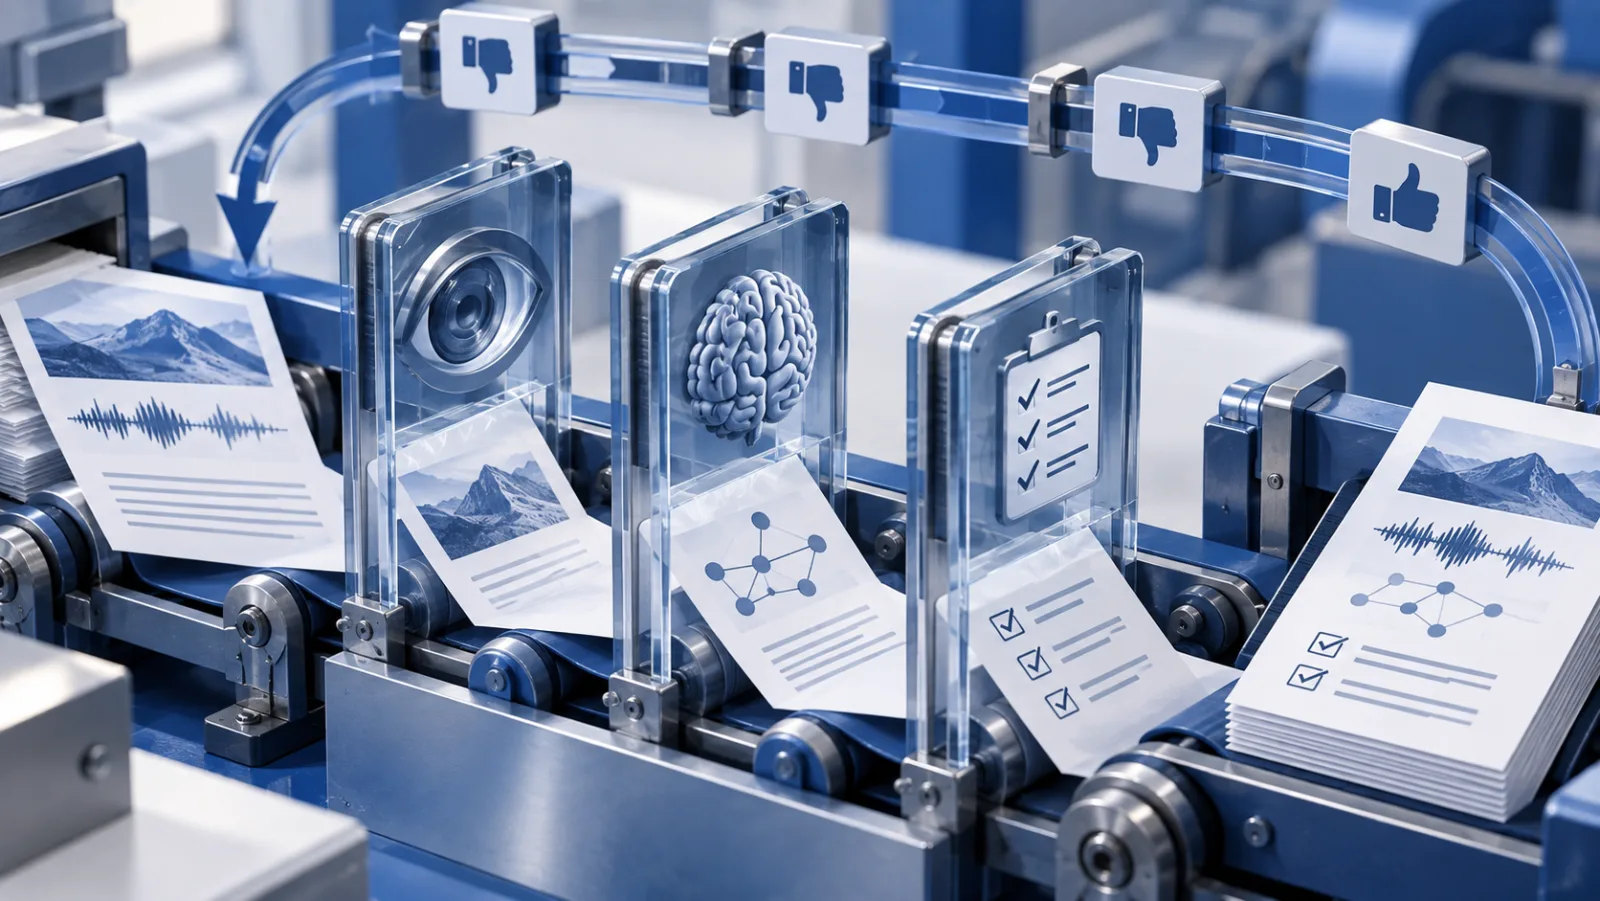
V-Rubrics shows how criterion-level and localized reinforcement-learning credit can make multimodal post-training more targeted when intermediate visual and reasoning errors matter.
A framework for assigning human vetoes and bounded AI override rights according to which failure—acting wrongly or failing to act—carries the greater cost.
Emoji-based jailbreak tests show why pre-release safety evaluation must vary how harmful intent is represented, not just whether a model refuses explicit text.
ATACompressor shows why context compression should decide both what evidence to preserve and how much representation capacity each query deserves.
LycheeMemory shows how compressed memory and state-dependent gating can cut long-context inference cost by allocating expensive reasoning only to selected evidence.
A polymer-literature benchmark shows why retrieval recall alone cannot decide between GraphRAG and VectorRAG for technical knowledge systems.
A multimodal assistant that refuses one harmful prompt may still fail after benign conversational context has accumulated, changing how safety teams should test interactions and moderate outputs.
KBevo shows that an external knowledge store can be optimized for downstream answers and edited later, but better task utility does not make the stored facts automatically trustworthy.