Cover image

The Best AI Team Knows When to Stay Quiet: GRADE and the Economics of Selective Reasoning

GRADE shows how a multi-agent AI system can improve reasoning by selectively activating experts, limiting communication, pruning weak branches, and recalibrating models when the roster changes.
July 19, 2026 · 21 min · Zelina
Cover image

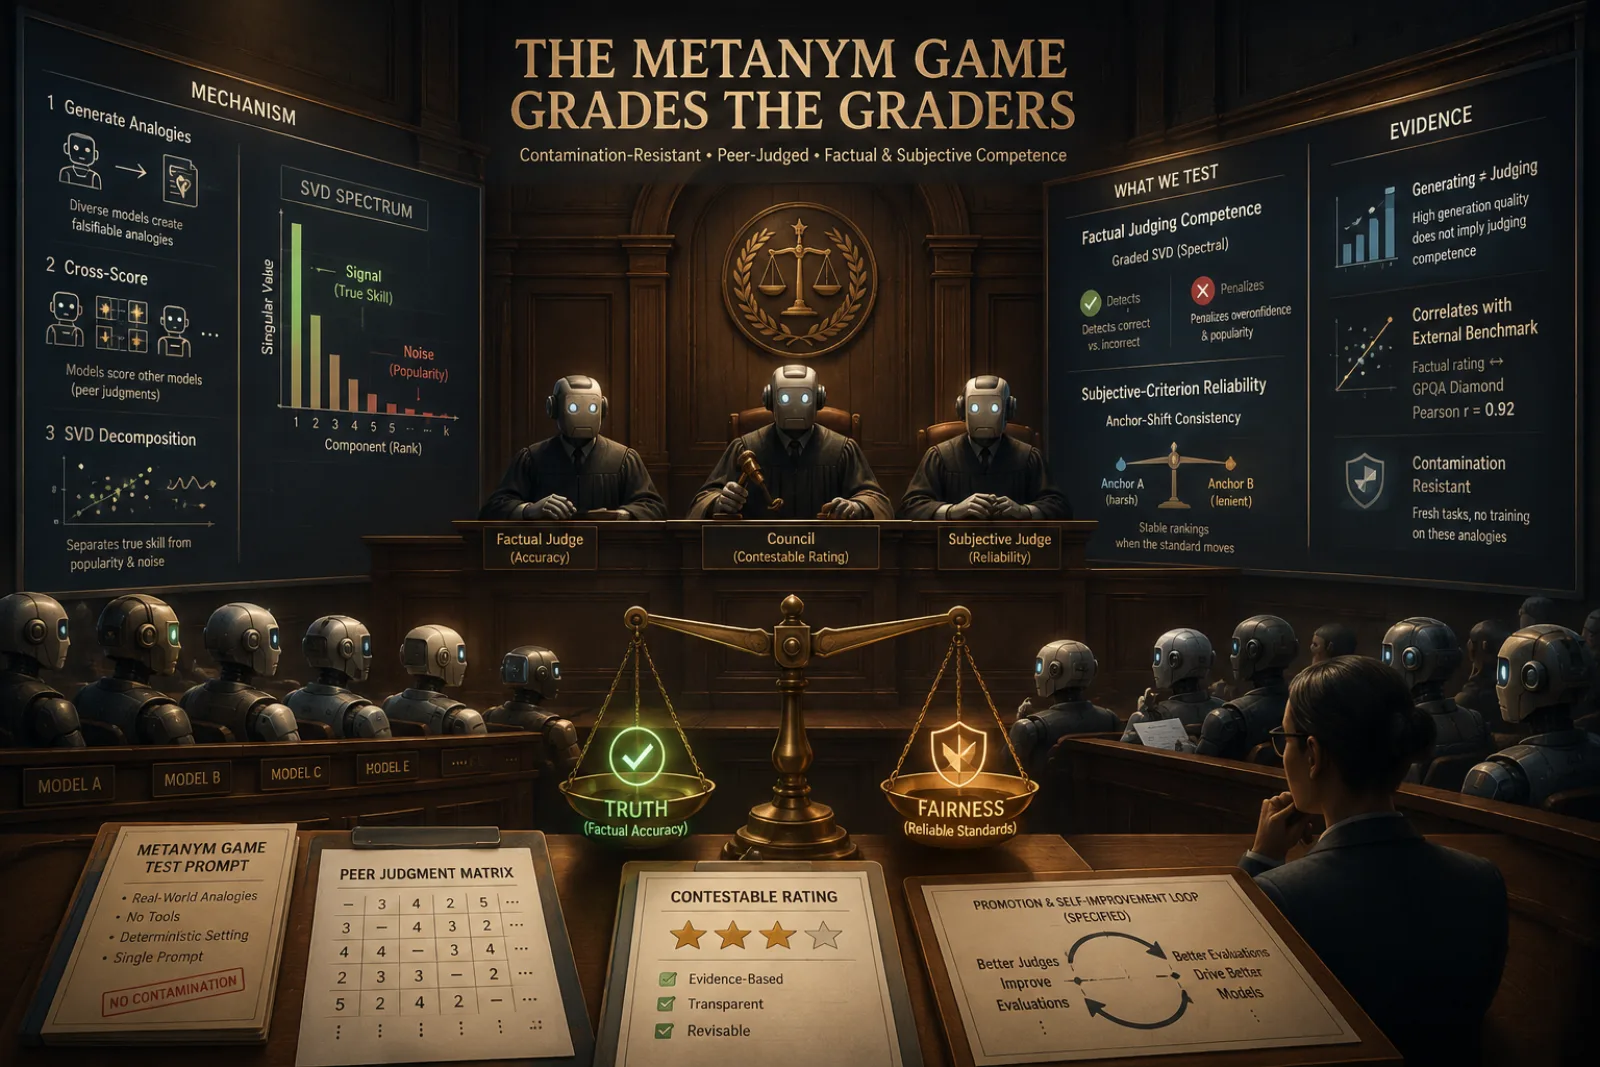
Judge, Jury, and Benchmark: The Metanym Game Grades the Graders

A self-generated analogy game separates models that produce strong answers from those that can reliably detect errors—and offers a blueprint for evaluator governance without a standing answer key.

July 18, 2026 · 21 min · Zelina
Cover image

Look Ahead, Look Back, or Fix It Later: Three Ways to Build an AI Agronomist

Agri-SAGE shows how retrieval, crop simulation, and different agent reasoning strategies create distinct trade-offs between simulated yield, adaptation, and computational cost.

July 18, 2026 · 18 min · Zelina
Cover image

Trust No One, Adjudicate Everything: When RAG Sources Disagree

MACR shows why reliable AI needs an explicit process for adjudicating conflicts, not another instruction to trust the model or the retrieved document.

July 18, 2026 · 18 min · Zelina
Cover image

Course Correction: Ask What Learners Use, Not What Courses They Took

A study of graduate bioscience trainees finds that reported LLM usage separates pre-course attitudes more consistently than prior AI coursework, offering a practical but limited signal for adaptive training.

July 17, 2026 · 18 min · Zelina
Cover image

Many Voices, One Label: How Pluralistic AI Flattens the World

A lifecycle framework reveals how AI systems can collect diverse views while quietly fixing the categories, proxies, and decision rights that matter most.

July 17, 2026 · 24 min · Zelina
Cover image

Thirteen Buckets and a Warning Light

A bilingual feedback pipeline shows how organizations can turn messy comments into governed early-warning signals—without pretending the system has diagnosed bias.

July 17, 2026 · 20 min · Zelina
Cover image

Swap the Videos, Break the Model

MotionHalluc shows that multimodal models can sound like competent coaches while failing to verify which person actually performed which motion.

July 16, 2026 · 20 min · Zelina
Cover image

The Agent Benchmark Without the Agent Bill

Pace shows how carefully selected static tests can screen models for expensive agentic evaluations—provided the proxy remains a filter rather than a substitute for reality.

July 16, 2026 · 16 min · Zelina
Cover image

The Refusal Rate That Refuses to Reassure

A large automated red-team study shows why high aggregate refusal rates can conceal concentrated, inexpensive, and operationally significant jailbreak exposure.

July 16, 2026 · 18 min · Zelina