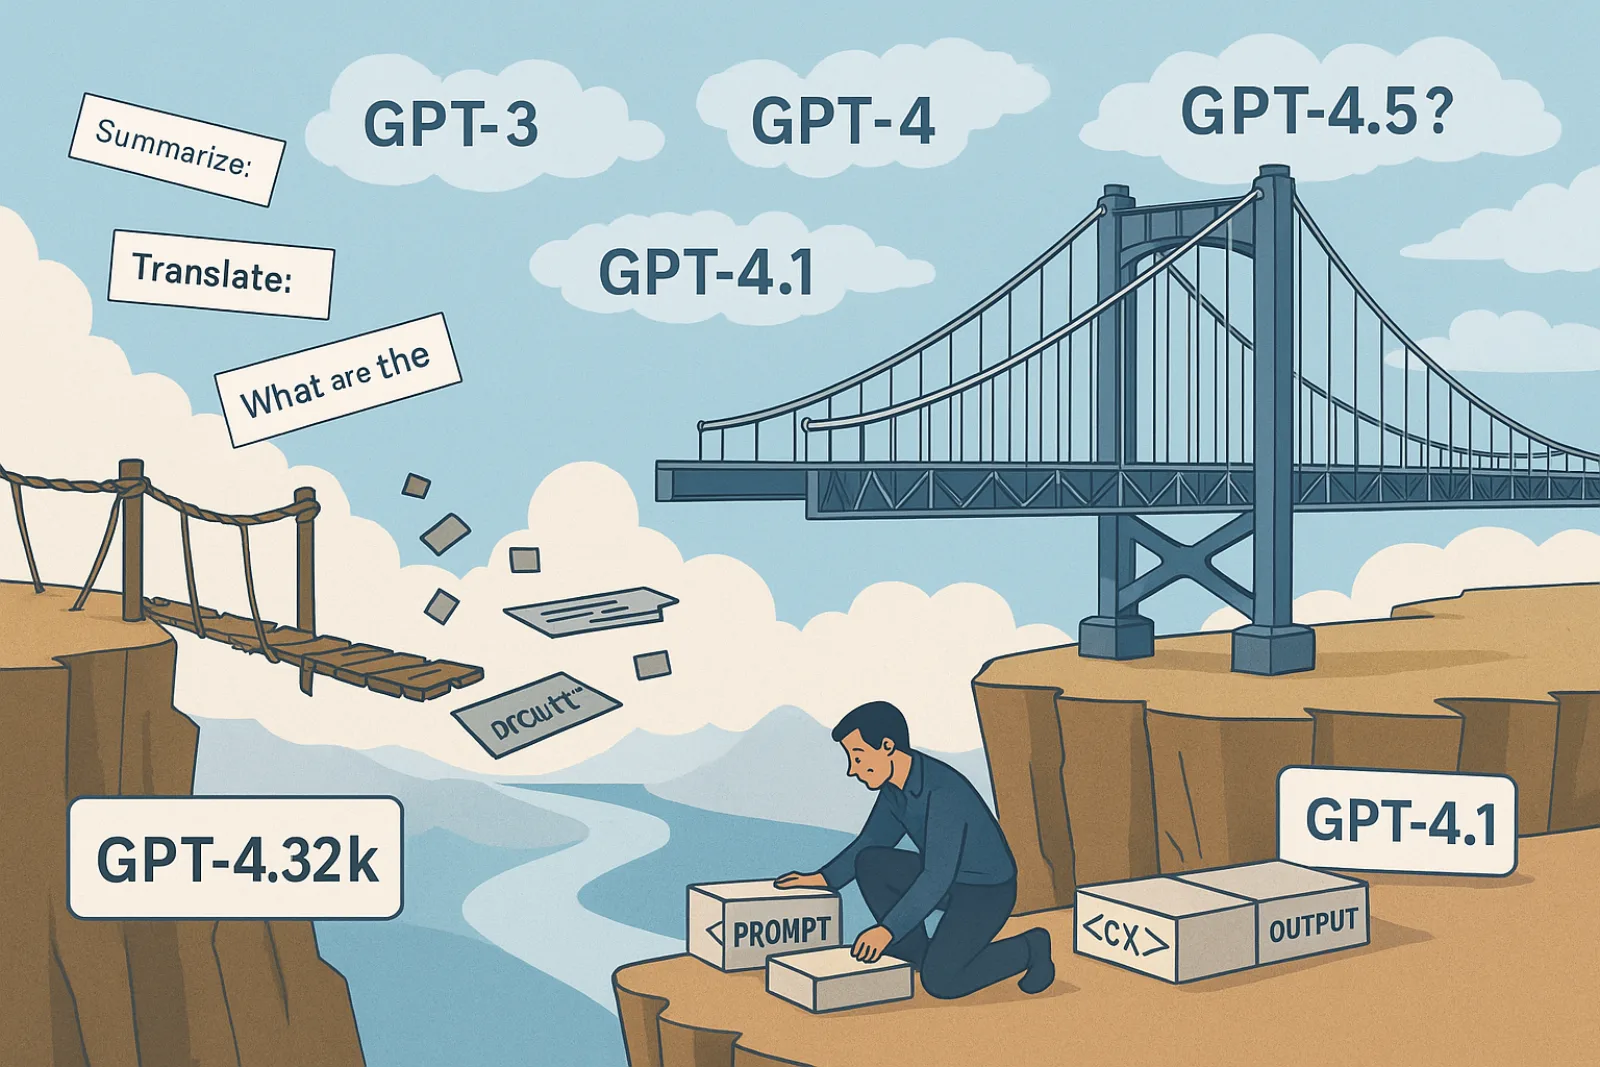
From Prompting to Porting: Surviving the LLM Upgrade Cycle
A case-first analysis of why production LLM prompts need migration discipline, not just better wording, when model versions change.
A case-first analysis of why production LLM prompts need migration discipline, not just better wording, when model versions change.
A comparison-based read of how fine-tuned open models can rival proprietary LLMs for narrow educational feedback tasks—without pretending they have conquered tutoring.
CAVGAN shows that LLM jailbreaks and defenses may be two sides of the same hidden-representation boundary problem.
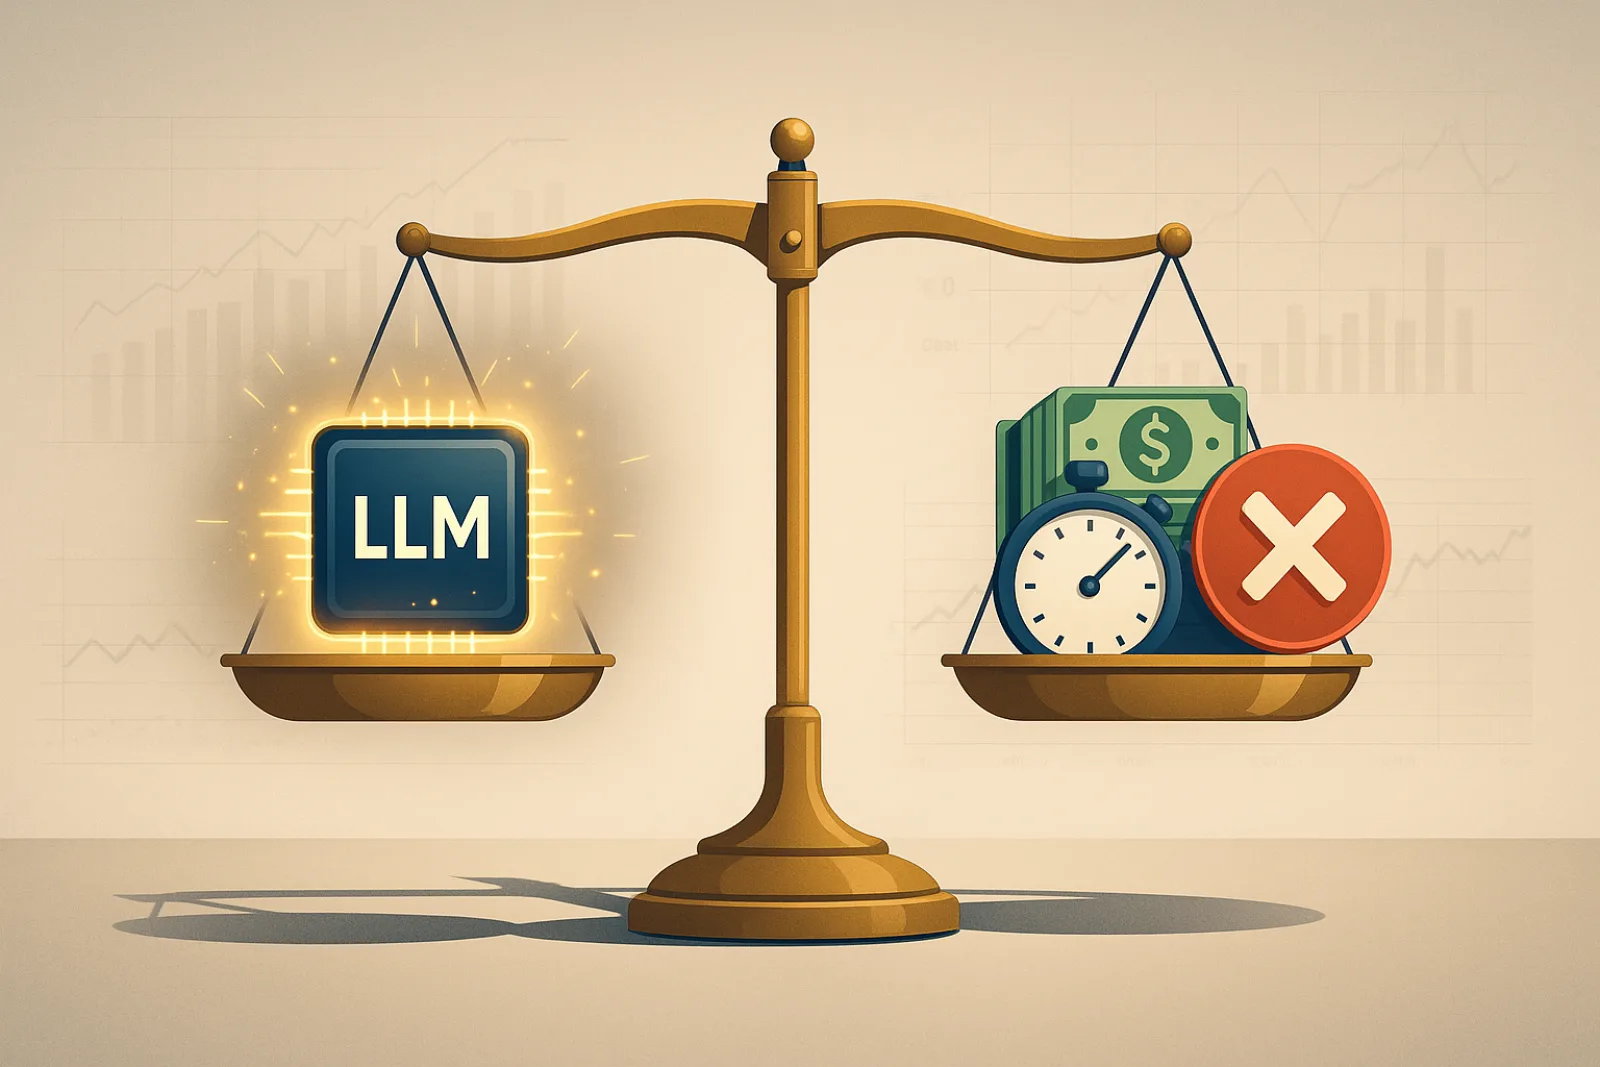
A practical reading of an economic LLM evaluation framework that turns accuracy, latency, abstention, and inference cost into dollar-valued deployment decisions.
A mechanism-first look at Partial Model Collapse, a machine unlearning method that turns self-generation drift into targeted output removal for LLMs.
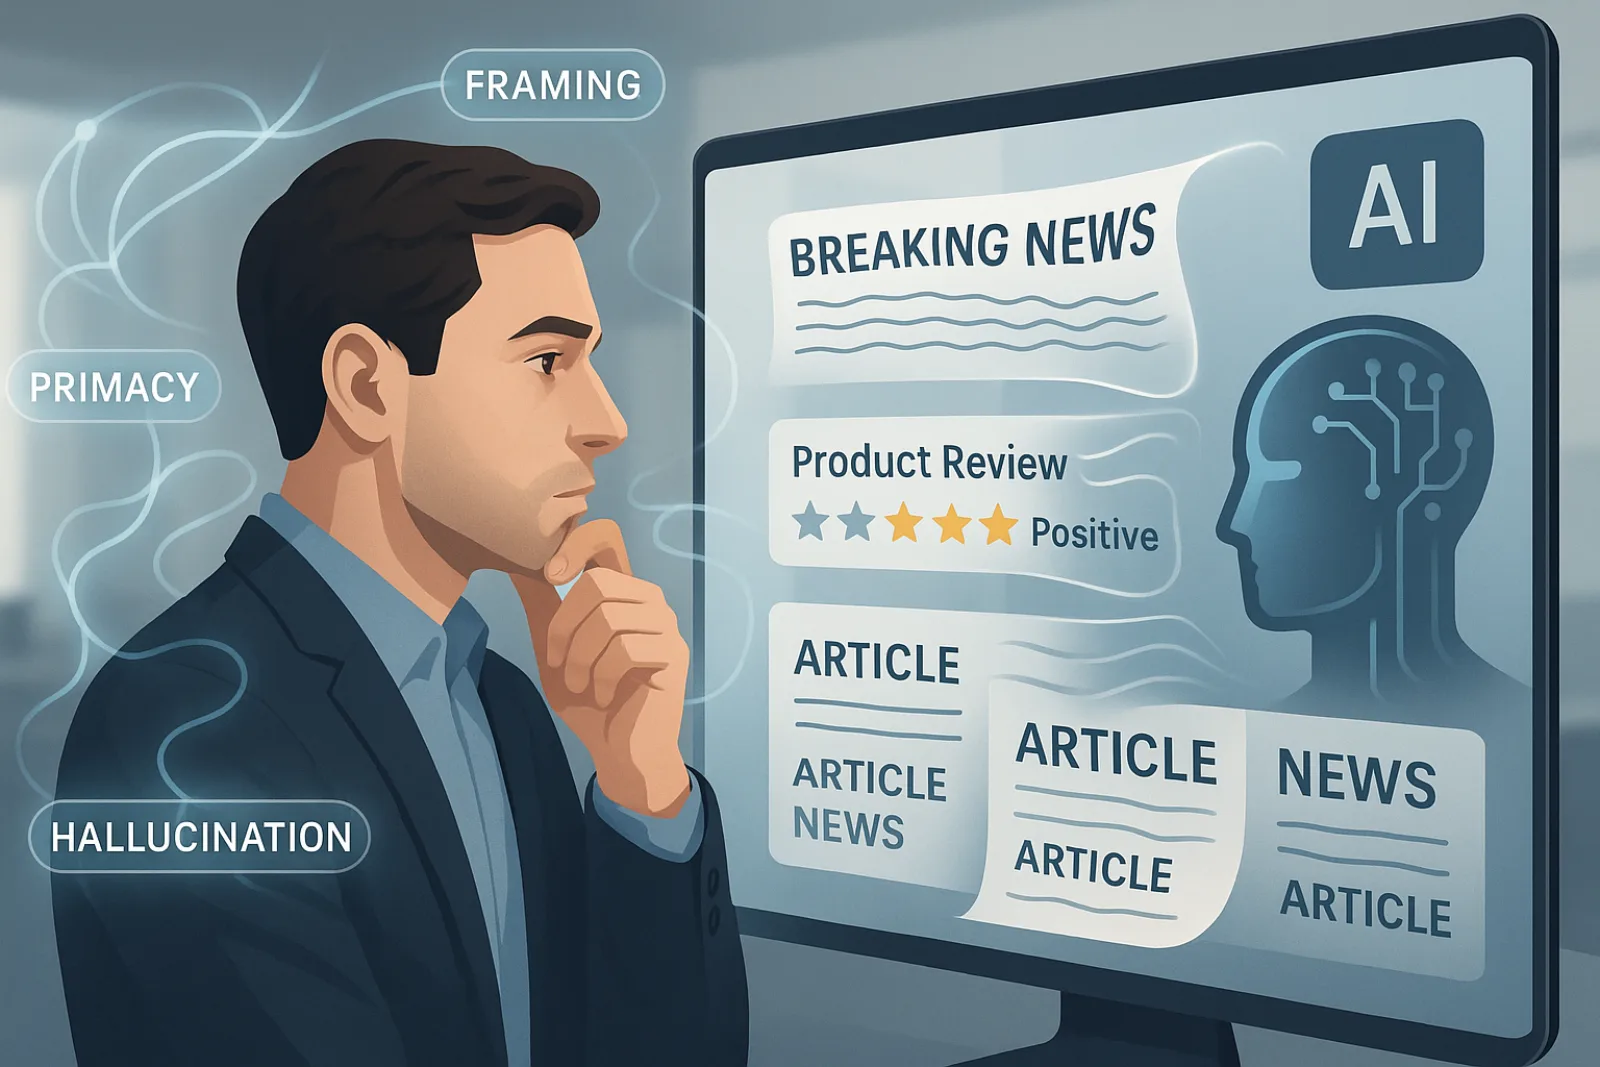
A mechanism-first reading of how LLM summaries can reframe evidence, overweight early context, hallucinate authority, and measurably shift user decisions.
X-Master shows that scientific AI progress can come from inference-time orchestration, tool access, critique, rewriting, and selection—not only from larger model training.
A practical reading of PhantomText, a study showing how invisible document manipulations can poison RAG systems before the model ever sees a prompt.
ASTRO shows that reasoning gains can come from training models to recover from wrong turns, not merely from scaling models or wrapping them in external agent scaffolds.
A mechanism-first reading of how LLM market agents coordinate prices, why communication and pressure matter, and what operators should test before deploying autonomous pricing agents.