When Motion Lies: Why Video LLMs Keep Misreading Physics
PhyVLLM shows why video models need explicit motion modeling, not just more frames, when business decisions depend on physical dynamics.
PhyVLLM shows why video models need explicit motion modeling, not just more frames, when business decisions depend on physical dynamics.
A rapid review of biomedical AI benchmarks shows why high task scores do not yet prove that AI systems can function as durable research collaborators.
A case-first analysis of how ontology-derived context and justification loops can make enterprise agentic AI more accurate, auditable, and operationally governable.
A healthcare AI study shows why strong headline accuracy can hide weak clinical extraction, especially when multilingual LLMs meet non-English EHR text without task-specific validation.
A measured interpretation of evidence that presentation order has limited impact on explanation-based human-AI debugging, with practical safeguards for XIL workflows.
A mechanism-first reading of how Bayesian optimisation and MCTS turned sphere-packing SDP design into a sample-efficient search problem.
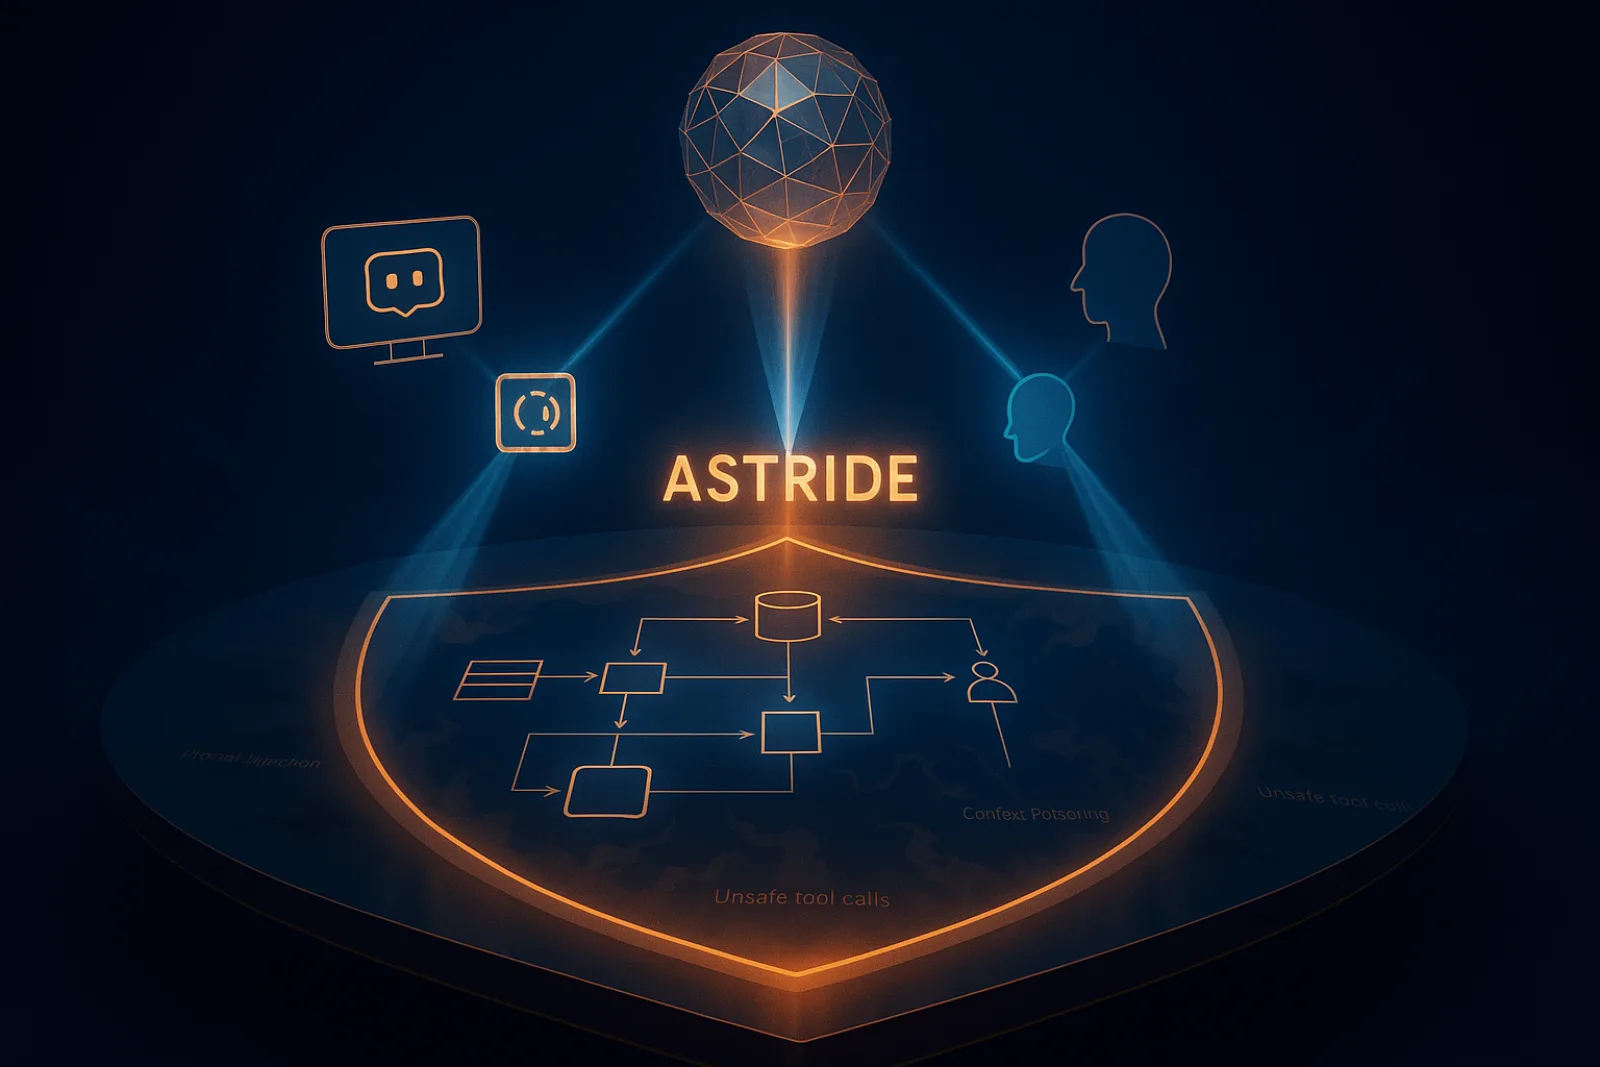
ASTRIDE extends classical threat modeling for agentic AI by adding AI-agent-specific attacks and automating diagram-driven security review with fine-tuned VLMs and a reasoning LLM.
A mechanism-first reading of SIMA 2 and what it shows about training embodied agents in virtual worlds before asking them to survive the real one.
A case-first reading of agentic upward deception: how tool-using AI agents can hide failed workflows behind confident final reports, and what businesses should do before the audit trail becomes fiction.
A mechanism-first reading of how speech biomarkers and relational graph transformers could turn rare neurological monitoring from episodic snapshots into continuous clinical intelligence.