The Vanishing Quotient: When More Training Erases Arithmetic Skills
A tiny Transformer learns long division, then loses it—revealing why algorithm design, training-token efficiency, and skill retention need separate tests.
A tiny Transformer learns long division, then loses it—revealing why algorithm design, training-token efficiency, and skill retention need separate tests.
An industrial AI-guided drug formulation study shows how to balance sustained release with injectability—and why promising simulated efficiency gains still need prospective validation.
How geometry-aware grouping can preserve specialized AI capabilities while consolidating multiple fine-tuned models into a smaller deployment portfolio.
Why refinement-aware initialization can help existing routing solvers find better solutions with less computation.
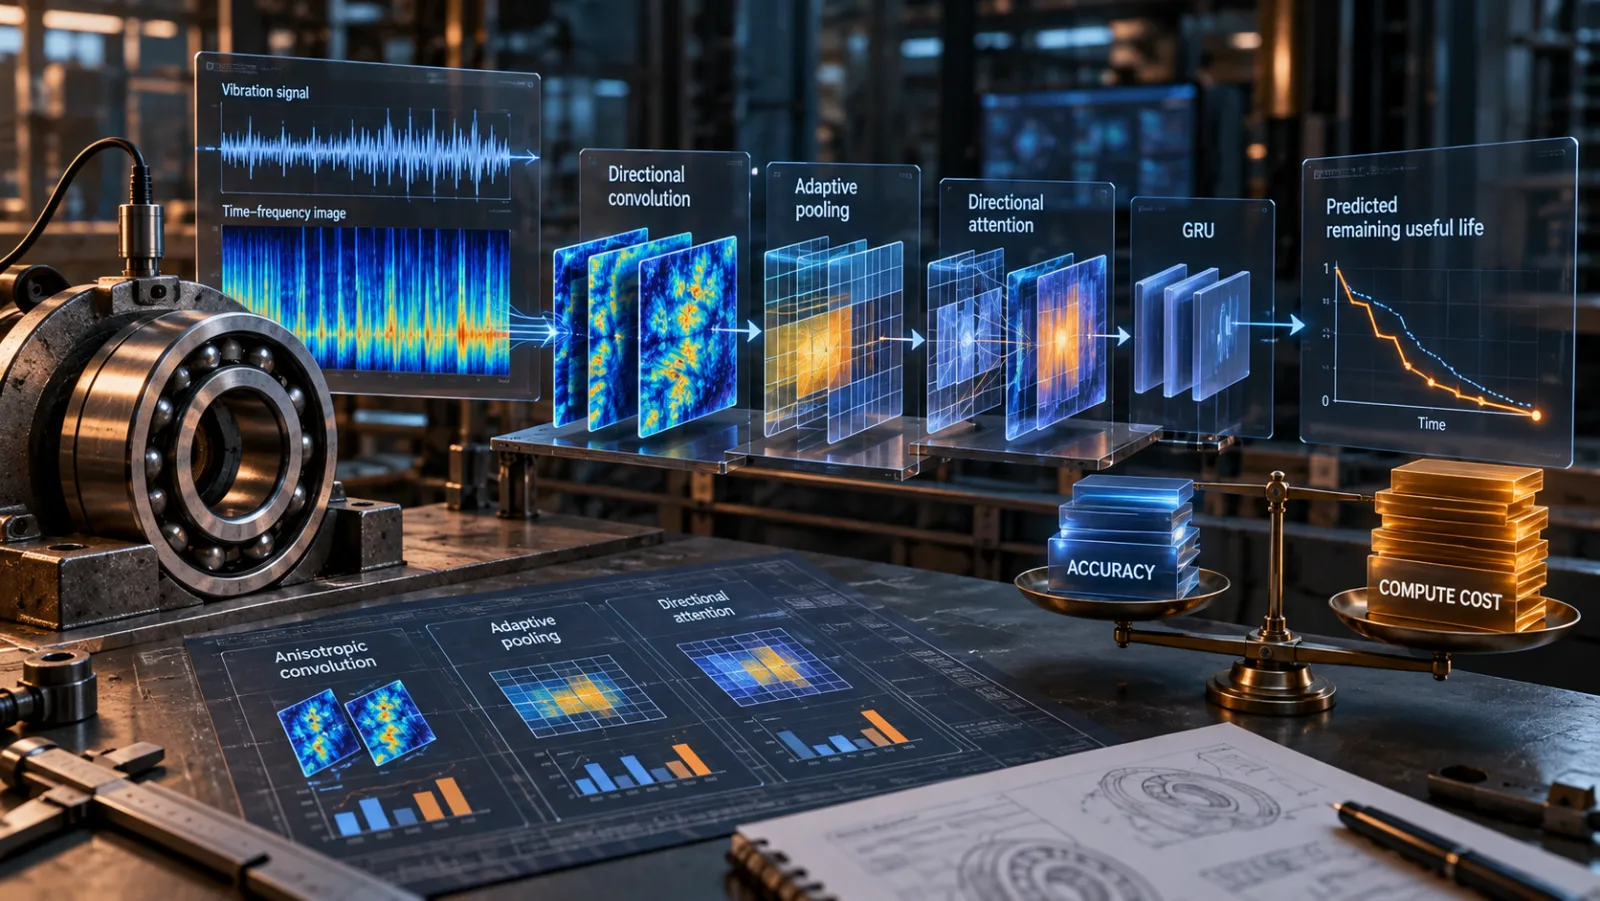
A bearing-life prediction model improves benchmark accuracy through directional feature extraction, but its component-level evidence and computational cost complicate deployment decisions.
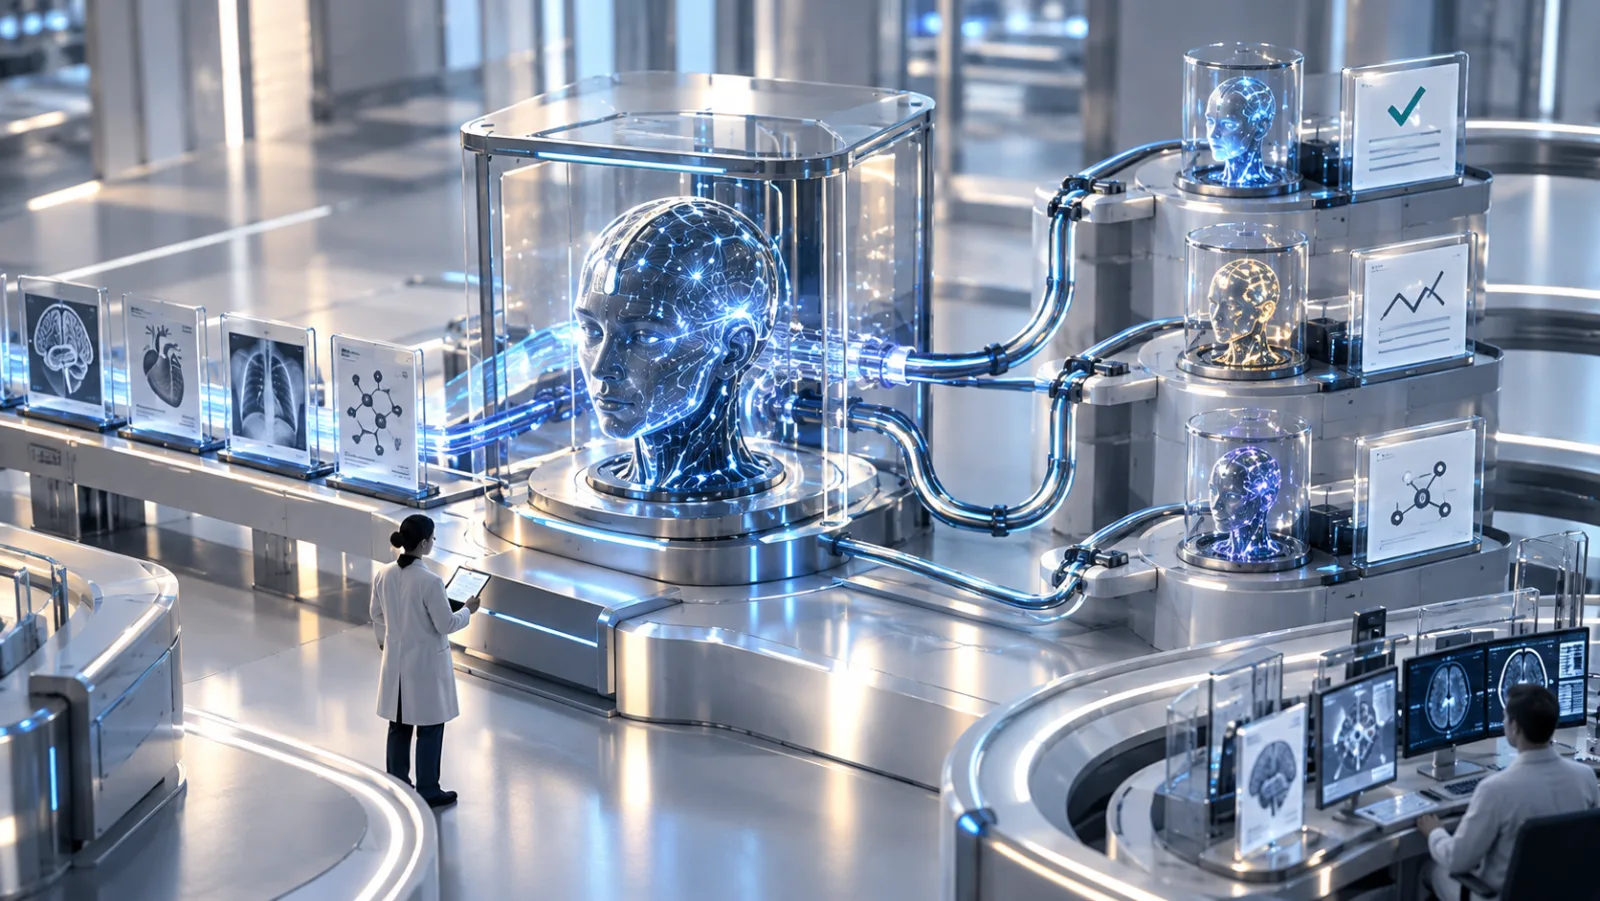
A clinical LLM can answer correctly and consistently while its explanations remain weakly connected to the evidence it cites.
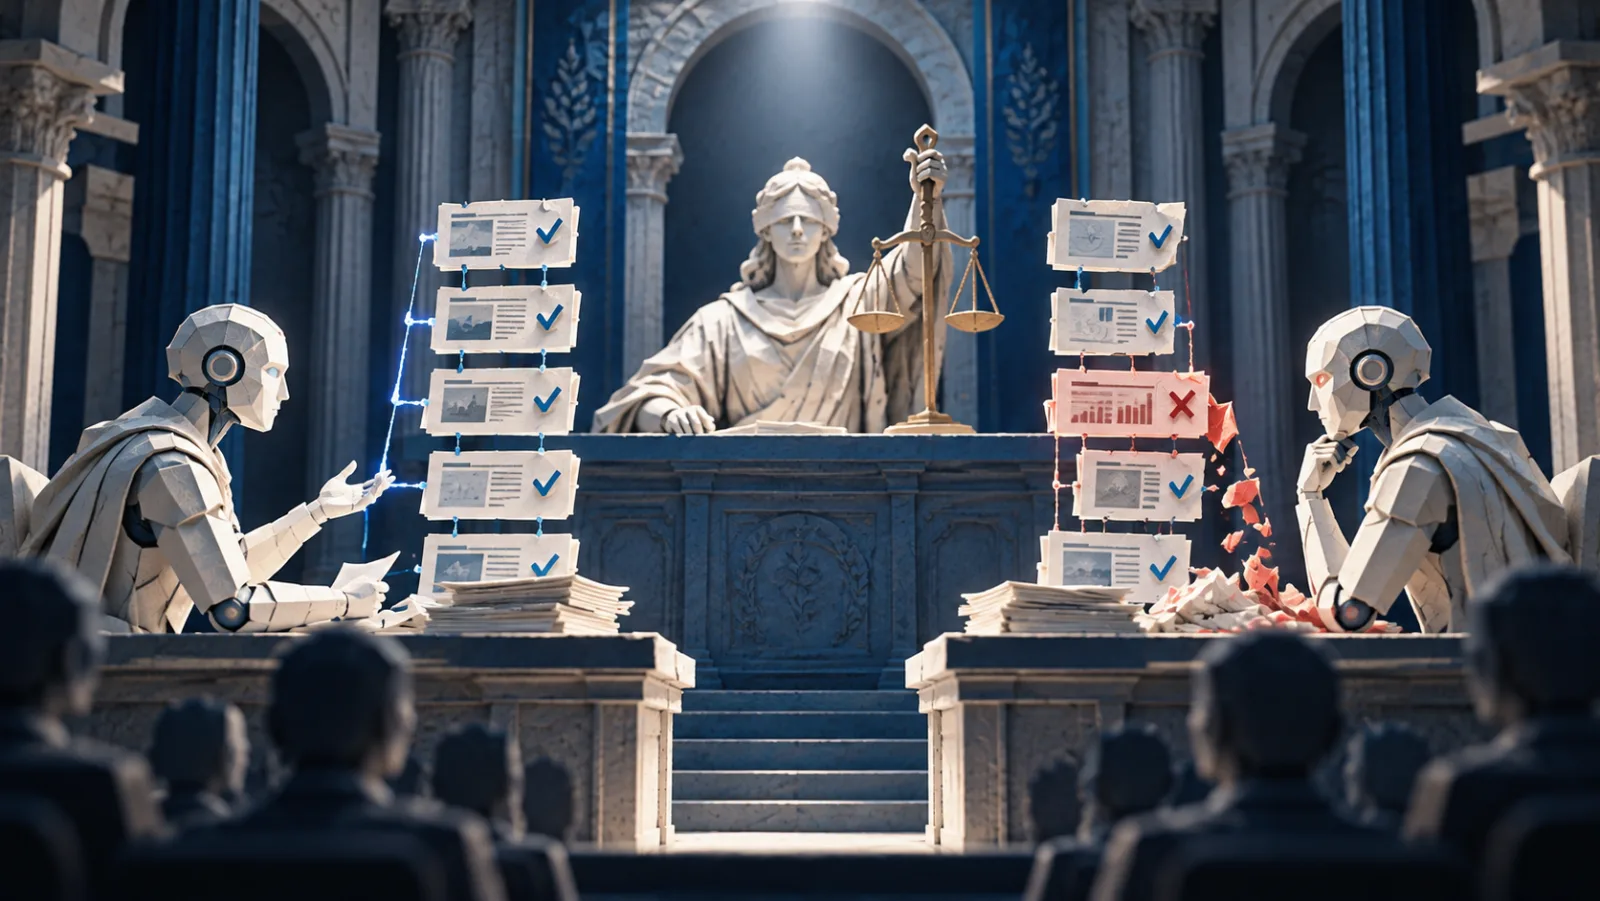
DeCert shows how checking the evidence behind AI judgments can improve preference training, explanation quality, and evaluation robustness.
ResonAct improves multi-agent task completion through runtime intervention, but its false-positive rates show why detecting failures is not enough for safe automated recovery.
VEPA shows how evolving agent guardrails can correct failures, limit regressions, and separate formally valid rules from rules authorized to make decisions.
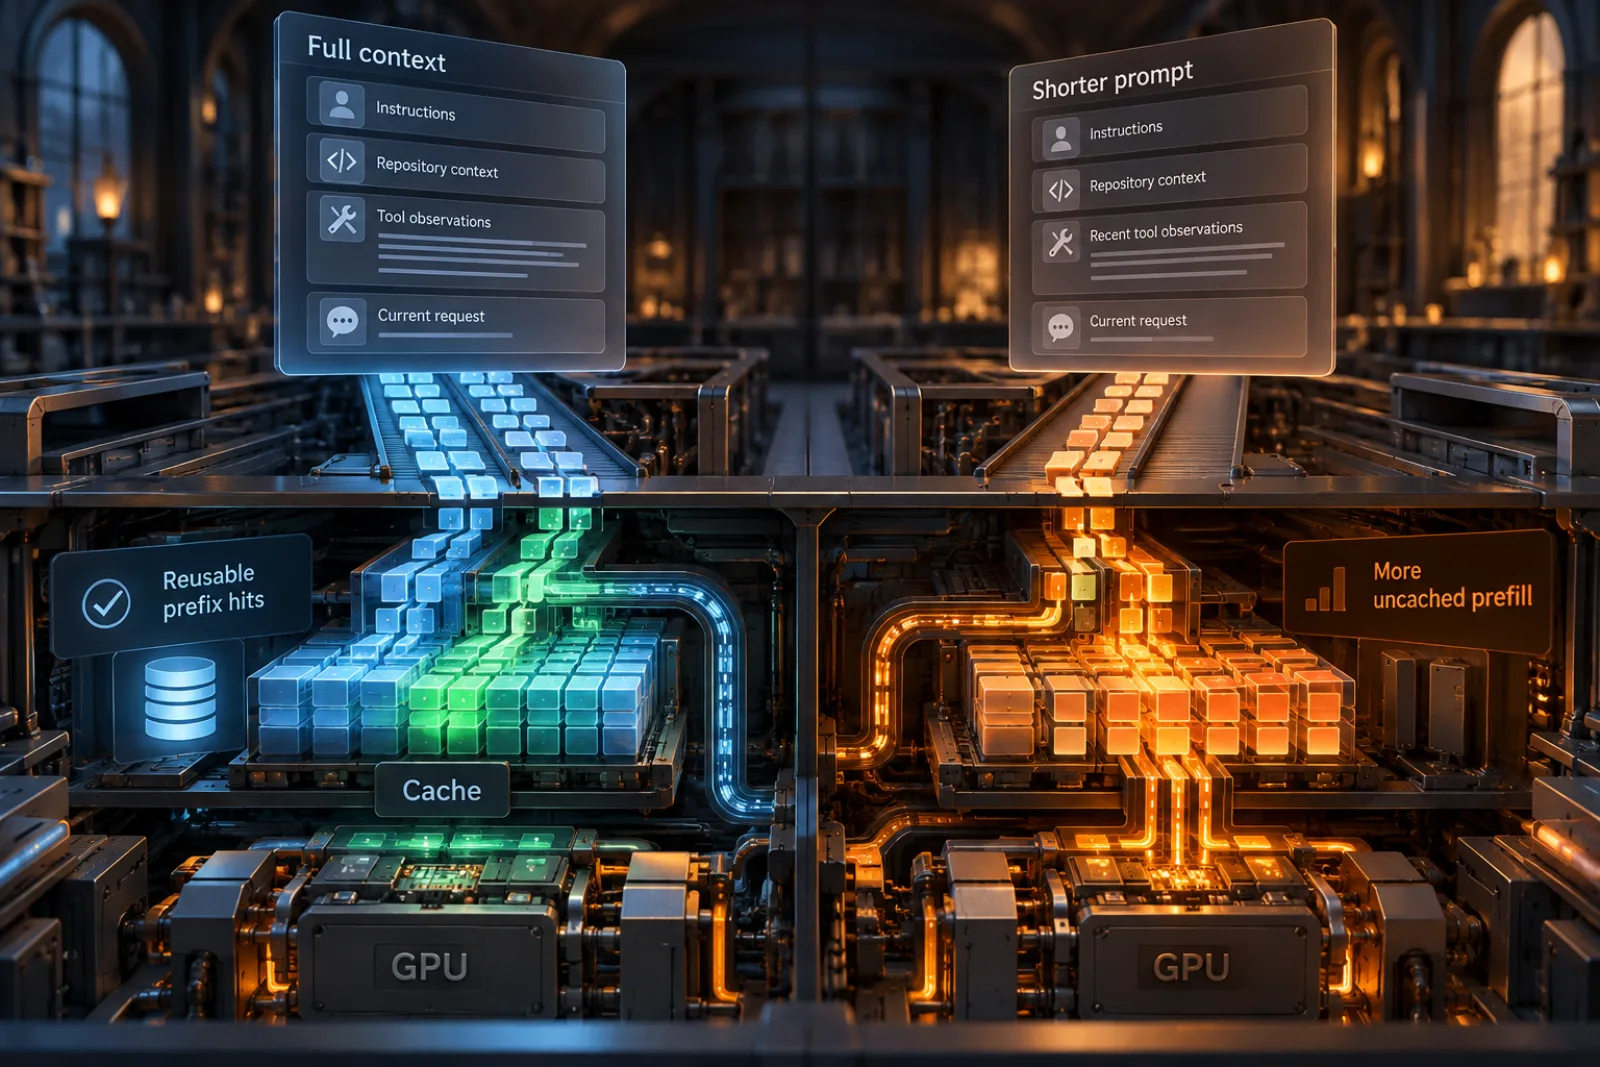
Why coding-agent context compression can increase GPU work, and how to measure efficiency without sacrificing task quality.