Both Alleles Scored 0.995. The Experiment Disagreed.
ARGUS shows how scientific AI agents can investigate genomic predictions without allowing language models to turn uncertain evidence into unsupported conclusions.
ARGUS shows how scientific AI agents can investigate genomic predictions without allowing language models to turn uncertain evidence into unsupported conclusions.
FaShift shows how predictive sensitivity and stability can guide which changing multimodal signals to suppress, preserve, or attenuate.
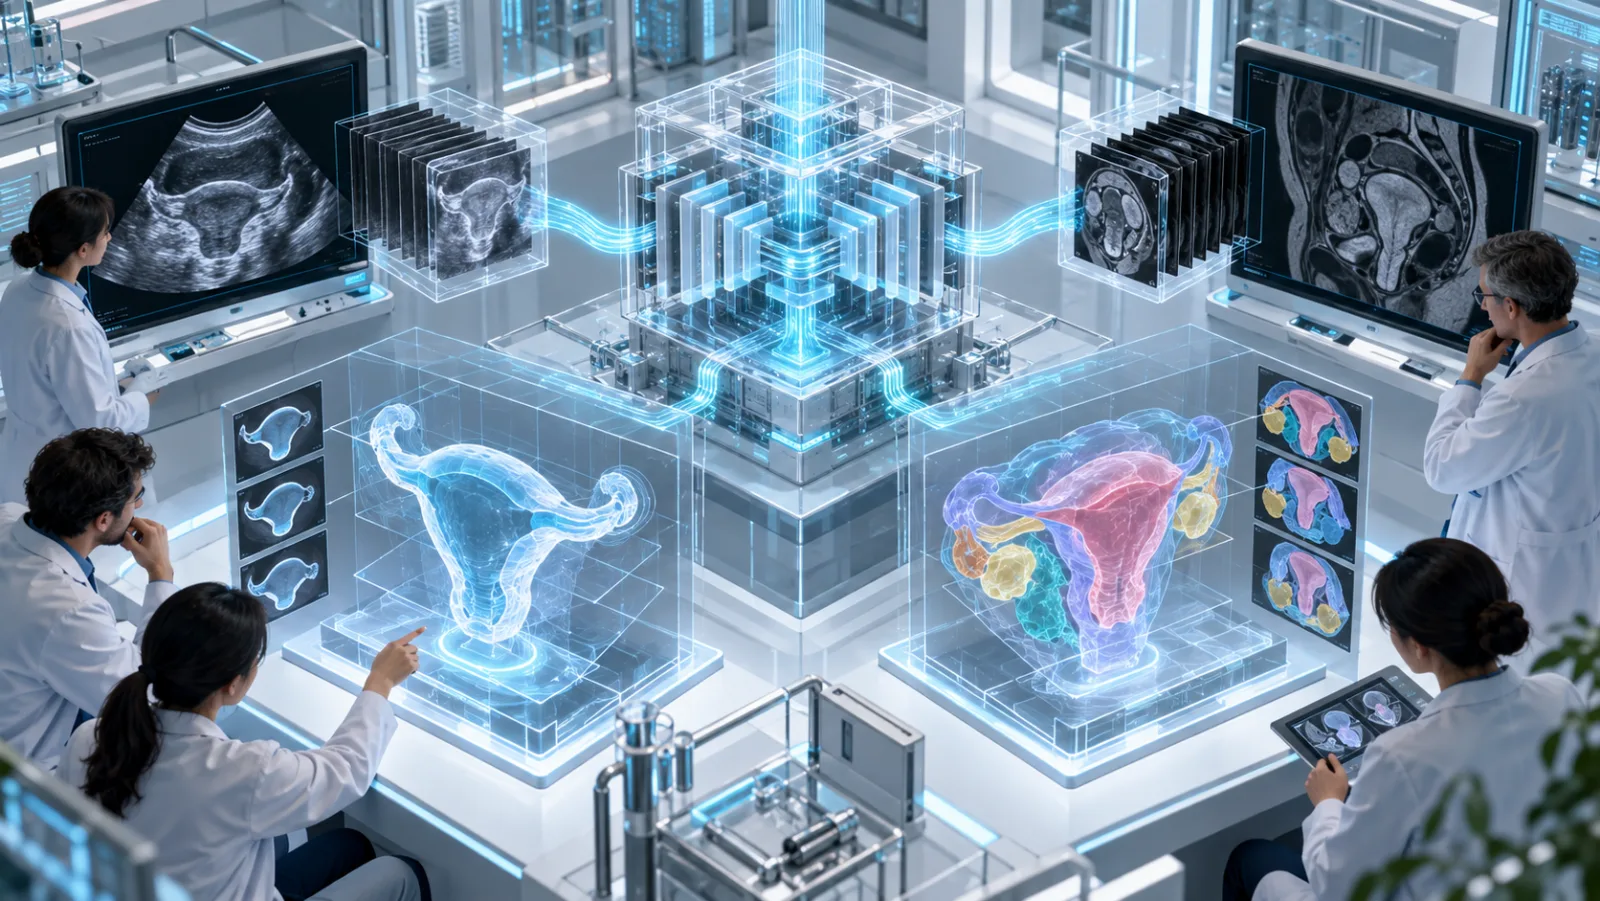
TPUS brings uterine ultrasound and MRI segmentation into one architecture, but its results show why better overlap does not always mean better boundaries.
ReTeach converts verified model failures into token-level training signals without reference solutions, improving accuracy while adding reflective training cost.
How SAGE coordinates visible-thermal image alignment and fusion to improve vehicle detection, and why geometric accuracy and inference cost still determine deployment value.
A representation-based data-selection method shows how fine-tuning teams can prioritize examples that expose potentially unassimilated knowledge rather than merely high model loss.
How reproducible evaluation and mandatory-rule checks make prompt compression more defensible for production AI agents.
COUNT shows how frozen corpus statistics stored in host RAM can improve transformer performance and support domain adaptation without additional learned n-gram embeddings.
VHop shows how sequential visual retrieval can outperform stronger LLMs and wider image search, while exposing important limits in real-world transfer.
Why generating more correct answers may barely improve an AI system's final output, and how to diagnose the gap between answer availability, selection, and reasoning support.