TL;DR for operators
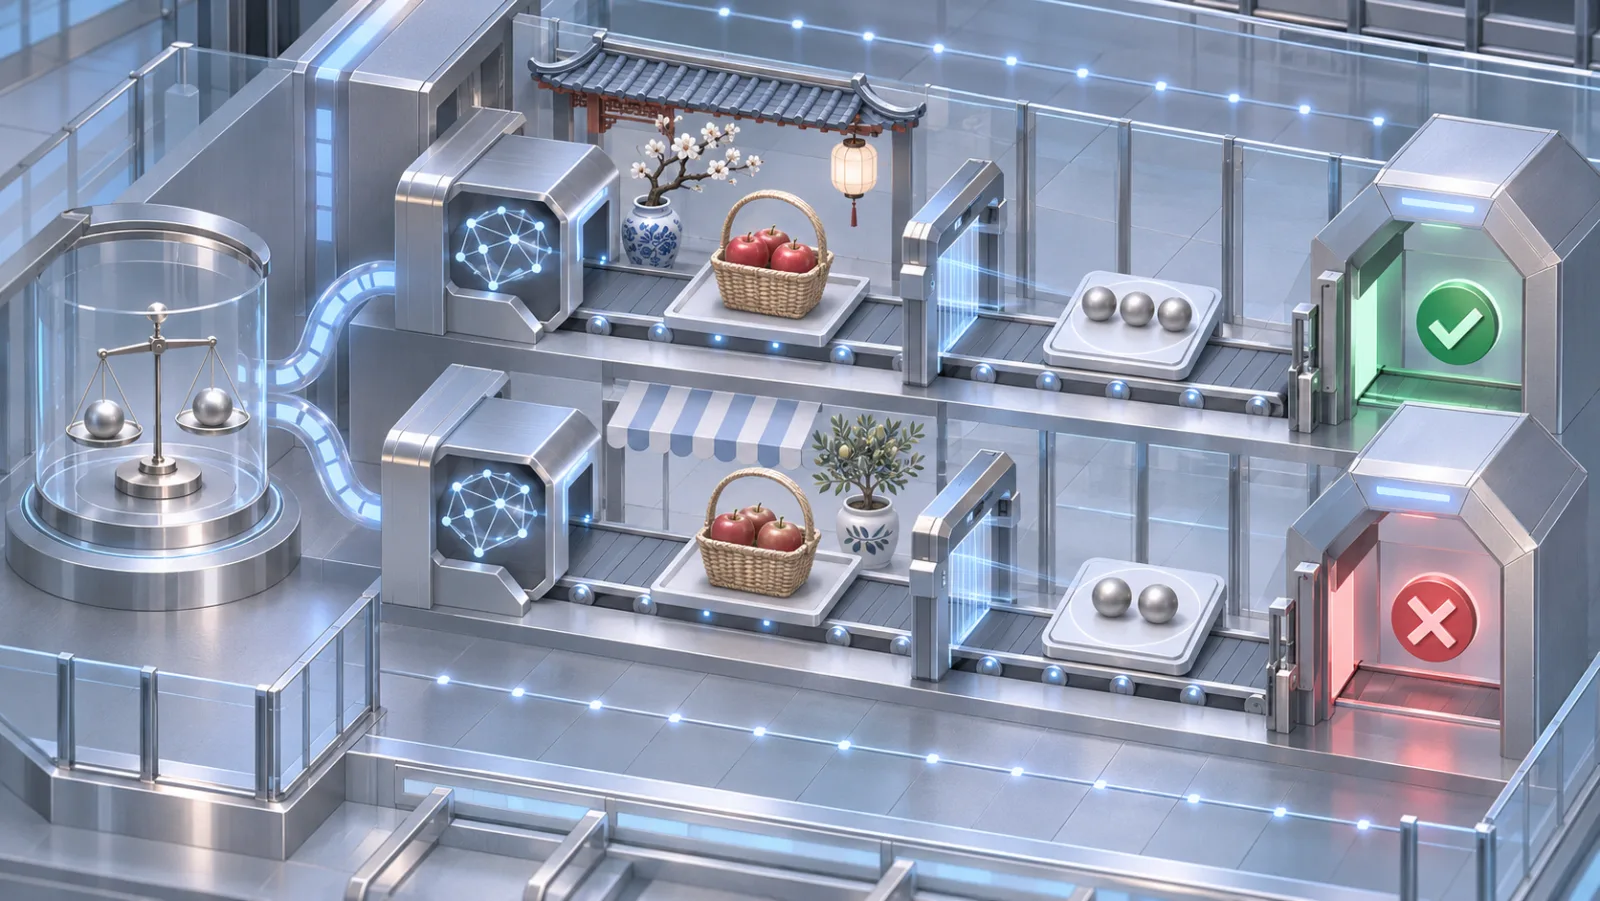
A multilingual AI model can preserve nearly the same average accuracy after cultural localization while changing which individual questions it answers correctly. In DAR-MGSM, a benchmark covering Modern Standard Arabic and five Arabic dialects, researchers evaluate direct translations and culturally localized versions of mathematical word problems.1
Across three Gemma 4 models, 316 of 3,582 eligible translated–localized pairs (8.8%) switch between correct and incorrect answers, despite an average accuracy decline of only 1.2 percentage points. Across all 11 evaluated models, mean accuracy decreases from 65.5% to 63.4%, but model-level effects vary considerably.
For teams qualifying Arabic-language AI systems, the operational implication is to measure correctness on matched original and localized questions, not just compare aggregate scores. Internal-representation experiments confirm that modified prompt spans can influence model behavior, although they do not establish that the exact cultural meaning of substituted entities causes the failures. The 8.8% discordance figure measures benchmark instability, not a production failure rate.
A localized question can change the answer without changing the mathematics
Consider an Arabic-language mathematics assistant evaluated on a translated word problem involving a person in Toulouse paying in dollars. A localization team replaces the location with Cairo and the currency with Egyptian pounds, while retaining every mathematical quantity and relationship.
The correct numerical answer should remain unchanged. Yet the assistant may solve one formulation correctly and fail on the other.
A conventional benchmark score can miss this difference. Suppose localization causes a model to lose correctness on some questions but gain it on others. Its overall accuracy might remain nearly constant, even though the set of questions it solves reliably has changed.
For a product team deciding whether to approve that assistant for regional users, those are different outcomes. Average accuracy measures how often the model succeeds across a test set. It does not establish whether success is stable when an equivalent question is expressed in culturally familiar terms.
The DAR-MGSM study makes this instability measurable.
The benchmark separates language translation from cultural adaptation
The researchers start with 250 English grade-school mathematics problems from MGSM-Rev2. Each problem receives professionally translated and manually reviewed versions in six Arabic varieties: Modern Standard Arabic (MSA), Egyptian, Emirati, Jordanian, Moroccan, and Saudi.
For each variety, the benchmark provides two conditions:
- Translated: The mathematics problem appears in Arabic while retaining the original culturally specific references.
- Localized: Names, locations, currency labels, and applicable numeral conventions are adapted to the target variety, without changing the underlying mathematical relationships or reference answer.
This produces 3,000 benchmark texts: 1,500 translated and 1,500 localized.
The matched construction is essential. It lets researchers observe whether changing cultural presentation affects a model’s answer while holding the mathematical task fixed. Fifty-one source problems have no entities requiring substantive localization, so the principal full-localization paired analysis excludes them.
Dataset construction also required considerable quality assurance. Depending on the Arabic variety, 4.0% to 49.6% of initially translated problems needed major correction or retranslation during internal review (Section 3.1; Appendix A, Table 6). These percentages describe corrections made during construction, not errors remaining in the released benchmark.
The resulting evaluation tests model behavior under a restricted form of cultural adaptation. It does not recreate mathematics problems originally developed in different local educational environments.
Average accuracy hides which questions switch from correct to incorrect
The main benchmark comparison covers 11 Arabic-centric and multilingual language models.
Across models and Arabic varieties, mean numerical-answer accuracy falls from 65.5% on translated problems to 63.4% on localized problems, a decline of 2.1 percentage points (Section 5.1, Table 3).
The average conceals substantial variation. Atlas-Chat-2B falls from 25.1% to 19.9%, and Jais2-8B-Chat from 65.7% to 60.7%. Conversely, GPT-5.4 improves from 89.1% to 89.7%, while Gemma4-26B changes only from 85.8% to 85.6%.
Moroccan Arabic has the lowest average accuracy among the six evaluated varieties, at 55.3% translated and 54.8% localized. That ranking characterizes the tested models and benchmark formulations, not the mathematical capabilities of Moroccan Arabic speakers.
A more revealing measurement compares correctness on each matched problem. A pair is discordant when the translated version receives a correct answer and the localized version an incorrect one, or vice versa.
The three Gemma 4 models produce the following full-localization results (Section 5.2, Table 4):
| Model | Correctness discordance | Localized accuracy change |
|---|---|---|
| Gemma4-2B | 12.9% | −1.7 pp |
| Gemma4-4B | 8.0% | −1.8 pp |
| Gemma4-26B | 5.6% | −0.3 pp |
Across these models, 180 eligible pairs are correct only in the translated condition, while 136 are correct only after localization. Their difference accounts for the modest net decline. Their sum—316—is the number of pairs whose correctness changes (Appendix F, Table 13).
The larger Gemma 4 models exhibit lower discordance, but even the 26B variant changes correctness on 5.6% of eligible pairs. A near-zero average accuracy difference therefore cannot be read as evidence of near-zero answer instability.
Internal representations change, but the semantic cause remains uncertain
The researchers next investigate whether the answer differences correspond to changes in the models’ intermediate computations.
They compare residual-stream trajectories: sequences of internal representations across transformer layers. Greater distance between trajectories indicates greater separation in the representations produced by two model runs.
Across pooled Gemma 4 comparisons covering the localization schemes, pairs answered correctly in both conditions have mean normalized trajectory distance of 0.29. Pairs correct in only one condition have mean distance of approximately 1.50 (Appendix F, Table 12).
This is an association between computational divergence and answer instability. The distance measurement alone cannot identify what causes the wrong answer.
A sampling robustness test provides a further check. Comparing translated–localized differences against repeated generation from the translated baseline, localization produces greater trajectory separation in 17 of 18 model-dialect cells. Localization correctness-flip rates exceed sampling flip rates in 13 cells, equal them in one, and fall below them in four (Appendix F, Table 14).
That result makes ordinary generation variability an incomplete explanation, although it remains a contributor in some settings.
The researchers then perform activation patching: replacing selected internal representations at modified entity-token spans with representations from another run and observing the resulting answer.
Patching matched entity spans reaches 54.7% best-layer correctness, compared with 35.7% for patching unrelated spans. This intervention provides stronger evidence that representations at the modified positions participate in the model’s behavior.
But the crucial control is shuffled-source patching. When representations come from mismatched source examples, best-layer correctness still reaches 52.3%, close to matched-source patching. Both achieve a source-closeness gain of 0.31 (Section 5.2, Figure 3; Appendix G).
Consequently, the experiment supports a causal role for internal states at localized spans, without establishing that the specific cultural identity or meaning of a replacement entity is responsible. More general changes in representation state could contribute to the observed recovery.
This distinction limits the mechanistic explanation without weakening the directly observed answer instability.
Model qualification needs paired localization tests
For teams selecting multilingual models or releasing localized AI applications, Cognaptus draws a bounded evaluation recommendation from these findings.
Keep translated benchmark cases, but pair them with culturally localized versions whose mathematical quantities, relationships, and reference answers are verified. Report both condition-specific accuracy and the rate at which correctness changes between matched formulations.
The paired report should also distinguish translated-only successes from localized-only successes. A low net accuracy change can otherwise conceal offsetting failures and recoveries.
Evaluation should be segmented by the dialects the application actually serves. The study documents differences across Arabic varieties and models, so a pooled multilingual score cannot substitute for a deployment-relevant dialect assessment.
For a localization or model-release team, matched questions can become regression tests across successive model versions. Cases that previously changed correctness can be rerun after model upgrades, prompt revisions, or localization changes. Repeated generations can help distinguish systematic sensitivity from sampling variability.
This is a proposed operational use of the benchmark design, not a workflow whose financial return or production effectiveness the paper measures.
Where the findings stop
Several boundaries affect how far these results can be applied.
The benchmark contains only 250 distinct English-origin problems, and localization changes selected surface entities rather than the broader cultural structure of mathematics instruction. Its five dialects and MSA do not cover all Arabic varieties.
The principal accuracy evaluation uses one generation per model, variety, and condition. Model families also have different prompting and decoding configurations. The mechanistic analysis is restricted to three Gemma 4 models, and the activation-patching controls leave the entity-specific semantic mechanism unresolved.
Nor does the study measure classroom learning, real-user outcomes, or deployed-system reliability. A benchmark discordance rate is not directly interchangeable with an incident rate in an educational application.
The practical conclusion is narrower and actionable: when mathematically equivalent localized questions produce different correctness outcomes, average accuracy is an incomplete qualification metric. Teams can detect that mismatch by preserving matched test cases and reporting answer-level stability alongside aggregate performance.
The mathematics has not changed. The evaluation needs to show when the model’s answer has.
Cognaptus: Automate the Present, Incubate the Future.
-
Noor Abo Mokh and Teresa Lynn and Nizar Habash and Ahmed Elshabrawy and Sara Alhajeri and Alaa Elsetohy and Preslav Nakov and Alham Fikri Aji (2026). Benchmarking Arabic Dialects for Math Problems. arXiv:2610.28607. https://arxiv.org/abs/2610.28607 ↩︎