TL;DR for operators
When a robot succeeds after repairing a failed procedure, the next decision is whether that repair should remain local or become a reusable capability. RoboFoundry1 addresses this through system evolution without foundation-model weight updates. It diagnoses failures from execution traces, revises memory or execution support, and verifies proposed general changes before retaining them. On EmbodiedBench, GPT-5.5 average success increases from 56.9% to 72.7%. An ablation also supports the value of persistent general-system improvement beyond task-specific repair. Organizations deploying embodied agents can investigate this approach before pursuing model replacement, but shared revisions still require deployment-specific testing, safety controls, and cost evaluation.
A successful repair creates another decision
A robot places an object incorrectly, receives feedback, and completes the task after its procedure is adjusted. The immediate problem appears resolved. Yet the revised procedure may work only for that object, environment, or robot configuration.
Should the system retain the repair for future tasks? Could reusing it interfere with another procedure? And can it identify whether the original failure came from perception, reasoning, planning, memory, or execution support?
These questions concern the system that turns model decisions into physical actions. Improving the underlying model is only one possible intervention.
RoboFoundry provides an instructive comparison. Across the four EmbodiedBench suites, its GPT-5.5 configuration raises average task success from 56.9% to 72.7%, a gain of 15.8 percentage points, or 27.8% relative to the baseline. The foundation model’s weights remain unchanged (Section 3.1, Table 1).
The improvement shifts attention toward a less obvious optimization target: the executable infrastructure surrounding the model.
The supporting system becomes part of the policy
A foundation model does not determine robot behavior independently. Its decisions depend on available context, persistent records, executable skills, recovery procedures, and interfaces that translate decisions into robot-specific actions.
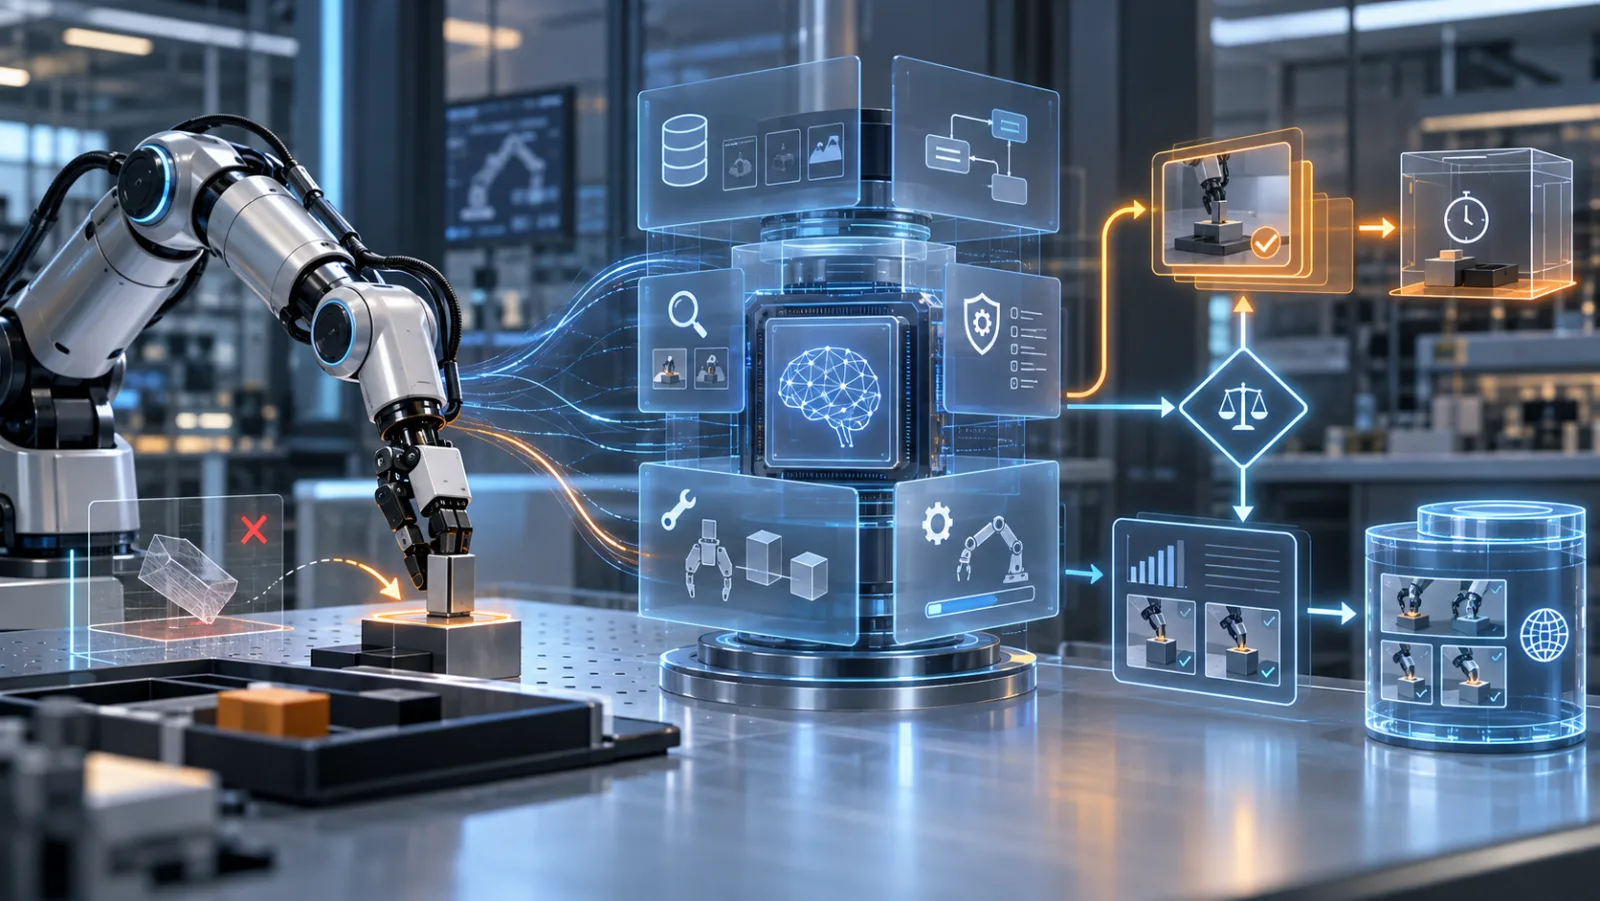
RoboFoundry formalizes this arrangement as Self-Evolving System-as-Policy. The foundation model $M$ remains frozen, while its supporting system $H(M)$ can change through persistent filesystem revisions (Section 2.1).
The architecture distinguishes two scopes:
- Task-specific system: Procedures and context revisions intended to resolve a particular task’s failure.
- General system: Persistent capabilities intended to benefit other tasks sharing a relevant deficiency.
The framework also separates semantic task decisions from robot-specific execution through its binding interfaces. Reusable task semantics can therefore connect to different robot implementations, provided compatible execution primitives exist.
At the execution level, hierarchical skills combine atomic actions into longer procedures. Recovery trees support replanning from valid intermediate states after a failure. The initial atomic skills rely on handcrafted, verified implementations; RoboFoundry does not demonstrate autonomous creation of arbitrary low-level motor controllers.
Consequently, the editable policy extends well beyond prompts. It includes how information is maintained, how executable procedures are composed, and how failures are handled.
From execution traces to targeted repairs
RoboFoundry operates through interacting execution and improvement loops.
The inner loop attempts tasks and records observations, actions, robot states, feedback, and failures. The outer loop examines these traces to determine what should change.
Its diagnosis separates six capability categories: perceive, reason, plan, save, retrieve, and utilize (Section 2.3).
The last three govern different memory operations. Saving determines what information persists; retrieval identifies relevant stored information; utilization determines how retrieved information enters active context and influences execution.
This separation permits targeted intervention. A robot that has already recorded a relevant object state may need better retrieval rather than additional memory. A robot that remembers the state correctly but repeats an invalid action sequence may instead need a revised skill composition or recovery procedure.
A proposed repair is first evaluated on the current task. Successful task-specific changes can then be considered for broader reuse.
The critical restriction is that a successful local repair does not automatically become a general-system update.
RoboFoundry’s capability-conditioned promotion procedure replays stored pre-repair traces from other tasks associated with the same capability deficiency. A verifier compares repairs proposed under the candidate general rule with previously validated task-specific repairs.
The general edit is accepted when its average transfer score is nonnegative (Section 2.3, Equation 3).
This is a defined promotion criterion, not proof that the revision will execute successfully in every unseen environment. Its reliability depends on the relevance of stored traces and the verifier’s ability to recognize damaging changes.
The study provides an ablation directly relevant to this mechanism. With Qwen3.7-Plus on EmbodiedBench, RoboFoundry-Lite, which retains task-level evolution but removes general-system evolution, achieves 63.2% average success. Full RoboFoundry reaches 70.3%.
The 7.1-percentage-point difference supports the incremental contribution of persistent general-system evolution under the benchmark protocol. It does not separately identify the causal contribution of every memory, diagnosis, or skill component.
The benchmarks test different parts of the system
The evaluation extends beyond a single task family. Its main comparisons, ablation, robustness tests, and physical demonstrations answer related but distinct questions.
| Evaluation | Reported evidence | Interpretation |
|---|---|---|
| EmbodiedBench, 1,128 tasks | GPT-5.5: 56.9% baseline versus 72.7% evolved | Main evidence that system changes improve task success with frozen weights |
| RoboMemArena, 26 tasks | RoboFoundry: 53.5% TSR and 72.8% CSR; PrediMem: 38.5% and 55.2% | Main evidence for long-horizon memory performance |
| LIBERO-PRO, 30 tasks | 91.9% versus 87.8% for Harness VLA (CC), averaged across six non-privileged settings | Robustness evidence under specified position and task perturbations |
| Physical nesting-doll manipulation | 70% versus 30% for standalone pi_0.5 | Initial evidence of online physical-robot adaptation |
Sources: Sections 3.1–3.4, Tables 1–4 and Figures 5–6. TSR denotes task success rate; CSR denotes cumulative success rate.
The memory results are especially informative about where improvements occur. RoboFoundry reaches 70.5% task success on RoboMemArena Transfer tasks, compared with 22.5% for PrediMem. The Sequence comparison is narrower, at 75.2% versus 72.5%. Context evolution also improves separately evaluated pi_0.5 and PrediMem configurations, supporting its applicability across different memory architectures (Tables 2–3).
Two additional tests constrain interpretation.
First, EmbodiedBench experiments with a 16K context budget continue to show gains from RoboFoundry. For GPT-5.5, average success increases from 63.4% to 71.7% under that condition. Expanding context alone does not consistently explain the improvement. This is a sensitivity check, not another independently established mechanism (Appendix A, Table 9).
Second, LIBERO-PRO experiments supplying privileged simulator object poses produce higher success than ordinary perception-based execution. This identifies perception quality as a remaining bottleneck. RoboFoundry has the highest average across the six non-privileged settings, although competing methods outperform it in particular conditions.
The physical evaluations add feasibility evidence. After evolving a towel-folding capability on a blue towel, the framework transfers it without further adaptation to green and pink towels, with success above 80% versus below 20% for the standalone baseline. Other demonstrations involve Unitree G1 semantic navigation and a chemistry-manipulation sequence.
These experiments support transfer under the tested configurations, not universal portability across hardware or environments.
What changes for deployment decisions
For organizations operating robots or tool-using agents, the Cognaptus interpretation is that system improvement should have an explicit promotion process, distinct from model selection.
A deployment team could retain the failure trace, diagnose the capability, record the proposed edit, test its local effect, and evaluate regressions before approving a shared revision. Memory-selection policies, recovery procedures, reusable skills, and execution adapters would become versioned operational components.
This approach changes two decisions.
The first is whether inadequate task performance justifies purchasing or deploying a stronger foundation model. A comparable system-level improvement experiment can establish whether the existing backbone has recoverable performance limitations.
The second is whether a locally effective repair deserves authority over other tasks or robots. RoboFoundry’s verification approach offers a research mechanism for that decision; production use would require stronger, domain-specific acceptance criteria and rollback procedures.
Cross-embodiment reuse likewise requires compatible semantic representations and robot-specific execution bindings. It is an integration strategy, not evidence that a procedure can execute unchanged on arbitrary hardware.
Where the evidence stops
The strongest results come from simulation benchmarks. Physical demonstrations report ten trials per task, limiting conclusions about failure probabilities and operational reliability. Principal aggregate improvements are not accompanied by comprehensive confidence intervals or significance tests.
Reported benchmark scores also include evolution rollouts. They therefore describe the performance of an evolving system rather than exclusively post-adaptation evaluation on untouched tasks.
Long-term safety, resistance to damaging persistent revisions, and reliability under arbitrary distribution shifts remain unestablished. The paper does not comprehensively measure the inference costs, repair attempts, verification overhead, or accumulated latency associated with evolution. The identified official repository also lists major benchmark implementations as pending, restricting immediate reproduction.
These gaps prevent a conclusion that system evolution is already safer or economically superior to model-level alternatives in production.
RoboFoundry nevertheless establishes a concrete research direction: meaningful improvements in embodied-agent performance can come from revising the executable system while preserving the foundation model. The harder problem is deciding which changes deserve to persist—and validating those decisions beyond the task that first motivated the repair.
Cognaptus: Automate the Present, Incubate the Future.
-
Jingsong Liang and Shuhao Liao and Shizhe Zhang and Diyuan Hou and Yuxin Cai and Xinjian Deng and Chengyang He and Wenhui Huang and Runjia Tan and Zhidong Wang and Lan Yu and Xuesong Tian and Guillaume Sartoretti and Jie Luo and Yao Mu and Wenjun Wu and Wanhua Li and Chen Lv (2026). RoboFoundry: System-as-Policy Evolution for Self-Learning Embodied Agents. arXiv:2609.32862. https://arxiv.org/abs/2609.32862 ↩︎