TL;DR for operators
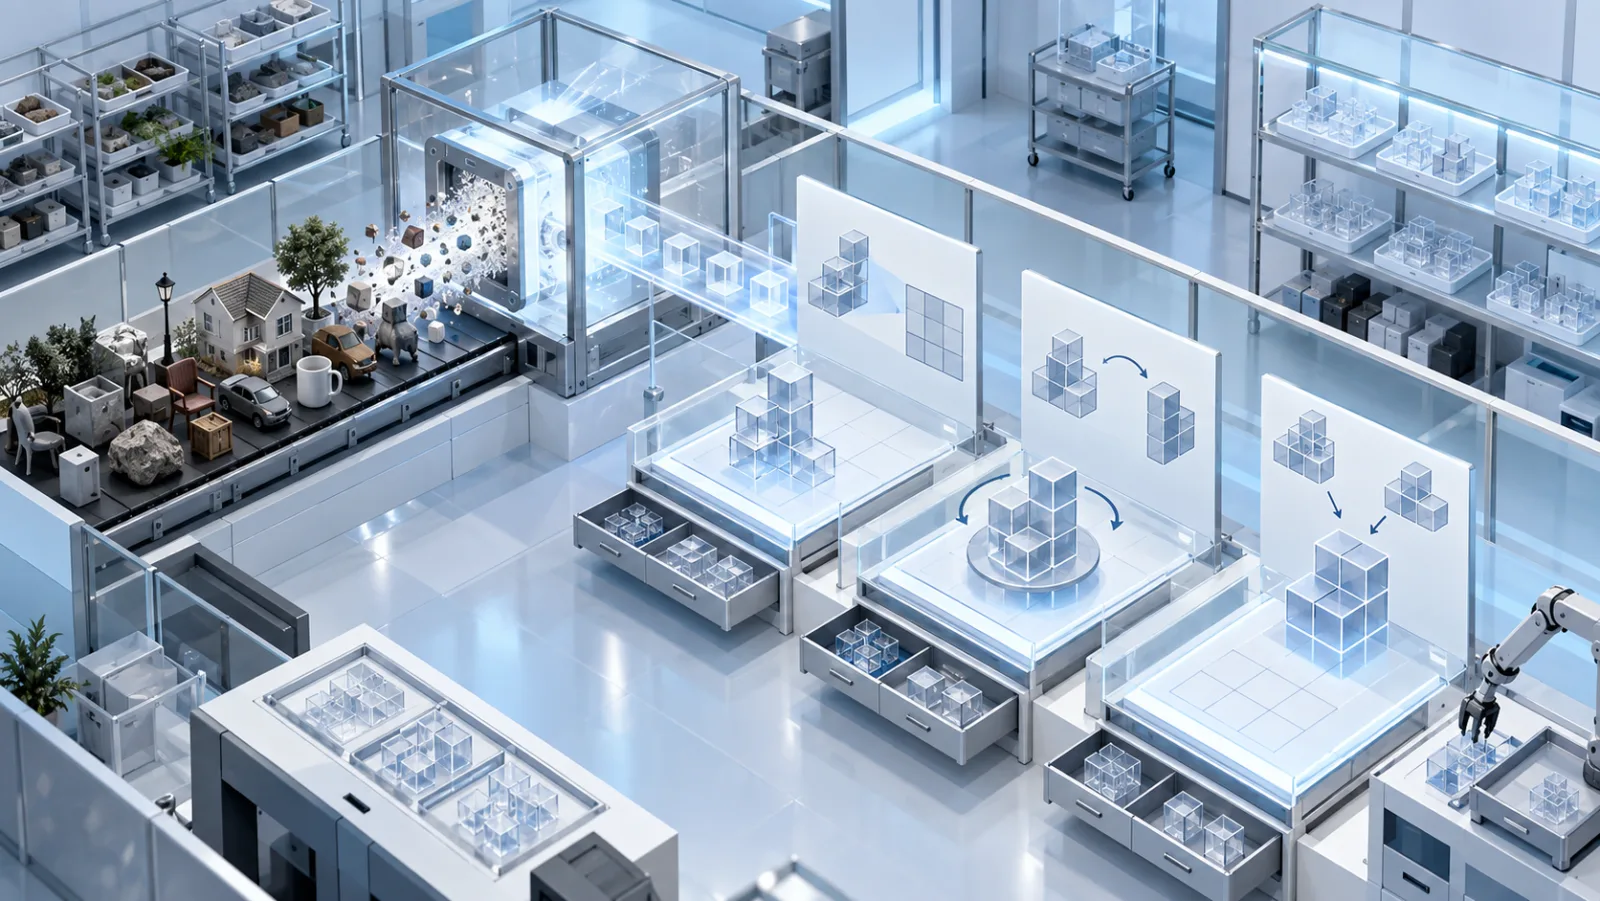
A synthetic-data budget creates a design choice: generate examples that resemble deployment tasks, or construct simpler exercises that isolate the operations a model will repeatedly need. SpatialBlock1 provides evidence for the second strategy.
In a matched Qwen2.5-VL-3B experiment, synthetic training on conventional relative-direction and relative-distance questions improves those same in-domain tasks. But the SpatialBlock curriculum performs better on several external evaluations: 49.1 versus 32.8 on MindCube, 28.1 versus 25.5 on MMSI-Bench, and 46.4 versus 43.6 on MMMU.
The result is not evidence that toy scenes can replace real-world spatial supervision wholesale. It is evidence that task structure can matter more than surface realism when the goal is to teach reusable spatial operations. The paper’s ablations reinforce that interpretation: combining several kinds of spatial manipulation works better than relying on one alone, and deliberately encoded visual cues contribute to transfer.
For teams developing multimodal systems, the practical question becomes less “How realistic should our synthetic data look?” and more “Which operation does each training example force the model to learn?”
Realistic labels can win their own task and still transfer worse
Synthetic data is often treated as a cheaper substitute for expensive annotation. Under that framing, greater realism seems preferable: if a production system must reason about object direction, distance, and geometry, training examples that resemble those labels should be useful.
SpatialBlock tests a different proposition.
The authors construct a matched synthetic dataset called Synthetic-Real using conventional relative-direction and relative-distance questions in the same block-based environment. That curriculum behaves as expected on its own targets. Relative-direction accuracy rises from 31.4 for the baseline to 43.4, while relative-distance accuracy increases from 74.1 to 76.9.
SpatialBlock does not improve those tasks. Its relative-direction score remains 31.4, while relative-distance accuracy falls to 67.4.
The pattern reverses outside those training targets.
| Training data | Relative direction | Relative distance | MindCube | MMSI-Bench | MMMU |
|---|---|---|---|---|---|
| Baseline | 31.4 | 74.1 | 39.1 | 26.1 | 45.6 |
| Synthetic-Real | 43.4 | 76.9 | 32.8 | 25.5 | 43.6 |
| SpatialBlock | 31.4 | 67.4 | 49.1 | 28.1 | 46.4 |
The conventional curriculum gets better at the measurements it directly practices. The block-manipulation curriculum transfers better to these three reported external evaluations.
That comparison changes the data-design problem. Similarity between a training label and a deployment label is not sufficient evidence that the training task teaches the most reusable representation.
The blocks are exercises for three different spatial operations
SpatialBlock-15k contains 15,000 examples, divided evenly across three task families. The environment is deliberately constrained: a $3\times3$ grid contains vertical stacks of one to four blocks, and severely occluded configurations are excluded.
The useful unit of analysis is not the block itself. It is the mental operation required by the question.
The first family asks the model to infer a two-dimensional view from a three-dimensional arrangement. The second requires imagining the same structure from another viewpoint. The third asks the model to combine structures or partial spatial information.
In the paper’s terminology, these are 3D-to-2D projection, viewpoint transformation, and structural combination.
Training all three together generally works better than training any one of them alone. With the Qwen2.5-VL-3B reasoning model, the combined curriculum reaches a 41.2 average across the reported out-of-domain benchmarks. The Q1-, Q2-, and Q3-only variants score 38.8, 38.0, and 39.1 respectively.
This is an ablation, not a separate headline result. Its purpose is diagnostic: it supports the interpretation that transfer comes partly from exposing the model to complementary spatial operations rather than repeatedly drilling one puzzle format.
The colors are part of the supervision
The rendered scenes also contain controlled color cues. These are not cosmetic augmentation.
For projection questions, color can indicate depth ordering. For viewpoint transformation, a colored block can serve as a persistent anchor. For structural combination, colors identify correspondences where structures overlap.
Removing those cues substantially reduces performance on the synthetic benchmark and weakens transfer on important external tests. For the direct model, MindCube falls from 49.1 to 41.2 and MMSI-Bench from 28.1 to 26.2. For the reasoning model, MindCube falls from 45.3 to 38.0 and MMSI-Bench from 29.2 to 24.4.
This makes the paper more relevant to synthetic-data engineering than a simple “synthetic versus real” comparison would suggest. Dataset design includes the information scaffolding embedded inside each example: what remains visually stable, what highlights correspondence, and what gives the model a tractable anchor while it learns a transformation.
A Cognaptus inference follows from this evidence: when generating synthetic training data, teams should specify the intended latent operation and the cues that make that operation learnable before optimizing scene realism or dataset volume.
Reasoning training changes the optimization route, not the main data argument
The paper trains two model families.
The direct models learn the correct answer tokens with standard cross-entropy. The reasoning-oriented models first receive LoRA-based supervised initialization and then undergo GRPO reinforcement learning, with rewards for answer correctness, output format, and response length.
Their strengths differ. Direct models produce especially large MindCube gains. For example, Qwen3-VL-4B rises from 26.2 to 51.3 on MindCube, while InternVL3-2B rises from 32.1 to 51.4.
Reasoning variants are stronger on some multi-image or diverse-viewpoint evaluations, and the paper reports a reasoning-step alignment score of 21.1 versus 17.8 for the baseline.
Initialization also matters. A no-initialization reasoning variant reaches an out-of-domain average of 39.2, compared with 41.2 for the paper’s LoRA-initialized SpatialBlock-3B reasoning model. The authors also report noisy teacher-generated cold-start rationales, which helps explain why initialization is treated as an empirical design variable rather than assumed to be interchangeable.
For deployment, this creates a secondary choice. Teams may prefer direct-answer adaptation when latency and concise output dominate, while reasoning-oriented training may be worth testing where explicit intermediate behavior is operationally valuable. The paper does not establish a universal winner between the two.
Spend a synthetic-data budget on operations, not realism alone
For robotics, embodied assistants, industrial vision, or other multimodal products, the most transferable part of this work is the curriculum-design principle.
A team with limited labeling or rendering capacity can ask four concrete questions:
- Which spatial operations recur across downstream tasks?
- Can those operations be isolated in a simpler synthetic environment?
- Which visual cues help the model track depth, correspondence, or persistent anchors?
- Does transfer survive when the surface appearance or viewpoint changes?
SpatialBlock provides encouraging evidence for that approach. Models trained at a fixed 45-degree rendering angle remain comparatively stable when evaluated on 30- and 60-degree renderings of the same underlying block structures. That robustness test supports the claim that the models learn something about structure beyond one exact camera configuration, although it is not evidence of unrestricted viewpoint invariance.
The evidence stops well before general 3D competence
The strongest interpretation should remain structural rather than geometric.
The training environment is highly simplified, with small block grids and limited stack heights. Severely occluded configurations are excluded. Most benchmark evaluation is multiple-choice. SB-Bench is closely aligned with the training domain, so its roughly 90–97% scores for many SpatialBlock variants should not be read as equivalent to comparable real-world competence.
The numerical results make the boundary clearer. On SPBench, the direct model improves object counting from 35.1 to 72.1 and the reasoning model improves object-size estimation from 17.6 to 38.3. Yet absolute-distance accuracy declines from the 30.9 baseline to 23.2 for the direct model and 21.4 for the reasoning model.
SpatialBlock therefore supports a narrower claim: carefully constructed synthetic curricula can teach structural operations that transfer beyond the toy environment. It does not show that the resulting models possess reliable metric geometry or broad real-scene 3D understanding.
Curriculum design is part of model design
The useful result in SpatialBlock is not that blocks are unusually powerful training objects. It is that synthetic examples can be designed around what the model must mentally do, rather than around what the final application looks like.
The matched comparison is particularly informative because the more conventional synthetic curriculum succeeds on the tasks it directly practices. SpatialBlock’s advantage appears when evaluation asks for different spatial reasoning behavior.
For teams deciding where to spend the next 15,000 synthetic examples, that shifts the design target. Scene realism remains relevant, but it is only one variable. The structure of the exercise, the diversity of the required operations, and the information cues embedded in each example can determine whether training produces a narrow skill or a reusable one.
Cognaptus: Automate the Present, Incubate the Future.
-
Soohyun Ryu and Sohee Kim and Eunho Yang (2026). SpatialBlock: Enhancing Spatial Intelligence in LVLMs via Synthetic Block-Stacking Problem. arXiv:2609.07064. https://arxiv.org/abs/2609.07064 ↩︎