TL;DR for operators
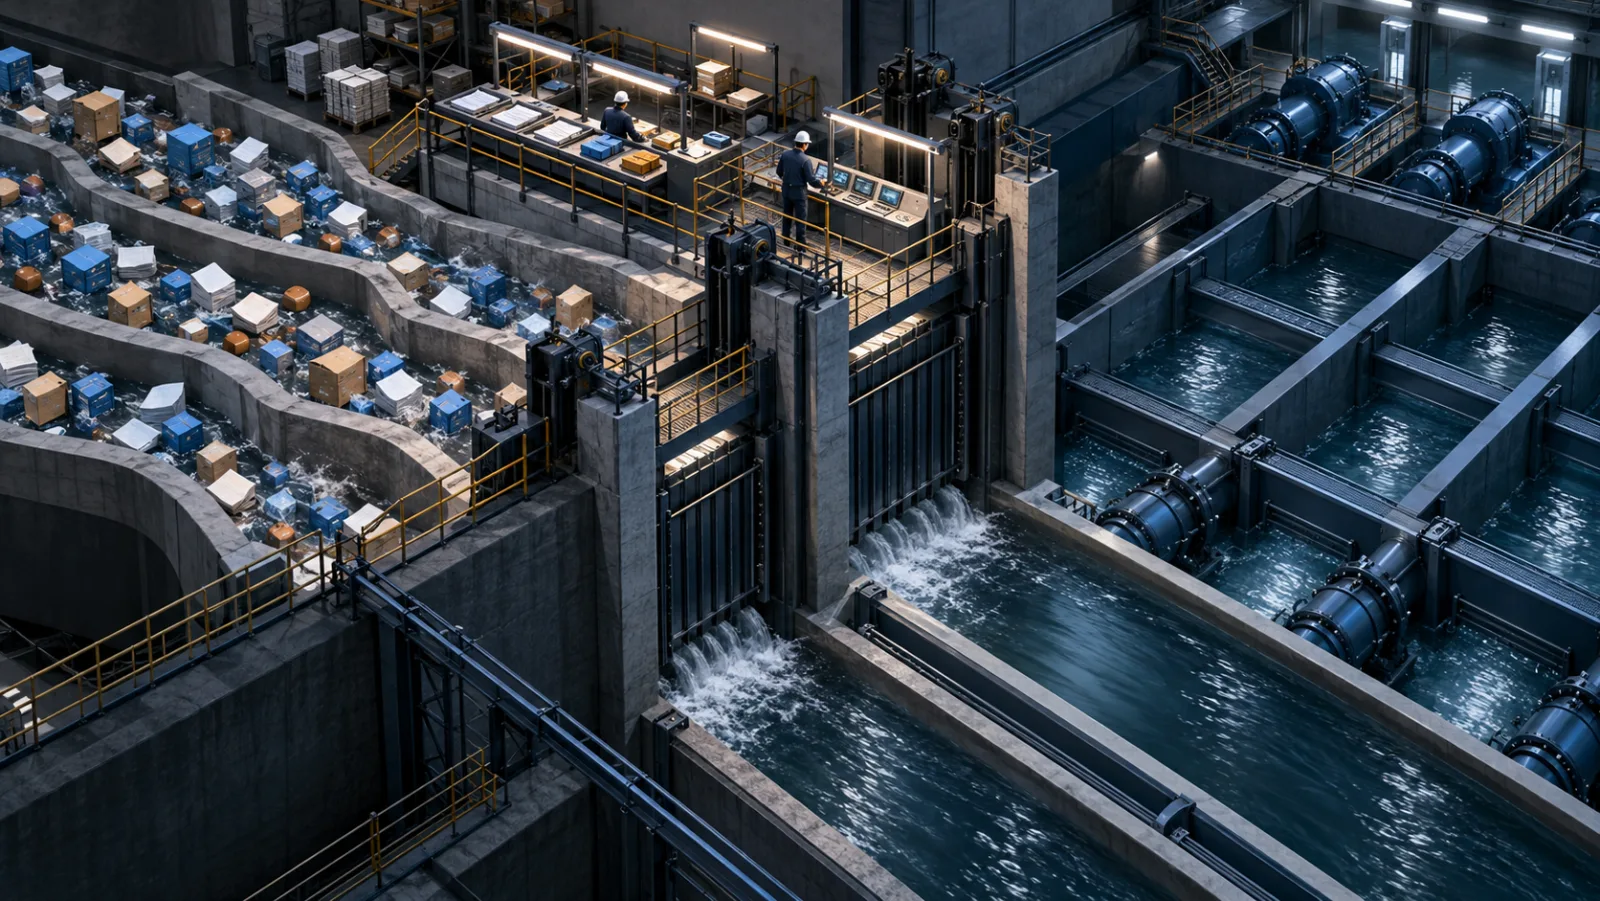
The most consequential choice in this paper is where the LLM is allowed to act. It does not decide whether simulated farms adopt solar panels. Instead, it works upstream: drafting behavioural rubrics and techno-economic scenarios that humans inspect, validate against explicit rules, freeze, and then feed into an existing calibrated simulation.
That separation matters for teams already responsible for trusted quantitative models. It lets generative AI expand the space of assumptions being tested without making runtime outcomes depend on fresh model generations. In the experiments, bounded behavioural adjustments are large enough to matter: optimistic specifications increase simulated adoption by roughly 11–13% relative to matched logistic baselines. Scenario results then show that higher adoption can carry very different fiscal consequences.
The architecture is therefore more relevant as a model-governance pattern than as evidence for autonomous LLM agents. Its robustness tests show that the augmented simulation behaves consistently across repeated runs and seeds. They do not establish that its LLM-derived behavioural assumptions accurately represent Irish dairy farmers or improve forecast accuracy.
Richer behaviour does not require a generative model at runtime
Teams maintaining calibrated policy or forecasting models face a recurring problem. The quantitative core may be disciplined and empirically tuned, while the behavioural assumptions around it remain comparatively rigid. An LLM can generate richer descriptions quickly, but letting it make live decisions inside the simulation introduces another source of nondeterminism, judgement and difficult-to-audit variation.
Faiud, Khaleghy, Schukat and Mason take a narrower route in LLM-Assisted Behavioural and Scenario Augmentation for Agent-Based Energy Adoption Models.1 Their simulation concerns solar-PV adoption by Irish dairy farms through 2040. The pre-existing calibrated model remains responsible for turning techno-economic utility into an adoption probability. The LLM is used offline to help draft behavioural specifications and scenarios.
Those outputs do not enter the model unchecked. The authors manually inspect and refine them for schema validity, weight sums, allowable multiplier ranges, monotonic ordering and consistency with the calibrated simulation. Scenario definitions receive rule-based checks as well. Once accepted, the specifications are fixed before execution.
This changes the governance question. The relevant design choice is no longer whether an LLM should replace a deterministic model. It is whether an LLM can assist specification while the validated model retains execution authority.
The behavioural layer is bounded around the calibrated probability
The existing model starts with a logistic adoption probability derived from economic utility:
The calibrated parameters $\alpha$ and $\beta$ remain fixed throughout the augmentation experiments.
The added behavioural layer uses five predefined inputs: payback attractiveness, grant support, feed-in-tariff or export attractiveness, financing attractiveness, and electricity-price pressure. Each behavioural rubric assigns weights to those factors and converts the resulting score into a multiplier.
The important control is the final clipping step. The multiplier cannot grow or shrink indefinitely:
The model then applies that bounded adjustment to the calibrated probability:
So the LLM-generated specification cannot replace the underlying probability mechanism. It can only modify its output within predetermined limits.
That is the main architectural contribution. For a model-governance team, every generative contribution has an explicit destination, an admissible range and a deterministic implementation. The production simulation is therefore reproducible once its specifications have been approved.
The behavioural adjustment is large enough to change policy results
The behavioural layer is not merely documentation around the original model. Across all three baseline policy settings, adoption rises monotonically as the simulation moves from the logistic baseline through conservative, balanced and optimistic behavioural regimes.
Under the 40% grant policy, optimistic behaviour raises simulated cumulative adoption from 3,094.4 to 3,442.4 farms, an 11.25% increase. Under the 60% grant policy, adoption rises from 3,478.6 to 3,924.4, or 12.81%.
Public expenditure rises as well. In that 60% grant case, cumulative public cost increases from €24.82 million to €28.57 million, a 15.09% increase.
The result is relevant because it shows what specification risk can mean in a decision model. A bounded behavioural assumption that looks modest at the probability level can materially change aggregate adoption and budget estimates over the simulation horizon.
It does not show that optimistic behaviour is more realistic. The experiment establishes sensitivity to structured behavioural assumptions, not their empirical truth.
Scenario analysis turns adoption into a cost-allocation question
The scenario experiments make the framework more operational for policy analysis because they modify variables that agencies, lenders, utilities and developers already monitor: grants, tariffs, financing costs, electricity prices, technology costs and export conditions.
Under the balanced behavioural rubric, the energy-crisis scenario increases simulated adoption by 11.54% relative to the calibrated baseline scenario while increasing public cost by 7.68%. Subsidy withdrawal moves both in the opposite direction: adoption falls 7.73%, while public cost falls 20.50%.
Rapid technology improvement is more instructive. It reduces public cost by 12.79% but also slightly reduces adoption, by 1.54%. Lower technology cost alone therefore does not dominate the other conditions encoded in the scenario.
The relevant policy question becomes less about maximizing simulated uptake and more about selecting an acceptable adoption-cost combination under a stated set of assumptions.
| Evidence block | Likely purpose | What it supports | What it does not establish |
|---|---|---|---|
| Behavioural regimes across three policies | Main evidence | Bounded behavioural specifications materially change adoption and cost | That one rubric matches real farmer behaviour |
| Seven techno-economic scenarios | Main comparative evidence | Policy and market assumptions produce different adoption-cost trade-offs | Forecasts of future Irish market conditions |
| 500 Monte Carlo worlds and five seeds | Robustness test | Results are internally stable and rankings are not seed artifacts | External behavioural validity |
| Multiplier bounds and rule checks | Implementation and governance control | LLM-derived inputs remain constrained and auditable | That LLM specifications outperform expert specifications |
The robustness tests qualify execution, not behaviour
The final diagnostics are strong for what they test. Across the evaluated scenarios, coefficients of variation range from about 0.0030 to 0.0041. All scenarios retain monotonic behavioural ordering, no saturation flags appear, and the authors report no seed-sensitive experiment rows. The maximum observed behavioural multiplier is 1.254.
These checks address a specific concern: whether adding the behavioural layer produces unstable, pathological or random-seed-dependent simulation behaviour. The reported evidence says it does not under the tested configurations.
But internal stability is a different property from behavioural validity.
The rubrics are structured approximations rather than estimates derived from observed farmer decisions. The paper does not compare its LLM-assisted rubrics with expert-designed alternatives, alternative prompt outputs or farmer-grounded behavioural models. Prompt wording, model bias and manual refinement can therefore still shape the specifications that ultimately become deterministic inputs.
For an operator, the distinction is consequential. A stable model can repeatedly produce the same answer to the wrong behavioural assumption.
Use generative AI for specification where execution must remain governable
The paper suggests a deployable pattern for teams that already have a calibrated decision model but need broader qualitative scenario coverage.
Policy teams can use an LLM to draft candidate assumptions about financing pressure, tariffs, grants or market conditions, provided those assumptions are translated into explicit variables and validated before execution. Model-governance teams can require that generative outputs stop at the specification boundary rather than flow directly into runtime decisions. Analysts can then compare scenarios using common model logic and retain a clear record of what changed.
That pattern is most defensible when a trusted quantitative core already exists and the LLM is being used to structure hypotheses rather than supply empirical evidence.
The unresolved question is whether LLM-assisted specification produces better assumptions than disciplined human specification. This study does not test that comparison. Its contribution is narrower and more immediately implementable: generative assistance can be separated from model authority.
For organizations exploring LLMs in simulations, that separation may be the feature worth copying first.
Cognaptus: Automate the Present, Incubate the Future.
-
Iias Faiud and Hossein Khaleghy and Michael Schukat and Karl Mason (2026). LLM-Assisted Behavioural and Scenario Augmentation for Agent-Based Energy Adoption Models. arXiv:2609.04866. https://arxiv.org/abs/2609.04866 ↩︎